
P.S. Free 2026 Amazon MLA-C01 dumps are available on Google Drive shared by ExamBoosts: https://drive.google.com/open?id=1SD0IebydkTqeuZLFNESWwQNPJMx-ICjH
You only need 20-30 hours to practice our software materials and then you can attend the exam. It costs you little time and energy. The MLA-C01 exam questions are easy to be mastered and simplified the content of important information. The MLA-C01 test guide conveys more important information with amount of answers and questions, thus the learning for the examinee is easy and highly efficient. So it is convenient for the learners to master the MLA-C01 Guide Torrent and pass the MLA-C01 exam in a short time.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Test Amazon MLA-C01 Preparation <<
You may feel astonished and doubtful about this figure; but we do make our MLA-C01 exam dumps well received by most customers. Better still, the 98-99% pass rate has helped most of the candidates get the certification successfully, which is far beyond that of others in this field. In recent years, supported by our professional expert team, our MLA-C01 Test Braindumps have grown up and have made huge progress. We pay emphasis on variety of situations and adopt corresponding methods to deal with. More successful cases of passing the MLA-C01 exam can be found and can prove our powerful strength.
NEW QUESTION # 116
Case Study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
Which AWS service or feature can aggregate the data from the various data sources?
Answer: A
NEW QUESTION # 117
A company wants to migrate ML models from an on-premises environment to Amazon SageMaker AI. The models are based on the PyTorch algorithm. The company needs to reuse its existing custom scripts as much as possible.
Which SageMaker AI feature should the company use?
Answer: A
Explanation:
SageMaker script mode allows ML engineers to bring existing training scripts written for frameworks such as PyTorch and TensorFlow directly into SageMaker with minimal changes. AWS documentation explicitly states that script mode is designed to support migration of existing ML workloads.
With script mode, the user provides a custom training script, and SageMaker handles infrastructure provisioning, distributed training, logging, and model artifact storage. This makes script mode ideal for companies that want to reuse established codebases without rewriting them.
Built-in algorithms require adopting AWS-provided implementations. SageMaker Canvas is a no-code tool, and JumpStart provides pretrained models and templates but does not focus on custom script reuse.
Therefore, Option D is the correct and AWS-recommended choice.
NEW QUESTION # 118
A company stores historical data in .csv files in Amazon S3. Only some of the rows and columns in the .csv files are populated. The columns are not labeled. An ML engineer needs to prepare and store the data so that the company can use the data to train ML models.
Select and order the correct steps from the following list to perform this task. Each step should be selected one time or not at all. (Select and order three.)
* Create an Amazon SageMaker batch transform job for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
* Use Amazon Athena to infer the schemas and available columns.
* Use AWS Glue crawlers to infer the schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.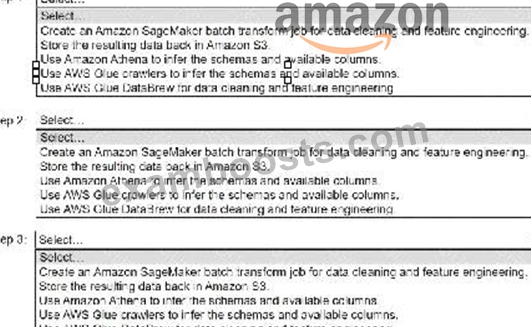
Answer:
Explanation: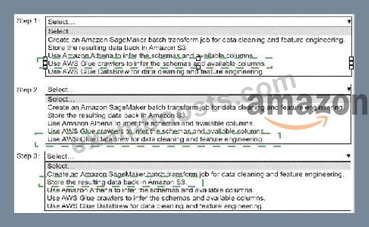
Explanation:
Step 1: Use AWS Glue crawlers to infer the schemas and available columns.Step 2: Use AWS Glue DataBrew for data cleaning and feature engineering.Step 3: Store the resulting data back in Amazon S3.
* Step 1: Use AWS Glue Crawlers to Infer Schemas and Available Columns
* Why?The data is stored in .csv files with unlabeled columns, and Glue Crawlers can scan the raw data in Amazon S3 to automatically infer the schema, including available columns, data types, and any missing or incomplete entries.
* How?Configure AWS Glue Crawlers to point to the S3 bucket containing the .csv files, and run the crawler to extract metadata. The crawler creates a schema in the AWS Glue Data Catalog, which can then be used for subsequent transformations.
* Step 2: Use AWS Glue DataBrew for Data Cleaning and Feature Engineering
* Why?Glue DataBrew is a visual data preparation tool that allows for comprehensive cleaning and transformation of data. It supports imputation of missing values, renaming columns, feature engineering, and more without requiring extensive coding.
* How?Use Glue DataBrew to connect to the inferred schema from Step 1 and perform data cleaning and feature engineering tasks like filling in missing rows/columns, renaming unlabeled columns, and creating derived features.
* Step 3: Store the Resulting Data Back in Amazon S3
* Why?After cleaning and preparing the data, it needs to be saved back to Amazon S3 so that it can be used for training machine learning models.
* How?Configure Glue DataBrew to export the cleaned data to a specific S3 bucket location. This ensures the processed data is readily accessible for ML workflows.
Order Summary:
* Use AWS Glue crawlers to infer schemas and available columns.
* Use AWS Glue DataBrew for data cleaning and feature engineering.
* Store the resulting data back in Amazon S3.
This workflow ensures that the data is prepared efficiently for ML model training while leveraging AWS services for automation and scalability.
NEW QUESTION # 119
A company is training a deep learning model to detect abnormalities in images. The company has limited GPU resources and a large hyperparameter space to explore. The company needs to test different configurations and avoid wasting computation time on poorly performing models that show weak validation accuracy in early epochs.
Which hyperparameter optimization strategy should the company use?
Answer: C
Explanation:
When GPU resources are limited and the hyperparameter search space is large, AWS documentation strongly recommends Bayesian optimization combined with early stopping. Bayesian optimization uses past evaluation results to intelligently select the next set of hyperparameters to test, focusing exploration on promising regions of the search space rather than testing all combinations.
In Amazon SageMaker, Bayesian optimization is the default and recommended strategy for hyperparameter tuning jobs. It significantly reduces the number of training runs required compared to grid or random search, making it highly cost-efficient for deep learning workloads.
Early stopping further improves efficiency by terminating training jobs that show poor validation performance in early epochs. This prevents wasted GPU time on configurations that are unlikely to perform well. AWS explicitly documents early stopping as a key feature for controlling training cost and duration.
Grid search and exhaustive search are computationally expensive and impractical for large hyperparameter spaces. Manual tuning is slow, error-prone, and does not scale.
By combining Bayesian optimization with early stopping, the company can rapidly converge on high- performing hyperparameter configurations while minimizing resource usage.
Therefore, Option B is the correct and AWS-aligned solution.
NEW QUESTION # 120
A company plans to use Amazon SageMaker AI to build image classification models. The company has 6 TB of training data stored on Amazon FSx for NetApp ONTAP. The file system is in the same VPC as SageMaker AI.
An ML engineer must make the training data accessible to SageMaker AI training jobs.
Which solution will meet these requirements?
Answer: B
Explanation:
Amazon SageMaker supports direct file system access for training jobs through Amazon FSx. AWS documentation states that FSx for NetApp ONTAP file systems can be mounted directly to SageMaker training instances when they are located in the same VPC.
Mounting the FSx file system allows SageMaker to stream large datasets efficiently without copying data into Amazon S3. This is ideal for very large datasets such as 6 TB of image data and avoids unnecessary storage duplication.
Options involving SageMaker Data Wrangler are intended for data preparation and exploration, not large- scale training data access. Mountpoint for Amazon S3 is not required and introduces additional complexity.
Therefore, Option A is the correct and AWS-aligned solution.
NEW QUESTION # 121
......
There is no doubt that among our three different versions of MLA-C01 guide torrent, the most prevalent one is PDF version, and this is particularly suitable and welcomed by youngsters. There are some features of this version: first of all, PDF version of our MLA-C01 prep guide can be printed into paper, though which you are able to do some note-writing and highlight the important exam points. There is an old saying goes, good memory is inferior to sodden ability to write, so we believe that it is a highly productive way for you to memory the knowledge point and review the reference books more effectively. Besides our MLA-C01 Exam Torrent support free demo download, as we mentioned before, it is an ideal way for you to be fully aware of our MLA-C01 prep guide and then purchasing them if suitable and satisfactory.
MLA-C01 Reliable Test Bootcamp: https://www.examboosts.com/Amazon/MLA-C01-practice-exam-dumps.html
BONUS!!! Download part of ExamBoosts MLA-C01 dumps for free: https://drive.google.com/open?id=1SD0IebydkTqeuZLFNESWwQNPJMx-ICjH