正確的なSnowflake DEA-C02無料ダウンロード &合格スムーズDEA-C02認定テキスト |素晴らしいDEA-C02受験料

BONUS!!! MogiExam DEA-C02ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1P3Dcb0SP5xLjHpK79vqqpmL1uiHMOnQh
Snowflakeの認定試験は最近ますます人気があるようになっています。IT認定試験は様々あります。どの試験を受験したことがありますか。たとえばDEA-C02認定試験などです。これらは全部大切な試験です。どちらを受験したいですか。ここで言いたいのはDEA-C02試験です。この試験を受けたいなら、MogiExamのDEA-C02問題集はあなたが楽に試験に合格するのを助けられます。
Snowflake DEA-C02 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|
| Data Ingestion and Consumption | 20% | - Data Unloading
- 1. Unloading to internal and external stages
- 2. Data export best practices
- 3. Partitioning unloading data
- Bulk Loading and Unloading
- 1. File format options (CSV, JSON, Parquet, AVRO)
- 2. COPY INTO command options and best practices
- 3. Data loading performance optimization
- 4. Handling staged files
- Continuous Data Loading
- 1. Snowpipe configuration and usage
- 2. Automating data loading with tasks
- 3. Real-time data ingestion patterns
|
| Performance Optimization | 15% | - Data Optimization
- 1. Search optimization service
- 2. Materialized views
- 3. Data cache management
- Query Optimization
- 1. Query profiling and analysis
- 2. Avoiding common performance pitfalls
- 3. Query result caching
- 4. Indexing strategies with clustering
- Warehouse Performance
- 1. Warehouse sizing and selection
- 2. Resource monitors
- 3. Multi-cluster warehouses
- 4. Warehouse scaling policies
|
| Security and Governance | 15% | - Governance and Compliance
- 1. Row access policies
- 2. Object tagging
- 3. Data retention policies
- 4. Access history and auditing
- Data Security
- 1. Column-level security
- 2. External tokenization
- 3. Row-level security policies
- 4. Data masking and tokenization
- Access Control
- 1. GRANT and REVOKE operations
- 2. Role-based access control (RBAC)
- 3. Role hierarchy and ownership
|
| Data Architecture and Processing | 20% | - Data Pipeline Design
- 1. Data scheduling and orchestration
- 2. Stream and task patterns
- 3. Pipeline monitoring and error handling
- Data Storage Architecture
- 1. Micro-partitioning and clustering
- 2. Table types (Permanent, Transient, Temporary)
- 3. Hybrid Tables concepts
- Data Modeling for Performance
- 1. Dimension handling
- 2. Star and snowflake schemas
- 3. Slowly changing dimensions (SCD)
|
| Data Transformation with Snowflake | 30% | - SQL Transformations
- 1. Working with semi-structured data (VARIANT)
- 2. Data type conversions and handling
- 3. Complex JOINs and set operations
- 4. Window functions advanced usage
- Data Processing Patterns
- 1. Zero-copy cloning for ETL
- 2. MERGE, UPDATE, DELETE operations
- 3. Time travel and change data capture
- Snowflake Scripting
- 1. Dynamic SQL
- 2. Procedures and control flow
- 3. Error handling
|
>> DEA-C02無料ダウンロード <<
DEA-C02認定テキスト & DEA-C02受験料
別の人の言い回しより自分の体験感じは大切なことです。我々の希望は誠意と専業化を感じられることですなので、お客様に無料のSnowflake DEA-C02問題集デモを提供します。購買の後、行き届いたアフタサービスを続けて提供します。Snowflake DEA-C02問題集を更新しるなり、あなたのメールボックスに送付します。あなたは一年間での更新サービスを楽しみにします。
Snowflake SnowPro Advanced: Data Engineer (DEA-C02) 認定 DEA-C02 試験問題 (Q101-Q106):
質問 # 101
You are tasked with building a data pipeline to process image metadata stored in JSON format from a series of URLs. The JSON structure contains fields such as 'image_url', 'resolution', 'camera_model', and 'location' (latitude and longitude). Your goal is to create a Snowflake table that stores this metadata along with a thumbnail of each image. Given the constraints that you want to avoid downloading and storing the images directly in Snowflake, and that Snowflake's native functions for image processing are limited, which of the following approaches would be most efficient and scalable?
- A. Create a Snowflake view that selects from a table containing the metadata URLs, using 'SYSTEM$URL GET to fetch the metadata. For each image URL found in the metadata, use a JavaScript UDF to generate a thumbnail. Embed the thumbnail into a VARCHAR column as a Base64 encoded string.
- B. Create a Python-based external function that fetches the JSON metadata and image from their respective URLs. The external function uses libraries like PIL (Pillow) to generate a thumbnail of the image and returns the metadata along with the thumbnail's Base64 encoded string within a JSON object.
- C. Create a Snowflake external table that points to an external stage which holds the JSON metadata files. Develop a spark process to fetch image URL, create thumbnails and store as base64 encoded strings in an external stage, create a view using the external table and generated thumbnails data
- D. Store just the 'image_url' in snowflake. Develop a separate application using any programming language to pre generate the thumbnails and host those at publicly accessible URLs. Within Snowflake, create a view to generate the links for image and thumbnail using 'CONCAT.
- E. Create a Snowflake stored procedure that iterates through each URL, downloads the JSON metadata using 'SYSTEM$URL_GET, extracts the image URL from the metadata, downloads the image using 'SYSTEM$URL_GET , generates a thumbnail using SQL scalar functions, and stores the metadata and thumbnail in a Snowflake table.
正解:B、D
解説:
Option C is the most appropriate solution. By using an external function with Python and libraries like PIL, you can efficiently handle image processing tasks that are difficult or impossible to perform natively within Snowflake. The external function encapsulates the image processing logic, keeping the Snowflake SQL code cleaner. Option E is also a valid solution as it leverages external processing. Option A is not performant as it tries to download image in snowflake which is not the best way to process image. Option B is not recommended because using JavaScript UDFs for binary data (images) can be inefficient. External Tables as described in Option D require pre-processing of data and storage to an external stage. Option D doesn't use the 'SYSTEM$URL GET' function that this question is trying to assess.
質問 # 102
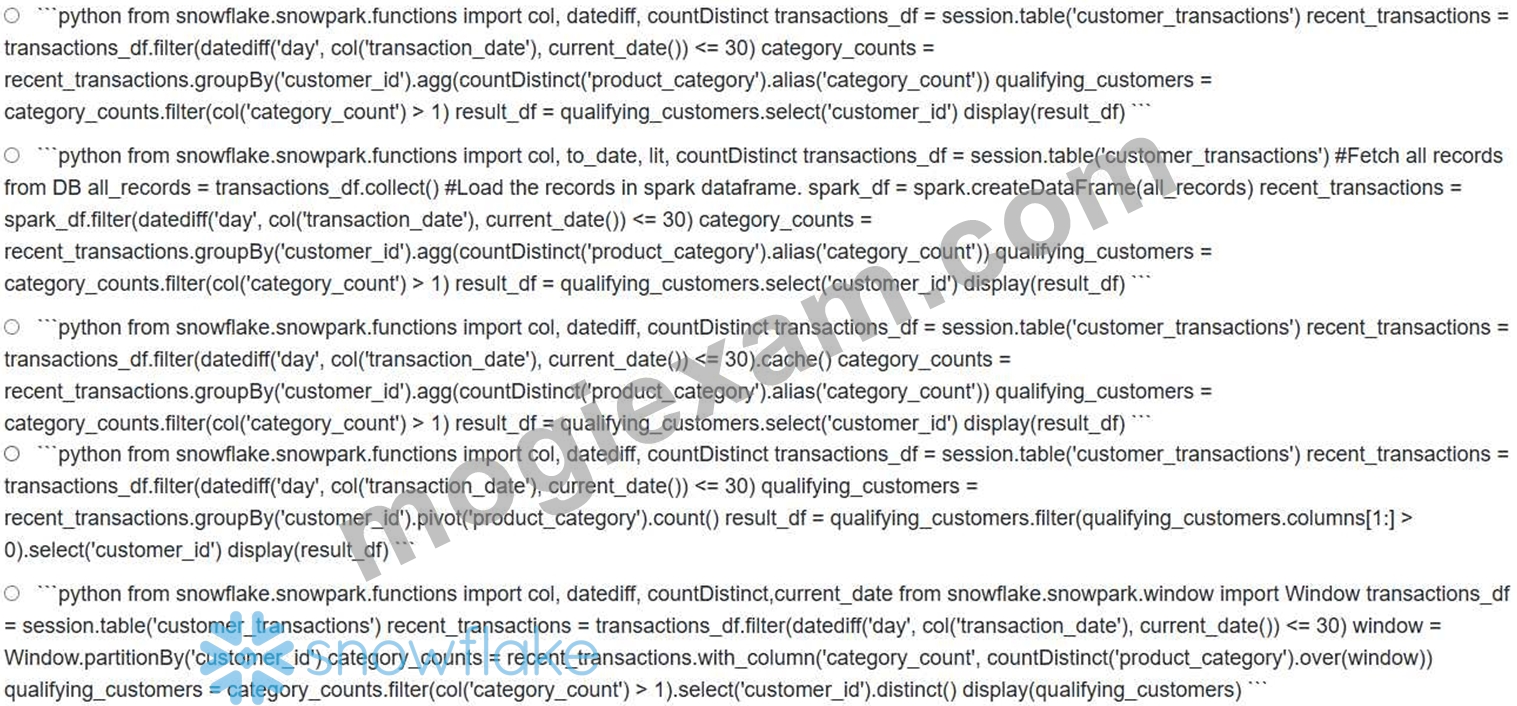
You are using Snowpark Python to perform data transformation on a large dataset stored in a Snowflake table named customer transactions'. This table contains columns such as 'customer id', 'transaction date', 'transaction amount', and product_category'. Your task is to identify customers who have made transactions in more than one product category within the last 30 days. Which of the following Snowpark Python snippets is the most efficient way to achieve this, minimizing data shuffling and maximizing query performance?
- A. Option C
- B. Option A
- C. Option D
- D. Option B
- E. Option E
正解:E
解説:
Option E is the most efficient. It filters the transactions within the last 30 days, uses a window function to calculate the distinct count of product categories per customer, and then filters to identify customers with more than one category. The use of window functions allows the aggregation to happen within Snowflake, minimizing data transfer and leveraging Snowflake's processing power. distinct at the end makes it unique.
質問 # 103
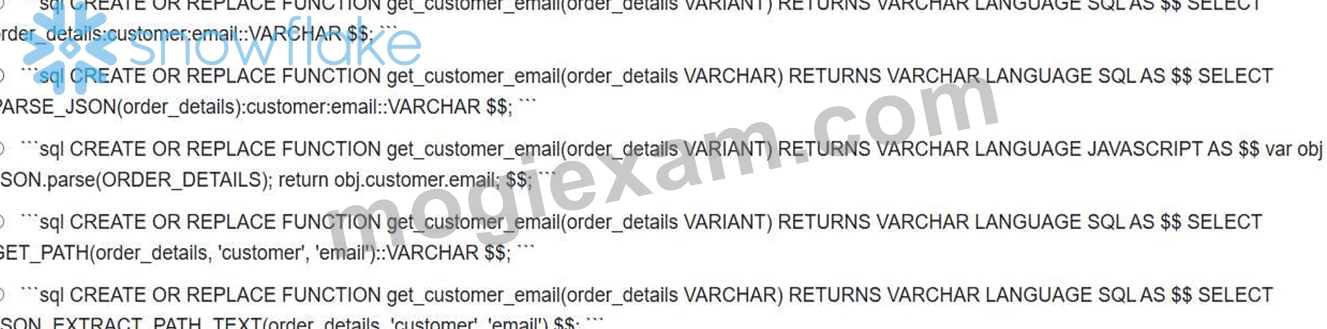
You have a Snowflake table called 'ORDERS' with a column named 'ORDER DETAILS that contains JSON data'. You need to create a UDF to extract a specific value from the JSON and return it. The JSON structure is consistent: '{'customer': {'name': 'John Doe', 'email': 'john.doe@example.com'}, 'items': [{'item id': 1, 'quantity': 2}, {'item id': 2, 'quantity': You want to extract the customer's email address. Which of the following UDF definitions is the most efficient and correct?
- A. Option C
- B. Option A
- C. Option E
- D. Option D
- E. Option B
正解:B
解説:
Option A is the most efficient and correct. Since the input is a VARIANT, Snowflake automatically parses the JSON. Using order_details:customer:email::VARCHAR directly accesses the nested fields in a performant manner within SQL. Using 'PARSE_JSON' when the input is already a VARIANT (Option B) is unnecessary and inefficient. Option C uses Javascript that while valid is slower than pure SQL solution when processing JSON. Option D using GET_PATH is valid, but not native to the syntax which is slightly less efficient. Option E is deprecated function that is no longer used, thus is invalid.
質問 # 104
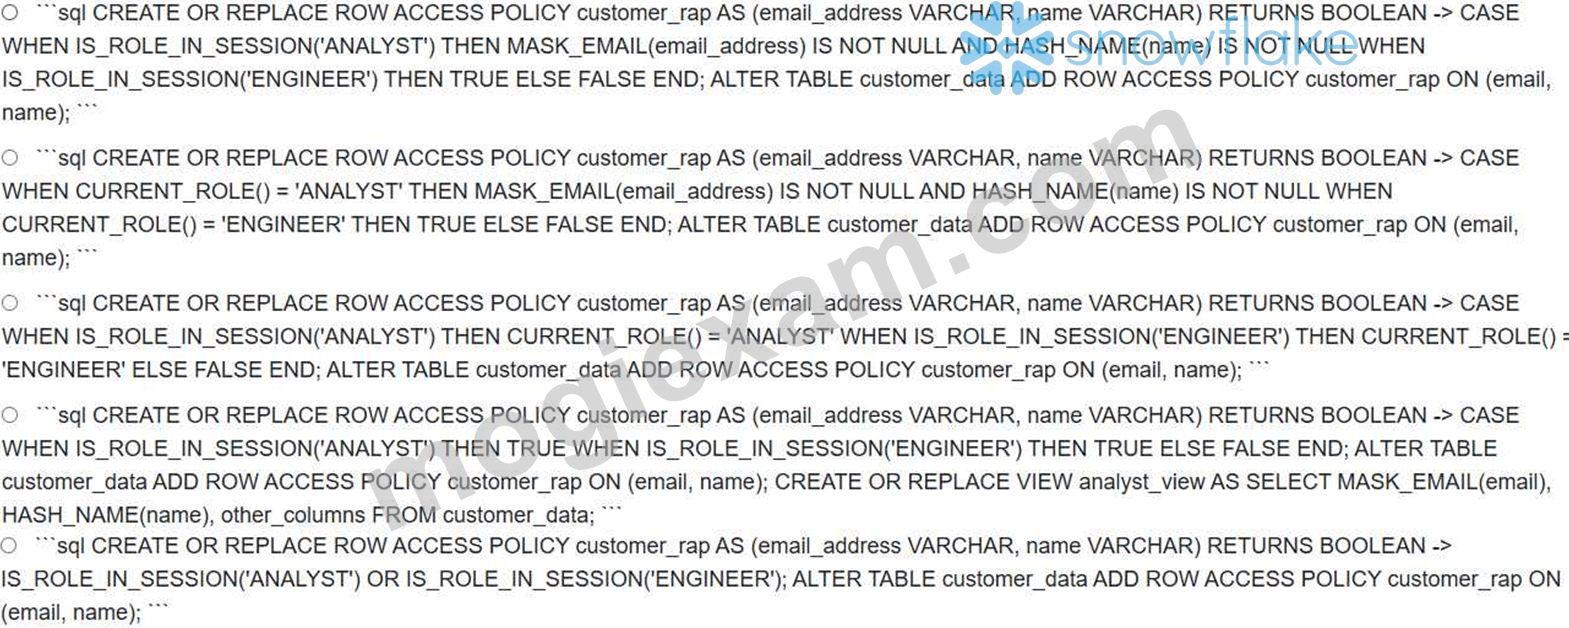
You are tasked with implementing a Row Access Policy (RAP) on a table 'customer_data' that contains Personally Identifiable Information (PII). The policy must meet the following requirements: 1. Data analysts with the 'ANALYST role should only see anonymized customer data (e.g., masked email addresses, hashed names). 2. Data engineers with the 'ENGINEER role should see the full, unmasked customer data for data processing purposes. 3. No other roles should have access to the data'. You create the following UDFs: 'MASK EMAIL(email address VARCHAR)': Returns an anonymized version of the email address. 'HASH NAME(name VARCHAR): Returns a hash of the customer name. Which of the following is the most efficient and secure way to implement this RAP, assuming minimal performance impact is desired?
- A. Option C
- B. Option A
- C. Option E
- D. Option B
- E. Option D
正解:E
解説:
Option D is the most efficient because it filters access based on roles in the RAP without applying expensive UDFs within the policy itself. This minimizes the performance impact of the RAP. The view 'analyst_view' then applies the masking/hashing for analysts. Options A and B apply the UDFs within the RAP, which will significantly degrade performance. The 'MASK EMAIL(email_address) IS NOT NULL' conditions are also incorrect as they are not validating the email. Option C doesn't implement the required masking/hashing for analysts at all, and also is not as effecient. Option E allows both roles to see all data which does not meet requirement 1.
質問 # 105
You are designing a data pipeline to ingest streaming data from Kafka into Snowflake. The data contains nested JSON structures representing customer orders. You need to transform this data and load it into a flattened Snowflake table named 'ORDERS FLAT'. Given the complexities of real-time data processing and the need for custom logic to handle certain edge cases within the JSON payload, which approach provides the MOST efficient and maintainable solution for transforming and loading this streaming data into Snowflake?
- A. Utilize a third-party ETL tool (like Apache Spark) to consume the data from Kafka, perform the JSON flattening and transformation logic, and then use the Snowflake connector to load the data into the 'ORDERS FLAT' table in batch mode.
- B. Use Snowflake's built-in JSON parsing functions within a Snowpipe COPY INTO statement, combined with a 'CREATE VIEW' statement on top of the loaded data. The view will use 'LATERAL FLATTEN' to present the data in the desired flattened structure without physically transforming the underlying data.
- C. Implement a custom external function (UDF) written in Java to parse and transform the JSON data before loading it into Snowflake. Configure Snowpipe to call this UDF during the data ingestion process. This UDF will flatten the JSON structure and return a tabular format directly insertable into 'ORDERS FLAT.
- D. Use Snowflake's Snowpipe with a COPY INTO statement that utilizes the 'STRIP OUTER ARRAY option to handle the JSON array, combined with a series of SQL queries with 'LATERAL FLATTEN' functions to extract the nested data after loading into a VARIANT column.
- E. Create a Python UDF that calls 'json.loads()' to parse the JSON within Snowflake and then use SQL commands with 'LATERAL FLATTEN' to navigate and extract the desired fields into a staging table. Afterward, use a separate SQL script to insert from staging to the final table 'ORDERS FLAT
正解:C
解説:
Option B offers the most efficient and maintainable solution. Using a Java UDF allows complex JSON parsing and transformation logic to be encapsulated and optimized. Calling the UDF directly from Snowpipe ensures efficient real-time processing during data ingestion. While other options can achieve the result, they often involve unnecessary steps or performance overhead (e.g., loading into a VARIANT column and then flattening with SQL, using external ETL tools for streaming ingestion, or creating views instead of physically transforming the data).
質問 # 106
......
MogiExamはIT認定試験のDEA-C02問題集を提供して皆さんを助けるウエブサイトです。MogiExamは先輩の経験を生かして暦年の試験の材料を編集することを通して、最高のDEA-C02問題集を作成しました。問題集に含まれているものは実際試験の問題を全部カバーすることができますから、あなたが一回で成功することを保証できます。
DEA-C02認定テキスト: https://www.mogiexam.com/DEA-C02-exam.html
- DEA-C02日本語pdf問題 😡 DEA-C02日本語版サンプル 🔮 DEA-C02資格勉強 📍 ➠ DEA-C02 🠰を無料でダウンロード➡ www.japancert.com ️⬅️で検索するだけDEA-C02日本語試験対策
- 効果的DEA-C02|ユニークなDEA-C02無料ダウンロード試験|試験の準備方法SnowPro Advanced: Data Engineer (DEA-C02)認定テキスト 🚙 ウェブサイト【 www.goshiken.com 】から➤ DEA-C02 ⮘を開いて検索し、無料でダウンロードしてくださいDEA-C02テスト内容
- DEA-C02 SnowPro Advanced: Data Engineer (DEA-C02)試験トレント、DEA-C02試験質問回答 🏯 { jp.fast2test.com }には無料の▷ DEA-C02 ◁問題集がありますDEA-C02日本語版サンプル
- 検証する-素敵なDEA-C02無料ダウンロード試験-試験の準備方法DEA-C02認定テキスト 🛰 今すぐ( www.goshiken.com )を開き、➽ DEA-C02 🢪を検索して無料でダウンロードしてくださいDEA-C02模擬練習
- ユニークDEA-C02|効率的なDEA-C02無料ダウンロード試験|試験の準備方法SnowPro Advanced: Data Engineer (DEA-C02)認定テキスト ❎ ➽ www.shikenpass.com 🢪で{ DEA-C02 }を検索して、無料でダウンロードしてくださいDEA-C02模擬モード
- 信頼的なDEA-C02無料ダウンロード一回合格-有難いDEA-C02認定テキスト ❗ ➥ www.goshiken.com 🡄サイトで{ DEA-C02 }の最新問題が使えるDEA-C02資格勉強
- DEA-C02日本語解説集 🆓 DEA-C02受験資格 🕤 DEA-C02日本語試験対策 👝 ( www.passtest.jp )で➠ DEA-C02 🠰を検索し、無料でダウンロードしてくださいDEA-C02資格勉強
- DEA-C02模擬練習 🔭 DEA-C02受験資格 👳 DEA-C02日本語版問題集 🏞 ➡ www.goshiken.com ️⬅️サイトにて➥ DEA-C02 🡄問題集を無料で使おうDEA-C02認定試験トレーリング
- DEA-C02試験の準備方法|正確的なDEA-C02無料ダウンロード試験|素敵なSnowPro Advanced: Data Engineer (DEA-C02)認定テキスト 💬 サイト[ www.jptestking.com ]で☀ DEA-C02 ️☀️問題集をダウンロードDEA-C02資格勉強
- DEA-C02テスト内容 🦗 DEA-C02受験対策書 🦛 DEA-C02資格トレーリング 🐕 ウェブサイト☀ www.goshiken.com ️☀️を開き、( DEA-C02 )を検索して無料でダウンロードしてくださいDEA-C02認定試験トレーリング
- 素晴らしいDEA-C02無料ダウンロードと便利なDEA-C02認定テキスト 📺 今すぐ「 www.it-passports.com 」を開き、【 DEA-C02 】を検索して無料でダウンロードしてくださいDEA-C02最新関連参考書
- findaspring.org, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! MogiExam DEA-C02ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1P3Dcb0SP5xLjHpK79vqqpmL1uiHMOnQh