DY0-001 New Test Bootcamp | DY0-001 Examcollection

DOWNLOAD the newest BraindumpsPass DY0-001 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1M7JFCytEORiA7jywqRmj0I3hlahkYL_y
Will you feel nervous while facing a real exam environment? If you do choose us, we will provide you the most real environment through the DY0-001 exam dumps. Our soft online test version will stimulate the real environment, through this, you will know the process of the real exam. DY0-001 Exam Dumps will build up your confidence as well as reduce the mistakes. If you need the practice just like this, just contact us.
CompTIA DY0-001 Exam Overview:
>> DY0-001 New Test Bootcamp <<
DY0-001 Examcollection | DY0-001 Exams Dumps
With BraindumpsPass user-friendly CompTIA DataAI Certification Exam (DY0-001) PDF format, you can prepare for the exam from any location at any time via laptops, tablets, and smartphones. In this CompTIA DY0-001 PDF document, we have included latest and DY0-001 Real Exam Questions. BraindumpsPass has made the DY0-001 PDF format to make it easier for students to acquire knowledge they need to ace the CompTIA exam.
| Topic | Details |
|---|
| Topic 1 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| Topic 2 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
| Topic 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| Topic 4 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| Topic 5 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
CompTIA DataAI Certification Exam Sample Questions (Q27-Q32):
NEW QUESTION # 27
A data scientist is standardizing a large data set that contains website addresses. A specific string inside some of the web addresses needs to be extracted. Which of the following is the best method for extracting the desired string from the text data?
- A. Large language model
- B. Named-entity recognition
- C. Find and replace
- D. Regular expressions
Answer: D
Explanation:
# Regular expressions (regex) are powerful tools for pattern matching in text. They are ideal for extracting substrings, such as domains, parameters, or specific keywords from URLs or structured text fields.
Why the other options are incorrect:
* B: NER is used to extract named entities (like names, places) - not substrings in structured text.
* C: LLMs are overkill and not efficient for simple string matching tasks.
* D: Find and replace is manual and non-scalable for large data sets.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 6.3:"Regular expressions provide a flexible method to extract patterns and substrings in structured or semi-structured text."
* Data Cleaning Handbook, Chapter 3:"Regex is the most effective tool for parsing text formats like URLs, emails, or custom tags."
-
NEW QUESTION # 28
An analyst is examining data from an array of temperature sensors and sees that one sensor consistently returns values that are much higher than the values from the other sensors. Which of the following terms best describes this type of error?
- A. Systematic
- B. Heteroskedastic
- C. Idiosyncratic
- D. Synthetic
Answer: A
Explanation:
# A systematic error is a consistent, repeatable error caused by faulty equipment or flawed measurement techniques. Since one sensor consistently over-reports values, this is a classic case of systematic error.
Why the other options are incorrect:
* A: Synthetic data is artificially generated - unrelated to sensor malfunction.
* C: Heteroskedasticity refers to non-constant variance - not consistent bias.
* D: Idiosyncratic errors are random and unpredictable - not consistent.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 1.4:"Systematic errors arise from consistent biases in measurement devices or methods, requiring calibration or correction."
-
NEW QUESTION # 29
Which of the following environmental changes is most likely to resolve a memory constraint error when running a complex model using distributed computing?
- A. Migrating to a cloud deployment
- B. Converting an on-premises deployment to a containerized deployment
- C. Moving model processing to an edge deployment
- D. Adding nodes to a cluster deployment
Answer: D
Explanation:
Increasing the number of nodes in your cluster directly expands the total available memory across the distributed system, alleviating memory‐constraint errors without changing your code or deployment paradigm. Containerization or edge deployments don't inherently provide more memory, and migrating to the cloud alone doesn't guarantee additional nodes unless you explicitly scale out.
NEW QUESTION # 30
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set:
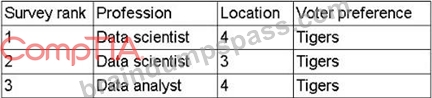
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
- A. In-sample data
- B. Extrapolated data
- C. Out-of-sample data
- D. Interpolated data
Answer: B
Explanation:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
NEW QUESTION # 31
A computer vision model is trained to identify cats on a training set that is composed of both cat and dog images. The model predicts a picture of a cat is a dog. Which of the following describes this error?
- A. Error due to reality
- B. Sampling error
- C. False positive error
- D. Type II error
Answer: D
Explanation:
Classifying an actual cat (positive instance) as a dog (negative prediction) is a false negative, which corresponds to a Type II error.
NEW QUESTION # 32
......
DY0-001 Examcollection: https://www.braindumpspass.com/CompTIA/DY0-001-practice-exam-dumps.html
- CompTIA DataAI Certification Exam Updated Study Material - DY0-001 Online Test Simulator - CompTIA DataAI Certification Exam Valid Exam Answers 🧭 Open website ➽ www.torrentvce.com 🢪 and search for [ DY0-001 ] for free download 🌎Test DY0-001 Questions Answers
- Downloadable DY0-001 PDF 🏃 DY0-001 Latest Test Camp 🦽 DY0-001 Test Prep 🙎 Search on { www.pdfvce.com } for ▶ DY0-001 ◀ to obtain exam materials for free download 🥒DY0-001 Training Tools
- Exam DY0-001 Certification Cost 🦪 DY0-001 Valid Vce ✡ DY0-001 Valid Vce 🚲 Download ⮆ DY0-001 ⮄ for free by simply searching on ➠ www.troytecdumps.com 🠰 🕛Test DY0-001 Questions Answers
- Trustworthy DY0-001 Pdf 🧽 DY0-001 Latest Test Camp 💬 DY0-001 Exam Pattern 🎉 Search for ➡ DY0-001 ️⬅️ and download it for free on 【 www.pdfvce.com 】 website 🌱Preparation DY0-001 Store
- Free PDF Quiz 2026 CompTIA High Hit-Rate DY0-001: CompTIA DataAI Certification Exam New Test Bootcamp ☕ Go to website ⮆ www.examcollectionpass.com ⮄ open and search for ➤ DY0-001 ⮘ to download for free 🔺DY0-001 Valid Vce
- DY0-001 Valid Exam Format 🙆 Test DY0-001 Questions Answers 🔘 DY0-001 Valid Vce 🧅 Go to website ▛ www.pdfvce.com ▟ open and search for 「 DY0-001 」 to download for free 💘DY0-001 Valid Real Test
- DY0-001 Test Dumps: CompTIA DataAI Certification Exam - DY0-001 Actual Exam Questions 🕥 Go to website ➡ www.testkingpass.com ️⬅️ open and search for 「 DY0-001 」 to download for free 🌔DY0-001 Latest Test Camp
- DY0-001 Test Dumps: CompTIA DataAI Certification Exam - DY0-001 Actual Exam Questions 💮 Simply search for ➥ DY0-001 🡄 for free download on ➥ www.pdfvce.com 🡄 💕DY0-001 Test Prep
- Hot DY0-001 New Test Bootcamp 100% Pass | High-quality DY0-001 Examcollection: CompTIA DataAI Certification Exam 🧸 Go to website ☀ www.prep4sures.top ️☀️ open and search for ▶ DY0-001 ◀ to download for free 🕣DY0-001 Training Courses
- Trustworthy DY0-001 Pdf 🏋 Test DY0-001 Questions Answers 🐱 DY0-001 Valid Vce 🌑 Open ➠ www.pdfvce.com 🠰 enter ➥ DY0-001 🡄 and obtain a free download 🎰DY0-001 Test Prep
- Exam DY0-001 Online 🔁 Downloadable DY0-001 PDF ⚾ New DY0-001 Mock Exam 📣 Search on 「 www.troytecdumps.com 」 for ⇛ DY0-001 ⇚ to obtain exam materials for free download 🥫New DY0-001 Mock Exam
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, mayagriffiths253.blogspot.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free & New DY0-001 dumps are available on Google Drive shared by BraindumpsPass: https://drive.google.com/open?id=1M7JFCytEORiA7jywqRmj0I3hlahkYL_y