BONUS!!! Download part of ITPassLeader AI-300 dumps for free: https://drive.google.com/open?id=1P0qZdkHRE8RTfdCLF63Yx0MeqIj0Yw-5
This is similar to the AI-300 desktop format but this is browser-based. It requires an active internet connection to run and is compatible with all browsers such as Google Chrome, Mozilla Firefox, Opera, MS Edge, Safari, Internet Explorer, and others. The Microsoft AI-300 Mock Exam helps you self-evaluate your Microsoft AI-300 exam preparation and mistakes. This way you improve consistently and attempt the AI-300 certification exam in an optimal way for excellent results in the exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 2: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Topic 3: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Topic 4: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
| Topic 5: Design and implement a GenAIOps infrastructure | 20–25% | - Set up Microsoft Foundry environment
|
Our AI-300 practice materials can be understood with precise content for your information, which will remedy your previous faults and wrong thinking of knowledge needed in this exam. As a result, many customers get manifest improvement and lighten their load by using our AI-300 Actual Exam. It is well-known that our AI-300 study guide can save a lot of time and effort. And with the simpilied content of our AI-300 practice questions, you can have a wonderful study experience as well.
NEW QUESTION # 139
You are preparing training data for a fine-tuning job in Microsoft Foundry.
Real production conversations cannot be used due to compliance requirements.
You need to generate synthetic interaction data that can be used for fine-tuning a generative model.
What should you do?
Answer: B
Explanation:
You can use a simulator or an LLM-as-a-judge pipeline to generate synthetic interaction data for fine-tuning. This technique is standard practice for maintaining strict data privacy while training models on specific business tasks.
Here is how to effectively structure and execute a synthetic data generation pipeline for Microsoft Azure AI Foundry (formerly Azure AI Studio).
Generation Methods
Persona-Driven Simulation: Prompt one LLM to act as a customer and another as your support agent to generate multi-turn dialogues.
Seed Data Expansion: Feed 10-20 hand-written, compliant examples into an LLM and instruct it to generate hundreds of diverse variations.
Schema-Based Evolution: Define variables (e.g., product types, user intents, sentiment levels) and programmatically combine them into prompt templates for an LLM to flesh out.
Reference:
https://www.digitaldividedata.com/blog/synthetic-data-generation-in-gen-ai
NEW QUESTION # 140
You create an Azure Machine Learning workspace.
You must use the Python SDK v2 to implement an experiment from a Jupiter notebook in the workspace. The experiment must log string metrics.
You need to implement the method to log the string metrics.
Which method should you use?
Answer: A
NEW QUESTION # 141
You manage an Azure Machine Learning workspace named Workspace1.
You plan to create a pipeline in the Azure Machine Learning Studio designer. The pipeline must include a custom component You need to ensure the custom component can be used in the pipeline. What should you do first.
Answer: E
Explanation:
Topic 1, Fabrikam Inc.Background
Fabrikam Inc. is a mid-sized healthcare analytics company that provides population health dashboards and predictive insights to regional hospital systems across the United States. Fabrikam Inc. customers rely on near real time analytics to monitor patient flow, staffing needs, and readmission risks. They use multiple traditional forecasting machine learning models for predictions. Fabrikam Inc. has an established Microsoft Azure footprint. The company uses Jupyter Notebooks that run on a local server as the primary development environment. The data science team is experiencing scalability, asset management and code management issues with the current development platform. Fabrikam Inc. plans to migrate to a cloud-based development environment to mitigate the issues.
Additionally, the company plans to implement a Retrieval-Augmented Generation (RAG)-based chat application for client support.
Leadership requires the application to be developed and deployed with a low operational risk.
Current Environment
Fabrikam Inc. operates a single Azure subscription that has the following components:
Azure Data Lake Storage Gen2 that contains de-identified clinical and operational datasets Azure AI Search indexing curated analytical documents and reference materials A small set of Python-based training scripts maintained by data scientists Azure OpenAI Service with deployed foundational models A Microsoft Foundry resource for building a RAG-based solution Evaluation data has manually defined expected responses.
The current challenges faced by the data science team include the following:
Model training jobs are run manually from notebooks.
Experiment tracking is inconsistent
Model versions are registered without standardized metadata.
Deployment is performed manually by data scientists, with limited rollback capability.
The team has no standardized evaluation process for generative AI outputs.
The environment currently allows public network access. Authentication relies on user accounts rather than managed identities.
Compute targets are manually created and shared across experiments. This has led to resource contention during peak usage.
Business Requirements
Fabrikam Inc. has the following business requirements for the modernization initiative:
Provide a conversational interface that answers analytics questions by using internal documents and datasets.
Ensure that sensitive healthcare-related data is not exposed outside the Fabrikam Inc. Azure tenant.
Enable repeatable and auditable model training and deployment processes.
Support experimentation to compare prompt strategies and fine-tuned models.
Align the model with the ranked preferences and optimize behavior for the long term.
Minimize disruption to existing analytics workloads during rollout.
Technical Requirements
To support the business goals, Fabrikam Inc. identifies these technical requirements:
Use Azure Machine Learning workspaces to centrally manage data assets, models, and environments.
Implement experiment tracking and model versioning for all training jobs.
Orchestrate training and evaluation by using pipelines rather than manually running notebooks.
Deploy traditional machine learning models with support for staged rollout and rollback.
Improve RAG-based solution output quality.
Use the existing evaluation datasets that are based on real data with input-output pairs.
Apply advanced fine-tuning techniques only when prompt engineering is insufficient Issues and Constraints Fabrikam Inc. must comply with internal security policies that require the company to restrict network access and avoid long-lived secrets. The data science team has limited Azure DevOps experience, so solutions must favor managed services and automation over custom infrastructure.
Cost predictability is important. Leadership prefers serverless or managed compute options where possible but is willing to approve dedicated compute for stable production workloads.
Problem Statement
Fabrikam Inc. must design and implement an Azure-based AI operations solution that enables reliable training, evaluation, deployment, and iteration of generative AI models. The solution must support experimentation and gradual rollout while ensuring governance, security, and operational stability. The data science and platform teams must collaborate to deliver this solution by using Azure Machine Learning and Microsoft Foundry capabilities.
NEW QUESTION # 142
You manage an Azure Machine Learning workspace named workspace1 by using the Python SDK v2.
The default datastore of workspace1 contains a folder named sample_data.
The folder structure contains the following content:
You write Python SDK v2 code to materialize the data from the files in the sample_data folder into a Pandas data frame.
You need to complete the Python SDK v2 code to use the MLTable folder as the materialization blueprint.
How should you complete the code? To answer, select the appropriate options in the answer area. NOTE:
Each correct selection is worth one point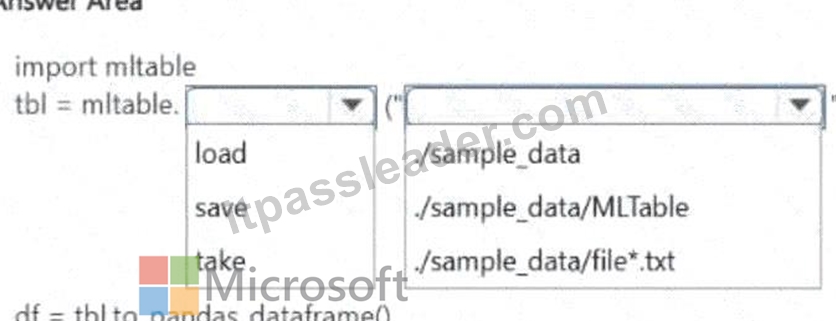
Answer:
Explanation:
Explanation:
The MLTable format in Azure Machine Learning Python SDK v2 is a structured abstraction over tabular data sources. It stores a YAML file alongside data files, describing how to read and transform the data. To materialize this into a Pandas DataFrame, you use the mltable library: first call mltable.load with the path to the MLTable folder to load the definition, then call to_pandas_dataframe() on the returned object. The path parameter should point to the folder containing the MLTable YAML file on the default datastore. MLTable abstracts the storage location and transformation steps, making the code storage-agnostic - the same code works whether data lives in Blob Storage, ADLS Gen2, or a local path. The SDK v2 approach with MLTable is the recommended pattern for governed, reusable data access in Azure Machine Learning.
Microsoft Learn Reference Topic: Create and use MLTable data assets in Azure Machine Learning Python SDK v2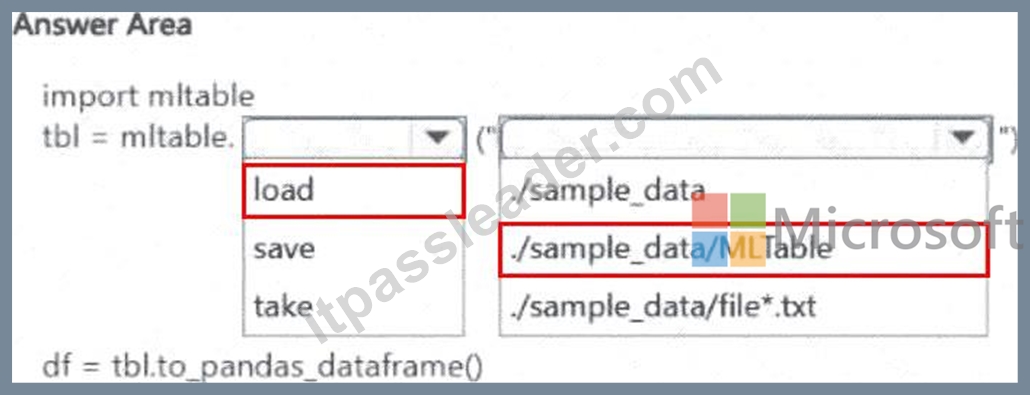
NEW QUESTION # 143
Drag and Drop Question
You have a Microsoft Foundry project with a connected Azure OpenAI Service model.
You have a set of text files stored locally on your computer.
You must set up a flow that will generate responses based on the content of your local files.
You need to implement a solution.
Which four actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.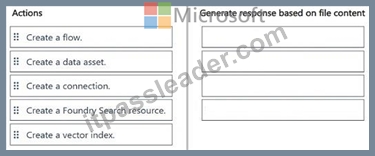
Answer:
Explanation:
NEW QUESTION # 144
......
For complete, comprehensive, and instant Operationalizing Machine Learning and Generative AI Solutions AI-300 exam preparation, the Microsoft AI-300 Exam Questions are the right choice. ITPassLeader offers reliable new exam format,exam dumps demo and valid exam online help customers pass the Operationalizing Machine Learning and Generative AI Solutions AI-300 easily.
Relevant AI-300 Questions: https://www.itpassleader.com/Microsoft/AI-300-dumps-pass-exam.html
2026 Latest ITPassLeader AI-300 PDF Dumps and AI-300 Exam Engine Free Share: https://drive.google.com/open?id=1P0qZdkHRE8RTfdCLF63Yx0MeqIj0Yw-5