Databricks-Certified-Data-Analyst-Associate試験対策書、Databricks-Certified-Data-Analyst-Associate日本語対策問題集

さらに、CertJuken Databricks-Certified-Data-Analyst-Associateダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1phq0jkpoJLbq9OKXYk-e3uMzup9BsyB4
CertJukenのIT専門家たちは受験生の皆さんのニーズを満たすように彼らの豊富な知識と経験を活かして試験トレーニング資料の品質をずっと高めています。受験生の皆さんが一回でDatabricksのDatabricks-Certified-Data-Analyst-Associate試験に合格することを保証します。CertJukenの製品を購入したら、あなたはいつでも最新かつ最正確な試験情報を得ることができます。CertJukenの資料のカバー率が高くて、受験生に便宜を与えられます。それに、問題集の合格率が100パーセントに達するのですから、あなたは安心に試験を受けることができます。
Databricks Databricks-Certified-Data-Analyst-Associate 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - 分析アプリケーション:統計分布の重要なポイント、データ拡張、そして2つのソースアプリケーション間のデータブレンディングについて説明します。さらに、ラストマイルETL、データブレンディングが効果的なシナリオ、主要な統計指標、記述統計、離散統計と連続統計についても説明します。
|
| トピック 2 | - データの視覚化とダッシュボード:このトピックのサブトピックでは、通知の送信方法、基本的なアラートの設定とトラブルシューティングの方法、更新スケジュールの設定方法、ダッシュボードを共有するメリットとデメリット、クエリパラメータによる出力の変化、すべての視覚化の色の変更方法について説明します。また、カスタマイズされたデータ視覚化、視覚化のフォーマット、クエリベースのドロップダウンリスト、ダッシュボードの共有方法についても説明します。
|
| トピック 3 | - Lakehouse における SQL:データベースからデータを取得するクエリ、SELECT クエリの出力、ANSI SQL の利点、アクセス、そしてシルバーレベルのデータのクリーンアップについて説明します。また、MERGE INTO、INSERT TABLE、COPY INTO を比較対照します。最後に、一般的なスケーリングシナリオにおける UDF の作成と適用に焦点を当てます。
|
| トピック 4 | - Databricks SQL:このトピックでは、主要な対象ユーザーと副次的な対象ユーザー、Databricks SQL の利点、基本的な Databricks SQL クエリの補完、スキーマブラウザー、Databricks SQL ダッシュボード、そして Databricks SQL エンドポイント
- ウェアハウスの目的について説明します。さらに、サーバーレス Databricks SQL エンドポイント
- ウェアハウス、Databricks SQL エンドポイント
- ウェアハウスのクラスターサイズとコストのトレードオフ、そして Partner Connect についても詳しく説明します。最後に、小さなファイルのアップロード、Databricks SQL と視覚化ツールの接続、メダリオンアーキテクチャ、ゴールドレイヤー、そしてストリーミングデータを扱う利点について説明します。
|
| トピック 5 | - データ管理:このトピックでは、データファイル管理ツールとしてのDelta Lake、Delta Lakeによるテーブルメタデータの管理、LakehouseにおけるDelta Lakeの利点、Databricks上のテーブル、テーブル所有者の責任、そしてデータの永続性について説明します。また、テーブルの管理、テーブル所有者によるData Explorerの使用、そして組織固有のPIIデータに関する考慮事項についても説明します。最後に、LOCATIONキーワードの変化と、データセキュリティを確保するためのData Explorerの使用法についても説明します。
|
>> Databricks-Certified-Data-Analyst-Associate試験対策書 <<
Databricks-Certified-Data-Analyst-Associate試験資料、Databricks-Certified-Data-Analyst-Associate試験問題、Databricks-Certified-Data-Analyst-Associate試験通過率
弊社のDatabricks-Certified-Data-Analyst-Associate練習資料は、さまざまな学位の受験者に適しています。この受験者は、この分野の知識のレベルに関係なく互換性があります。 これらのDatabricks Certified Data Analyst Associate Examトレーニング資料は、当社にとって名誉あるものであり、お客様の目標を達成するための最大の特権として扱っています。 一方、理論と実践を離婚することはできませんが、心配する必要はありません。刺激テストの質問があり、学習と実践の両方を同時に行うことができます。 私たちの知る限り、Databricks-Certified-Data-Analyst-Associate試験準備は何百万人もの受験者に夢を追いかけ、より効率的に学習するように動機付けました。 Databricks-Certified-Data-Analyst-Associateの練習資料は、あなたを失望させません。
Databricks Certified Data Analyst Associate Exam 認定 Databricks-Certified-Data-Analyst-Associate 試験問題 (Q62-Q67):
質問 # 62
A data analyst runs the following command:
INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers;
What is the result of running this command?
- A. The command fails because it is written incorrectly.
- B. The suppliers table now contains both the data it had before the command was run and the data from the new suppliers table, and any duplicate data is deleted.
- C. The suppliers table now contains only the data from the new suppliers table.
- D. The suppliers table now contains both the data it had before the command was run and the data from the new suppliers table, including any duplicate data.
- E. The suppliers table now contains the data from the new suppliers table, and the new suppliers table now contains the data from the suppliers table.
正解:A
解説:
The command INSERT INTO stakeholders.suppliers TABLE stakeholders.new_suppliers is not a valid syntax for inserting data into a table in Databricks SQL. According to the documentation12, the correct syntax for inserting data into a table is either:
* INSERT { OVERWRITE | INTO } [ TABLE ] table_name [ PARTITION clause ] [ ( column_name [,
...] ) | BY NAME ] query
* INSERT INTO [ TABLE ] table_name REPLACE WHERE predicate query
The command in the question is missing the OVERWRITE or INTO keyword, and the query part that specifies the source of the data to be inserted. The TABLE keyword is optional and can be omitted.
The PARTITION clause and the column list are also optional and depend on the table schema and the data source. Therefore, the command in the question will fail with a syntax error.
INSERT | Databricks on AWS
INSERT - Azure Databricks - Databricks SQL | Microsoft Learn
質問 # 63
A data analyst creates a Databricks SQL Query where the result set has the following schema:
region STRING
number_of_customer INT
When the analyst clicks on the "Add visualization" button on the SQL Editor page, which of the following types of visualizations will be selected by default?
- A. Histogram
- B. Line Chart
- C. There is no default. The user must choose a visualization type.
- D. Violin Chart
- E. IBar Chart
正解:E
解説:
According to the Databricks SQL documentation, when a data analyst clicks on the "Add visualization" button on the SQL Editor page, the default visualization type is Bar Chart. This is because the result set has two columns: one of type STRING and one of type INT. The Bar Chart visualization automatically assigns the STRING column to the X-axis and the INT column to the Y-axis. The Bar Chart visualization is suitable for showing the distribution of a numeric variable across different categories. Reference: Visualization in Databricks SQL, Visualization types
質問 # 64
In which of the following scenarios should a data engineer select a Task in the Depends On field of a new Databricks Job Task?
- A. When another task needs to use as little compute resources as possible.
- B. When another task has the same dependency libraries as the new task.
- C. When another task needs to be replaced by the new task.
- D. When another task needs to fail before the new task begins.
- E. When another task needs to successfully complete before the new task begins.
正解:E
解説:
Option E is correct. The Depends On field is used to define task dependencies in a Databricks job, so a downstream task waits for an upstream task according to the dependency rules. The standard use case is when one task must complete successfully before the next task starts. Official Databricks extract: "You can control the execution order of tasks by specifying dependencies between them," and Databricks runs upstream tasks before downstream tasks.
質問 # 65
A data scientist has asked a data analyst to create histograms for every continuous variable in a data set. The data analyst needs to identify which columns are continuous in the data set.
What describes a continuous variable?
- A. A categorical variable in which the number of categories continues to increase over time
- B. A quantitative variable that can take on an uncountable set of values
- C. A quantitative variable that never stops changing
- D. A quantitative variable Chat can take on a finite or countably infinite set of values
正解:B
解説:
A continuous variable is a type of quantitative variable that can assume an infinite number of values within a given range. This means that between any two possible values, there can be an infinite number of other values. For example, variables such as height, weight, and temperature are continuous because they can be measured to any level of precision, and there are no gaps between possible values. This is in contrast to discrete variables, which can only take on specific, distinct values (e.g., the number of children in a family). Understanding the nature of continuous variables is crucial for data analysts, especially when selecting appropriate statistical methods and visualizations, such as histograms, to accurately represent and analyze the data.
質問 # 66
A data engineer is working with a nested array column products in table transactions. They want to expand the table so each unique item in products for each row has its own row where the transaction_id column is duplicated as necessary.
They are using the following incomplete command:
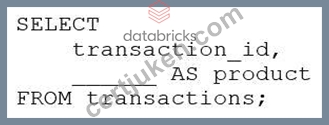
Which of the following lines of code can they use to fill in the blank in the above code block so that it successfully completes the task?
- A. array distinct(produces)
- B. array(produces)
- C. explode(produces)
- D. reduce(produces)
- E. flatten(produces)
正解:C
解説:
The explode function is used to transform a DataFrame column of arrays or maps into multiple rows, duplicating the other column's values. In this context, it will be used to expand the nested array column products in the transactions table so that each unique item in products for each row has its own row and the transaction_id column is duplicated as necessary. References: Databricks Documentation I also noticed that you sent me an image along with your message. The image shows a snippet of SQL code that is incomplete. It begins with "SELECT" indicating a query to retrieve data. "transaction_id," suggests that transaction_id is one of the columns being selected. There are blanks indicated by underscores where certain parts of the SQL command should be, including what appears to be an alias for a column and part of the FROM clause. The query ends with "FROM transactions;" indicating data is being selected from a
'transactions' table.
If you are interested in learning more about Databricks Data Analyst Associate certification, you can check out the following resources:
* Databricks Certified Data Analyst Associate: This is the official page for the certification exam, where you can find the exam guide, registration details, and preparation tips.
* Data Analysis With Databricks SQL: This is a self-paced course that covers the topics and skills required for the certification exam. You can access it for free on Databricks Academy.
* Tips for the Databricks Certified Data Analyst Associate Certification: This is a blog post that provides some useful advice and study tips for passing the certification exam.
* Databricks Certified Data Analyst Associate Certification: This is another blog post that gives an overview of the certification exam and its benefits.
質問 # 67
......
もしあなたはまだ合格のためにDatabricks Databricks-Certified-Data-Analyst-Associateに大量の貴重な時間とエネルギーをかかって一生懸命準備し、Databricks Databricks-Certified-Data-Analyst-Associate「Databricks Certified Data Analyst Associate Exam」認証試験に合格するの近道が分からなくって、今はCertJukenが有効なDatabricks Databricks-Certified-Data-Analyst-Associate認定試験の合格の方法を提供して、君は半分の労力で倍の成果を取るの与えています。
Databricks-Certified-Data-Analyst-Associate日本語対策問題集: https://www.certjuken.com/Databricks-Certified-Data-Analyst-Associate-exam.html
- Databricks-Certified-Data-Analyst-Associate合格率書籍 💹 Databricks-Certified-Data-Analyst-Associate日本語版受験参考書 🦌 Databricks-Certified-Data-Analyst-Associate模擬対策問題 🥐 検索するだけで【 www.japancert.com 】から▛ Databricks-Certified-Data-Analyst-Associate ▟を無料でダウンロードDatabricks-Certified-Data-Analyst-Associate試験準備
- Databricks-Certified-Data-Analyst-Associate日本語対策問題集 🦑 Databricks-Certified-Data-Analyst-Associate問題集無料 🤝 Databricks-Certified-Data-Analyst-Associate試験準備 🥱 ⮆ www.goshiken.com ⮄で“ Databricks-Certified-Data-Analyst-Associate ”を検索して、無料で簡単にダウンロードできますDatabricks-Certified-Data-Analyst-Associate試験復習赤本
- Databricks-Certified-Data-Analyst-Associate模擬対策問題 🏡 Databricks-Certified-Data-Analyst-Associate練習問題集 🔆 Databricks-Certified-Data-Analyst-Associate試験復習赤本 🔡 ➽ www.shikenpass.com 🢪サイトにて最新➤ Databricks-Certified-Data-Analyst-Associate ⮘問題集をダウンロードDatabricks-Certified-Data-Analyst-Associate日本語版受験参考書
- Databricks-Certified-Data-Analyst-Associate日本語版対策ガイド 🛄 Databricks-Certified-Data-Analyst-Associate試験攻略 🐗 Databricks-Certified-Data-Analyst-Associate日本語関連対策 🏹 最新《 Databricks-Certified-Data-Analyst-Associate 》問題集ファイルは⮆ www.goshiken.com ⮄にて検索Databricks-Certified-Data-Analyst-Associate試験攻略
- Databricks-Certified-Data-Analyst-Associate問題集無料 🎣 Databricks-Certified-Data-Analyst-Associate日本語参考 🕐 Databricks-Certified-Data-Analyst-Associate日本語対策問題集 🥬 “ www.passtest.jp ”サイトにて⮆ Databricks-Certified-Data-Analyst-Associate ⮄問題集を無料で使おうDatabricks-Certified-Data-Analyst-Associate練習問題集
- タイトル:Databricks Certified Data Analyst Associate Exam試験テストエンジン、Databricks-Certified-Data-Analyst-Associate予備資料、Databricks Certified Data Analyst Associate Exam模擬試験 👫 ⏩ www.goshiken.com ⏪で[ Databricks-Certified-Data-Analyst-Associate ]を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Analyst-Associate試験準備
- 実際的なDatabricks-Certified-Data-Analyst-Associate試験対策書試験-試験の準備方法-高品質なDatabricks-Certified-Data-Analyst-Associate日本語対策問題集 😙 ➽ Databricks-Certified-Data-Analyst-Associate 🢪の試験問題は➡ www.mogiexam.com ️⬅️で無料配信中Databricks-Certified-Data-Analyst-Associate日本語参考
- Databricks-Certified-Data-Analyst-Associate資料的中率 🔫 Databricks-Certified-Data-Analyst-Associate日本語版受験参考書 ⚪ Databricks-Certified-Data-Analyst-Associate過去問無料 🔊 今すぐ☀ www.goshiken.com ️☀️で「 Databricks-Certified-Data-Analyst-Associate 」を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Analyst-Associate試験復習赤本
- 完璧Databricks Databricks-Certified-Data-Analyst-Associate|信頼的なDatabricks-Certified-Data-Analyst-Associate試験対策書試験|試験の準備方法Databricks Certified Data Analyst Associate Exam日本語対策問題集 🎋 ⮆ www.goshiken.com ⮄に移動し、➤ Databricks-Certified-Data-Analyst-Associate ⮘を検索して、無料でダウンロード可能な試験資料を探しますDatabricks-Certified-Data-Analyst-Associate日本語解説集
- 高品質Databricks-Certified-Data-Analyst-Associate試験対策書 | 最初の試行で簡単に勉強して試験に合格する - 信頼できるDatabricks-Certified-Data-Analyst-Associate: Databricks Certified Data Analyst Associate Exam 🍺 今すぐ{ www.goshiken.com }で➠ Databricks-Certified-Data-Analyst-Associate 🠰を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Analyst-Associate日本語版受験参考書
- 完璧Databricks Databricks-Certified-Data-Analyst-Associate|信頼的なDatabricks-Certified-Data-Analyst-Associate試験対策書試験|試験の準備方法Databricks Certified Data Analyst Associate Exam日本語対策問題集 ☁ 「 www.xhs1991.com 」サイトにて➽ Databricks-Certified-Data-Analyst-Associate 🢪問題集を無料で使おうDatabricks-Certified-Data-Analyst-Associate過去問無料
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, camp-fire.jp, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、CertJuken Databricks-Certified-Data-Analyst-Associateダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1phq0jkpoJLbq9OKXYk-e3uMzup9BsyB4