2026 Latest EduDump DP-700 PDF Dumps and DP-700 Exam Engine Free Share: https://drive.google.com/open?id=1eY-GRafL-bfN2yQ_bBHvs5bFUjn6eS8h
Are you planning to crack the Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric DP-700 certification test in a short time and don't know how to prepare for it? EduDump has updated DP-700 Dumps questions for the applicants who want to prepare for the Microsoft DP-700 Certification test successfully within a few days. This study material is available in three different formats that you can trust to crack the Microsoft DP-700 certification test with ease.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Data Engineering Solutions Using Microsoft Fabric |
| Exam Number: | DP-700 |
| Certificate Validity Period: | 1 year |
| Available Languages: | Portuguese (Brazil), English, Korean, Spanish, Japanese, Chinese (Simplified), French, German |
| Passing Score: | 700 (scaled score 100–1000) |
| Real Exam Qty: | 50–60 |
| Exam Duration: | 100 minutes |
| Related Certifications: | Microsoft Certified: Power BI Data Analyst Associate Microsoft Certified: Azure Data Engineer Associate |
| Exam Price: | $165 USD |
| Exam Format: | Interactive items, Case studies, Multiple select, Multiple choice, Scenario-based |
| Recommended Training: | Microsoft Learn: Implementing Data Engineering Solutions Using Microsoft Fabric Microsoft Fabric Documentation |
| Exam Registration: | Microsoft Official Exam Registration Pearson VUE Registration |
| Sample Questions: | Microsoft DP-700 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No mandatory prerequisites; recommended experience with data integration, transformation, SQL, PySpark, KQL, and Microsoft Fabric |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-700 |
>> Authorized DP-700 Test Dumps <<
Our passing rate is very high to reach 99% and our DP-700 exam torrent also boost high hit rate. Our DP-700 study questions are compiled by authorized experts and approved by professionals with years of experiences. They are compiled according to the latest development conditions in the theory and practice and the questions and answers are based on real exam. Our DP-700 study questions are linked tightly with the exam papers in the past and conform to the popular trend in the industry. Our product convey you more important information with less amount of the questions and answers. Thus we can be sure that our DP-700 guide torrent are of high quality and can help you pass the exam with high probability.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 99
You have a Fabric workspace that contains an eventhouse and a KQL database named Database1. Database1 has the following:
A table named Table1
A table named Table2
An update policy named Policy1
Policy1 sends data from Table1 to Table2.
The following is a sample of the data in Table2.
Recently, the following actions were performed on Table1:
An additional element named temperature was added to the StreamData column.
The data type of the Timestamp column was changed to date.
The data type of the DeviceId column was changed to string.
You plan to load additional records to Table2.
Which two records will load from Table1 to Table2? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.


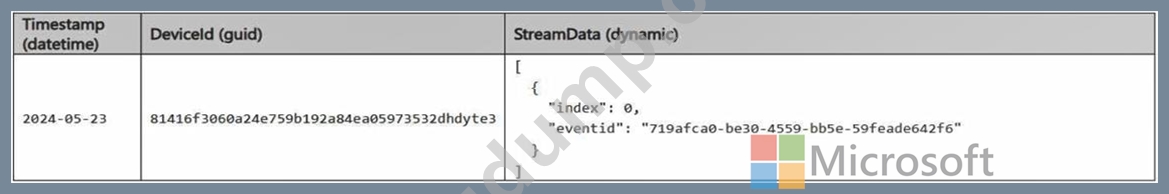

Answer: B,D
Explanation:
Changes to Table1 Structure:
StreamData column: An additional temperature element was added.
Timestamp column: Data type changed from datetime to date.
DeviceId column: Data type changed from guid to string.
Impact of Changes:
Only records that comply with Table2's structure will load.
Records that deviate from Table2's column data types or structure will be rejected.
Record B:
Timestamp: Matches Table2 (datetime format).
DeviceId: Matches Table2 (guid format).
StreamData: Contains only the index and eventid, which matches Table2.
Accepted because it fully matches Table2's structure and data types.
Record D:
Timestamp: Matches Table2 (datetime format).
DeviceId: Matches Table2 (guid format).
StreamData: Matches Table2's structure.
Accepted because it fully matches Table2's structure and data types.
NEW QUESTION # 100
You have a Fabric workspace named Workspace1 that is connected to a GitHub repository named repo1.
Workspace1 contains the items shown in the following table.
You modify Semantic model 1, Semanticmodel2, and Report2.
You need to commit the changes to repo1.
What is the minimum number of commits you should perform?
Answer: A
NEW QUESTION # 101
You have an Azure subscription that contains a blob storage account named sa1. Sa1 contains two files named Filelxsv and File2.csv.
You have a Fabric tenant that contains the items shown in the following table.
You need to configure Pipeline1 to perform the following actions:
* At 2 PM each day, process Filel.csv and load the file into flhl.
* At 5 PM each day. process File2.csv and load the file into flhl.
The solution must minimize development effort. What should you use?
Answer: A
NEW QUESTION # 102
You plan to use Apache Spark to process the data in Lakehouse1.
You need to configure the workspace to ensure that users can share Spark cluster resources across notebooks.
The solution must ensure that variables and code execution in one notebook remain isolated from those in other notebooks.
What should you do?
Answer: A
Explanation:
The correct configuration is high concurrency mode . High concurrency enables multiple compatible Fabric notebooks to share the resources of an existing Spark application rather than requiring a separate Spark application for every notebook. This improves Spark resource utilization and substantially reduces session startup overhead.
Critically, sharing the Spark application does not mean that notebook execution state is merged. Microsoft Fabric assigns each workload its own REPL core within the shared Spark application. Each REPL core maintains isolated execution state, which prevents local variables or code execution in one notebook from overwriting the execution state of another notebook. This directly satisfies the requirement for both resource sharing and notebook-level isolation. Microsoft Learn For notebooks to share a high-concurrency session, Microsoft specifies compatibility requirements such as the same user boundary, default lakehouse, Spark compute configuration, and appropriate library configuration.
Microsoft Learn
Autoscaling changes the number of executors allocated according to workload demand but does not provide notebook session sharing. The native execution engine is intended to improve Spark execution performance rather than enable concurrent notebook isolation. Per-notebook environment configuration likewise does not provide the required shared Spark session architecture.
Study Guide reference: Monitor and optimize an analytics solution # Configure and optimize Spark # high concurrency sessions # Spark resource utilization and workload isolation.
NEW QUESTION # 103
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a KQL database that contains two tables named Stream and Reference. Stream contains streaming data in the following format.
Reference contains reference data in the following format.
Both tables contain millions of rows.
You have the following KQL queryset.
You need to reduce how long it takes to run the KQL queryset.
Solution: You change project to extend.
Does this meet the goal?
Answer: A
Explanation:
Using extend retains all columns in the table, potentially increasing the size of the output unnecessarily.
project is more efficient because it selects only the required columns.
NEW QUESTION # 104
......
DP-700 Valid Mock Exam: https://www.edudump.com/exams/Microsoft/DP-700/
What's more, part of that EduDump DP-700 dumps now are free: https://drive.google.com/open?id=1eY-GRafL-bfN2yQ_bBHvs5bFUjn6eS8h