Databricks-Certified-Professional-Data-Engineer模擬体験、Databricks-Certified-Professional-Data-Engineer認定テキスト
P.S.JpshikenがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=1Ob7dv-mLedEm1sRLXrEmkEr47I0QEQD9
Databricks Databricks-Certified-Professional-Data-Engineer試験を難しく感じる人に「やってもいないのに、できないと言わないこと」を言いたいです。我々JpshikenへのDatabricks Databricks-Certified-Professional-Data-Engineer試験問題集は専業化のチームが長時間で過去のデータから分析研究された成果で、あなたを試験に迅速的に合格できるのを助けます。依然躊躇うなら、弊社の無料のDatabricks Databricks-Certified-Professional-Data-Engineerデモを参考しましょう。そうしたら、Databricks Databricks-Certified-Professional-Data-Engineer試験はそんなに簡単なことだと知られます。
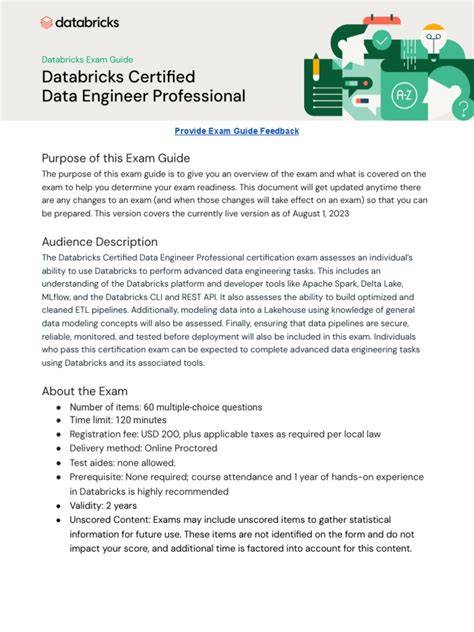
Databricks認定プロフェッショナルデータエンジニア試験は、世界中どこからでも受験できるオンライン試験です。試験は時間制限があり、複数の選択肢の問題と、Databricksを使用して特定のタスクを実行する能力を証明するための実践的な課題から構成されています。試験は、Databricksのデータエンジニアリングの概念と技術を徹底的に理解することが必要であり、難易度が高く設計されています。
>> Databricks-Certified-Professional-Data-Engineer模擬体験 <<
有効的なDatabricks Databricks-Certified-Professional-Data-Engineer模擬体験 & 合格スムーズDatabricks-Certified-Professional-Data-Engineer認定テキスト | 信頼的なDatabricks-Certified-Professional-Data-Engineer復習教材
Jpshiken弊社が提供する製品は、専門家によって精巧にコンパイルされており、Databricksお客様に便利な方法でDatabricks-Certified-Professional-Data-Engineer学習教材の学習を支援することを目的としたさまざまなバージョンを強化しています。 Databricks-Certified-Professional-Data-Engineer彼らは毎日アップデートをチェックしており、Databricks Certified Professional Data Engineer Exam購入日から無料のアップデートサービスが受けられることを保証できます。Databricks-Certified-Professional-Data-Engineer 販売前または販売後にカスタマーサービスを提供するDatabricks試験問題について質問や疑問がある場合は、試験資料について質問や疑問がある場合は連絡してください。Databricks Certified Professional Data Engineer Exam専門の担当者が解決に役立ちます。 Databricks-Certified-Professional-Data-Engineer学習資料の使用に関する問題。
Databricks認定プロフェッショナルデータエンジニアの試験では、データの摂取、変換、ストレージ、処理など、幅広いトピックについて説明しています。この試験では、DataBricksツールとテクノロジーを使用して、実際の問題と課題を解決する候補者の能力をテストします。この試験に合格した候補者は、ビッグデータ処理と分析のための主要なクラウドベースのプラットフォームであるDataBricksを使用して、データパイプラインの設計、構築、管理に習熟していることを示しています。
Databricks Databricks-Certified-Professional-Data-Engineer 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - セキュリティとガバナンス: データ マスキングを実現するための動的ビューの作成と、動的ビューを使用して行と列へのアクセスを制御する方法について説明します。
|
| トピック 2 | - Databricks ツール:Databricks ツールのトピックでは、Delta Lake のさまざまな機能について解説します。トランザクションログ、楽観的同時実行制御、Delta クローン、インデックスの最適化、そして Databricks SQL サービスのパフォーマンスを最適化するためのデータパーティション戦略などについて理解を深めます。
|
| トピック 3 | - データ処理:このトピックでは、パーティションヒントの理解、データの効果的なパーティション分割、部分ファイルサイズの制御、レコードの更新、構造化ストリーミングとDelta Lakeの活用、ストリームスタティック結合と重複排除の実装について解説します。さらに、変更データキャプチャの活用と、小さなファイルに関連するパフォーマンス問題の解決についても詳しく説明します。
|
Databricks Certified Professional Data Engineer Exam 認定 Databricks-Certified-Professional-Data-Engineer 試験問題 (Q10-Q15):
質問 # 10
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings. The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream to power several production monitoring dashboards and a production model. At present, 45 of the 100 fields are being used in at least one of these applications.
The data engineer is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields.
Which of the following accurately presents information about Delta Lake and Databricks that may impact their decision-making process?
- A. Because Databricks will infer schema using types that allow all observed data to be processed, setting types manually provides greater assurance of data quality enforcement.
- B. Schema inference and evolution on .Databricks ensure that inferred types will always accurately match the data types used by downstream systems.
- C. Because Delta Lake uses Parquet for data storage, data types can be easily evolved by just modifying file footer information in place.
- D. The Tungsten encoding used by Databricks is optimized for storing string data; newly-added native support for querying JSON strings means that string types are always most efficient.
- E. Human labor in writing code is the largest cost associated with data engineering workloads; as such, automating table declaration logic should be a priority in all migration workloads.
正解:A
解説:
This is the correct answer because it accurately presents information about Delta Lake and Databricks that may impact the decision-making process of a junior data engineer who is trying to determine the best approach for dealing with schema declaration given the highly-nested structure of the data and the numerous fields. Delta Lake and Databricks support schema inference and evolution, which means that they can automatically infer the schema of a table from the source data and allow adding new columns or changing column types without affecting existing queries or pipelines. However, schema inference and evolution may not always be desirable or reliable, especially when dealing with complex or nested data structures or when enforcing data quality and consistency across different systems. Therefore, setting types manually can provide greater assurance of data quality enforcement and avoid potential errors or conflicts due to incompatible or unexpected data types. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Schema inference and partition of streaming DataFrames/Datasets" section.
質問 # 11
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable.
Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use a SCALAR Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- B. Use applyInPandas() on a Spark DataFrame that receives all rows for each stock symbol as a Pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
- C. Use a grouped_agg Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- D. Use a SCALAR_ITER Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
正解:B
解説:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
質問 # 12
Which of the following statements can successfully read the notebook widget and pass the python variable to a SQL statement in a Python notebook cell?
- A. 1.order_date = dbutils.widgets.get("widget_order_date")
2.
3.spark.sql(f"SELECT * FROM sales WHERE orderDate = 'f{order_date }'") - B. 1.order_date = dbutils.widgets.get("widget_order_date")
2.
3.spark.sql("SELECT * FROM sales WHERE orderDate = order_date") - C. 1.order_date = dbutils.widgets.get("widget_order_date")
2.
3.spark.sql(f"SELECT * FROM sales WHERE orderDate = 'order_date' ") - D. 1.order_date = dbutils.widgets.get("widget_order_date")
2.
3.spark.sql(f"SELECT * FROM sales WHERE orderDate = '{order_date}' ")
(Correct) - E. 1.order_date = dbutils.widgets.get("widget_order_date")
2.
3.spark.sql(f"SELECT * FROM sales WHERE orderDate = '${order_date }' ")
正解:D
質問 # 13
The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs Ul. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.
What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?
- A. Can Read
- B. Can run
- C. Can edit
- D. Can manage
正解:A
解説:
Granting a user 'Can Read' permissions on a notebook within Databricks allows them to view the notebook's content without the ability to execute or edit it. This level of permission ensures that the new team member can review the production logic for learning or auditing purposes without the risk of altering the notebook's code or affecting production data and workflows. This approach aligns with best practices for maintaining security and integrity in production environments, where strict access controls are essential to prevent unintended modifications.References: Databricks documentation on access control and permissions for notebooks within the workspace (https://docs.databricks.com/security/access-control/workspace-acl.html).
質問 # 14
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company.
A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users.
Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
- A. No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.
- B. "Read" permissions should be set on a secret scope containing only those credentials that will be used by a given team.
- C. ''Read'' permissions should be set on a secret key mapped to those credentials that will be used by a given team.
- D. "Manage" permission should be set on a secret scope containing only those credentials that will be used by a given team.
正解:B
解説:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
References:
* Databricks Documentation on Secret Management: Secrets
質問 # 15
......
Databricks-Certified-Professional-Data-Engineer認定テキスト: https://www.jpshiken.com/Databricks-Certified-Professional-Data-Engineer_shiken.html
- Databricks-Certified-Professional-Data-Engineer復習攻略問題 🥼 Databricks-Certified-Professional-Data-Engineer再テスト 🥬 Databricks-Certified-Professional-Data-Engineer日本語版対応参考書 🍫 ▷ www.it-passports.com ◁は、➽ Databricks-Certified-Professional-Data-Engineer 🢪を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Professional-Data-Engineer技術問題
- Databricks-Certified-Professional-Data-Engineer模擬体験 - Databricks Certified Professional Data Engineer Examに合格するための親友 💘 ▛ www.goshiken.com ▟を入力して[ Databricks-Certified-Professional-Data-Engineer ]を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer日本語版対応参考書
- Databricks-Certified-Professional-Data-Engineer学習教材 🟧 Databricks-Certified-Professional-Data-Engineer復習攻略問題 ➖ Databricks-Certified-Professional-Data-Engineer最新問題 🐒 ⮆ www.jpexam.com ⮄は、( Databricks-Certified-Professional-Data-Engineer )を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Professional-Data-Engineer日本語版対応参考書
- ハイパスレートDatabricks-Certified-Professional-Data-Engineer模擬体験 - 資格試験のリーダープロバイダー - 早速ダウンロードDatabricks-Certified-Professional-Data-Engineer認定テキスト 🥪 サイト➠ www.goshiken.com 🠰で▷ Databricks-Certified-Professional-Data-Engineer ◁問題集をダウンロードDatabricks-Certified-Professional-Data-Engineer試験解答
- Databricks-Certified-Professional-Data-Engineer関連問題資料 🪒 Databricks-Certified-Professional-Data-Engineer合格内容 🎵 Databricks-Certified-Professional-Data-Engineer日本語資格取得 🕙 ➤ www.shikenpass.com ⮘で【 Databricks-Certified-Professional-Data-Engineer 】を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer合格受験記
- Databricks-Certified-Professional-Data-Engineer受験記対策 🔦 Databricks-Certified-Professional-Data-Engineer合格内容 🦥 Databricks-Certified-Professional-Data-Engineer試験番号 🍻 ウェブサイト✔ www.goshiken.com ️✔️を開き、➽ Databricks-Certified-Professional-Data-Engineer 🢪を検索して無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer的中関連問題
- Databricks-Certified-Professional-Data-Engineer試験解答 🥅 Databricks-Certified-Professional-Data-Engineer科目対策 ⚫ Databricks-Certified-Professional-Data-Engineer合格内容 💼 ⇛ www.xhs1991.com ⇚を入力して▛ Databricks-Certified-Professional-Data-Engineer ▟を検索し、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer合格内容
- Databricks-Certified-Professional-Data-Engineer日本語資格取得 🐛 Databricks-Certified-Professional-Data-Engineer合格受験記 🦼 Databricks-Certified-Professional-Data-Engineer合格受験記 😇 ➠ Databricks-Certified-Professional-Data-Engineer 🠰の試験問題は➽ www.goshiken.com 🢪で無料配信中Databricks-Certified-Professional-Data-Engineer試験解答
- Databricks-Certified-Professional-Data-Engineer受験記対策 🔮 Databricks-Certified-Professional-Data-Engineer最新問題 🚁 Databricks-Certified-Professional-Data-Engineer関連問題資料 🧏 ▛ www.japancert.com ▟は、▶ Databricks-Certified-Professional-Data-Engineer ◀を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Professional-Data-Engineer再テスト
- ハイパスレートDatabricks-Certified-Professional-Data-Engineer模擬体験 - 資格試験のリーダープロバイダー - 早速ダウンロードDatabricks-Certified-Professional-Data-Engineer認定テキスト 🍹 ✔ www.goshiken.com ️✔️を開き、✔ Databricks-Certified-Professional-Data-Engineer ️✔️を入力して、無料でダウンロードしてくださいDatabricks-Certified-Professional-Data-Engineer的中関連問題
- Databricks-Certified-Professional-Data-Engineer技術問題 😯 Databricks-Certified-Professional-Data-Engineer資格講座 🌃 Databricks-Certified-Professional-Data-Engineer試験番号 💝 検索するだけで▛ www.japancert.com ▟から➤ Databricks-Certified-Professional-Data-Engineer ⮘を無料でダウンロードDatabricks-Certified-Professional-Data-Engineer試験解答
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. JpshikenがGoogle Driveで共有している無料かつ新しいDatabricks-Certified-Professional-Data-Engineerダンプ:https://drive.google.com/open?id=1Ob7dv-mLedEm1sRLXrEmkEr47I0QEQD9