Reliable Certified-Data-Engineer-Professional Test Guide - Online Certified-Data-Engineer-Professional Test

Actual4Dumps is also offering one year free Certified-Data-Engineer-Professional updates. You can update your Certified-Data-Engineer-Professional study material for 90 days from the date of purchase. The Databricks Certified Data Engineer Professional updated package will include all the past questions from the past papers. You can pass the Certified-Data-Engineer-Professional exam easily with the help of the PDF dumps included in the package. It will have all the questions that you should cover for the Databricks Certified-Data-Engineer-Professional Exam. If you are facing any issues with the products you have, then you can always contact our 24/7 support to get assistance.
| Section | Objectives |
|---|
| Topic 1: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 2: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Share live Lakehouse data with external computing platforms
- 2. Configure sharing with external platforms using the open sharing protocol
- 3. Configure Databricks-to-Databricks Sharing
|
| Topic 3: Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- 2. Use system tables for resource, cost, audit, and workload monitoring
- 3. Use Query Profiler and Spark UI to monitor workloads
- 4. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
|
| Topic 4: Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Develop data quarantining processes for invalid data
- 2. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
|
| Topic 5: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Build append-only pipelines for batch and streaming data using Delta
- 2. Ingest data from message buses and cloud storage
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 6: Ensuring Data Security and Compliance | - Data Security
- 1. Use ACLs to secure workspace objects and enforce least privilege
- 2. Apply anonymization and pseudonymization techniques
- 3. Use row filters and column masks for sensitive data
- Compliance
- 1. Develop data purging solutions according to data retention policies
- 2. Implement pipelines that detect and mask personally identifiable information
|
| Topic 7: Developing Code for Data Processing using Python and SQL | - Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Compare streaming tables and materialized views
- 3. Configure environments, dependencies, memory, and retry behavior
- 4. Use APPLY CHANGES APIs for change data capture
- 5. Use control flow operators in pipeline components
- 6. Develop unit and integration tests for data processing code
- 7. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 8. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Manage and troubleshoot third-party library installations and dependencies
- 3. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
|
| Topic 8: Cost & Performance Optimisation | - Delta Optimization
- 1. Use Change Data Feed to address streaming table limitations and improve latency
- 2. Apply data skipping and file pruning techniques
- 3. Understand deletion vectors and liquid clustering
- Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Topic 9: Debugging and Deploying | - Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 2. Analyze errors and remediate failed job runs
- 3. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
|
| Topic 10: Data Modelling | - Scalable Data Models
- 1. Understand Liquid Clustering versus partitioning and Z-Ordering
- 2. Optimize data layout using Liquid Clustering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
>> Reliable Certified-Data-Engineer-Professional Test Guide <<
100% Free Certified-Data-Engineer-Professional – 100% Free Reliable Test Guide | the Best Online Databricks Certified Data Engineer Professional Test
Choosing right study materials is key point to pass the Databricks certification exam. Actual4Dumps is equipped with the latest questions and valid answers to ensure the preparation of Certified-Data-Engineer-Professional exam easier. The feedback from our candidates showed that our Certified-Data-Engineer-Professional Dumps PDF covers almost 90% questions in the actual test. So put our dumps to your shopping cart quickly.
Databricks Certified Data Engineer Professional Sample Questions (Q225-Q230):
NEW QUESTION # 225
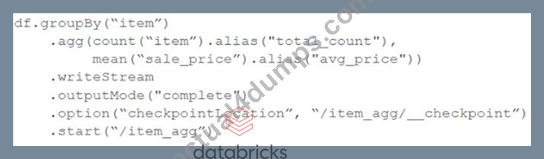
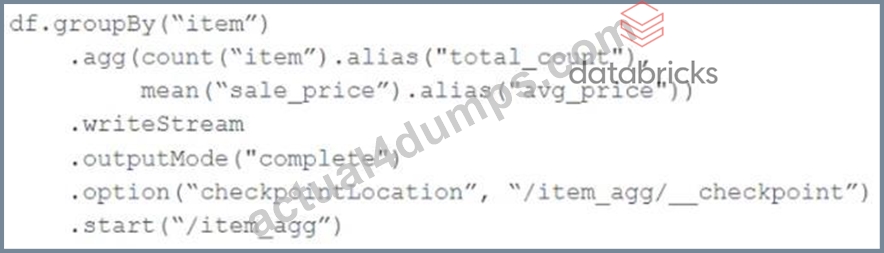
A data team's Structured Streaming job is configured to calculate running aggregates for item sales to update a downstream marketing dashboard. The marketing team has introduced a new field to track the number of times this promotion code is used for each item. A junior data engineer suggests updating the existing query as follows: Note that proposed changes are in bold.
Original query:
Proposed query:
Which step must also be completed to put the proposed query into production?
- A. Increase the shuffle partitions to account for additional aggregates
- B. Specify a new checkpointlocation
- C. Remove .option (mergeSchema', true') from the streaming write
- D. Run REFRESH TABLE delta, /item_agg'
- E. Register the data in the "/item_agg" directory to the Hive metastore
Answer: B
Explanation:
When introducing a new aggregation or a change in the logic of a Structured Streaming query, it is generally necessary to specify a new checkpoint location. This is because the checkpoint directory contains metadata about the offsets and the state of the aggregations of a streaming query. If the logic of the query changes, such as including a new aggregation field, the state information saved in the current checkpoint would not be compatible with the new logic, potentially leading to incorrect results or failures. Therefore, to accommodate the new field and ensure the streaming job has the correct starting point and state information for aggregations, a new checkpoint location should be specified.
NEW QUESTION # 226
A data engineer is designing a system to process batch patient encounter data stored in an S3 bucket, creating a Delta table (patient_encounters) with columns encounter_id, patient_id, encounter_date, diagnosis_code, and treatment_cost. The table is queried frequently by patient_id and encounter_date, requiring fast performance. Fine-grained access controls must be enforced. The engineer wants to minimize maintenance and boost performance. How should the data engineer create the patient_encounters table?
- A. Create an external table in Unity Catalog, specifying an S3 location for the data files. Enable predictive optimization through table properties, and configure Unity Catalog permissions for access controls.
- B. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
- C. Create a managed table in Unity Catalog. Configure Unity Catalog permissions for access controls, schedule jobs to run OPTIMIZE and VACUUM commands daily to achieve best performance.
- D. Create a managed table in Hive Metastore. Configure Hive Metastore permissions for access controls, and rely on predictive optimization to enhance query performance and simplify maintenance.
Answer: B
Explanation:
Databricks documentation specifies that Unity Catalog managed tables are the preferred choice for secure, low-maintenance Delta Lake architectures. Managed tables provide full lifecycle management, including metadata, file storage, and access control integration with Unity Catalog.
Fine-grained permissions can be enforced at the column and row level through built-in Unity Catalog governance.
Additionally, Predictive Optimization (Auto Optimize + Auto Compaction) automatically manages file sizes, metadata pruning, and layout optimization, eliminating the need for manual maintenance such as scheduling OPTIMIZE or VACUUM.
External tables (A) require manual path management, and Hive Metastore tables (D) do not support Unity Catalog access policies. Therefore, creating a managed Unity Catalog table with predictive optimization provides both the security and performance benefits needed, making B the correct solution.
NEW QUESTION # 227
A data team is implementing an append-only Delta Lake pipeline that processes both batch and streaming data. They want to ensure that schema changes in the source data are automatically incorporated without breaking the pipeline. Which configuration should the team use when writing data to the Delta table?
- A. overwriteSchema = true
- B. validateSchema = false
- C. mergeSchema = true
- D. ignoreChanges = false
Answer: C
Explanation:
Setting mergeSchema to true allows Delta Lake to automatically evolve the table schema by incorporating new columns from the source data during writes. This enables append-only pipelines to handle schema changes seamlessly in both batch and streaming workloads without breaking the pipeline.
NEW QUESTION # 228
A data engineer is building a Lakeflow Declarative Pipelines pipeline to process healthcare claims data. A metadata JSON file defines data quality rules for multiple tables, including:
{
"claims": [
{"name": "valid_patient_id", "constraint": "patient_id IS NOT NULL"},
{"name": "non_negative_amount", "constraint": "claim_amount >= 0"}
]
}
The pipeline must dynamically apply these rules to the claims table without hardcoding the rules.
How should the data engineer achieve this?
- A. Load the JSON metadata, loop through its entries, and apply expectations using dlt.expect_all.
- B. Use a SQL CONSTRAINT block referencing the JSON file path.
- C. Invoke an external API to validate records against the metadata rules.
- D. Reference each expectation with @dlt.expect decorators in the table declaration.
Answer: A
Explanation:
Lakeflow Declarative Pipelines provide the expect_all method for programmatically applying multiple data quality expectations at once. The documentation explains that @dlt.expect_all accepts a dictionary of expectation names mapped to SQL constraints, allowing rules to be dynamically loaded from metadata such as JSON files. This ensures that pipelines remain maintainable and scalable without needing to hardcode individual @dlt.expect decorators. The event logs will track each expectation's pass and fail counts individually, making it auditable.
NEW QUESTION # 229
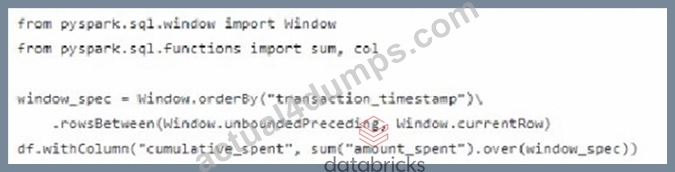
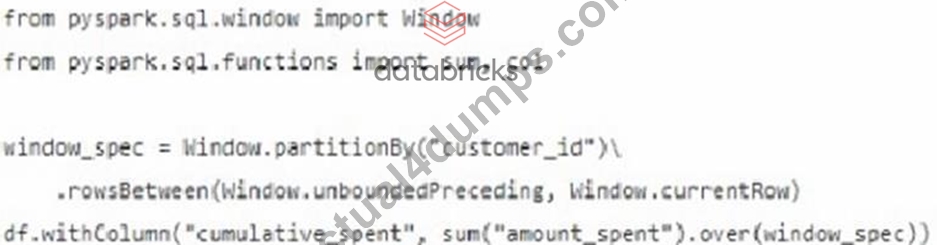
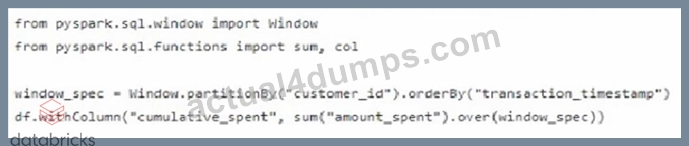
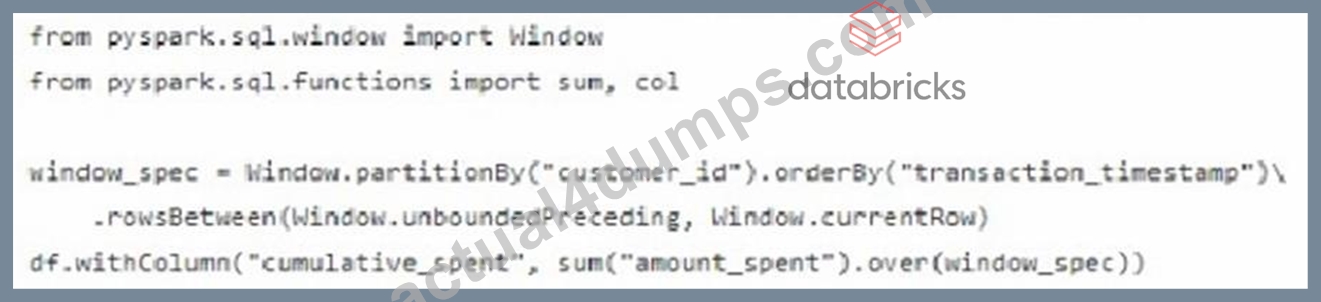
A data engineer is analyzing transactional data in a PySpark DataFrame df containing customer_id, transaction_timestamp (precise to milliseconds), and amount_spent. The objective is to compute a cumulative sum of amount_spent per customer, strictly ordered by transaction_timestamp. The cumulative sum must include all transactions from the earliest timestamp up to and including the current row, respecting temporal ordering within each customer partition. Which PySpark code snippet most accurately constructs the appropriate window specification and applies the aggregation to yield the correct cumulative expenditure per customer?
Answer: D
Explanation:
This window specification partitions the data by customer_id, orders transactions by transaction_timestamp, and defines the frame from the first transaction through the current one.
This guarantees that the cumulative sum is computed independently per customer and strictly follows the temporal order, including all prior transactions up to the current row.
NEW QUESTION # 230
......
We are committed to provide you the best and the latest Certified-Data-Engineer-Professional training materials for you. Quality of the Certified-Data-Engineer-Professional exam dumps has get high evaluation among our customers, they think highly of it, since we help them pass the exam easily. Furthermore if we have the updated version, our system will send the Latest Certified-Data-Engineer-Professional Exam Dumps to your email address automatically, you don’t need to worry about missing the latest version, you just need to concentrate your attention on practicing, and we will do the rest for you.
Online Certified-Data-Engineer-Professional Test: https://www.actual4dumps.com/Certified-Data-Engineer-Professional-study-material.html
- 100% Free Certified-Data-Engineer-Professional – 100% Free Reliable Test Guide | Updated Online Databricks Certified Data Engineer Professional Test 🛂 Copy URL 【 www.troytecdumps.com 】 open and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free ⚗Exam Certified-Data-Engineer-Professional Simulations
- Test Certified-Data-Engineer-Professional Dates 👔 Valid Certified-Data-Engineer-Professional Exam Objectives 🎃 Certified-Data-Engineer-Professional Fresh Dumps 🧒 Easily obtain ▛ Certified-Data-Engineer-Professional ▟ for free download through 「 www.pdfvce.com 」 🧈Certification Certified-Data-Engineer-Professional Exam Infor
- Accurate Certified-Data-Engineer-Professional Study Material 🏇 Certified-Data-Engineer-Professional Detailed Study Plan 😉 Certified-Data-Engineer-Professional Examcollection Questions Answers 👲 Search for ➠ Certified-Data-Engineer-Professional 🠰 and easily obtain a free download on 「 www.testkingpass.com 」 🟨Certified-Data-Engineer-Professional Practice Exam Fee
- Certified-Data-Engineer-Professional Trustworthy Exam Torrent 🕦 Certified-Data-Engineer-Professional Braindump Free 😹 Certified-Data-Engineer-Professional Practice Exam Fee 🕞 Search for ▛ Certified-Data-Engineer-Professional ▟ and download it for free immediately on ➡ www.pdfvce.com ️⬅️ 📮Exam Certified-Data-Engineer-Professional Simulations
- Test Certified-Data-Engineer-Professional Dates 📫 Certified-Data-Engineer-Professional Practice Exam Fee 🌎 Latest Certified-Data-Engineer-Professional Exam Online 🍣 Go to website ✔ www.prepawayete.com ️✔️ open and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download for free 🚏Test Certified-Data-Engineer-Professional Dates
- Certified-Data-Engineer-Professional Fresh Dumps 🟨 Exam Certified-Data-Engineer-Professional Simulations 👙 Certified-Data-Engineer-Professional Trustworthy Exam Torrent 🥪 Search for ▶ Certified-Data-Engineer-Professional ◀ and download it for free immediately on ▶ www.pdfvce.com ◀ 🖕Certification Certified-Data-Engineer-Professional Exam Infor
- 100% Free Certified-Data-Engineer-Professional – 100% Free Reliable Test Guide | Updated Online Databricks Certified Data Engineer Professional Test 🌜 Immediately open ( www.pass4test.com ) and search for ☀ Certified-Data-Engineer-Professional ️☀️ to obtain a free download 🏴Valid Certified-Data-Engineer-Professional Exam Objectives
- Databricks Certified Data Engineer Professional Verified Practice Cram - Certified-Data-Engineer-Professional Study Pdf Dumps - Databricks Certified Data Engineer Professional Exam Training Dumps 🖤 Open ⇛ www.pdfvce.com ⇚ and search for ➠ Certified-Data-Engineer-Professional 🠰 to download exam materials for free 🩸Exam Certified-Data-Engineer-Professional Vce Format
- 100% Free Certified-Data-Engineer-Professional – 100% Free Reliable Test Guide | Updated Online Databricks Certified Data Engineer Professional Test 🩱 Easily obtain free download of ( Certified-Data-Engineer-Professional ) by searching on ⇛ www.pass4test.com ⇚ 💛Certified-Data-Engineer-Professional Practice Exam Fee
- 100% Free Certified-Data-Engineer-Professional – 100% Free Reliable Test Guide | Updated Online Databricks Certified Data Engineer Professional Test ♣ The page for free download of ➽ Certified-Data-Engineer-Professional 🢪 on ➤ www.pdfvce.com ⮘ will open immediately 🔮Exam Certified-Data-Engineer-Professional Vce Format
- Reliable Certified-Data-Engineer-Professional Test Guide - Pass Guaranteed First-grade Certified-Data-Engineer-Professional - Online Databricks Certified Data Engineer Professional Test 💉 The page for free download of ▷ Certified-Data-Engineer-Professional ◁ on ⮆ www.pdfdumps.com ⮄ will open immediately 🍦Valid Certified-Data-Engineer-Professional Exam Questions
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, blogfreely.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes