2026 Latest ITExamSimulator SPS-C01 PDF Dumps and SPS-C01 Exam Engine Free Share: https://drive.google.com/open?id=18mbWtUStkTbNUsvHGQP22BI-zpvT4Be7
Our SPS-C01 study materials combine the key information about the test in the past years’ test papers and the latest emerging knowledge points among the industry to help the clients both solidify the foundation and advance with the times. We give priority to the user experiences and the clients’ feedback, SPS-C01 Study Materials will constantly improve our service and update the version to bring more conveniences to the clients and make them be satisfied.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Topic 2: Data Transformations and Operations | 35% | - Advanced operations
|
| Topic 3: Performance and Best Practices | 10% | - Security and governance
|
| Topic 4: Snowpark API and Development | 30% | - Python API fundamentals
|
>> Exam SPS-C01 Collection Pdf <<
To do this you just need to pass the Snowflake SPS-C01 certification exam. Are you ready to accept this challenge? Looking for the proven and easiest way to crack the Snowflake SPS-C01 certification exam? If your answer is yes then you do not need to go anywhere. Just download SPS-C01 exam practice questions and start Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam preparation without wasting further time. The ITExamSimulator Snowflake SPS-C01 Dumps will provide you with everything that you need to learn, prepare and pass the challenging SPS-C01 exam with flying colors. You must try ITExamSimulator Snowflake SPS-C01 exam questions today.
NEW QUESTION # 39
Consider the following Snowpark Python code snippet that retrieves data and calculates aggregate values, however, the application performance is slow when you are fetching dataframe, given the 'block' parameter controls the synchronous/asynchronous behavior of the 'collect()' method. Choose ALL the statements about "session.create_dataframe([rowl ,row2],schema)' that are correct:
Answer: C
Explanation:
The method, when used with the default 'block=True' , operates synchronously, meaning it waits for the result to be fully available before proceeding to the next line of code. This can introduce latency and slow down the application, especially with larger datasets. Using 'block=False' makes the operation asynchronous, allowing the application to continue executing other tasks while the data is being retrieved in the background. Increasing warehouse size will have the same effect regardless, because of . The 'block' parameter is crucial for controlling synchronous versus asynchronous behaviour. The warehouse has no direct influence since the bottleneck is with 'collect()'. Converting to pandas does not fix the inherent blocking problem and makes the problem worse, given it increase network I/O to move data to client side.
NEW QUESTION # 40
You have a DataFrame 'df containing user profile data'. A column named "profile" stores JSON objects with potentially missing fields. These objects might include 'name', 'age', 'location', and 'preferences'. You need to extract the user's name and age. If 'age' is missing, you want to default to 0. Furthermore, you want to filter out any rows where the 'location' field is an empty string. Which combination of Snowpark code snippets will achieve this? (Select all that apply)





Answer: B,D,E
Explanation:
Options A, B and C correctly address the requirements. They extract the name and handle the missing 'age' by defaulting to 0, and filter out rows with an empty string for 'location'. - Option A uses 'nvr to replace NULL 'age' values and ' to filter out empty locations. - Option B uses 'iff to achieve the same age default and sf.lit(")' for filtering. - Option C uses 'coalesce' to default 'age' and 'sf.lengtm to check if the location string has any characters. Option D will filter out all the rows where location is Null and option E uses zeroifnull function which is deprecated, and replaces age which is 0 if column is NULL. and option D wont filer empty string in location
NEW QUESTION # 41
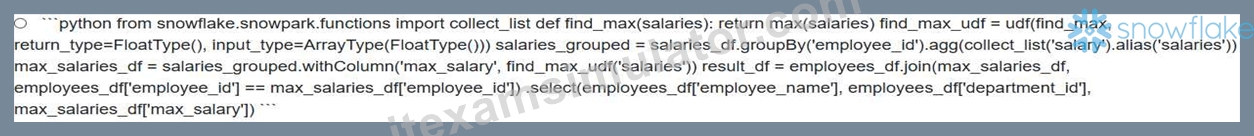
You have two Snowpark DataFrames: 'employees_df with columns 'employee_id' (INTEGER), 'employee_name' (STRING), 'department_id' (INTEGER), and 'salaries_df' with columns 'employee_id' (INTEGER), "salary' (FLOAT), 'effective_date' (DATE). You need to create a new DataFrame that contains the employee's name, department, and the highest salary they have ever received. Assuming there can be multiple salary entries for the same employee with different 'effective date' values, which of the following Snowpark code snippets would correctly and efficiently solve this problem?




Answer: D
Explanation:
Option B is the most efficient solution. It first calculates the maximum salary for each employee in the DataFrame using 'groupBy' and 'max' , then joins this aggregated result with the 'employees_df to retrieve the employee's name and department. This approach avoids unnecessary data shuffling and minimizes the amount of data processed in the join. Option A performs the join before the aggregation, which can be less efficient. Options C and E use window functions, which are more complex and may not be as efficient for this simple aggregation. Option D uses a UDF and 'collect_list' , which can be very inefficient due to data transfer and UDF overhead.
NEW QUESTION # 42
A data engineer is tasked with creating a Snowpark session using JWT authentication. They have a private key 'rsa_key.pff, a user name 'snowpark_user' , and an account identifier 'my_account'. The goal is to create a session object suitable for submitting Snowpark jobs. Which code snippet correctly demonstrates the instantiation of a session object using JWT?





Answer: C
Explanation:
Option B correctly reads the private key file, converts it to the required PEM format, and then uses it within the connection parameters to establish a Snowpark session. It handles the private key securely by loading and formatting it properly before passing it to the connection parameters. Option A, C and D attempts to directly provide the path to the private key or read the content with incorrect formatting which is incorrect. Option E doesn't address reading the private key in correct form and only address warehouse selection after the session is create.
NEW QUESTION # 43
You are developing a Snowpark application to ingest a large dataset into Snowflake. You have a DataFrame with a schema that matches the target table 'TARGET TABLE. Due to network constraints, you need to optimize the insertion process to minimize the number of API calls. Which of the following approaches would provide the MOST efficient way to insert the data?
Answer: B
Explanation:
The most efficient approach is option C: 'data_df.insert_into('TARGET_TABLE')'. This method leverages Snowpark's optimized data transfer mechanisms and performs bulk insertion using the underlying Snowflake engine which minimizes api calls and faster to insert the data. Option A is highly inefficient due to the overhead of constructing and executing individual SQL statements. Option B introduces Pandas, which is slower. Option D involves additional staging steps. Option E is manual chunking which is also slower.
NEW QUESTION # 44
......
Will you feel that the product you have brought is not suitable for you? One trait of our SPS-C01 exam prepare is that you can freely download a demo to have a try. Because there are excellent free trial services provided by our SPS-C01 exam guides, our products will provide three demos that specially designed to help you pick the one you are satisfied. On the one hand, by the free trial services you can get close contact with our products, learn about the detailed information of our SPS-C01 Study Materials, and know how to choose the right version of our SPS-C01 exam questions.
SPS-C01 Latest Dumps Files: https://www.itexamsimulator.com/SPS-C01-brain-dumps.html
P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by ITExamSimulator: https://drive.google.com/open?id=18mbWtUStkTbNUsvHGQP22BI-zpvT4Be7