BONUS!!! Download part of VCEPrep DP-100 dumps for free: https://drive.google.com/open?id=1qE7yTunUCFn87FFJXFmGLuHLjgZqVD9z
We are dedicated to providing our clients with the most current and accurate Designing and Implementing a Data Science Solution on Azure study material. That is why we provide 1 year of free DP-100 questions updates if the Microsoft certification test content changes after your purchase. With this option, our clients can confidently use the most up-to-date and dependable DP-100 preparatory material.
Preparing for the Microsoft DP-100: Designing and Implementing a Data Science Solution on Azure exam requires a solid understanding of data science concepts, machine learning algorithms, and Azure cloud technologies. Candidates can utilize various resources such as online courses, practice exams, and study guides to prepare for the exam.
The DP-100 Certification Exam is intended for data scientists, data architects, and data engineers who want to validate their expertise in designing and implementing data science solutions on Azure. It is also suitable for professionals who are responsible for implementing Azure-based machine learning and AI solutions, including data analysts, developers, and IT administrators.
>> Microsoft DP-100 New Dumps Book <<
A good DP-100 certification must be supported by a good DP-100 exam practice, which will greatly improve your learning ability and effectiveness. Our study materials have the advantage of short time, high speed and high pass rate. You only take 20 to 30 hours to practice our DP-100 Guide materials and then you can take the exam. If you use our study materials, you can get the DP-100 certification by spending very little time and energy reviewing and preparing.
To prepare for the DP-100 Exam, candidates can take instructor-led training courses, self-paced online courses, and practice tests. Microsoft offers several training courses that cover the exam objectives, including "Designing and Implementing a Data Science Solution on Azure" and "Implementing an Azure Data Solution." Candidates can also access online resources such as Microsoft documentation and GitHub repositories to learn about Azure technologies and data science concepts.
NEW QUESTION # 349
You need to define a modeling strategy for ad response.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
Explanation
Step 1: Implement a K-Means Clustering model
Step 2: Use the cluster as a feature in a Decision jungle model.
Decision jungles are non-parametric models, which can represent non-linear decision boundaries.
Step 3: Use the raw score as a feature in a Score Matchbox Recommender model The goal of creating a recommendation system is to recommend one or more "items" to "users" of the system.
Examples of an item could be a movie, restaurant, book, or song. A user could be a person, group of persons, or other entity with item preferences.
Scenario:
Ad response rated declined.
Ad response models must be trained at the beginning of each event and applied during the sporting event.
Market segmentation models must optimize for similar ad response history.
Ad response models must support non-linear boundaries of features.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/multiclass-decision-jungle
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/score-matchbox-recommende
NEW QUESTION # 350
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You create an Azure Machine Learning service datastore in a workspace. The datastore contains the following files:
* /data/2018/Q1.csv
* /data/2018/Q2.csv
* /data/2018/Q3.csv
* /data/2018/Q4.csv
* /data/2019/Q1.csv
All files store data in the following format:
id,f1,f2i
1,1.2,0
2,1,1,
1 3,2.1,0
You run the following code:
You need to create a dataset named training_data and load the data from all files into a single data frame by using the following code:
Solution: Run the following code: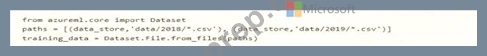
Does the solution meet the goal?
Answer: B
Explanation:
Use two file paths.
Use Dataset.Tabular_from_delimeted, instead of Dataset.File.from_files as the data isn't cleansed.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-create-register-datasets
NEW QUESTION # 351
An organization uses Azure Machine Learning service and wants to expand their use of machine learning.
You have the following compute environments. The organization does not want to create another compute environment.
You need to determine which compute environment to use for the following scenarios.
Which compute types should you use? To answer, drag the appropriate compute environments to the correct scenarios. Each compute environment may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Box 1: nb_server
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/concept-compute-target
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-set-up-training-targets
NEW QUESTION # 352
You are developing a machine learning, experiment by using Azure. The following images show the input and output of a machine learning experiment:
Use the drop-down menus to select the answer choice that answers each question based on the information presented in the graphic.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 353
You have an Azure Machine learning workspace. The workspace contains a dataset with data in a tabular form.
You plan to use the Azure Machine Learning SDK for Python vl to create a control script that will load the dataset into a pandas dataframe in preparation for model training The script will accept a parameter designating the dataset You need to complete the script.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
NEW QUESTION # 354
......
DP-100 Fresh Dumps: https://www.vceprep.com/DP-100-latest-vce-prep.html
BTW, DOWNLOAD part of VCEPrep DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1qE7yTunUCFn87FFJXFmGLuHLjgZqVD9z