100% Pass Databricks - Newest Databricks-Certified-Professional-Data-Engineer - Questions Databricks Certified Professional Data Engineer Exam Pdf

P.S. Free 2026 Databricks Databricks-Certified-Professional-Data-Engineer dumps are available on Google Drive shared by TestPDF: https://drive.google.com/open?id=1RBrHOLMJH76UMFQozh1rglwjaFefVwnc
In order to meet all demands of all customers, our company has employed a lot of excellent experts and professors in the field to design and compile the Databricks-Certified-Professional-Data-Engineer study materials with a high quality. It has been a generally accepted fact that the Databricks-Certified-Professional-Data-Engineer Study Materials from our company are more useful and helpful for all people who want to pass exam and gain the related exam. We believe this resulted from our constant practice, hard work and our strong team spirit.
| Section | Weight | Objectives |
|---|
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs
- Troubleshooting pipelines and errors
- CI/CD and DevOps practices
|
| Cost & Performance Optimisation | 13% | - Query optimization and caching
- Storage optimization (partitioning, Z-order, indexing)
- Cluster configuration and scaling
|
| Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion
- Connecting to diverse data sources
- Schema inference and evolution
|
| Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks
- Handling missing or inconsistent data
- Standardization and normalization
|
| Ensuring Data Security and Compliance | 10% | - Compliance standards implementation
- Data encryption and masking
- Access control and permissions
|
| Data Modelling | 6% | - Delta Lake table design
- Medallion Architecture implementation
- Schema design and management
|
| Monitoring and Alerting | 10% | - Setting up alerts and notifications
- Performance and health monitoring
- Pipeline observability and logging
|
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access
- Unity Catalog data sharing
|
| Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools
- Batch and incremental processing logic
- Data transformation and aggregation
|
| Data Governance | 7% | - Policy enforcement
- Unity Catalog management
- Data lineage and metadata tracking
|
>> Questions Databricks-Certified-Professional-Data-Engineer Pdf <<
Interactive Databricks Databricks-Certified-Professional-Data-Engineer EBook | Practice Databricks-Certified-Professional-Data-Engineer Test Engine
Dear every IT candidates, here, I will recommend TestPDF Databricks-Certified-Professional-Data-Engineer exam training material to all of you. If you use Databricks Databricks-Certified-Professional-Data-Engineer test bootcamp, you will not need to purchase anything else or attend other training. We promise that you can pass your Databricks-Certified-Professional-Data-Engineer Certification at first attempt. The high pass rate has helped lots of IT candidates get their IT certification. In case of failure, we promise to give you full refund. No help, full refund!
Databricks Certified Professional Data Engineer Exam Sample Questions (Q40-Q45):
NEW QUESTION # 40
Which statement describes Delta Lake Auto Compaction?
- A. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
- B. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- C. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- D. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- E. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
Answer: B
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones.
Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB.
Auto Compaction only compacts files that have not been compacted previously. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Auto Compaction for Delta Lake on Databricks" section.
"Auto compaction occurs after a write to a table has succeeded and runs synchronously on the cluster that has performed the write. Auto compaction only compacts files that haven't been compacted previously."
https://learn.microsoft.com/en-us/azure/databricks/delta/tune-file-size
NEW QUESTION # 41
All records from an Apache Kafka producer are being ingested into a single Delta Lake table with the following schema:
key BINARY, value BINARY, topic STRING, partition LONG, offset LONG, timestamp LONG There are 5 unique topics being ingested. Only the "registration" topic contains Personal Identifiable Information (PII). The company wishes to restrict access to PII. The company also wishes to only retain records containing PII in this table for 14 days after initial ingestion. However, for non-PII information, it would like to retain these records indefinitely.
Which of the following solutions meets the requirements?
- A. Because the value field is stored as binary data, this information is not considered PII and no special precautions should be taken.
- B. Data should be partitioned by the topic field, allowing ACLs and delete statements to leverage partition boundaries.
- C. Data should be partitioned by the registration field, allowing ACLs and delete statements to be set for the PII directory.
- D. Separate object storage containers should be specified based on the partition field, allowing isolation at the storage level.
- E. All data should be deleted biweekly; Delta Lake's time travel functionality should be leveraged to maintain a history of non-PII information.
Answer: B
Explanation:
Explanation
Partitioning the data by the topic field allows the company to apply different access control policies and retention policies for different topics. For example, the company can use the Table Access Control feature to grant or revoke permissions to the registration topic based on user roles or groups. The company can also use the DELETE command to remove records from the registration topic that are older than 14 days, while keeping the records from other topics indefinitely. Partitioning by the topic field also improves the performance of queries that filter by the topic field, as they can skip reading irrelevant partitions. References:
Table Access Control: https://docs.databricks.com/security/access-control/table-acls/index.html DELETE: https://docs.databricks.com/delta/delta-update.html#delete-from-a-table
NEW QUESTION # 42
A table is registered with the following code:
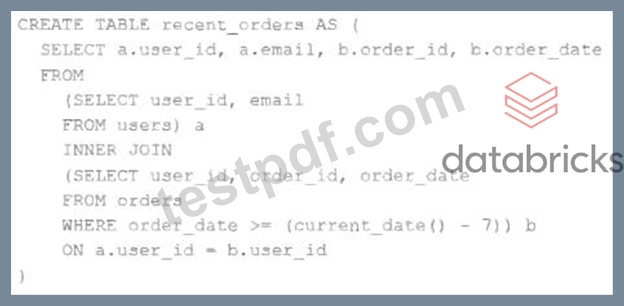
Bothusersandordersare Delta Lake tables. Which statement describes the results of queryingrecent_orders?
- A. Results will be computed and cached when the table is defined; these cached results will incrementally update as new records are inserted into source tables.
- B. All logic will execute when the table is defined and store the result of joining tables to the DBFS; this stored data will be returned when the table is queried.
- C. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query finishes.
- D. All logic will execute at query time and return the result of joining the valid versions of the source tables at the time the query began.
- E. The versions of each source table will be stored in the table transaction log; query results will be saved to DBFS with each query.
Answer: B
NEW QUESTION # 43
In order to prevent accidental commits to production data, a senior data engineer has instituted a policy that all development work will reference clones of Delta Lake tables. After testing both deep and shallow clone, development tables are created using shallow clone.
A few weeks after initial table creation, the cloned versions of several tables implemented as Type 1 Slowly Changing Dimension (SCD) stop working. The transaction logs for the source tables show that vacuum was run the day before.
Why are the cloned tables no longer working?
- A. The metadata created by the clone operation is referencing data files that were purged as invalid by the vacuum command
- B. Running vacuum automatically invalidates any shallow clones of a table; deep clone should always be used when a cloned table will be repeatedly queried.
- C. Because Type 1 changes overwrite existing records, Delta Lake cannot guarantee data consistency for cloned tables.
- D. The data files compacted by vacuum are not tracked by the cloned metadata; running refresh on the cloned table will pull in recent changes.
Answer: A
Explanation:
In Delta Lake, a shallow clone creates a new table by copying the metadata of the source table without duplicating the data files. When the vacuum command is run on the source table, it removes old data files that are no longer needed to maintain the transactional log's integrity, potentially including files referenced by the shallow clone's metadata. If these files are purged, the shallow cloned tables will reference non-existent data files, causing them to stop working properly. This highlights the dependency of shallow clones on the source table's data files and the impact of data management operations like vacuum on these clones.
Databricks documentation on Delta Lake, particularly the sections on cloning tables (shallow and deep cloning) and data retention with the vacuum command (https://docs.databricks.com/delta/index.html).
NEW QUESTION # 44
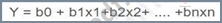
Which method is used to solve for coefficients bO, b1, ... bn in your linear regression model:
- A. Apriori Algorithm
- B. Integer programming
- C. Ordinary Least squares
- D. Ridge and Lasso
Answer: C
Explanation:
Explanation : RY = b0 + b1x1+b2x2+ .... +bnxn
In the linear model, the bi's represent the unknown p parameters. The estimates for these unknown parameters
are chosen so that, on average, the model provides a reasonable estimate of a person's income based on age
and education. In other words, the fitted model should minimize the overall error between the linear model and
the actual observations. Ordinary Least Squares (OLS) is a common technique to estimate the parameters
NEW QUESTION # 45
......
In a year after your payment, we will inform you that when the Databricks-Certified-Professional-Data-Engineer exam guide should be updated and send you the latest version. Our company has established a long-term partnership with those who have purchased our Databricks-Certified-Professional-Data-Engineer exam questions. We have made all efforts to update our products in order to help you deal with any change, making you confidently take part in the Databricks-Certified-Professional-Data-Engineer Exam. Every day they are on duty to check for updates of Databricks-Certified-Professional-Data-Engineer study materials for providing timely application. We also welcome the suggestions from our customers, as long as our clients propose rationally.
Interactive Databricks-Certified-Professional-Data-Engineer EBook: https://www.testpdf.com/Databricks-Certified-Professional-Data-Engineer-exam-braindumps.html
- Databricks Databricks-Certified-Professional-Data-Engineer Dumps - Pass Exam Immediately [2026] 🥕 Go to website 《 www.examdiscuss.com 》 open and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download for free 🕢Free Databricks-Certified-Professional-Data-Engineer Practice Exams
- Current Databricks-Certified-Professional-Data-Engineer Exam Content 🚑 Updated Databricks-Certified-Professional-Data-Engineer CBT 🍭 Databricks-Certified-Professional-Data-Engineer Exam Course 🧊 Simply search for 《 Databricks-Certified-Professional-Data-Engineer 》 for free download on [ www.pdfvce.com ] 🔄Free Databricks-Certified-Professional-Data-Engineer Practice Exams
- Pass4sure Databricks-Certified-Professional-Data-Engineer Exam Prep 🤛 New Databricks-Certified-Professional-Data-Engineer Exam Format 🎺 Free Databricks-Certified-Professional-Data-Engineer Practice Exams 🥅 Search for ▷ Databricks-Certified-Professional-Data-Engineer ◁ on 《 www.dumpsquestion.com 》 immediately to obtain a free download 🦺Accurate Databricks-Certified-Professional-Data-Engineer Answers
- Databricks-Certified-Professional-Data-Engineer Test Result 😧 Current Databricks-Certified-Professional-Data-Engineer Exam Content 🌶 Certification Databricks-Certified-Professional-Data-Engineer Torrent 🔴 Search for 【 Databricks-Certified-Professional-Data-Engineer 】 and easily obtain a free download on ➠ www.pdfvce.com 🠰 🍫Databricks-Certified-Professional-Data-Engineer Test Topics Pdf
- Databricks-Certified-Professional-Data-Engineer Exam Practice 😘 Current Databricks-Certified-Professional-Data-Engineer Exam Content 🦆 New Databricks-Certified-Professional-Data-Engineer Exam Question 🐯 Search for 《 Databricks-Certified-Professional-Data-Engineer 》 and obtain a free download on ➠ www.examcollectionpass.com 🠰 🥺Databricks-Certified-Professional-Data-Engineer Exam Practice
- Quiz Databricks - Professional Databricks-Certified-Professional-Data-Engineer - Questions Databricks Certified Professional Data Engineer Exam Pdf 😟 Enter 《 www.pdfvce.com 》 and search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 to download for free ↩Databricks-Certified-Professional-Data-Engineer Exam Practice
- 100% Pass 2026 Databricks Accurate Questions Databricks-Certified-Professional-Data-Engineer Pdf 🍫 Search for ➽ Databricks-Certified-Professional-Data-Engineer 🢪 and obtain a free download on ⮆ www.testkingpass.com ⮄ 🧰Updated Databricks-Certified-Professional-Data-Engineer CBT
- Databricks-Certified-Professional-Data-Engineer Test Topics Pdf ⚠ Exam Databricks-Certified-Professional-Data-Engineer Book 🎆 Updated Databricks-Certified-Professional-Data-Engineer CBT 🍅 Copy URL ➥ www.pdfvce.com 🡄 open and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download for free 👄Free Databricks-Certified-Professional-Data-Engineer Practice Exams
- Current Databricks-Certified-Professional-Data-Engineer Exam Content 🦆 Databricks-Certified-Professional-Data-Engineer Dump Ⓜ Databricks-Certified-Professional-Data-Engineer Exam Course 👟 《 www.pdfdumps.com 》 is best website to obtain ➥ Databricks-Certified-Professional-Data-Engineer 🡄 for free download 🧎Valid Dumps Databricks-Certified-Professional-Data-Engineer Files
- 100% Pass 2026 Databricks Accurate Questions Databricks-Certified-Professional-Data-Engineer Pdf ⛳ Open ⇛ www.pdfvce.com ⇚ enter ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and obtain a free download 🤚Certification Databricks-Certified-Professional-Data-Engineer Torrent
- Databricks-Certified-Professional-Data-Engineer Reliable Exam Tutorial 🍶 Databricks-Certified-Professional-Data-Engineer Test Result 🧐 Databricks-Certified-Professional-Data-Engineer Test Result 🎼 Open website ▶ www.exam4labs.com ◀ and search for ➠ Databricks-Certified-Professional-Data-Engineer 🠰 for free download 🦰Databricks-Certified-Professional-Data-Engineer Reliable Exam Prep
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of TestPDF Databricks-Certified-Professional-Data-Engineer dumps for free: https://drive.google.com/open?id=1RBrHOLMJH76UMFQozh1rglwjaFefVwnc