Certified-Data-Engineer-Professional Dumps und Test Überprüfungen sind die beste Wahl für Ihre Databricks Certified-Data-Engineer-Professional Testvorbereitung

Die Schulungsunterlagen zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung von unserem It-Pruefung können Ihre Kenntnisse während der Vorbereitungszeit prüfen und auch Ihre Leistungen innerhalb bestimmten Zeit bewerten. Unsere Schulungsunterlagen zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung sind das Ergebnis der langjährigen ständigen Untersuchung und Erforschung von den erfahrenen IT-Experten aus It-Pruefung. Ihre Autorität ist über jeden Zweifel erhaben. Wenn Sie noch Befürchtungen haben, können Sie die kostenlose Demo herunterladen, dann entscheiden Sie sich, ob Sie It-Pruefung wählen.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Topic 1: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 2: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Topic 3: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 2. Create pipeline components using control flow operators such as if/else and foreach
- 3. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 4. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 5. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 6. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 7. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 8. Explain the advantages and disadvantages of streaming tables compared to materialized views
- Using Python and Tools for Development
- 1. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
| Topic 4: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Topic 5: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 6: Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Use row filters and column masks to protect sensitive table data
|
| Topic 7: Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 4. Apply Change Data Feed to address streaming table limitations and improve latency
- 5. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
|
| Topic 8: Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Topic 9: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 10: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
>> Certified-Data-Engineer-Professional Exam <<
Certified-Data-Engineer-Professional Examsfragen, Certified-Data-Engineer-Professional Prüfungsaufgaben
It-Pruefung wird nicht nur Ihren Wunsch erfüllen, sondern Ihnen einen einjährigen kostenlosen Update-Service und Kundendienst bieten. Die Prüfungsfragen von It-Pruefung sind alle richtig, die Ihnen beim Bestehen der Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung helfen. Im It-Pruefung können Sie kostenlos einen Teil der Fragen und Antworten zur Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung als Probe herunterladen.
Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Prüfungsfragen mit Lösungen (Q153-Q158):
153. Frage
The data architect has mandated that all tables in the Lakehouse should be configured as external (also known as "unmanaged") Delta Lake tables.
Which approach will ensure that this requirement is met?
- A. When data is saved to a table, make sure that a full file path is specified alongside the Delta format.
- B. When tables are created, make sure that the EXTERNAL keyword is used in the CREATE TABLE statement.
- C. When the workspace is being configured, make sure that external cloud object storage has been mounted.
- D. When a database is being created, make sure that the LOCATION keyword is used.
- E. When configuring an external data warehouse for all table storage, leverage Databricks for all ELT.
Antwort: B
Begründung:
To create an external or unmanaged Delta Lake table, you need to use the EXTERNAL keyword in the CREATE TABLE statement. This indicates that the table is not managed by the catalog and the data files are not deleted when the table is dropped. You also need to provide a LOCATION clause to specify the path where the data files are stored.
For example:
CREATE EXTERNAL TABLE events ( date DATE, eventId STRING, eventType STRING, data STRING) USING DELTA LOCATION `/mnt/delta/events'; This creates an external Delta Lake table named events that references the data files in the
`/mnt/delta/events' path. If you drop this table, the data files will remain intact and you can recreate the table with the same statement.
154. Frage
The view updates represents an incremental batch of all newly ingested data to be inserted or updated in the customers table.
The following logic is used to process these records.
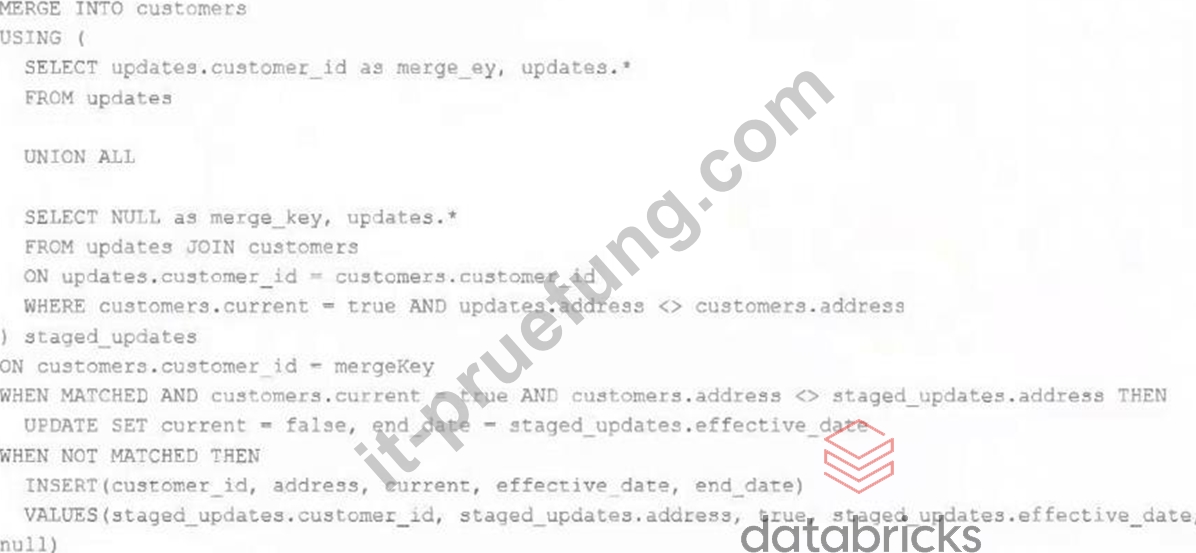
Which statement describes this implementation?
- A. The customers table is implemented as a Type 2 table; old values are maintained but marked as no longer current and new values are inserted.
- B. The customers table is implemented as a Type 0 table; all writes are append only with no changes to existing values.
- C. The customers table is implemented as a Type 1 table; old values are overwritten by new values and no history is maintained.
- D. The customers table is implemented as a Type 2 table; old values are overwritten and new customers are appended.
- E. The customers table is implemented as a Type 3 table; old values are maintained as a new column alongside the current value.
Antwort: A
155. Frage
A Delta Lake table representing metadata about content posts from users has the following schema:
user_id LONG, post_text STRING, post_id STRING, longitude FLOAT,
latitude FLOAT, post_time TIMESTAMP, date DATE
This table is partitioned by the date column. A query is run with the following filter:
longitude < 20 & longitude > -20
Which statement describes how data will be filtered?
- A. Statistics in the Delta Log will be used to identify data files that might include records in the filtered range.
- B. Statistics in the Delta Log will be used to identify partitions that might Include files in the filtered range.
- C. The Delta Engine will use row-level statistics in the transaction log to identify the flies that meet the filter criteria.
- D. No file skipping will occur because the optimizer does not know the relationship between the partition column and the longitude.
- E. The Delta Engine will scan the parquet file footers to identify each row that meets the filter criteria.
Antwort: A
Begründung:
This is the correct answer because it describes how data will be filtered when a query is run with the following filter: longitude < 20 & longitude > -20. The query is run on a Delta Lake table that has the following schema: user_id LONG, post_text STRING, post_id STRING, longitude FLOAT, latitude FLOAT, post_time TIMESTAMP, date DATE. This table is partitioned by the date column.
When a query is run on a partitioned Delta Lake table, Delta Lake uses statistics in the Delta Log to identify data files that might include records in the filtered range. The statistics include information such as min and max values for each column in each data file. By using these statistics, Delta Lake can skip reading data files that do not match the filter condition, which can improve query performance and reduce I/O costs.
156. Frage
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on task A.
If tasks A and B complete successfully but task C fails during a scheduled run, which statement describes the resulting state?
- A. All logic expressed in the notebook associated with tasks A and B will have been successfully completed; any changes made in task C will be rolled back due to task failure.
- B. Because all tasks are managed as a dependency graph, no changes will be committed to the Lakehouse until ail tasks have successfully been completed.
- C. All logic expressed in the notebook associated with task A will have been successfully completed; tasks B and C will not commit any changes because of stage failure.
- D. Unless all tasks complete successfully, no changes will be committed to the Lakehouse; because task C failed, all commits will be rolled back automatically.
- E. All logic expressed in the notebook associated with tasks A and B will have been successfully completed; some operations in task C may have completed successfully.
Antwort: E
Begründung:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The resulting state after running the second command is that an external table will be created in the storage container mounted to /mnt/finance_eda_bucket with the new name prod.sales_by_store. The command will not change any data or move any files in the storage container; it will only update the table reference in the metastore and create a new Delta transaction log for the renamed table.
157. Frage
A data engineer is configuring Delta Sharing for a Databricks-to-Databricks scenario to optimize read performance. The recipient needs to perform time travel queries and streaming reads on shared sales data. Which configuration will provide the optimal performance while enabling these capabilities?
- A. Share tables WITH HISTORY, ensure tables don't have partitioning enabled, and enable CDF before sharing.
- B. Use the open sharing protocol instead of Databricks-to-Databricks sharing for better performance.
- C. Share the entire schema WITHOUT HISTORY and rely on recipient-side caching for performance.
- D. Share tables WITHOUT HISTORY and enable partitioning for better query performance.
Antwort: A
Begründung:
The official Delta Sharing guidance specifies that in order for recipients to use time travel queries and streaming reads, providers must share Delta tables WITH HISTORY. Sharing history ensures the Delta log is included, which enables efficient access to table snapshots and incremental data streams.
Additionally, Change Data Feed (CDF) must be enabled prior to sharing if downstream consumers require streaming CDC queries. Without history, recipients cannot perform time travel or streaming queries. Open sharing supports static Delta tables but lacks streaming support.
Therefore, sharing tables WITH HISTORY and enabling CDF is the required configuration for both performance and functionality.
158. Frage
......
Sie können jetzt Databricks Certified-Data-Engineer-Professional Zertifikat erhalten. Unser It-Pruefung bietet die neue Version von Databricks Certified-Data-Engineer-Professional Prüfung. Sie brauchen nicht mehr, die neuesten Schulungsunterlagen von Databricks Certified-Data-Engineer-Professional zu suchen. Weil Sie die besten Schulungsunterlagen von Databricks Certified-Data-Engineer-Professional gefunden haben. Benutzen Sie beruhigt unsere Certified-Data-Engineer-Professional Schulungsunterlagen. Sie werden sicher die Databricks Certified-Data-Engineer-Professional Zertifizierungsprüfung bestehen.
Certified-Data-Engineer-Professional Examsfragen: https://www.it-pruefung.com/Certified-Data-Engineer-Professional.html
- Kostenlos Certified-Data-Engineer-Professional Dumps Torrent - Certified-Data-Engineer-Professional exams4sure pdf - Databricks Certified-Data-Engineer-Professional pdf vce ⬆ ➠ www.zertfragen.com 🠰 ist die beste Webseite um den kostenlosen Download von 【 Certified-Data-Engineer-Professional 】 zu erhalten 🌠Certified-Data-Engineer-Professional Musterprüfungsfragen
- Kostenlos Certified-Data-Engineer-Professional Dumps Torrent - Certified-Data-Engineer-Professional exams4sure pdf - Databricks Certified-Data-Engineer-Professional pdf vce 🏳 URL kopieren ⇛ www.itzert.com ⇚ Öffnen und suchen Sie “ Certified-Data-Engineer-Professional ” Kostenloser Download 🍆Certified-Data-Engineer-Professional Online Prüfung
- Certified-Data-Engineer-Professional Prüfungsübungen 🦈 Certified-Data-Engineer-Professional Musterprüfungsfragen 💟 Certified-Data-Engineer-Professional Prüfungsübungen 🌝 Suchen Sie jetzt auf ▷ www.zertsoft.com ◁ nach ☀ Certified-Data-Engineer-Professional ️☀️ um den kostenlosen Download zu erhalten 📻Certified-Data-Engineer-Professional Tests
- Neueste Certified-Data-Engineer-Professional Pass Guide - neue Prüfung Certified-Data-Engineer-Professional braindumps - 100% Erfolgsquote 🔫 Öffnen Sie die Webseite ⮆ www.itzert.com ⮄ und suchen Sie nach kostenloser Download von ▛ Certified-Data-Engineer-Professional ▟ 🔛Certified-Data-Engineer-Professional Tests
- Certified-Data-Engineer-Professional Prüfungsfragen, Certified-Data-Engineer-Professional Fragen und Antworten, Databricks Certified Data Engineer Professional 🍇 Suchen Sie jetzt auf ▶ www.pass4test.de ◀ nach ➡ Certified-Data-Engineer-Professional ️⬅️ um den kostenlosen Download zu erhalten ♣Certified-Data-Engineer-Professional Übungsmaterialien
- Certified-Data-Engineer-Professional Neuesten und qualitativ hochwertige Prüfungsmaterialien bietet - quizfragen und antworten ☣ Öffnen Sie ➽ www.itzert.com 🢪 geben Sie ⏩ Certified-Data-Engineer-Professional ⏪ ein und erhalten Sie den kostenlosen Download 🧺Certified-Data-Engineer-Professional PDF Testsoftware
- Certified-Data-Engineer-Professional Der beste Partner bei Ihrer Vorbereitung der Databricks Certified Data Engineer Professional 🐐 Öffnen Sie die Webseite ▶ www.zertpruefung.ch ◀ und suchen Sie nach kostenloser Download von ➥ Certified-Data-Engineer-Professional 🡄 ↩Certified-Data-Engineer-Professional Prüfungsinformationen
- Certified-Data-Engineer-Professional Neuesten und qualitativ hochwertige Prüfungsmaterialien bietet - quizfragen und antworten 🙈 Geben Sie ➡ www.itzert.com ️⬅️ ein und suchen Sie nach kostenloser Download von ➥ Certified-Data-Engineer-Professional 🡄 🌷Certified-Data-Engineer-Professional Lernressourcen
- Neueste Certified-Data-Engineer-Professional Pass Guide - neue Prüfung Certified-Data-Engineer-Professional braindumps - 100% Erfolgsquote 🤬 URL kopieren ⇛ www.zertsoft.com ⇚ Öffnen und suchen Sie ➠ Certified-Data-Engineer-Professional 🠰 Kostenloser Download 🌙Certified-Data-Engineer-Professional PDF Testsoftware
- Certified-Data-Engineer-Professional Vorbereitung ↗ Certified-Data-Engineer-Professional Übungsmaterialien 🥗 Certified-Data-Engineer-Professional Online Tests 🐇 ( www.itzert.com ) ist die beste Webseite um den kostenlosen Download von 《 Certified-Data-Engineer-Professional 》 zu erhalten ⤴Certified-Data-Engineer-Professional Kostenlos Downloden
- Certified-Data-Engineer-Professional Online Tests 🚣 Certified-Data-Engineer-Professional Deutsch Prüfungsfragen 💬 Certified-Data-Engineer-Professional Zertifizierung 🕋 Suchen Sie auf [ www.zertpruefung.ch ] nach kostenlosem Download von ⏩ Certified-Data-Engineer-Professional ⏪ 👝Certified-Data-Engineer-Professional Online Prüfung
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, forum.anchorpointpodcast.com, Disposable vapes