BONUS!!! Download part of PracticeTorrent DP-600 dumps for free: https://drive.google.com/open?id=1VA1EVfXXBxf0VXw3COCrrSGmOGLEys2K
Our company is a reliable and leading company in the business of DP-600 test dumps, we are famous for the commitment. We have in this business for years, and we have a team of high efficiency. The DP-600 test dumps are quite efficient and correct, we have the professional team for update of the DP-600 test material, and if we have any new version, we will send it to you timely, it will help you to pass the exam successfully.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Victory won't come to me unless I go to it. It is time to start to clear exam and obtain an IT certification to improve your competitor from our Microsoft DP-600 training PDF if you don't want to be discarded by epoch. Many IT workers have a nice improve after they get a useful certification. If you are willing, our DP-600 Training Pdf can give you a good beginning. No need to doubt and worry, thousands of candidates choose our exam training materials, you shouldn't miss this high pass-rate DP-600 training PDF materials.
NEW QUESTION # 208
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a Fabric tenant that contains a semantic model named Model1.
You discover that the following query performs slowly against Model1.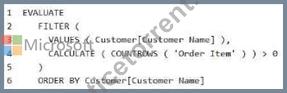
You need to reduce the execution time of the query.
Solution: You replace line 4 by using the following code:
NOT ( CALCULATE ( COUNTROWS ( 'Order Item' ) ) < 0)
Does this meet the goal?
Answer: A
Explanation:
This change is logically equivalent to the original condition and does not optimize the performance.
NEW QUESTION # 209
You have a Fabric tenant that contains a workspace named Workspace1. Workspace1 contains a lakehouse named Lakehouse1 and a warehouse named Warehouse1.
You need to create a new table in Warehouse1 named POSCustomers by querying the customer table in Lakehouse1.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.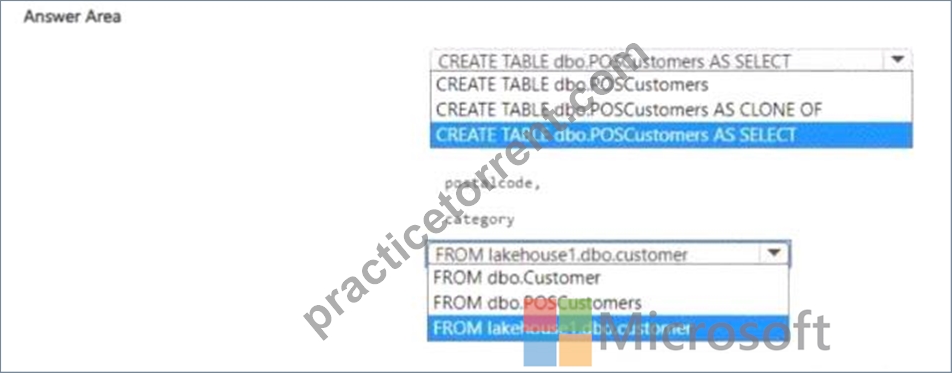
Answer:
Explanation:
Explanation: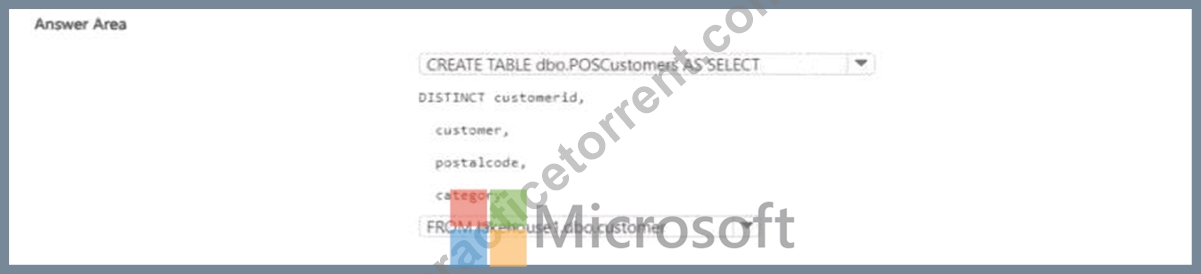
Step 1 - Creating the new table from a query
To create a table in a SQL warehouse using a query, the correct syntax is:
CREATE TABLE < table_name > AS SELECT ...
So we must select:
CREATE TABLE dbo.POSCustomers AS SELECT
Step 2 - Selecting the source table
Since the data source is the Lakehouse1 table Customer , the fully qualified name is:
lakehouse1.dbo.Customer
CREATE TABLE dbo.POSCustomers AS SELECT
postalcode,
category
FROM lakehouse1.dbo.Customer;
References:
CREATE TABLE AS SELECT (CTAS) in Fabric Warehouse
Fabric Lakehouse and Warehouse interoperability
NEW QUESTION # 210
You have a Fabric tenant that contains a lakehouse named Lakehouse1
Readings from 100 loT devices are appended to a Delta table in Lakehouse1. Each set of readings is approximately 25 KB. Approximately 10 GB of data is received daily.
All the table and SparkSession settings are set to the default.
You discover that queries are slow to execute. In addition, the lakehouse storage contains data and log files that are no longer used.
You need to remove the files that are no longer used and combine small files into larger files with a target size of 1 GB per file.
What should you do? To answer, drag the appropriate actions to the correct requirements. Each action may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.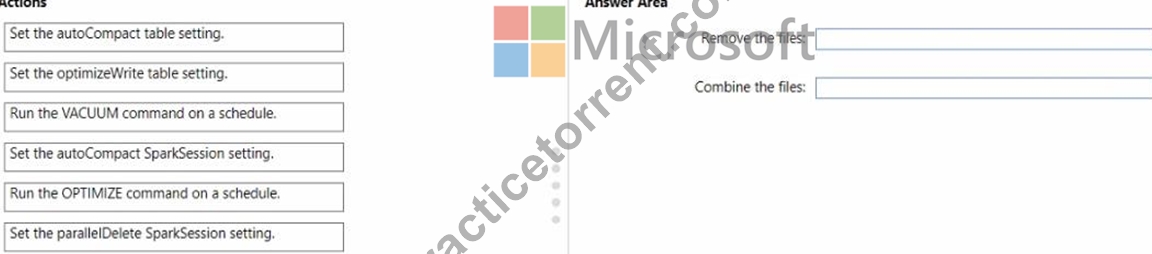
Answer:
Explanation: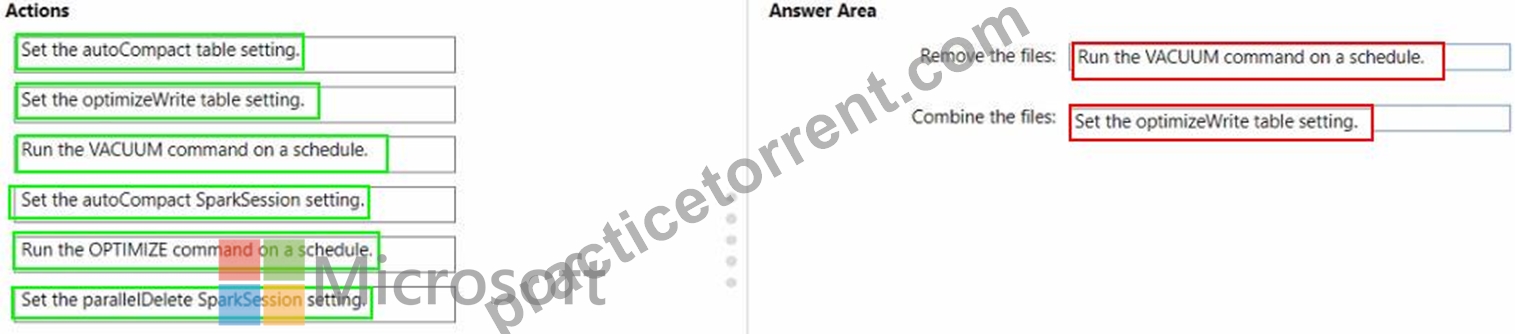
Topic 2, Litware. Inc.
Overview
Litware. Inc. is a manufacturing company that has offices throughout North America. The analytics team at Litware contains data engineers, analytics engineers, data analysts, and data scientists.
Existing Environment
litware has been using a Microsoft Power Bl tenant for three years. Litware has NOT enabled any Fabric capacities and features.
Fabric Environment
Litware has data that must be analyzed as shown in the following table.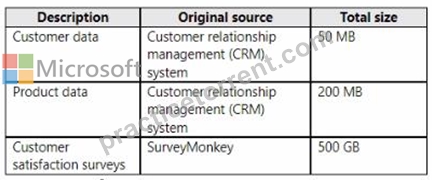
The Product data contains a single table and the following columns.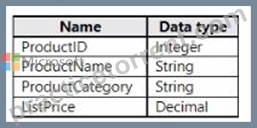
The customer satisfaction data contains the following tables:
* Survey
* Question
* Response
For each survey submitted, the following occurs:
* One row is added to the Survey table.
* One row is added to the Response table for each question in the survey.
The Question table contains the text of each survey question. The third question in each survey response is an overall satisfaction score. Customers can submit a survey after each purchase.
User Problems
The analytics team has large volumes of data, some of which is semi-structured. The team wants to use Fabric to create a new data store.
Product data is often classified into three pricing groups: high, medium, and low. This logic is implemented in several databases and semantic models, but the logic does NOT always match across implementations.
Planned Changes
Litware plans to enable Fabric features in the existing tenant. The analytics team will create a new data store as a proof of concept (PoC). The remaining Litware users will only get access to the Fabric features once the PoC is complete. The PoC will be completed by using a Fabric trial capacity.
The following three workspaces will be created:
* AnalyticsPOC: Will contain the data store, semantic models, reports, pipelines, dataflows, and notebooks used to populate the data store
* DataEngPOC: Will contain all the pipelines, dataflows, and notebooks used to populate Onelake
* DataSciPOC: Will contain all the notebooks and reports created by the data scientists The following will be created in the AnalyticsPOC workspace:
* A data store (type to be decided)
* A custom semantic model
* A default semantic model
* Interactive reports
The data engineers will create data pipelines to load data to OneLake either hourly or daily depending on the data source. The analytics engineers will create processes to ingest transform, and load the data to the data store in the AnalyticsPOC workspace daily. Whenever possible, the data engineers will use low-code tools for data ingestion. The choice of which data cleansing and transformation tools to use will be at the data engineers' discretion.
All the semantic models and reports in the Analytics POC workspace will use the data store as the sole data source.
Technical Requirements
The data store must support the following:
* Read access by using T-SQL or Python
* Semi-structured and unstructured data
* Row-level security (RLS) for users executing T-SQL queries
Files loaded by the data engineers to OneLake will be stored in the Parquet format and will meet Delta Lake specifications.
Data will be loaded without transformation in one area of the AnalyticsPOC data store. The data will then be cleansed, merged, and transformed into a dimensional model.
The data load process must ensure that the raw and cleansed data is updated completely before populating the dimensional model.
The dimensional model must contain a date dimension. There is no existing data source for the date dimension. The Litware fiscal year matches the calendar year. The date dimension must always contain dates from 2010 through the end of the current year.
The product pricing group logic must be maintained by the analytics engineers in a single location. The pricing group data must be made available in the data store for T-SQL queries and in the default semantic model. The following logic must be used:
* List prices that are less than or equal to 50 are in the low pricing group.
* List prices that are greater than 50 and less than or equal to 1,000 are in the medium pricing group.
* List pnces that are greater than 1,000 are in the high pricing group.
Security Requirements
Only Fabric administrators and the analytics team must be able to see the Fabric items created as part of the PoC. Litware identifies the following security requirements for the Fabric items in the AnalyticsPOC workspace:
* Fabric administrators will be the workspace administrators.
* The data engineers must be able to read from and write to the data store. No access must be granted to datasets or reports.
* The analytics engineers must be able to read from, write to, and create schemas in the data store. They also must be able to create and share semantic models with the data analysts and view and modify all reports in the workspace.
* The data scientists must be able to read from the data store, but not write to it. They will access the data by using a Spark notebook.
* The data analysts must have read access to only the dimensional model objects in the data store. They also must have access to create Power Bl reports by using the semantic models created by the analytics engineers.
* The date dimension must be available to all users of the data store.
* The principle of least privilege must be followed.
Both the default and custom semantic models must include only tables or views from the dimensional model in the data store. Litware already has the following Microsoft Entra security groups:
* FabricAdmins: Fabric administrators
* AnalyticsTeam: All the members of the analytics team
* DataAnalysts: The data analysts on the analytics team
* DataScientists: The data scientists on the analytics team
* Data Engineers: The data engineers on the analytics team
* Analytics Engineers: The analytics engineers on the analytics team
Report Requirements
The data analysis must create a customer satisfaction report that meets the following requirements:
* Enables a user to select a product to filter customer survey responses to only those who have purchased that product
* Displays the average overall satisfaction score of all the surveys submitted during the last 12 months up to a selected date
* Shows data as soon as the data is updated in the data store
* Ensures that the report and the semantic model only contain data from the current and previous year
* Ensures that the report respects any table-level security specified in the source data store
* Minimizes the execution time of report queries
NEW QUESTION # 211
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
Your network contains an on-premises Active Directory Domain Services (AD DS) domain named contoso.com that syncs with a Microsoft Entra tenant by using Microsoft Entra Connect.
You have a Fabric tenant that contains a semantic model.
You enable dynamic row-level security (RLS) for the model and deploy the model to the Fabric service.
You query a measure that includes the USERNAME() function, and the query returns a blank result.
You need to ensure that the measure returns the user principal name (UPN) of a user.
Solution: You update the measure to use the USEROBJECTID() function.
Does this meet the goal?
Answer: A
NEW QUESTION # 212
You have a Fabric tenant
You plan to create a data pipeline named Pipeline1. Pipeline1 will include two activities that will execute in sequence. You need to ensure that a failure of the first activity will NOT block the second activity. Which conditional path should you configure between the first activity and the second activity?
Answer: B
Explanation:
Upon Success: downstream runs only if the first activity succeeds.
Upon Failure: downstream runs only if the first activity fails.
Upon Skip: downstream runs if the activity was skipped.
Upon Completion: downstream runs regardless of whether the first activity succeeded or failed.
Since we want the second activity to run even if the first fails, the correct answer is Upon Completion.
Reference: Pipeline activity dependencies in Fabric Data Factory
NEW QUESTION # 213
......
Our world is in the state of constant change and evolving. If you want to keep pace of the time and continually transform and challenge yourself you must attend one kind of DP-600 certificate test to improve your practical ability and increase the quantity of your knowledge. Buying our DP-600 Study Materials can help you pass the test smoothly. Our DP-600 study materials have gone through strict analysis and verification by senior experts and are ready to supplement new resources at any time.
Study DP-600 Dumps: https://www.practicetorrent.com/DP-600-practice-exam-torrent.html
What's more, part of that PracticeTorrent DP-600 dumps now are free: https://drive.google.com/open?id=1VA1EVfXXBxf0VXw3COCrrSGmOGLEys2K