DOWNLOAD the newest Exam-Killer MuleSoft-Integration-Architect-I PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1cyuleOfCulw50hkZoBqyBDm2MwFR60vz
Though the content of our MuleSoft-Integration-Architect-I practice guide is the same, the varied formats indeed bring lots of conveniences to our customers. The PDF version of MuleSoft-Integration-Architect-I exam materials can be printed so that you can take it wherever you go. And the Software version can simulate the real exam environment and support offline practice. Besides, the APP online can be applied to all kind of electronic devices. No matter who you are, I believe you can do your best to achieve your goals through our MuleSoft-Integration-Architect-I Preparation questions!
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
>> Regualer MuleSoft-Integration-Architect-I Update <<
Our MuleSoft-Integration-Architect-I exam guide are not only rich and varied in test questions, but also of high quality. A very high hit rate gives you a good chance of passing the final MuleSoft-Integration-Architect-I exam. According to past statistics, 98 % - 99 % of the users who have used our MuleSoft-Integration-Architect-I Study Materials can pass the exam successfully. So without doubt, you will be our nest passer as well as long as you buy our MuleSoft-Integration-Architect-Ipractice braindumps.
NEW QUESTION # 233
Refer to the exhibit.
A shopping cart checkout process consists of a web store backend sending a sequence of API invocations to an Experience API, which in turn invokes a Process API. All API invocations are over HTTPS POST. The Java web store backend executes in a Java EE application server, while all API implementations are Mule applications executing in a customer -hosted Mule runtime.
End-to-end correlation of all HTTP requests and responses belonging to each individual checkout Instance is required. This is to be done through a common correlation ID, so that all log entries written by the web store backend, Experience API implementation, and Process API implementation include the same correlation ID for all requests and responses belonging to the same checkout instance.
What is the most efficient way (using the least amount of custom coding or configuration) for the web store backend and the implementations of the Experience API and Process API to participate in end-to-end correlation of the API invocations for each checkout instance?
A)
The web store backend, being a Java EE application, automatically makes use of the thread-local correlation ID generated by the Java EE application server and automatically transmits that to the Experience API using HTTP-standard headers No special code or configuration is included in the web store backend, Experience API, and Process API implementations to generate and manage the correlation ID
B)
The web store backend generates a new correlation ID value at the start of checkout and sets it on the X-CORRELATlON-lt HTTP request header In each API invocation belonging to that checkout No special code or configuration is included in the Experience API and Process API implementations to generate and manage the correlation ID
C)
The Experience API implementation generates a correlation ID for each incoming HTTP request and passes it to the web store backend in the HTTP response, which includes it in all subsequent API invocations to the Experience API.
The Experience API implementation must be coded to also propagate the correlation ID to the Process API in a suitable HTTP request header
D)
The web store backend sends a correlation ID value in the HTTP request body In the way required by the Experience API The Experience API and Process API implementations must be coded to receive the custom correlation ID In the HTTP requests and propagate It in suitable HTTP request headers
Answer: A
Explanation:
Correct answer is "The web store backend generates a new correlation ID value at the start of checkout and sets it on the X-CORRELATION-ID HTTP request header in each API invocation belonging to that checkout No special code or configuration is included in the Experience API and Process API implementations to generate and manage the correlation ID" : By design, Correlation Ids cannot be changed within a flow in Mule 4 applications and can be set only at source. This ID is part of the Event Context and is generated as soon as the message is received by the application. When a HTTP Request is received, the request is inspected for "X-Correlation-Id" header. If "X-Correlation-Id" header is present, HTTP connector uses this as the Correlation Id. If "X-Correlation-Id" header is NOT present, a Correlation Id is randomly generated. For Incoming HTTP Requests: In order to set a custom Correlation Id, the client invoking the HTTP request must set "X-Correlation-Id" header. This will ensure that the Mule Flow uses this Correlation Id. For Outgoing HTTP Requests: You can also propagate the existing Correlation Id to downstream APIs. By default, all outgoing HTTP Requests send "X-Correlation-Id" header. However, you can choose to set a different value to "X-Correlation-Id" header or set "Send Correlation Id" to NEVER.
Mulesoft Reference: https://help.mulesoft.com/s/article/How-to-Set-Custom-Correlation-Id-for-Flows-with-HTTP-Endpoint-in-Mule-4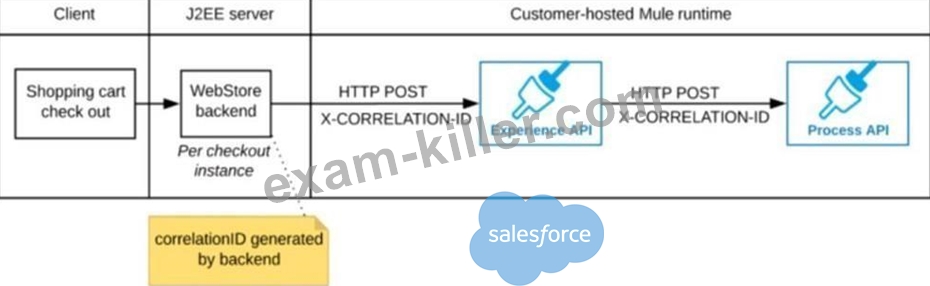
NEW QUESTION # 234
A Mule application is built to support a local transaction for a series of operations on a single database. The Mule application has a Scatter-Gather that participates in the local transaction.
What is the behavior of the Scatter-Gather when running within this local transaction?
Answer: C
NEW QUESTION # 235
An Order microservice and a Fulfillment microservice are being designed to communicate with their dients through message-based integration (and NOT through API invocations).
The Order microservice publishes an Order message (a kind of command message) containing the details of an order to be fulfilled. The intention is that Order messages are only consumed by one Mute application, the Fulfillment microservice.
The Fulfilment microservice consumes Order messages, fulfills the order described therein, and then publishes an OrderFulfilted message (a kind of event message). Each OrderFulfilted message can be consumed by any interested Mule application, and the Order microservice is one such Mute application.
What is the most appropriate choice of message broker(s) and message destination(s) in this scenario?
Answer: D
Explanation:
* If you need to scale a JMS provider/ message broker, - add nodes to scale it horizontally or - add memory to scale it vertically * Cons of adding another JMS provider/ message broker: - adds cost. - adds complexity to use two JMS brokers - adds Operational overhead if we use two brokers, say, ActiveMQ and IBM MQ * So Two options that mention to use two brokers are not best choice. * It's mentioned that "The Fulfillment microservice consumes Order messages, fulfills the order described therein, and then publishes an OrderFulfilled message. Each OrderFulfilled message can be consumed by any interested Mule application." - When you publish a message on a topic, it goes to all the subscribers who are interested - so zero to many subscribers will receive a copy of the message. - When you send a message on a queue, it will be received by exactly one consumer. * As we need multiple consumers to consume the message below option is not valid choice: "Order messages are sent to an Anypoint MQ exchange. OrderFulfilled messages are sent to an Anypoint MQ queue. Both microservices interact with Anypoint MQ as the message broker, which must therefore scale to support the load of both microservices" * Order messages are only consumed by one Mule application, the Fulfillment microservice, so we will publish it on queue and OrderFulfilled message can be consumed by any interested Mule application so it need to be published on Topic using same broker. * answer: Best choice in this scenario is: "Order messages are sent to a JMS queue. OrderFulfilled messages are sent to a JMS topic. Both microservices interact with the same JMS provider (message broker) instance, which must therefore scale to support the load of both microservices" Tried to depict scenario in diagram:
Diagram Description automatically generated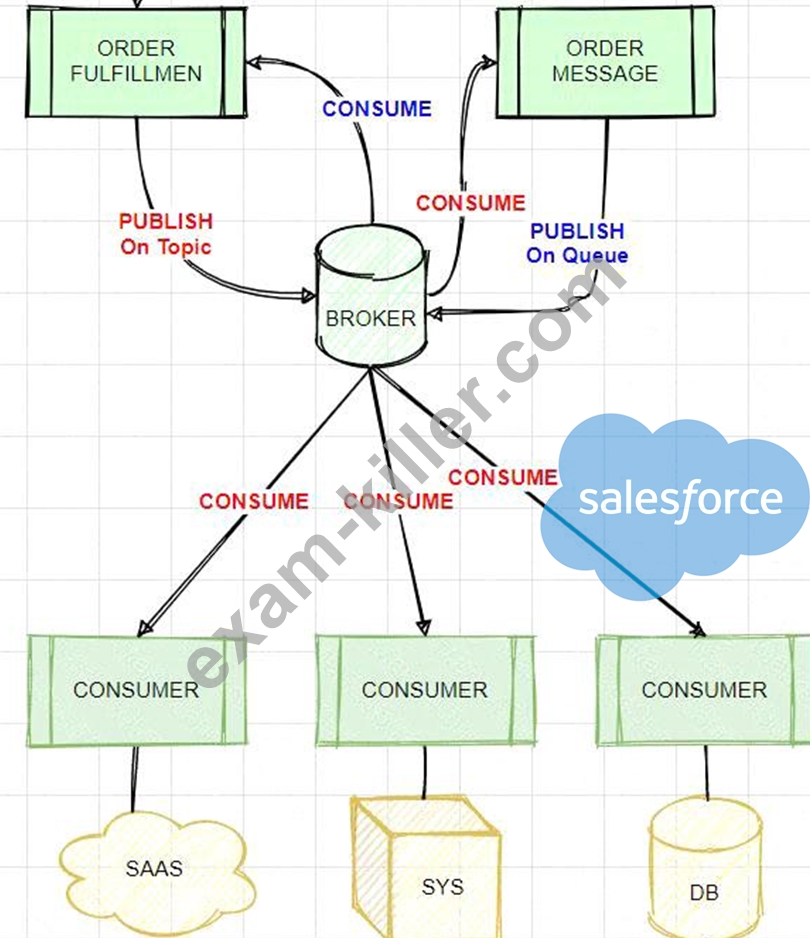
NEW QUESTION # 236
What is not true about Mule Domain Project?
Answer: A
Explanation:
* Mule Domain Project is ONLY available for customer-hosted Mule runtimes, but not for Anypoint Runtime Fabric
* Mule domain project is available for Hybrid and Private Cloud (PCE). Rest all provide application isolation and can't support domain project.
What is Mule Domain Project?
* A Mule Domain Project is implemented to configure the resources that are shared among different projects.
These resources can be used by all the projects associated with this domain. Mule applications can be associated with only one domain, but a domain can be associated with multiple projects. Shared resources allow multiple development teams to work in parallel using the same set of reusable connectors. Defining these connectors as shared resources at the domain level allows the team to: - Expose multiple services within the domain through the same port. - Share the connection to persistent storage. - Share services between apps through a well-defined interface. - Ensure consistency between apps upon any changes because the configuration is only set in one place.
* Use domains Project to share the same host and port among multiple projects. You can declare the http connector within a domain project and associate the domain project with other projects. Doing this also allows to control thread settings, keystore configurations, time outs for all the requests made within multiple applications. You may think that one can also achieve this by duplicating the http connector configuration across all the applications. But, doing this may pose a nightmare if you have to make a change and redeploy all the applications.
* If you use connector configuration in the domain and let all the applications use the new domain instead of a default domain, you will maintain only one copy of the http connector configuration. Any changes will require only the domain to the redeployed instead of all the applications.
You can start using domains in only three steps:
1) Create a Mule Domain project
2) Create the global connector configurations which needs to be shared across the applications inside the Mule Domain project
3) Modify the value of domain in mule-deploy.properties file of the applications Graphical user interface Description automatically generated
NEW QUESTION # 237
A corporation has deployed multiple mule applications implementing various public and private API's to different cloudhub workers. These API's arc Critical applications that must be highly available and in line with the reliability SLA as defined by stakeholders.
How can API availability (liveliness or readiness) be monitored so that Ops team receives outage notifications?
Answer: B
Explanation:
To ensure the high availability and reliability of critical APIs, it is essential to monitor their liveliness and readiness. Anypoint Monitoring provides comprehensive monitoring capabilities for Mule applications. Here' s how it can be implemented:
* Application Monitoring: Enable monitoring for each individual Mule application. This allows for real- time visibility into the performance and health of each API.
* Custom Dashboards: Create custom dashboards in Anypoint Monitoring to track key metrics such as response time, error rates, and throughput.
* Alerts and Notifications: Configure alerts based on specific failure conditions or performance thresholds. These alerts can notify the Ops team immediately when an outage or performance degradation is detected.
* Proactive Management: With detailed insights and proactive alerts, the Ops team can quickly respond to issues, ensuring that the APIs remain available and meet the defined SLAs.
References:
* Anypoint Monitoring
* Configuring Alerts
NEW QUESTION # 238
......
We will be happy to assist you with any questions regarding our products. Our Salesforce MuleSoft-Integration-Architect-I practice exam software helps to prepare applicants to practice time management, problem-solving, and all other tasks on the standardized exam and lets them check their scores. The Salesforce MuleSoft-Integration-Architect-I Practice Test results help students to evaluate their performance and determine their readiness without difficulty.
MuleSoft-Integration-Architect-I Test Dumps Free: https://www.exam-killer.com/MuleSoft-Integration-Architect-I-valid-questions.html
P.S. Free & New MuleSoft-Integration-Architect-I dumps are available on Google Drive shared by Exam-Killer: https://drive.google.com/open?id=1cyuleOfCulw50hkZoBqyBDm2MwFR60vz