DOWNLOAD the newest BraindumpStudy SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1w5FeiGwS20-JgTVAgaXEm2Q7-WsWRWw0
We have the SPS-C01 Questions and answers with high accuracy and timely update. Our professional team checks SPS-C01 answers and questions carefully with their professional knowledge. We also have the latest information about the exam center, and will update the version according to the new requirements. Pass guarantee and money back guarantee are also our principles, and if you have any questions, you can also consult the service stuff.
| Section | Objectives |
|---|---|
| Topic 1: Snowpark Fundamentals | - Snowpark architecture and concepts
|
| Topic 2: Data Engineering with Snowpark | - Pipeline development
|
| Topic 3: DataFrame Operations and Data Processing | - Data transformation workflows
|
| Topic 4: User Defined Functions and Stored Procedures | - Extending Snowpark with custom logic
|
| Topic 5: Testing, Debugging, and Deployment | - Production readiness
|
| Topic 6: Performance Optimization and Best Practices | - Efficient Snowpark execution
|
>> New SPS-C01 Test Registration <<
All the SPS-C01 study materials of our company are designed by the experts and professors in the field. The quality of our study materials is guaranteed. According to the actual situation of all customers, we will make the suitable study plan for all customers. If you buy the SPS-C01 Study Materials from our company, we can promise that you will get the professional training to help you pass your exam easily. By our professional training, you will pass your exam and get the related certification in the shortest time.
NEW QUESTION # 165
A data scientist is developing a Snowpark application that needs to authenticate to Snowflake using Key Pair Authentication. Which of the following steps are essential for configuring the Snowflake CLI to enable Key Pair Authentication and then correctly create a Snowpark session? (Select TWO)
Answer: B,E
Explanation:
Key Pair Authentication requires generating an RSA key pair (Option A) and configuring the Snowflake user with the public key (Option D). Setting the 'AUTHENTICATOR parameter to 'snowflake' is the correct approach. 'EXTERNALBROWSER uses the web-based browser authentication, while the private key is specified within the connection parameters directly, not the Snowflake CLI config.
NEW QUESTION # 166
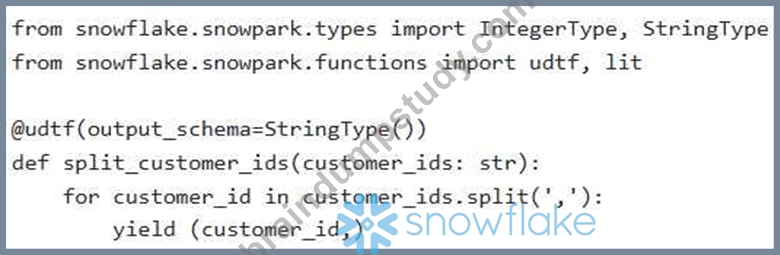
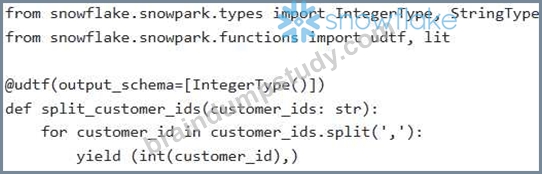
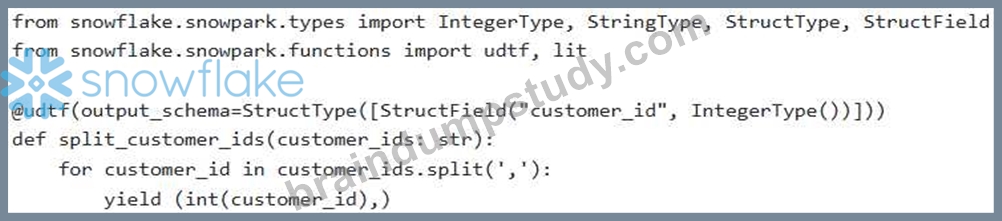
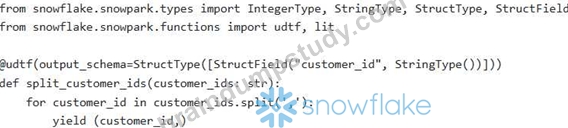
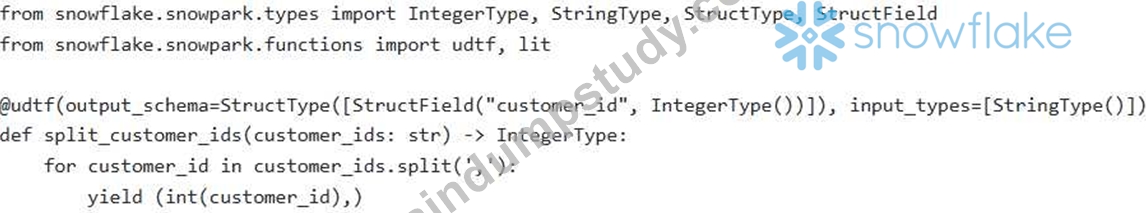
You are tasked with creating a UDTF using Snowpark Python that splits a comma-separated string of customer IDs into individual rows. The input is a string (VARCHAR) and the output should be a table with a single column named 'customer_id' of type INTEGER. Which of the following code snippets CORRECTLY defines and registers the UDTF, ensuring proper data type handling? Assume is a valid Snowpark Session object.
Answer: C
Explanation:
Option B correctly defines the UDTF. It uses 'StructType' and to define the output schema with a column named 'customer_id' of type "Integer Type'. The code also correctly converts the customer ID to an integer before yielding it. Option A defines the output schema as 'StringType' , which is incorrect. Option C does not correctly define a column name. Option D uses 'StringType' for the column, which violates the requirements. Option E adds and a return annotation which are valid, but the structure of the annotation is still not correct for a UDTF.
NEW QUESTION # 167
You have a Snowpark DataFrame named 'products' with columns 'product_id' (INT), 'product_name' (STRING), and 'price' (DOUBLE). You want to apply a transformation to calculate a 'discounted_price' column, which is the 'price' reduced by 10% if the price is greater than $100.00. Which of the following code snippets is the most efficient way to achieve this using Snowpark Python?





Answer: C,E
Explanation:
The most efficient ways are B and C. Option B directly uses the 'when' and 'otherwise' functions in Snowpark, which are optimized for execution within Snowflake. Option C is similar to B but explicitly uses 'lit' to represent the numeric literal, ensuring proper type handling in Snowpark. IJDFs (Option A) are generally less efficient than built-in functions. Option D attempts to use RDDs, which are not part of the Snowpark API. Option E is not valid Snowpark python syntax. Therefore, B and C are the correct answers.
NEW QUESTION # 168
You have a Snowpark DataFrame 'products_df with columns 'product_id', 'category', and 'price'. You want to find the top 3 most expensive products within each category Which of the following Snowpark code snippets will accomplish this, using window functions?





Answer: D
Explanation:
Option D correctly partitions the data by category, orders by price in descending order (most expensive first), assigns a rank using , and then filters for ranks less than or equal to 3. Option A misses the snowflake.snowpark.functions import, but functionally same as D. Option B orders by price in ascending order (cheapest first). Option C does not partition by category and Option E filters where rank < 3 instead of less than or equal to. D is most correct because of syntax and concept implementation, and will pass the code check
NEW QUESTION # 169
A data engineering team is building a Snowpark pipeline to process IoT sensor data'. They want to create a UDF that uses a 3rd-party Python library (not available in Snowflake's Anaconda channel) to analyze the sensor readings. The UDF needs to be efficiently deployed and managed within Snowflake. Which of the following approaches represents the MOST robust and scalable way to register and deploy this UDF using Snowpark?
Answer: C
Explanation:
Option B is the correct answer. It describes the best practice for deploying UDFs with external Python libraries in Snowflake. Creating a virtual environment, zipping it, uploading it to a stage, and referencing it during UDF registration ensures proper dependency management and avoids conflicts. Option A is problematic because embedding the library directly makes the UDF definition very large and unmanageable. Option C will not work if the required version isn't available. Option D is incorrect because functions.udf relies on packages available in the Snowflake Anaconda channel and doesn't manage custom packages. While Option E could work, its overly complex for this specific scenario compared to utilizing Snowpark virtual enviornment and stage management. Option B is more efficient and streamlined.
NEW QUESTION # 170
......
In order to provide a convenient study method for all people, our company has designed the online engine of the SPS-C01 study practice dump. The online engine is very convenient and suitable for all people to study, and you do not need to download and install any APP. We believe that the SPS-C01 exam questions from our company will help all customers save a lot of installation troubles. You just need to have a browser on your device you can use our study materials. We can promise that the SPS-C01 Prep Guide from our company will help you prepare for your exam well. If you decide to buy and use the study materials from our company, it means that you are not far from success.
Exam SPS-C01 Dumps: https://www.braindumpstudy.com/SPS-C01_braindumps.html
BONUS!!! Download part of BraindumpStudy SPS-C01 dumps for free: https://drive.google.com/open?id=1w5FeiGwS20-JgTVAgaXEm2Q7-WsWRWw0