P.S. ShikenPASSがGoogle Driveで共有している無料かつ新しいMule-Arch-201ダンプ:https://drive.google.com/open?id=1NOK04Ohi6GKPX1LZ1v9OlVq6h4Q8WdyN
Mule-Arch-201試験に合格して証明書を取得する方法に関する質問を検討していますか?最良の答えは、Mule-Arch-201クイズトレントをダウンロードして学習することです。 Mule-Arch-201試験の質問は、必要なものを短時間で取得するのに役立ちます。 Mule-Arch-201トレーニング準備を購入した後、ShikenPASSダウンロードしてインストールするのに少し時間が必要です。その後、学習するのに約20〜30時間かかります。 Mule-Arch-201試験ガイドをご覧いただき、貴重な時間を割いていただければ幸いです。
| Section | Weight | Objectives |
|---|---|---|
| Deploying API Implementations to CloudHub | 11% | - Deployment optimization and scaling - CloudHub architecture and capabilities - VPC and private space configuration - Worker sizing and resource planning |
| Managing APIs | 12% | - API policies and security enforcement - Rate limiting and throttling - Versioning and deprecation strategies - API lifecycle management |
| Monitoring and Analyzing Application Networks | 8% | - Monitoring strategies and tools - Logging and alerting configuration - Analytics and insight generation - Operational visibility and optimization |
| Designing and Sharing APIs | 11% | - API layering: Experience, Process, System APIs - API specification and documentation - API design standards and best practices - Asset sharing and reuse via Anypoint Exchange |
| Architecting and Deploying API Implementations | 11% | - Runtime architecture and deployment options - High availability and fault tolerance - CI/CD and DevOps integration - Networking and security configuration |
| Explaining Application Network Basics | 11% | - Core concepts of application networks - Benefits of modern API design - API-led connectivity principles |
| Establishing Organizational and Platform Foundations | 17% | - Anypoint Platform architecture and components - Governance and organizational structure - Center for Enablement (C4E) operating model - Platform strategy and roadmap definition |
| Meeting API Quality Goals | 8% | - Security and compliance standards - Maintainability and testability - Reliability and availability targets - Performance and latency requirements |
| Applying Integration Patterns | 11% | - Event-driven and synchronous integration - Scalability and performance patterns - Error handling and reliability patterns - Common integration patterns and use cases |
今は、もっと難しい認定試験を受けることを恐れる時ではありません。 Mule-Arch-201学習クイズでは、限られた時間内に問題を解決できます。当社のウェブサイトは、優れた学習ガイダンス、実践的な質問と回答、そしてあなたの本当の強みである選択のための質問を提供します。 Mule-Arch-201トレーニング資料を受け取り、問題なく渡すことができます。
質問 # 25
The Line of Business (LoB) of an eCommerce company is requesting a process that sends automated notifications via email every time a new order is processed through the customer's mobile application or through the internal company's web application. In the future, multiple notification channels may be added: for example, text messages and push notifications.
What is the most effective API-led connectivity approach for the scenario described above?
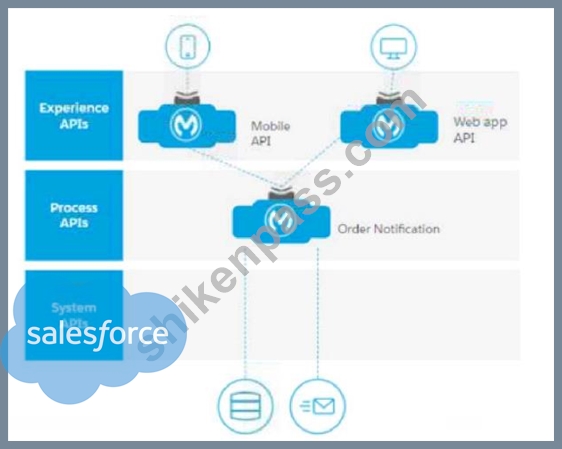
正解:C
解説:
In this scenario, the best approach to satisfy the API-led connectivity principles and support future scalability is:
Experience APIs:
Create separate Experience APIs for the web application and the mobile application. This allows each application to have an optimized interface, supporting different needs and potential differences in request/response structures or security configurations.
Process API:
A single Process API can be used to orchestrate the workflow, including retrieving the email template from a database and preparing the email content. By centralizing this logic in the Process layer, we can ensure it is reusable and easily adaptable for different notification channels in the future.
System API:
A System API specifically designed for sending emails (using the Anypoint Connector for Email) abstracts the email-sending functionality from the business logic. This approach ensures that the email-sending function is reusable and scalable, and it can easily be extended or modified if other notification channels (like SMS or push notifications) are added later.
Why Option A is Correct:
This structure aligns with API-led connectivity principles by separating concerns across Experience, Process, and System layers. It provides flexibility for future notification channels and isolates each layer's responsibility, making it easier to maintain and scale.
of Incorrect Options:
Option B lacks a separate System API for sending emails, which goes against the principle of isolating back-end functionality in System APIs.
Option C similarly lacks a dedicated System API, reducing flexibility and reusability.
Option D suggests creating multiple Process APIs for database retrieval, which adds unnecessary complexity and does not adhere to the single-orchestration principle typically followed in API-led design.
Reference
For further guidance on API-led connectivity and the responsibilities of each API layer, refer to MuleSoft's documentation on API-led architecture and design best practices.
質問 # 26
In an organization, the InfoSec team is investigating Anypoint Platform related data traffic.
From where does most of the data available to Anypoint Platform for monitoring and alerting originate?
正解:B
解説:
Correct Answe r: From the Mule runtime irrespective of the deployment model
*****************************************
>> Monitoring and Alerting metrics are always originated from Mule Runtimes irrespective of the deployment model.
>> It may seems that some metrics (Runtime Manager) are originated from Mule Runtime and some are (API Invocations/ API Analytics) from API Manager. However, this is realistically NOT TRUE. The reason is, API manager is just a management tool for API instances but all policies upon applying on APIs eventually gets executed on Mule Runtimes only (Either Embedded or API Proxy).
>> Similarly all API Implementations also run on Mule Runtimes.
So, most of the day required for monitoring and alerts are originated fron Mule Runtimes only irrespective of whether the deployment model is MuleSoft-hosted or Customer-hosted or Hybrid.
質問 # 27
A Rate Limiting policy is applied to an API implementation to protect the back-end system. Recently, there have been surges in demand that cause some API client POST requests to the API implementation to be rejected with policy-related errors, causing delays and complications to the API clients.
How should the API policies that are applied to the API implementation be changed to reduce the frequency of errors returned to API clients, while still protecting the back-end system?
正解:C
解説:
When managing high traffic to an API, especially with POST requests, it is crucial to ensure the API's policies both protect the back-end systems and provide a smooth client experience. Here's the approach to reducing errors:
Rate Limiting Policy: This policy enforces a limit on the number of requests within a defined time period. However, rate limiting alone may cause clients to hit limits during demand surges, leading to errors.
Adding an SLA-based Spike Control Policy:
Spike Control is designed to handle sudden increases in traffic by smoothing out bursts of requests, which is particularly useful during high-demand periods.
By configuring SLA-based Spike Control, you can define thresholds for specific client tiers. For instance, premium clients might have higher limits or more flexibility in traffic bursts than standard clients.
Why Option D is Correct:
Keeping the Rate Limiting policy continues to provide baseline protection for the back-end.
Adding the SLA-based Spike Control policy allows for differentiated control, where requests are queued or delayed during bursts rather than outright rejected. This approach significantly reduces error responses to clients while still controlling overall traffic.
of Incorrect Options:
Option A (adding Client ID Enforcement) would not reduce errors related to traffic surges.
Option B (HTTP Caching) is not applicable as caching is generally ineffective for non-idempotent requests like POST.
Option C (only Spike Control without Rate Limiting) may leave the back-end system vulnerable to sustained high traffic levels, reducing protection.
Reference
For more information on configuring Rate Limiting and SLA-based Spike Control policies, refer to MuleSoft documentation on API Policies and Rate Limiting.
質問 # 28
A company uses a hybrid Anypoint Platform deployment model that combines the EU control plane with customer-hosted Mule runtimes. After successfully testing a Mule API implementation in the Staging environment, the Mule API implementation is set with environment-specific properties and must be promoted to the Production environment. What is a way that MuleSoft recommends to configure the Mule API implementation and automate its promotion to the Production environment?
正解:A
解説:
Correct Answe r: Bundle properties files for each environment into the Mule API implementation's deployable archive, then promote the Mule API implementation to the Production environment using Anypoint CLI or the Anypoint Platform REST APIs
*****************************************
>> Anypoint Exchange is for asset discovery and documentation. It has got no provision to modify the properties of Mule API implementations at all.
>> API Manager is for managing API instances, their contracts, policies and SLAs. It has also got no provision to modify the properties of API implementations.
>> API policies are to address Non-functional requirements of APIs and has again got no provision to modify the properties of API implementations.
So, the right way and recommended way to do this as part of development practice is to bundle properties files for each environment into the Mule API implementation and just point and refer to respective file per environment.
質問 # 29
An Order API must be designed that contains significant amounts of integration logic and involves the invocation of the Product API.
The power relationship between Order API and Product API is one of "Customer/Supplier", because the Product API is used heavily throughout the organization and is developed by a dedicated development team located in the office of the CTO.
What strategy should be used to deal with the API data model of the Product API within the Order API?
正解:A
解説:
Correct Answe r: Convince the development team of the product API to adopt the API data model of the Order API such that integration logic of the Order API can work with one consistent internal data model
*****************************************
Key details to note from the given scenario:
>> Power relationship between Order API and Product API is customer/supplier So, as per below rules of "Power Relationships", the caller (in this case Order API) would request for features to the called (Product API team) and the Product API team would need to accomodate those requests.
質問 # 30
......
お客様に最高のサービスをお楽しみいただくために、当社のMule-Arch-201試験準備はすべて、何百人もの経験豊富な専門家によって設計されました。 Mule-Arch-201テストの質問は、お客様が試験に関する重要な知識を学ぶのに役立ちます。同時に、Mule-Arch-201テストトレントは、暗記学習の習慣に陥るのを防ぐのに役立ちます。学習に20〜30時間費やすだけで、Mule-Arch-201試験を受けて合格することができます。さらに、当社のMule-Arch-201試験準備の正式な制作チームは、お客様に最新の情報をお楽しみいただけるよう、毎日学習システムを更新します。
Mule-Arch-201実際試験: https://www.shikenpass.com/Mule-Arch-201-shiken.html
無料でクラウドストレージから最新のShikenPASS Mule-Arch-201 PDFダンプをダウンロードする:https://drive.google.com/open?id=1NOK04Ohi6GKPX1LZ1v9OlVq6h4Q8WdyN