P.S. Free 2026 Google Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by Real4dumps: https://drive.google.com/open?id=15DtUpiH2Ju7gKTyepgRKzKfqwnSj7-yN
We have a special technical customer service staff to solve all kinds of consumers’ problems on our Professional-Machine-Learning-Engineer exam questions. If you have questions when installing or using our Professional-Machine-Learning-Engineer practice engine, you can always contact our customer service staff via email or online consultation. They will solve your questions about Professional-Machine-Learning-Engineer Preparation materials with enthusiasm and professionalism, giving you a timely response whenever you contact them.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Real Exam Qty: | 50-60 |
| Passing Score: | Not officially published, approximately 70% |
| Related Certifications: | Google Cloud Professional Cloud Architect Google Cloud Professional Data Engineer |
| Exam Price: | $200 USD (plus tax where applicable) |
| Exam Duration: | 120 minutes |
| Certificate Validity Period: | 2 years |
| Exam Format: | Multiple choice, Multiple select |
| Available Languages: | Japanese, English |
| Recommended Training: | Google Cloud Skills Boost - Professional Machine Learning Engineer Learning Path Official Exam Guide |
| Exam Registration: | Google Cloud Certification Registration |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online-proctored remote exam or onsite-proctored exam at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended 3+ years industry experience including 1+ year designing/managing Google Cloud solutions |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Professional-Machine-Learning-Engineer Preparation Store <<
Through years of marketing, our Professional-Machine-Learning-Engineer latest certification guide has won the support of many customers. The most obvious data is that our products are gradually increasing each year, and it is a great effort to achieve such a huge success thanks to our product development. First of all, we have done a very good job in studying the updating of materials. In addition, the quality of our Professional-Machine-Learning-Engineer real study braindumps is strictly controlled by teachers. So, believe that we are the right choice, if you have any questions about our study materials, you can consult us.
Earning the Google Professional Machine Learning Engineer certification demonstrates to employers and clients that an individual has the skills and knowledge to design, build, and deploy machine learning models using Google Cloud technologies. It also opens up opportunities for career growth and advancement in the field of machine learning.
NEW QUESTION # 153
You have developed an application that uses a chain of multiple scikit-learn models to predict the optimal price for your company's products. The workflow logic is shown in the diagram Members of your team use the individual models in other solution workflows. You want to deploy this workflow while ensuring version control for each individual model and the overall workflow Your application needs to be able to scale down to zero. You want to minimize the compute resource utilization and the manual effort required to manage this solution. What should you do?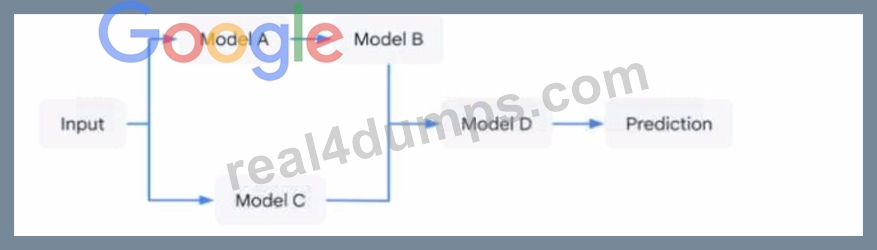
Answer: A
NEW QUESTION # 154
A Machine Learning Specialist must build out a process to query a dataset on Amazon S3 using Amazon Athena. The dataset contains more than 800,000 records stored as plaintext CSV files. Each record contains
200 columns and is approximately 1.5 MB in size. Most queries will span 5 to 10 columns only.
How should the Machine Learning Specialist transform the dataset to minimize query runtime?
Answer: D
Explanation:
Using compressions will reduce the amount of data scanned by Amazon Athena, and also reduce your S3 bucket storage. It's a Win-Win for your AWS bill. Supported formats: GZIP, LZO, SNAPPY (Parquet) and ZLIB.
Reference: https://www.cloudforecast.io/blog/using-parquet-on-athena-to-save-money-on-aws/
NEW QUESTION # 155
You want to rebuild your ML pipeline for structured data on Google Cloud. You are using PySpark to conduct data transformations at scale, but your pipelines are taking over 12 hours to run. To speed up development and pipeline run time, you want to use a serverless tool and SQL syntax.
You have already moved your raw data into Cloud Storage. How should you build the pipeline on Google Cloud while meeting the speed and processing requirements?
Answer: C
Explanation:
BigQuery is a serverless, highly scalable, and cost-effective cloud data warehouse. It can be used to store and query large amounts of data using SQL syntax. BigQuery Load is a tool that can be used to load data into BigQuery from a variety of sources, including Cloud Storage.
NEW QUESTION # 156
You work for a company that builds bridges for cities around the world. To track the progress of projects at construction sites, your company has set up cameras at each location. Each hour, the cameras take a picture that is sent to a Cloud Storage bucket. A team of specialists reviews the images, filters important ones, and then annotates unique specialized construction equipment in the images. You want to propose an ML solution that will help the company scale and reduce costs for this process. You need the solution to have minimal up-front cost. What method should you propose?
Answer: B
NEW QUESTION # 157
You are the Director of Data Science at a large company, and your Data Science team has recently begun using the Kubeflow Pipelines SDK to orchestrate their training pipelines. Your team is struggling to integrate their custom Python code into the Kubeflow Pipelines SDK. How should you instruct them to proceed in order to quickly integrate their code with the Kubeflow Pipelines SDK?
Answer: A
Explanation:
The easiest way to integrate custom Python code into the Kubeflow Pipelines SDK is to use the func_to_container_op function, which converts a Python function into a pipeline component. This function automatically builds a Docker image that executes the Python function, and returns a factory function that can be used to create kfp.dsl.ContainerOp instances for the pipeline. This option has the following benefits:
* It allows the data science team to reuse their existing Python code without rewriting it or packaging it into containers manually.
* It simplifies the component specification and implementation, as the function signature defines the component interface and the function body defines the component logic.
* It supports various types of inputs and outputs, such as primitive types, files, directories, and dictionaries.
The other options are less optimal for the following reasons:
* Option B: Using the predefined components available in the Kubeflow Pipelines SDK to access Dataproc, and run the custom code there, introduces additional complexity and cost. This option requires creating and managing Dataproc clusters, which are ephemeral and scalable clusters of Compute Engine instances that run Apache Spark and Apache Hadoop. Moreover, this option requires writing the custom code in PySpark or Hadoop MapReduce, which may not be compatible with the existing Python code.
* Option C: Packaging the custom Python code into Docker containers, and using the load_component_from_file function to import the containers into the pipeline, introduces additional steps and overhead. This option requires creating and maintaining Dockerfiles, building and pushing Docker images, and writing component specifications in YAML files. Moreover, this option requires managing the dependencies and versions of the Python code and the Docker images.
* Option D: Deploying the custom Python code to Cloud Functions, and using Kubeflow Pipelines to trigger the Cloud Function, introduces additional latency and limitations. This option requires creating and deploying Cloud Functions, which are serverless functions that execute in response to events.
Moreover, this option requires invoking the Cloud Functions from the Kubeflow Pipelines using HTTP requests, which can incur network overhead and latency. Additionally, this option is subject to the quotas and limits of Cloud Functions, such as the maximum execution time and memory usage.
:
Building Python function-based components | Kubeflow
Building Python Function-based Components | Kubeflow
NEW QUESTION # 158
......
Download Professional-Machine-Learning-Engineer Free Dumps: https://www.real4dumps.com/Professional-Machine-Learning-Engineer_examcollection.html
What's more, part of that Real4dumps Professional-Machine-Learning-Engineer dumps now are free: https://drive.google.com/open?id=15DtUpiH2Ju7gKTyepgRKzKfqwnSj7-yN