Free PDF 2026 Accurate Databricks Databricks-Certified-Data-Engineer-Associate: New Databricks Certified Data Engineer Associate Exam Test Dumps

You can finish practicing all the contents in our Databricks Databricks-Certified-Data-Engineer-Associate practice materials within 20 to 30 hours, and you will be confident enough to attend the exam for our Databricks Certified Data Engineer Associate Exam Databricks-Certified-Data-Engineer-Associate exam dumps are exact compiled with the questions and answers of the real exam. During the whole year after purchasing, you will get the latest version of our Databricks-Certified-Data-Engineer-Associate Study Materials for free.
Databricks Certified Data Engineer Associate Exam is ideal for data engineers, data analysts, data scientists, and other professionals who are interested in building and maintaining data pipelines using Databricks. By achieving this certification, candidates can demonstrate their expertise in working with Databricks and their ability to build and maintain scalable data pipelines. Databricks Certified Data Engineer Associate Exam certification can also help professionals advance their careers and open up new job opportunities in the field of data engineering.
Databricks Certified Data Engineer Associate Exam is a vendor-neutral certification that tests candidates on their understanding of Databricks architecture and features, data ingestion and processing, data transformation and storage, and machine learning. Databricks-Certified-Data-Engineer-Associate Exam also covers important concepts such as performance tuning, security, and troubleshooting in Databricks. Passing the exam demonstrates that a candidate has the skills, knowledge, and expertise to work with Databricks to design, build, and maintain advanced data pipelines and solutions.
>> New Databricks-Certified-Data-Engineer-Associate Test Dumps <<
High-quality New Databricks-Certified-Data-Engineer-Associate Test Dumps - Pass Databricks-Certified-Data-Engineer-Associate Once - Complete Frenquent Databricks-Certified-Data-Engineer-Associate Update
Many candidates said that they failed once, now try the second time but they still have no confidence, they want to know if our Databricks-Certified-Data-Engineer-Associate braindumps PDF materials can help them clear exam 100%. We say "Yes, 100% passing rate for most exams". They would like to purchase Databricks-Certified-Data-Engineer-Associate Braindumps Pdf materials since they understand the test cost is quite expensive and passing exam is not really easy. Why not choose Databricks-Certified-Data-Engineer-Associate braindumps PDF materials at the beginning?
The GAQM Databricks-Certified-Data-Engineer-Associate (Databricks Certified Data Engineer Associate) Certification Exam is designed for individuals who are interested in pursuing a career in data engineering. Databricks Certified Data Engineer Associate Exam certification exam is developed in collaboration with Databricks, a leading data and AI company that provides a unified analytics platform for data engineering, data science, and machine learning. The Databricks-Certified-Data-Engineer-Associate Exam Tests candidates on their knowledge of data engineering principles, practices, and tools.
Databricks Certified Data Engineer Associate Exam Sample Questions (Q261-Q266):
NEW QUESTION # 261
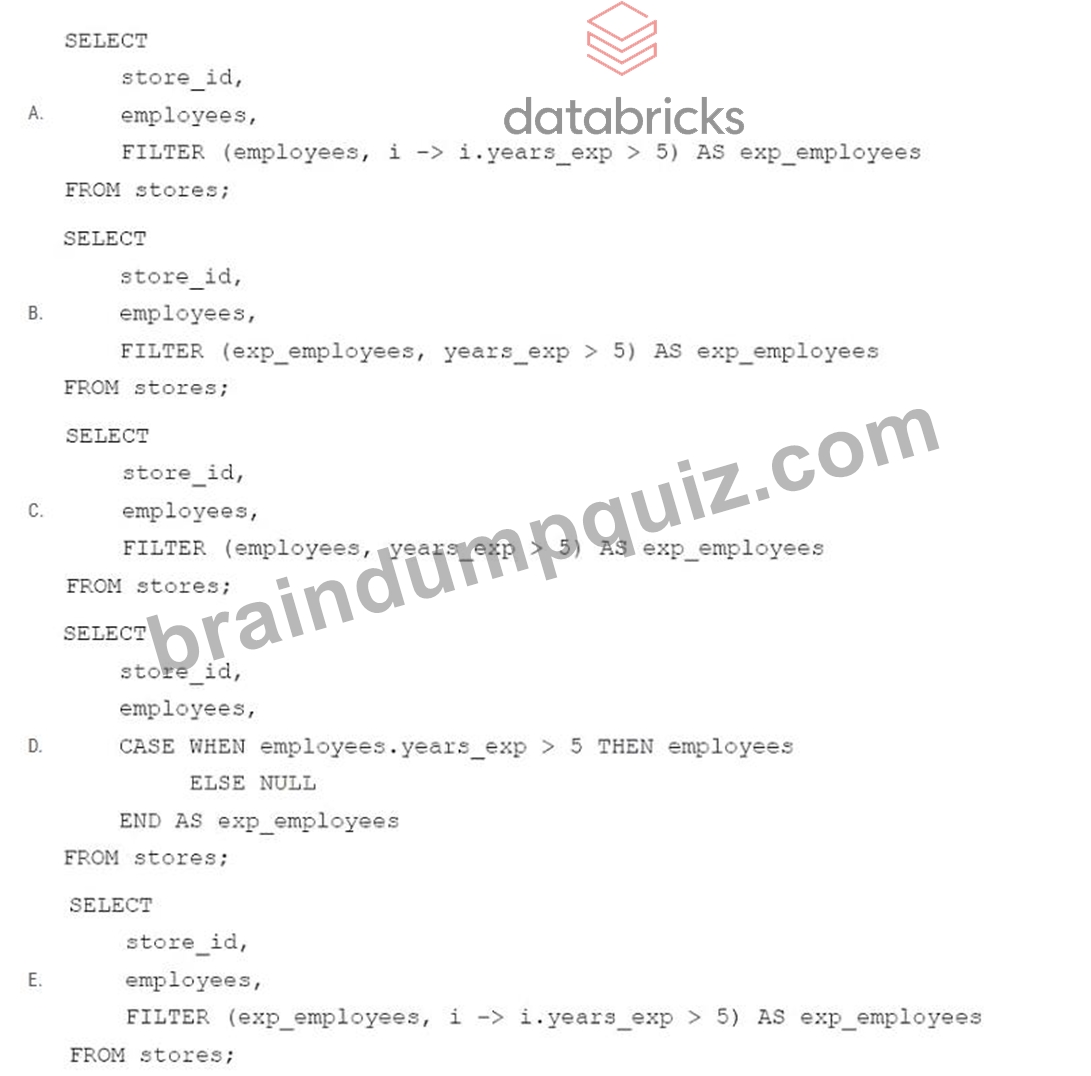
A data engineer needs to apply custom logic to identify employees with more than 5 years of experience in array column employees in table stores. The custom logic should create a new column exp_employees that is an array of all of the employees with more than 5 years of experience for each row. In order to apply this custom logic at scale, the data engineer wants to use the FILTER higher-order function.
Which of the following code blocks successfully completes this task?
- A. Option C
- B. Option D
- C. Option B
- D. Option E
- E. Option A
Answer: E
Explanation:
Option A is the correct answer because it uses the FILTER higher-order function correctly to filter out employees with more than 5 years of experience from the array column "employees". It applies a lambda function i -> i.years_exp > 5 that checks if the years of experience of each employee in the array is greater than 5. If this condition is met, the employee is included in the new array column "exp_employees".
The use of higher-order functions like FILTER can be referenced from Databricks documentation on Higher-Order Functions.
NEW QUESTION # 262
A data engineer wants to schedule their Databricks SQL dashboard to refresh every hour, but they only want the associated SQL endpoint to be running when it is necessary. The dashboard has multiple queries on multiple datasets associated with it. The data that feeds the dashboard is automatically processed using a Databricks Job.
Which of the following approaches can the data engineer use to minimize the total running time of the SQL endpoint used in the refresh schedule of their dashboard?
- A. They can turn on the Auto Stop feature for the SQL endpoint.
- B. They can reduce the cluster size of the SQL endpoint.
- C. They can set up the dashboard's SQL endpoint to be serverless.
- D. They can ensure the dashboard's SQL endpoint is not one of the included query's SQL endpoint.
- E. They can ensure the dashboard's SQL endpoint matches each of the queries' SQL endpoints.
Answer: A
Explanation:
The Auto Stop feature allows the SQL endpoint to automatically stop after a specified period of inactivity. This can help reduce the cost and resource consumption of the SQL endpoint, as it will only run when it is needed to refresh the dashboard or execute queries. The data engineer can configure the Auto Stop setting for the SQL endpoint from the SQL Endpoints UI, by selecting the desired idle time from the Auto Stop dropdown menu. The default idle time is 120 minutes, but it can be set to as low as 15 minutes or as high as 240 minutes. Alternatively, the data engineer can also use the SQL Endpoints REST API to set the Auto Stop setting programmatically. Reference: SQL Endpoints UI, SQL Endpoints REST API, Refreshing SQL Dashboard
NEW QUESTION # 263
In which of the following file formats is data from Delta Lake tables primarily stored?
- A. JSON
- B. Delta
- C. A proprietary, optimized format specific to Databricks
- D. Parquet
- E. CSV
Answer: D
Explanation:
Explanation
https://docs.delta.io/latest/delta-faq.html
NEW QUESTION # 264
A data engineer is migrating pipeline tasks to reduce operational toil. The workspace uses Unity Catalog and is in a region that supports serverless. The engineer wants Databricks to auto-select instance types, manage scaling, apply Photon, and handle runtime upgrades automatically for job runs.
How should the data engineer meet this requirement while adhering to Databricks constraints?
- A. Use an all-purpose cluster with cluster policies to enforce standard sizes and enable autoscaling.
- B. Create a job with a single-task job cluster and manually set the instance families and minimum/maximum workers.
- C. Run the job on a serverless compute for workflows configuration, ensuring Unity Catalog is enabled and regional support is available.
- D. Use a Pro SQL warehouse and schedule Python notebook tasks to execute as pipeline steps.
Answer: C
Explanation:
Serverless compute for workflows is designed to minimize operational overhead for Databricks Jobs while enforcing Unity Catalog governance. When a job is configured to run on serverless compute (in supported regions), Databricks automatically selects instance types, manages autoscaling, enables Photon where applicable, and handles runtime upgrades without user intervention. This directly satisfies the requirement to reduce operational toil. All-purpose clusters (option B) and traditional job clusters (option C) still require users to manage cluster sizing, instance families, and runtime versions, which contradicts the goal of automation. SQL warehouses (option A) are intended for SQL workloads and do not support running general Python notebook job tasks as workflow steps. Databricks documentation specifies that serverless workflows are compatible with Unity Catalog and are the recommended approach when users want fully managed compute for scheduled pipelines and tasks, provided the workspace is in a supported region. This makes serverless compute the correct and fully compliant solution.
NEW QUESTION # 265
A data engineer is working with two tables. Each of these tables is displayed below in its entirety.
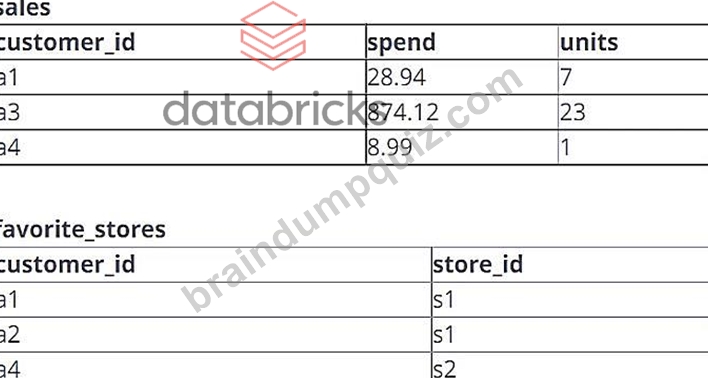
The data engineer runs the following query to join these tables together:
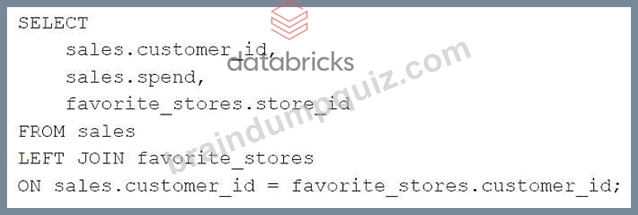
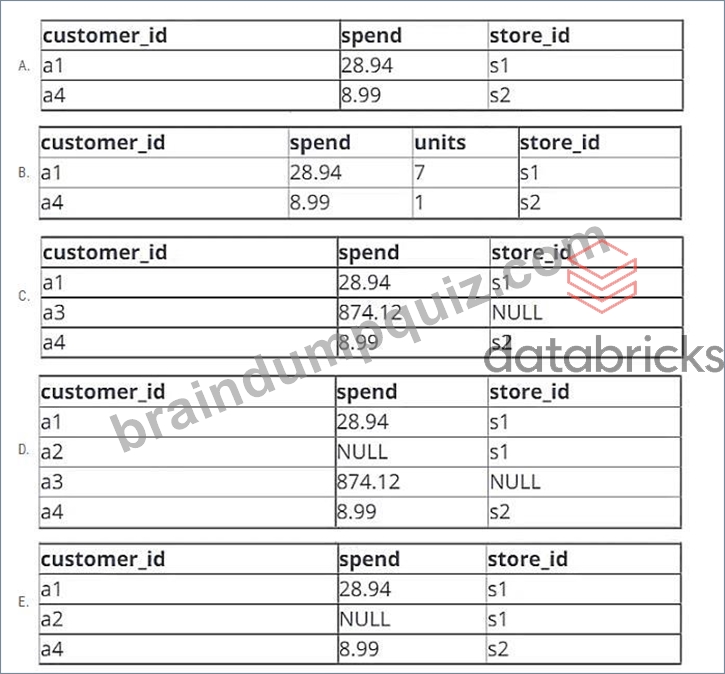
Which of the following will be returned by the above query?
- A. Option C
- B. Option D
- C. Option B
- D. Option E
- E. Option A
Answer: E
Explanation:
Option A is the correct answer because it shows the result of an INNER JOIN between the two tables. An INNER JOIN returns only the rows that have matching values in both tables based on the join condition. In this case, the join condition is ON a.customer_id = c.customer_id, which means that only the rows that have the same customer ID in both tables will be included in the output. The output will have four columns:
customer_id, name, account_id, and overdraft_amt. The output will have four rows, corresponding to the four customers who have accounts in the account table.
The use of INNER JOIN can be referenced from Databricks documentation on SQL JOIN or from other sources like W3Schools or GeeksforGeeks.
NEW QUESTION # 266
......
Frenquent Databricks-Certified-Data-Engineer-Associate Update: https://www.braindumpquiz.com/Databricks-Certified-Data-Engineer-Associate-exam-material.html
- Latest Databricks Databricks-Certified-Data-Engineer-Associate Practice Test - Proven Way to Crack Exam 💮 Copy URL ▷ www.troytecdumps.com ◁ open and search for ⮆ Databricks-Certified-Data-Engineer-Associate ⮄ to download for free 🕵Databricks-Certified-Data-Engineer-Associate Dump File
- 100% Valid Databricks Databricks-Certified-Data-Engineer-Associate Dumps PDF Updated Questions- Pdfvce 🦗 Search for ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ and easily obtain a free download on 《 www.pdfvce.com 》 🦜Answers Databricks-Certified-Data-Engineer-Associate Free
- Reliable Databricks-Certified-Data-Engineer-Associate Exam Review 🧔 Valid Databricks-Certified-Data-Engineer-Associate Vce 👬 Databricks-Certified-Data-Engineer-Associate Test Book 🏅 Open website ➡ www.testkingpass.com ️⬅️ and search for ➽ Databricks-Certified-Data-Engineer-Associate 🢪 for free download 🎧Valid Databricks-Certified-Data-Engineer-Associate Test Voucher
- Valid Databricks-Certified-Data-Engineer-Associate Study Notes 🍭 Valid Braindumps Databricks-Certified-Data-Engineer-Associate Ppt 😍 Databricks-Certified-Data-Engineer-Associate Exam Engine 🌋 Download ▛ Databricks-Certified-Data-Engineer-Associate ▟ for free by simply entering 【 www.pdfvce.com 】 website 🔥Valid Braindumps Databricks-Certified-Data-Engineer-Associate Ppt
- Databricks-Certified-Data-Engineer-Associate Unlimited Exam Practice 🌏 Books Databricks-Certified-Data-Engineer-Associate PDF 🚀 Databricks-Certified-Data-Engineer-Associate Test Book 🎴 Open ▛ www.practicevce.com ▟ and search for ✔ Databricks-Certified-Data-Engineer-Associate ️✔️ to download exam materials for free 💫Databricks-Certified-Data-Engineer-Associate Exam Engine
- Valid Databricks-Certified-Data-Engineer-Associate Vce ℹ Answers Databricks-Certified-Data-Engineer-Associate Free 👸 Books Databricks-Certified-Data-Engineer-Associate PDF 🔚 Search on ➠ www.pdfvce.com 🠰 for ▛ Databricks-Certified-Data-Engineer-Associate ▟ to obtain exam materials for free download 🥍Valid Braindumps Databricks-Certified-Data-Engineer-Associate Ppt
- Databricks-Certified-Data-Engineer-Associate Pass-Sure Materials - Databricks-Certified-Data-Engineer-Associate Quiz Bootcamp - Databricks-Certified-Data-Engineer-Associate Test Quiz 🧝 Open ➽ www.pdfdumps.com 🢪 and search for ➡ Databricks-Certified-Data-Engineer-Associate ️⬅️ to download exam materials for free ☘Databricks-Certified-Data-Engineer-Associate Braindumps Downloads
- 2026 New Databricks-Certified-Data-Engineer-Associate Test Dumps | Reliable Databricks Frenquent Databricks-Certified-Data-Engineer-Associate Update: Databricks Certified Data Engineer Associate Exam 🔓 Download ➤ Databricks-Certified-Data-Engineer-Associate ⮘ for free by simply searching on ➡ www.pdfvce.com ️⬅️ 🤧Databricks-Certified-Data-Engineer-Associate Authorized Pdf
- 2026 New Databricks-Certified-Data-Engineer-Associate Test Dumps | Reliable Databricks Frenquent Databricks-Certified-Data-Engineer-Associate Update: Databricks Certified Data Engineer Associate Exam 💖 Go to website ➥ www.dumpsquestion.com 🡄 open and search for ▶ Databricks-Certified-Data-Engineer-Associate ◀ to download for free 🏈Test Databricks-Certified-Data-Engineer-Associate Dates
- 2026 New Databricks-Certified-Data-Engineer-Associate Test Dumps | Reliable Databricks Frenquent Databricks-Certified-Data-Engineer-Associate Update: Databricks Certified Data Engineer Associate Exam 🚥 Search for { Databricks-Certified-Data-Engineer-Associate } and download it for free immediately on ➽ www.pdfvce.com 🢪 💼Databricks-Certified-Data-Engineer-Associate Braindumps Downloads
- Reliable Databricks-Certified-Data-Engineer-Associate Exam Review 🦇 Valid Databricks-Certified-Data-Engineer-Associate Vce 🌰 Valid Databricks-Certified-Data-Engineer-Associate Test Voucher 💏 Search for ▷ Databricks-Certified-Data-Engineer-Associate ◁ and download exam materials for free through ▛ www.practicevce.com ▟ 📠Reliable Databricks-Certified-Data-Engineer-Associate Exam Review
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes