Databricks-Certified-Professional-Data-Engineer Test King & Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf

If you are preparing for the exam in order to get the related certification, here comes a piece of good news for you. The Databricks-Certified-Professional-Data-Engineer guide torrent is compiled by our company now has been praised as the secret weapon for candidates who want to pass the Databricks-Certified-Professional-Data-Engineer exam as well as getting the related certification, so you are so lucky to click into this website where you can get your secret weapon. Our reputation for compiling the best Databricks-Certified-Professional-Data-Engineer Training Materials has created a sound base for our future business. We are clearly focused on the international high-end market, thereby committing our resources to the specific product requirements of this key market sector. There are so many advantages of our Databricks-Certified-Professional-Data-Engineer exam torrent, and now, I would like to introduce some details about our Databricks-Certified-Professional-Data-Engineer guide torrent for your reference.
| Section | Weight | Objectives |
|---|
| Topic 1: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
- 1. Jobs and job scheduling
- 2. Task dependencies and orchestration
- 3. Monitoring and alerting
|
| Topic 2: Data Ingestion | 15-20% | - Streaming ingestion
- 1. Kafka integration
- 2. Structured streaming fundamentals
- Batch ingestion methods
- 1. Integration with external systems
- 2. Spark APIs for ingestion
- 3. DBR autoloader
|
| Topic 3: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
- 1. Built-in and user-defined functions
- 2. Spark APIs in Python
- 3. Performance optimization techniques
- Spark DataFrames and Spark SQL
- 1. Window functions
- 2. DataFrame operations and transformations
- 3. Spark SQL queries and functions
|
| Topic 4: Delta Lake | 20-25% | - Delta Lake operations
- 1. Schema evolution and enforcement
- 2. Delta Live Tables
- 3. Merge, update, delete operations
- Delta Lake fundamentals
- 1. Optimize and Z-order
- 2. ACID transactions
- 3. Time travel and data versioning
|
| Topic 5: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
- 1. Differences between data lake, data warehouse, and lakehouse
- 2. Bronze, silver, gold data layers
- 3. Data governance fundamentals
|
>> Databricks-Certified-Professional-Data-Engineer Test King <<
Trustworthy Databricks Databricks-Certified-Professional-Data-Engineer Pdf | Practice Test Databricks-Certified-Professional-Data-Engineer Fee
These Databricks-Certified-Professional-Data-Engineer exam questions braindumps are designed in a way that makes it very simple for the candidates. Each and every Databricks-Certified-Professional-Data-Engineer topic is elaborated with examples clearly. Use ITExamSimulator top rate Databricks Databricks-Certified-Professional-Data-Engineer Exam Testing Tool for making your success possible. Databricks-Certified-Professional-Data-Engineer exam preparation is a hard subject. Plenty of concepts get mixed up together due to which student feel difficult to identify them. There is no similar misconception in Databricks-Certified-Professional-Data-Engineer Dumps because we have made it more interactive for you. The candidates who are less skilled may feel difficult to understand the Databricks-Certified-Professional-Data-Engineer questions can take help from these braindumps. The tough topics of Databricks-Certified-Professional-Data-Engineer certification have been further made easy with examples, simulations and graphs. Candidates can avail the opportunity of demo of free Databricks-Certified-Professional-Data-Engineer dumps.
Databricks Certified Professional Data Engineer Exam Sample Questions (Q213-Q218):
NEW QUESTION # 213
A data engineer wants to automate job monitoring and recovery in Databricks using the Jobs API. They need to list all jobs, identify a failed job, and rerun it.
Which sequence of API actions should the data engineer perform?
- A. Use the jobs/get endpoint to retrieve job details, then use jobs/update to rerun failed jobs.
- B. Use the jobs/list endpoint to list jobs, then use the jobs/create endpoint to create a new job, and run the new job using jobs/run-now.
- C. Use the jobs/cancel endpoint to remove failed jobs, then recreate them with jobs/create and run the new ones.
- D. Use the jobs/list endpoint to list jobs, check job run statuses with jobs/runs/list, and rerun a failed job using jobs/run-now.
Answer: D
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
The Databricks Jobs REST API provides several endpoints for automation. The correct monitoring and rerun flow uses three specific calls:
GET /api/2.1/jobs/list - Lists all available jobs within the workspace.
GET /api/2.1/jobs/runs/list - Returns all runs for a specific job, including their current state (e.g., TERMINATED: FAILED).
POST /api/2.1/jobs/run-now - Immediately triggers a rerun of the specified job.
This sequence aligns with Databricks' prescribed automation model for job observability and recovery. Using jobs/update modifies metadata but does not rerun jobs, and jobs/create is only used for creating new jobs, not rerunning failed ones. Cancelling and recreating jobs introduces unnecessary duplication. Therefore, option A is the correct automated recovery workflow.
NEW QUESTION # 214
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
- A. Add a table comment warning all users that the table schema and field names will be changing on a given date; overwrite the table in place to the specifications of the customer-facing application.
- B. Create a new table with the required schema and new fields and use Delta Lake's deep clone functionality to sync up changes committed to one table to the corresponding table.
- C. Send all users notice that the schema for the table will be changing; include in the communication the logic necessary to revert the new table schema to match historic queries.
- D. Configure a new table with all the requisite fields and new names and use this as the source for the customer-facing application; create a view that maintains the original data schema and table name by aliasing select fields from the new table.
- E. Replace the current table definition with a logical view defined with the query logic currently writing the aggregate table; create a new table to power the customer-facing application.
Answer: D
Explanation:
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed. Verified Reference: [Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CREATE VIEW" section.
NEW QUESTION # 215
The data engineer team has been tasked with configured connections to an external database that does not have a supported native connector with Databricks. The external database already has data security configured by group membership. These groups map directly to user group already created in Databricks that represent various teams within the company.
A new login credential has been created for each group in the external database. The Databricks Utilities Secrets module will be used to make these credentials available to Databricks users.
Assuming that all the credentials are configured correctly on the external database and group membership is properly configured on Databricks, which statement describes how teams can be granted the minimum necessary access to using these credentials?
- A. ''Read'' permissions should be set on a secret key mapped to those credentials that will be used by a given team.
- B. "Read" permissions should be set on a secret scope containing only those credentials that will be used by a given team.
- C. No additional configuration is necessary as long as all users are configured as administrators in the workspace where secrets have been added.
- D. "Manage" permission should be set on a secret scope containing only those credentials that will be used by a given team.
Answer: B
Explanation:
In Databricks, using the Secrets module allows for secure management of sensitive information such as database credentials. Granting 'Read' permissions on a secret key that maps to database credentials for a specific team ensures that only members of that team can access these credentials. This approach aligns with the principle of least privilege, granting users the minimum level of access required to perform their jobs, thus enhancing security.
:
Databricks Documentation on Secret Management: Secrets
NEW QUESTION # 216
The following code has been migrated to a Databricks notebook from a legacy workload:
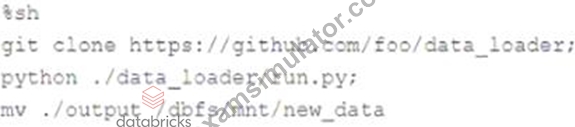
The code executes successfully and provides the logically correct results, however, it takes over 20 minutes to extract and load around 1 GB of data.
Which statement is a possible explanation for this behavior?
- A. %sh executes shell code on the driver node. The code does not take advantage of the worker nodes or Databricks optimized Spark.
- B. Python will always execute slower than Scala on Databricks. The run.py script should be refactored to Scala.
- C. %sh triggers a cluster restart to collect and install Git. Most of the latency is related to cluster startup time.
- D. %sh does not distribute file moving operations; the final line of code should be updated to use %fs instead.
- E. Instead of cloning, the code should use %sh pip install so that the Python code can get executed in parallel across all nodes in a cluster.
Answer: A
Explanation:
https://www.databricks.com/blog/2020/08/31/introducing-the-databricks-web-terminal.html The code is using %sh to execute shell code on the driver node. This means that the code is not taking advantage of the worker nodes or Databricks optimized Spark. This is why the code is taking longer to execute. A better approach would be to use Databricks libraries and APIs to read and write data from Git and DBFS, and to leverage the parallelism and performance of Spark. For example, you can use the Databricks Connect feature to run your Python code on a remote Databricks cluster, or you can use the Spark Git Connector to read data from Git repositories as Spark DataFrames.
NEW QUESTION # 217
A data engineer is designing a Lakeflow Declarative Pipeline to process streaming order data. The pipeline uses Auto Loader to ingest data and must enforce data quality by ensuring customer_id and amount are greater than zero. Invalid records should be dropped.
Which Lakeflow Declarative Pipelines configurations implement this requirement using Python?
- A. @dlt.table
@dlt.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
@dlt.expect_or_drop("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders") - B. @dlt.table
@dlt.expect("valid_customer", "customer_id IS NOT NULL")
@dlt.expect("valid_amount", "amount > 0")
def silver_orders():
return dlt.read_stream("bronze_orders") - C. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect("valid_customer", "customer_id IS NOT NULL")
.expect("valid_amount", "amount > 0")
) - D. @dlt.table
def silver_orders():
return (
dlt.read_stream("bronze_orders")
.expect_or_drop("valid_customer", "customer_id IS NOT NULL")
.expect_or_drop("valid_amount", "amount > 0")
)
Answer: D
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
Lakeflow Declarative Pipelines (LDP), formerly Delta Live Tables (DLT), supports enforcing data quality using expectations. Expectations can either:
Track violations (expect) → records that do not meet conditions are flagged but still included in the pipeline.
Drop violations (expect_or_drop) → records that do not meet conditions are excluded from downstream tables.
Fail pipeline on violations (expect_or_fail) → records that fail conditions stop the pipeline.
In this scenario, the requirement explicitly states that invalid records (where customer_id is null or amount ≤ 0) must be dropped. According to the official documentation, the correct method is .expect_or_drop("expectation_name", "SQL_predicate") applied on the streaming input.
Option A is correct: It uses .expect_or_drop directly within the transformation chain for both rules, ensuring records that fail are removed before writing to the silver table.
Option B incorrectly uses @dlt.expect decorators, which only track violations but do not drop invalid rows.
Option C uses .expect, which also only flags rows, not drop them.
Option D uses @dlt.expect_or_drop decorator syntax, which is not supported in Python API; expect_or_drop must be applied as a method on the DataFrame, not as a decorator.
Therefore, the correct solution is Option A, which ensures compliance by enforcing data quality and dropping invalid rows programmatically during ingestion.
NEW QUESTION # 218
......
Preparing for the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) certification test can be a difficult task for candidates. They often face several challenges during their preparation for the Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) exam, including fear, lack of updated Databricks-Certified-Professional-Data-Engineer Exam Dumps, and time constraints. Fortunately, there is a solution to these challenges. ITExamSimulator is a reliable website that provides genuine and updated Databricks-Certified-Professional-Data-Engineer Practice Test.
Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf: https://www.itexamsimulator.com/Databricks-Certified-Professional-Data-Engineer-brain-dumps.html
- Top Databricks-Certified-Professional-Data-Engineer Test King | Pass-Sure Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf: Databricks Certified Professional Data Engineer Exam 🔳 Open ☀ www.pdfdumps.com ️☀️ and search for { Databricks-Certified-Professional-Data-Engineer } to download exam materials for free 🧸Valid Databricks-Certified-Professional-Data-Engineer Exam Test
- Valid Braindumps Databricks-Certified-Professional-Data-Engineer Files 🥥 Exam Dumps Databricks-Certified-Professional-Data-Engineer Zip 👍 Databricks-Certified-Professional-Data-Engineer Reliable Braindumps Pdf 🥽 Search for ⇛ Databricks-Certified-Professional-Data-Engineer ⇚ and download exam materials for free through ➽ www.pdfvce.com 🢪 🧦Valid Braindumps Databricks-Certified-Professional-Data-Engineer Files
- Databricks Databricks-Certified-Professional-Data-Engineer ExamQuestions - 100% Success 🥤 Search on 《 www.vce4dumps.com 》 for ▷ Databricks-Certified-Professional-Data-Engineer ◁ to obtain exam materials for free download 👦Valid Braindumps Databricks-Certified-Professional-Data-Engineer Files
- Updated 100% Free Databricks-Certified-Professional-Data-Engineer – 100% Free Test King | Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf 🧀 Simply search for ➤ Databricks-Certified-Professional-Data-Engineer ⮘ for free download on 「 www.pdfvce.com 」 🦺Pdf Databricks-Certified-Professional-Data-Engineer Torrent
- 100% Pass 2026 Databricks Databricks-Certified-Professional-Data-Engineer: Databricks Certified Professional Data Engineer Exam Pass-Sure Test King 🧺 Open 【 www.examcollectionpass.com 】 and search for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to download exam materials for free 😨Valid Braindumps Databricks-Certified-Professional-Data-Engineer Files
- Top Databricks-Certified-Professional-Data-Engineer Test King | Pass-Sure Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf: Databricks Certified Professional Data Engineer Exam 🕶 Immediately open ✔ www.pdfvce.com ️✔️ and search for { Databricks-Certified-Professional-Data-Engineer } to obtain a free download 🪕Latest Databricks-Certified-Professional-Data-Engineer Training
- Free PDF Databricks - Databricks-Certified-Professional-Data-Engineer - Newest Databricks Certified Professional Data Engineer Exam Test King 🎴 Search on ☀ www.troytecdumps.com ️☀️ for ▛ Databricks-Certified-Professional-Data-Engineer ▟ to obtain exam materials for free download 😞Databricks-Certified-Professional-Data-Engineer Test Practice
- Examcollection Databricks-Certified-Professional-Data-Engineer Free Dumps 🖼 Databricks-Certified-Professional-Data-Engineer Authentic Exam Questions ✒ Valid Databricks-Certified-Professional-Data-Engineer Exam Test ✔ The page for free download of 【 Databricks-Certified-Professional-Data-Engineer 】 on ▛ www.pdfvce.com ▟ will open immediately ☎Exam Databricks-Certified-Professional-Data-Engineer Assessment
- Top Databricks-Certified-Professional-Data-Engineer Test King | Pass-Sure Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf: Databricks Certified Professional Data Engineer Exam 👺 Open website ☀ www.vce4dumps.com ️☀️ and search for ⮆ Databricks-Certified-Professional-Data-Engineer ⮄ for free download 😐Pdf Databricks-Certified-Professional-Data-Engineer Torrent
- Databricks Databricks-Certified-Professional-Data-Engineer Dumps | Questions (2026) 💍 Download ▶ Databricks-Certified-Professional-Data-Engineer ◀ for free by simply entering ➡ www.pdfvce.com ️⬅️ website 💮Databricks-Certified-Professional-Data-Engineer Exam Outline
- Top Databricks-Certified-Professional-Data-Engineer Test King | Pass-Sure Trustworthy Databricks-Certified-Professional-Data-Engineer Pdf: Databricks Certified Professional Data Engineer Exam 🎆 Copy URL { www.prep4sures.top } open and search for ➥ Databricks-Certified-Professional-Data-Engineer 🡄 to download for free 🎳Databricks-Certified-Professional-Data-Engineer Exam Outline
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes