As we all know, the influence of AI-200 exam guides even have been extended to all professions and trades in recent years. Passing the AI-200 exam is not only for obtaining a paper certification, but also for a proof of your ability. Most people regard Microsoft certification as a threshold in this industry, therefore, for your convenience, we are fully equipped with a professional team with specialized experts to study and design the most applicable AI-200 Exam prepare. We have organized a team to research and study question patterns pointing towards various learners.
| Section | Objectives |
|---|---|
| Implement and monitor AI workloads | - Deploy AI models and services - Monitor performance and troubleshoot issues |
| Plan and manage Azure AI solutions | - Plan security and compliance requirements - Select appropriate Azure AI services - Monitor and optimize AI solutions |
| Implement Azure AI solutions | - Implement generative AI solutions using Azure OpenAI - Implement computer vision solutions - Implement natural language processing solutions - Implement knowledge mining with Azure AI Search |
>> Free AI-200 Exam Questions <<
We are living in a good society; everything is changing so fast with the development of technology. So an ambitious person must be able to realize his dreams if he is willing to make efforts. Winners always know the harder they work the luckier they are. Our AI-200 practice materials are prepared for the diligent people craving for success. Almost all people pursuit a promising career, the reality is not everyone acts quickly and persistently. That is the reason why success belongs to few people.
NEW QUESTION # 73
Drag and Drop Question
A semantic search application queries Azure Database for PostgreSQL and stores document embeddings and metadata in a table with the following columns:
- embedding (pgvector)
- department
- created_at
The application must return the top five most similar documents for a given query embedding only from the finance department.
You need to implement semantic retrieval with metadata filtering.
Which query components should you select? To answer, move the appropriate query components to the correct requirements. You may use each query component once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.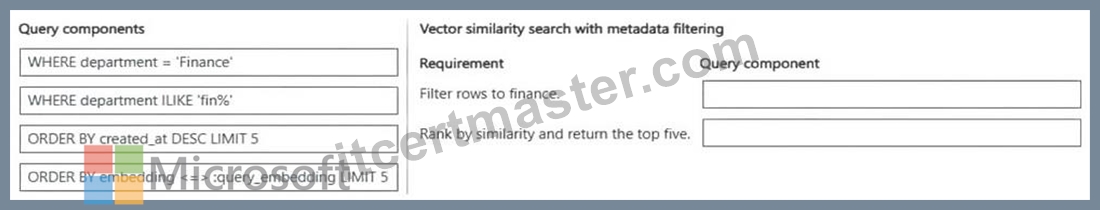
Answer:
Explanation: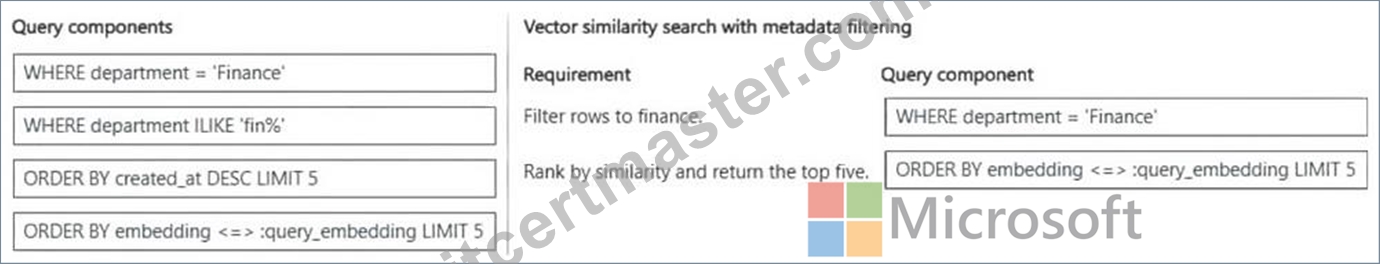
Explanation:
Box 1: WHERE department = 'Finance'
Box 2: ORDER BY embedding <=> :query_vector LIMIT 5
To rank and return the top five most similar documents by similarity in Microsoft Learn, use the ORDER BY embedding <=> [query_vector] expression combined with LIMIT 5, where <=> computes the cosine distance.
Reference:
https://learn.microsoft.com/en-us/azure/postgresql/extensions/how-to-use-pgvector
NEW QUESTION # 74
You deploy a production Azure Function app that connects to an Azure SQL Database.
The solution must provide the following functionality:
- Prevent secrets from being exposed in source control.
- Support secret rotation without redeploying the function app.
- Avoid downtime during credential updates.
You need to configure secure and maintainable secret management.
What should you configure?
Answer: D
Explanation:
To meet all requirements, you should configure Application settings with Key Vault references.
Source Control Protection: The Function App source code and configuration files only store a reference URI (e.g., @Microsoft.KeyVault(SecretUri=...)) rather than the actual connection string, keeping secrets entirely out of source control.
Seamless Secret Rotation: Azure Key Vault handles secret rotation natively. When a database password changes, you simply update the secret in Key Vault.
Zero Downtime: By using versionless Key Vault references (omitting the specific version GUID from the URI), the Azure Function App will automatically fetch the latest secret version within 24 hours without requiring a code redeployment or app restart.
References:
https://oneuptime.com/blog/post/2026-02-16-how-to-configure-managed-identity-for-azure-app-service-to-access-key-vault-secrets-without-credentials/view
NEW QUESTION # 75
You need to optimize secure database connectivity from the containerized Recommendation API.
How should you configure the application?
Answer:
Explanation:
Explanation:
* Comply with the authentication policy for database access: Use managed identity authentication.
* Support high-concurrency requests with minimal latency: Use a connection pooling library.
* Protect database stability during traffic spikes: Configure maximum pool size.
The Recommendation API should use managed identity authentication because Fabrikam explicitly requires service-to-database authentication without long-lived credentials. Azure Container Apps managed identities allow applications to obtain Microsoft Entra tokens at runtime and access supported Azure resources without storing usernames, passwords, or connection secrets in application configuration.
For high-concurrency PostgreSQL access, implement a connection pooling library . Azure Database for PostgreSQL documentation recommends connection pooling because repeatedly opening new database connections creates backend processes and consumes CPU and memory. Reusing existing connections reduces connection-establishment overhead and improves latency and throughput. Azure also provides PgBouncer as a built-in pooling option for Flexible Server.
To protect PostgreSQL during sudden traffic spikes, configure a maximum pool size . An unlimited pool can allow application demand to create excessive concurrent connections, which can exhaust database memory and increase contention. Microsoft warns that increasing connection counts can cause significant performance degradation and recommends conservative connection limits combined with pooling.
Therefore, the optimal configuration combines managed identity + connection pooling + bounded pool size
.
Study Guide references: Azure Container Apps managed identities; Azure Database for PostgreSQL connection management; PgBouncer; connection-pool sizing and resource protection.
NEW QUESTION # 76
You maintain multiple versions of a container image in Azure Container Registry.
The production deployment must always run the exact same image build even if tags are changed later.
You need to ensure predictable and immutable image selection during deployment.
What should you do?
Answer: A
Explanation:
Use the image ' s SHA-256 manifest digest when defining the production deployment. Azure Container Registry assigns every pushed image manifest a unique digest, and Microsoft explicitly states that pulling an image by digest guarantees the image version being retrieved , even if an identically named tag is later pushed to a different image. A digest reference has the form myregistry.azurecr.io/repository@sha256: < digest > .
Tags such as production or latest are mutable references . By default, a user or pipeline with sufficient permissions can push a different image under the same tag. Microsoft therefore warns against relying on reusable stable tags for production deployments when exact image reproducibility is required.
A scheduled rebuild also creates a new image artifact and therefore cannot guarantee that production executes the original build. In contrast, the manifest digest is content-addressed and resolves to the precise image manifest selected at deployment time.
Thus, for deterministic and immutable production image selection, reference the container image by its SHA digest rather than by a mutable tag .
Study Guide references: Azure Container Registry # image manifests and digests; image addressing; tagging
/versioning recommendations; immutable deployment references.
NEW QUESTION # 77
You are implementing a Retrieval-Augmented Generation (RAG) system by using the native vector search capabilities of Azure Cosmos DB for NoSQL API.
You have a container named Documents that stores technical articles. Each article includes a property named embedding.
You must ensure that the system can perform efficient similarity searches between user queries and the stored articles.
You need to configure the database resources to support semantic retrieval.
Which configurations should you use? To answer, move the appropriate configurations to the correct requirements. You may use each configuration once, more than once, or not at all. You may need to move the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* Facilitate mathematical distance calculations between data points: Configure a vector index.
* Define the document schema for high-dimensional data: Store data as a numeric array.
Azure Cosmos DB for NoSQL supports native vector search by storing embeddings directly in JSON documents and defining a vector embedding policy plus a vector index on the embedding path. Microsoft documents that vector search compares a query vector with stored vectors by calculating similarity or distance through the VectorDistance() system function. A vector index materially improves this process by reducing search latency, increasing throughput, and lowering RU consumption compared with an unindexed vector scan.
The embedding property itself must be stored as an array of numeric values . Microsoft examples show embedding properties such as " contentVector " : [2, -1, 4, ...] and define the associated vector policy with attributes including path, data type, dimensions, and distance function. This representation is required because embeddings are high-dimensional numerical vectors generated by an embedding model.
A composite index optimizes queries involving multiple scalar properties but does not provide vector- distance indexing. A Base64-encoded string cannot be used directly for native vector similarity calculations because Cosmos DB expects the vector field to contain numeric values matching the configured dimensionality.
Study Guide references: Azure Cosmos DB for NoSQL # vector embedding policies; vector indexes; VectorDistance(); numeric embedding arrays; native vector search.
NEW QUESTION # 78
......
Our AI-200 exambraindumps are known for the quality as well as the high pass rate. The pass rate is above98%. If you buy the AI-200 learning materials, in our website, we will guarantee the safety of your electric instrument as well as a sound shopping environment, you can set it as a safety web, since our professionals will check it regularly for the safety. If you have the desire, contact us.
AI-200 Latest Test Bootcamp: https://www.itcertmaster.com/AI-200.html