BONUS!!! Download part of RealExamFree AI-200 dumps for free: https://drive.google.com/open?id=13IoBbtlLTJ_Aa68QnwwBaJQse8OAZm4a
Just only dozens of money on Microsoft AI-200 latest study guide will assist you pass exam and 24-hours worm aid service. These Microsoft AI-200 test questions will help you secure the Microsoft AI-200 credential on the first attempt. We are aware that students face undue pressure during the Microsoft AI-200 certification exam preparation.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Integrate backend services and build event-driven architectures | 25% | - Build serverless APIs and workflows
|
| Topic 2: Develop AI solutions using Azure data services | 30% | - Design and optimize data access and retrieval
|
| Topic 3: Develop containerized AI solutions on Azure | 25% | - Implement container hosting environments
|
| Topic 4: Secure, monitor, and optimize AI solutions | 20% | - Implement observability and reliability
|
>> Authorized Microsoft AI-200 Certification <<
Our AI-200 exam cram is famous for instant access to download, and you can receive the downloading link and password within ten minutes, and if you don’t receive, you can contact us, and we will give you reply as quickly as possible. In addition, AI-200 exam materials are high quality, and we can ensure you that you can pass the exam just one time. We have free demo for you to have a try before buying AI-200 Exam Materials, so that you can have a deeper understanding of what you are going to buy. Free update for one year for AI-200 training materials is also available.
NEW QUESTION # 57
You are building a semantic search feature for a chatbot. You store document embeddings in Redis.
You review the following Python code that connects to Redis and stores an embedding value:
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Verified Answer: Yes; No; Yes.
Detailed Explanation: `HSET` stores the binary embedding as a field in the Redis hash keyed by `doc:1`, so the first statement is true. The code does not create a RediSearch/Redis Query Engine vector index or define a vector field schema; merely storing bytes does not enable similarity search, so the second statement is false.
`EXPIRE doc:1 600` sets a 600-second lifetime, which is ten minutes, making the third statement true.
Study Guide Alignment: AI data-management workloads: Cosmos DB, PostgreSQL, caching, vector storage, vector retrieval, consistency, and connection optimization.
Official Microsoft Learn References: AI-200 Study Guide | Vector search in Azure Managed Redis
NEW QUESTION # 58
Case Study 1 - Fabrikam Inc.
Background
Fabrikam Inc. is a global retail analytics company that provides AI-driven demand forecasting and product recommendation services to online retailers. The company is modernizing its solution to run entirely on Microsoft Azure.
The platform ingests transaction data, generates embeddings for semantic retrieval, performs vector similarity search, and returns product recommendations through containerized microservices. Developers use Python and Azure SDKs. Operations teams manage container orchestration, scaling, monitoring, and security.
The solution must meet strict performance, scalability, and security requirements.
Current environment
Application architecture
The Recommendation engine is a customer-facing HTTP API running as a containerized Python application. The engine is deployed to Azure Container Apps (ACA).
Embeddings are stored in Azure Database for PostgreSQL by using pgvector.
Semantic retrieval uses metadata filtering combined with vector similarity search.
Azure Managed Redis is used as a caching layer.
Front-end and API workloads are deployed to Azure Container Apps (ACA).
Batch model retraining workloads run in Azure Kubernetes Service (AKS).
Container and CI/CD
Container images are stored in Azure Container Registry (ACR).
CI/CD uses ACR Tasks to build images on commit.
ACA environments support revision management.
AKS workloads are deployed by using Kubernetes manifest files stored in Git.
Monitoring
Logs are collected in Azure Monitor.
Teams inspect container logs and Kubernetes events when troubleshooting.
Developers write KQL queries to analyze latency spikes.
Business requirements
Customer experience: Maintain a seamless, low-latency recommendation experience for end- users, even during unpredictable seasonal traffic spikes.
Operational cost efficiency: Minimize compute expenditures by deallocating resources during periods of inactivity and by preventing runaway scaling costs.
Data integrity and freshness: Ensure that product recommendations always reflect the most current catalog metadata and pricing to prevent customer dissatisfaction.
Security and compliance: Adhere to a Zero Trust security model by eliminating long-lived credentials and centralizing the management of all sensitive secrets.
Global scalability: Support the rapid ingestion of millions of new product embeddings daily without degrading query performance for existing retailers.
Technical requirements
Performance: Semantic search latency must remain under 200 milliseconds at peak load.
Database optimization: Use pgvector for embeddings and implement metadata filtering to reduce compute overhead. Configure compute and memory appropriately for vector workloads to ensure high-dimensional index residency in RAM and efficient mathematical throughput. Vector similarity calculations must be performed only against products that satisfy mandatory metadata constraints.
Database performance: Database connections must support high concurrency with minimal latency through the implementation of connection optimization.
Data load strategy: To ensure maximum ingestion throughput, secondary indexes must be applied only after bulk loading of embeddings is complete.
Caching: Redis cache entries must expire automatically after 10 minutes. Implement a reactive mechanism to invalidate cache entries upon metadata updates.
Identity: Use managed identities for all service-to-service and service-to-database authentication.
Plain-text credentials in configuration files are strictly prohibited.
Secret management: All secrets must be stored centrally. Secrets must be rotated automatically by using a centralized lifecycle policy.
Scaling: Use Kubernetes event-driven autoscaling (KEDA) for event-driven scaling. The Recommendation API must scale based on HTTP traffic, while batch jobs must scale based on queue length and support scale-to-zero.
CI/CD: All images must be stored in Azure Container Registry. Use ACR Tasks to automate image builds triggered by source code commits.
Monitoring: Use KQL to analyze performance telemetry and troubleshoot microservice connectivity failures. Inspect logs and events when troubleshooting AKS and ACA.
You need to implement a secret management solution for the Recommendation API to satisfy the security and identity requirements of Fabrikam Inc.
Which service should you use?
Answer: B
Explanation:
Scenario, technical requirements: Secret management: All secrets must be stored centrally.
Secrets must be rotated automatically by using a centralized lifecycle policy.
Azure Key Vault is the correct and recommended service to store secrets in this scenario. It fulfills all the requirements for centralized management, Python SDK integration, and automated rotation.
Reference:
https://www.cloudthat.com/resources/blog/securing-sensitive-information-with-azure-key-vault
NEW QUESTION # 59
You are designing an Azure Database for PostgreSQL table for semantic search. Queries frequently filter on the created_at column.
The schema must support vector similarity search and reliable date filtering.
You need to ensure that the table meets the requirements.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: B,D
NEW QUESTION # 60
You plan to create a Docker image that runs an ASP.NET Core application named ContosoApp. You have a setup script named setupScript.psl and a series of application files including ContoscApp.dll.
You need to create a Dockerfile document that meets the following requirements:
* Call SQiupScript.psI when the container is built.
* Run CantosoApp.dill when the container starts.
The Dockerfile document must be created in the same folder where ContosoApp.dll and setupScnpt.ps! are stored.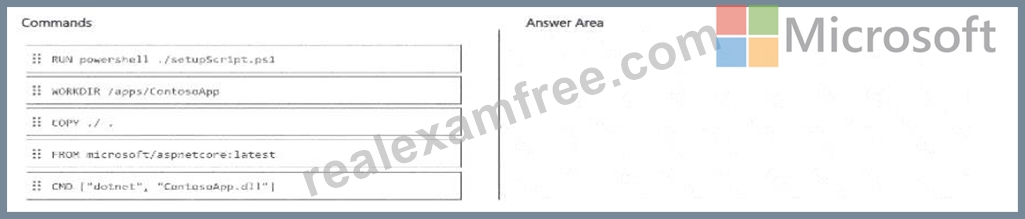
Answer:
Explanation: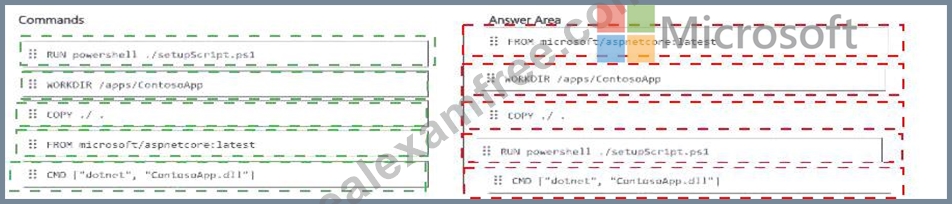
Explanation: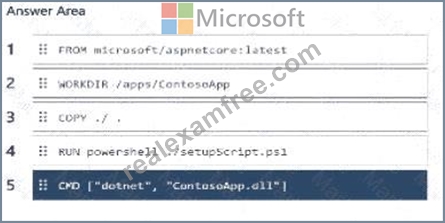
NEW QUESTION # 61
Hotspot Question
A company uses Azure Monitor Application Insights to monitor application behavior, including incoming requests and dependencies.
You must identify failed requests from the last hour. You must also calculate the average duration of failed request dependency calls, grouped by operation name.
You need to analyze telemetry in Application Insights.
Which operators should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Box 1: where
Filter telemetry rows
The where operator filters a table to rows that satisfy a specific predicate. Both box 1 and box 2 require filtering telemetry data to the last hour (timestamp > ago(1h)).
Box 2: where
In the Kusto Query Language (KQL), the where operator filters a table to rows that satisfy a specific predicate or condition. Inside the inner subquery, you need to filter the dependencies telemetry table to only include records from the last hour (timestamp > ago(1)) Box 3: summarize Aggregate calculated data The summarize operator produces a table that aggregates the content of the input table. It is used here with the avg() aggregation function to calculate the average duration grouped by the operation_Name.
Reference:
https://tryhackme.com/room/kqlkustobasicqueries
NEW QUESTION # 62
......
We have three versions of Microsoft AI-200 learning materials available, including PDF, Software and APP online. The most popular one is PDF version of Microsoft AI-200 study guide can be printed into papers so that you are able to write some notes or highlight the emphasis. On the other hand, Software version of our Microsoft AI-200 Practice Questions is also welcomed by customers, especially for windows users.
AI-200 Lead2pass: https://www.realexamfree.com/AI-200-real-exam-dumps.html
DOWNLOAD the newest RealExamFree AI-200 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=13IoBbtlLTJ_Aa68QnwwBaJQse8OAZm4a