Databricks Databricks-Machine-Learning-Professional Detailed Answers: Databricks Certified Machine Learning Professional - Braindumpsqa Free PDF
P.S. Free & New Databricks-Machine-Learning-Professional dumps are available on Google Drive shared by Braindumpsqa: https://drive.google.com/open?id=1BdWfZWO9f0jrl4G-JG2f3q4F08zRoPyH
If you want to pass the exam quickly, Databricks-Machine-Learning-Professional prep guide is your best choice. We know that many users do not have a large amount of time to learn. In response to this, we have scientifically set the content of the data. You can use your piecemeal time to learn, and every minute will have a good effect. In order for you to really absorb the content of Databricks-Machine-Learning-Professional Exam Questions, we will tailor a learning plan for you. This study plan may also have a great impact on your work and life. As long as you carefully study the Databricks-Machine-Learning-Professional study guide for twenty to thirty hours, you can go to the Databricks-Machine-Learning-Professional exam.
| Section | Weight | Objectives |
|---|
| Model Development | 47% | - Feature Store
- 1. Feature Store concepts and usage
- 2. Automated feature pipelines
- MLflow Advanced Features
- 1. Model registry and versioning
- 2. Experiment tracking and model management
- SparkML and Scaling
- 1. Ray/Optuna distributed tuning
- 2. Distributed training and hyperparameter tuning
- 3. Building scalable ML pipelines with SparkML
|
| Model Lifecycle Management (MLOps) | 43% | - Automated Workflows
- 1. Automated retraining workflows
- 2. CI/CD pipelines for ML
- Testing Strategies
- 1. Model testing and validation
- 2. Data quality testing
- Monitoring
- 1. Lakehouse Monitoring for drift detection
- 2. Model performance monitoring
- Environment Management
- 1. Environment configuration and reproducibility
- 2. Databricks Asset Bundles (DABs)
|
| Model Deployment | 10% | - Model Serving
- 1. Databricks Model Serving
- 2. Custom serving solutions
- Deployment Strategies
- 1. Real-time Deployment
- 2. Batch Deployment
- 3. Streaming Deployment
|
>> Databricks-Machine-Learning-Professional Detailed Answers <<
Accurate Databricks - Databricks-Machine-Learning-Professional Detailed Answers
Learn for your Databricks Databricks-Machine-Learning-Professional certification with confidence by utilizing the Braindumpsqa Databricks-Machine-Learning-Professional study guide, which is always forward-thinking, convenient, current, and dependable. If you are still unsure whether to pursue Braindumpsqa Databricks-Machine-Learning-Professional Exam Questions for Databricks Certified Machine Learning Professional certification exam preparation, you are losing the game at the first stage in a fiercely competitive marketplace. Braindumpsqa Databricks-Machine-Learning-Professional questions are the best option.
Databricks Certified Machine Learning Professional Sample Questions (Q53-Q58):
NEW QUESTION # 53
A Machine Learning Engineer is building a fraud detection model that needs to use both pre- computed features from a feature table and real-time calculated features based on user location data sent with each inference request. The engineer has created a Python UDF called calculate_distance in Unity Catalog at main.fraud_detection.calculate_distance that computes the distance between a transaction location and the user's current location. The feature table main.fraud_detection.user_features contains historical user spending patterns with primary key user_id.
The engineer has written the following code to implement this scenario:
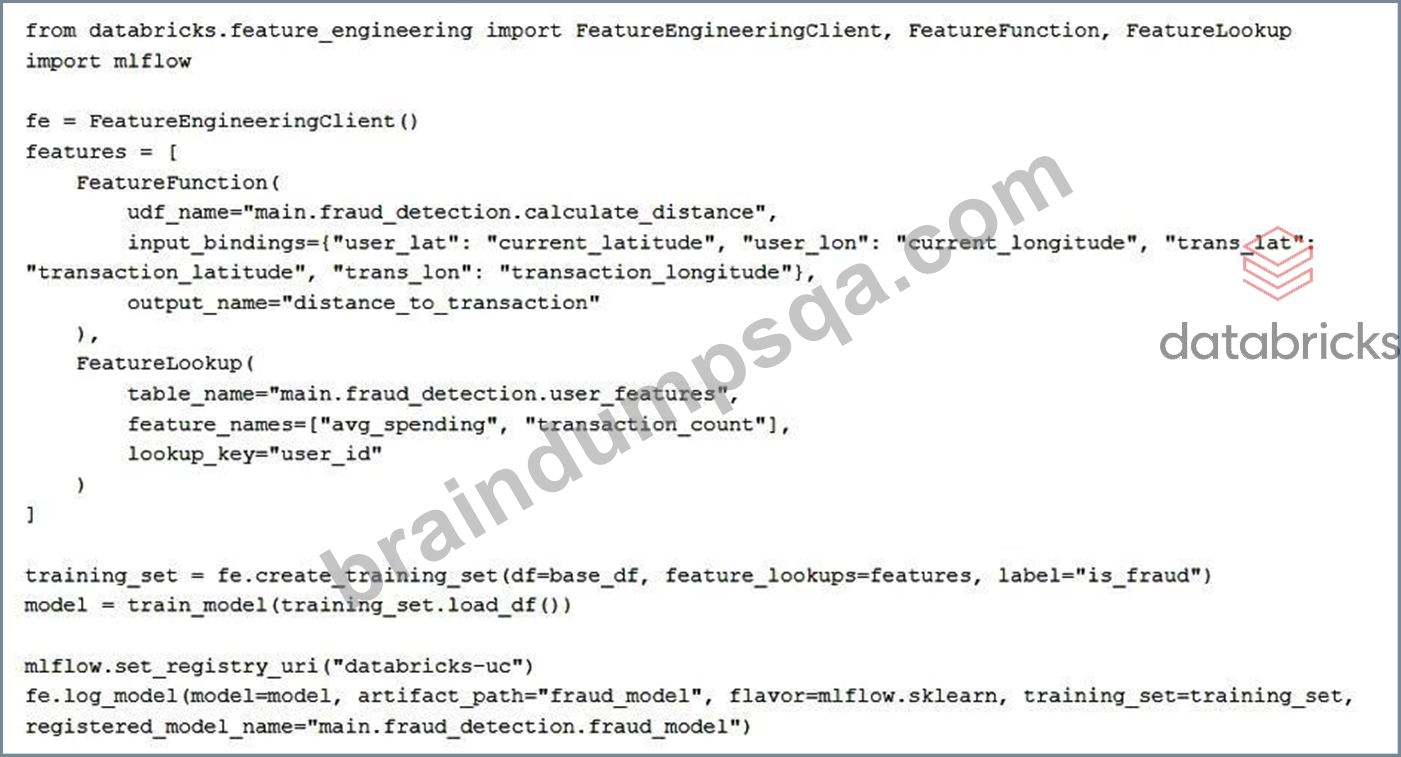
Which benefit of this implementation approach makes it suited to the real-time fraud detection use case?
- A. The FeatureFunction caches computed distance values in the online store to improve inference latency for location pairs.
- B. The FeatureLookup function avoids the need for joining the full table main.fraud_detection.user_features with training_set increasing efficiency.
- C. The model automatically performs feature lookup and computation during inference without additional serving code.
- D. The Unity Catalog registry automatically creates REST API endpoints for UDF functions used in feature computation.
Answer: C
Explanation:
By defining both FeatureLookup and FeatureFunction objects in the training set and logging the model with the FeatureEngineeringClient, the feature logic is packaged with the model. During inference, Databricks automatically performs feature lookups from the feature table and computes the on-demand distance feature using request-time inputs, without requiring any additional custom serving or feature-joining code. This makes the approach well suited for real-time fraud detection.
NEW QUESTION # 54
In order to connect an MLflow Model Registry Webhook to a Databricks Job, the Job ID must be provided to the code block used to create the webhook. Which approach can be used to obtain a Databricks Job ID?
- A. The Job ID field in the Jobs page in the UI
- B. The Job ID field in the Job details section of the specific Job page in the UI
- C. The Job ID field returned in a query using the Jobs API
- D. All of these approaches
Answer: D
Explanation:
A Databricks Job ID can be obtained in multiple ways - it is displayed directly in the Jobs page, in the Job details section of a specific Job, and can also be retrieved programmatically through the Databricks Jobs API. Any of these methods can be used to supply the Job ID when configuring an MLflow Model Registry Webhook.
NEW QUESTION # 55
What is commonly monitored in deployed ML models?
- A. Code style
- B. Model drift and prediction quality
- C. GPU usage only
- D. Notebook formatting
Answer: B
Explanation:
Production ML systems monitor:
data drift
model drift
prediction accuracy.
NEW QUESTION # 56
A machine learning engineer has developed a random forest model using scikit-learn and registered the model using MLflow. They now want to deploy that model in parallel. Which of the following operations can they use to create a function they can use to deploy the registered scikit- learn model in parallel?
- A. mlflow.pyfunk.spark.udf
- B. mlflow.spark.pandas_udf
- C. It is not possible to deploy a scikit-learn model in parallel.
- D. mlflow.sklearn.spark.udf
Answer: D
Explanation:
The correct operation is mlflow.sklearn.spark_udf, which creates a Spark UDF from a registered scikit-learn model. This allows the model to be applied in parallel across a Spark DataFrame, enabling scalable batch inference using Spark.
NEW QUESTION # 57
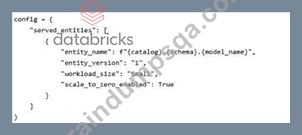
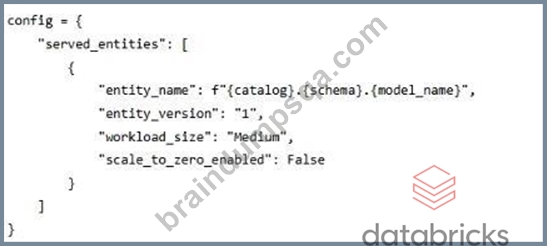
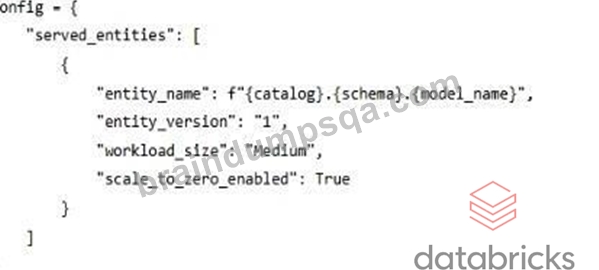
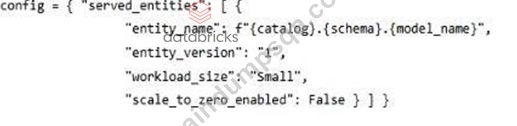
A Machine Learning Engineer needs to develop a custom anomaly detection model that monitors the internal IT infrastructure of their company. The model takes in compute metrics, logs, and user data and generates a binary prediction. The engineer plans to deploy it as a Databricks Model Serving endpoint. In production there will only be one client calling the endpoint once every
15 seconds. Leadership sees the model as an important part of their operational improvement strategy so maintaining consistent, stable, low latency inference is a requirement while minimizing infrastructure costs. The engineer plans to deploy the endpoint via the MLflow Deployment SDK.
Which endpoint config for the MLflow Deployment SDK should the engineer select?
Answer: D
Explanation:
With a single client making requests every 15 seconds, the traffic is steady and predictable, and low-latency inference is a strict requirement. Disabling scale-to-zero avoids cold start latency, ensuring consistent response times. Selecting a Small workload size minimizes infrastructure costs while still providing sufficient resources for a lightweight binary classification model, making this configuration the best balance between performance, stability, and cost.
NEW QUESTION # 58
......
Perhaps you are in a bad condition and need help to solve all the troubles. Don’t worry, once you realize economic freedom, nothing can disturb your life. Our Databricks Certified Machine Learning Professional study materials can help you out. Learning is the best way to make money. So you need to learn our Databricks-Machine-Learning-Professional study materials carefully after you have paid for them. As long as you are determined to change your current condition, nothing can stop you. Once you get the Databricks-Machine-Learning-Professional certificate, all things around you will turn positive changes. Never give up yourself. You have the right to own a bright future.
Databricks-Machine-Learning-Professional Test Study Guide: https://www.braindumpsqa.com/Databricks-Machine-Learning-Professional_braindumps.html
- Free PDF Quiz 2026 Latest Databricks Databricks-Machine-Learning-Professional Detailed Answers ♣ Copy URL 「 www.exam4labs.com 」 open and search for ✔ Databricks-Machine-Learning-Professional ️✔️ to download for free 🚥New Databricks-Machine-Learning-Professional Exam Simulator
- Pass Guaranteed 2026 Databricks Databricks-Machine-Learning-Professional –Efficient Detailed Answers 🙅 Easily obtain free download of ⮆ Databricks-Machine-Learning-Professional ⮄ by searching on ⏩ www.pdfvce.com ⏪ 🔼New Databricks-Machine-Learning-Professional Exam Format
- Pass Guaranteed 2026 Databricks Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional First-grade Detailed Answers 😛 Enter ➡ www.dumpsmaterials.com ️⬅️ and search for ➥ Databricks-Machine-Learning-Professional 🡄 to download for free 🔘Test Databricks-Machine-Learning-Professional Score Report
- 2026 Databricks-Machine-Learning-Professional Detailed Answers Pass Certify | Valid Databricks-Machine-Learning-Professional Test Study Guide: Databricks Certified Machine Learning Professional 💲 Search for ▶ Databricks-Machine-Learning-Professional ◀ and download it for free on ⮆ www.pdfvce.com ⮄ website 🚶Databricks-Machine-Learning-Professional Exam Lab Questions
- Hot Databricks-Machine-Learning-Professional Detailed Answers 100% Pass | Latest Databricks-Machine-Learning-Professional: Databricks Certified Machine Learning Professional 100% Pass ⌨ Search on 《 www.practicevce.com 》 for ⏩ Databricks-Machine-Learning-Professional ⏪ to obtain exam materials for free download 🔉Databricks-Machine-Learning-Professional Free Dump Download
- Databricks-Machine-Learning-Professional Reliable Test Materials 🏏 Databricks-Machine-Learning-Professional Valid Exam Sample 🚇 Databricks-Machine-Learning-Professional Actual Dumps 💻 Go to website ➤ www.pdfvce.com ⮘ open and search for ▛ Databricks-Machine-Learning-Professional ▟ to download for free 🖌Databricks-Machine-Learning-Professional Actual Dumps
- 100% Pass Databricks-Machine-Learning-Professional Databricks Certified Machine Learning Professional Marvelous Detailed Answers 💮 Search for { Databricks-Machine-Learning-Professional } and obtain a free download on ▶ www.prep4sures.top ◀ 🕋Latest Databricks-Machine-Learning-Professional Test Cram
- Databricks-Machine-Learning-Professional Reliable Test Materials ❕ Reliable Databricks-Machine-Learning-Professional Test Forum 👳 Reliable Databricks-Machine-Learning-Professional Test Forum 🔺 Download ⏩ Databricks-Machine-Learning-Professional ⏪ for free by simply entering 《 www.pdfvce.com 》 website 🗯Databricks-Machine-Learning-Professional Valid Exam Sample
- Practice Databricks-Machine-Learning-Professional Mock 🪔 Latest Databricks-Machine-Learning-Professional Cram Materials 🕙 Databricks-Machine-Learning-Professional Exam Lab Questions 💙 Search for ⮆ Databricks-Machine-Learning-Professional ⮄ and download exam materials for free through ➥ www.pdfdumps.com 🡄 🚑Latest Databricks-Machine-Learning-Professional Cram Materials
- Newest Databricks-Machine-Learning-Professional Detailed Answers - Pass Databricks-Machine-Learning-Professional Exam Easily 🔂 Easily obtain ⇛ Databricks-Machine-Learning-Professional ⇚ for free download through ⏩ www.pdfvce.com ⏪ ↗Databricks-Machine-Learning-Professional Actual Dumps
- Pass Guaranteed 2026 Databricks Databricks-Machine-Learning-Professional –Efficient Detailed Answers 🙂 Go to website ➥ www.practicevce.com 🡄 open and search for { Databricks-Machine-Learning-Professional } to download for free 🎃Practice Databricks-Machine-Learning-Professional Mock
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.wonderlink.de, tooter.in, Disposable vapes
BONUS!!! Download part of Braindumpsqa Databricks-Machine-Learning-Professional dumps for free: https://drive.google.com/open?id=1BdWfZWO9f0jrl4G-JG2f3q4F08zRoPyH