Although it is not an easy thing for somebody to pass the AI-500 exam, ActualVCE can help aggressive people to achieve their goals. More qualified AI-500 certification for our future employment has the effect to be reckoned with, only to have enough qualification certifications to prove their ability, can we win over rivals in the social competition. This is the reason why we need to recognize the importance of getting our AI-500 Quiz torrent. And with our AI-500 exam questions, you dream will be easy to come true.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Evaluate, optimize, and monitor multi-agent solutions | 20–25% | - Assess performance and reliability
|
| Topic 2: Architect multi-agent solutions | 15–20% | - Design logical architecture for multi-agent systems
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20–25% | - Apply security and compliance
|
| Topic 4: Develop multi-agent solutions in Azure | 30–35% | - Manage state and memory
|
>> Valid AI-500 Exam Syllabus <<
Our professions endeavor to provide you with the newest information on our AI-500 exam questions with dedication on a daily basis to ensure that you can catch up with the slight changes of the AI-500 exam. Therefore, our customers are able to enjoy the high-productive and high-efficient users’ experience. In this circumstance, as long as your propose and demand on AI-500 Guide quiz are rational, we have the duty to guarantee that you can enjoy the one-year updating system for free.
NEW QUESTION # 10
You need to implement a logging solution for claim Approval.
What should you use for each process? To answer, drag the appropriate resources to the correct processes.
Each resource may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: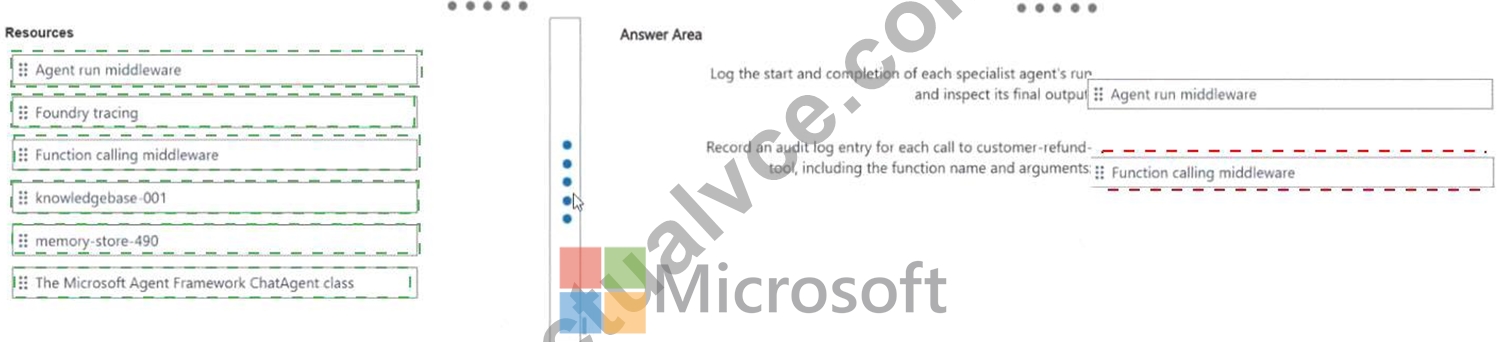
Explanation:
Log the start/completion of each specialist run and inspect the final output with Agent run middleware; record each customer-refund-tool call, including function name and arguments, with Function calling middleware.
The two logging requirements occur at different lifecycle boundaries. Agent run middleware surrounds an agent invocation, so it is the appropriate place to capture run start, run completion, exceptions, and the final agent result. Function calling middleware surrounds tool/function execution and can inspect the selected function, arguments, result, and failures. That makes it the correct boundary for an audit record of each customer-refund-tool invocation. Foundry tracing can provide broader distributed observability, but the question asks for reusable Microsoft Agent Framework middleware at the exact execution points. A knowledge store or memory store does not provide execution interception. Separating the two concerns also supports a cleaner audit model: agent-level middleware records specialist behavior, while function-level middleware records tool use. This aligns with Microsoft ' s middleware model, where cross-cutting concerns such as logging, validation, and exception handling can be implemented once and applied consistently rather than duplicated inside every agent or tool.
Official Microsoft reference: Microsoft Agent Framework - Defining middleware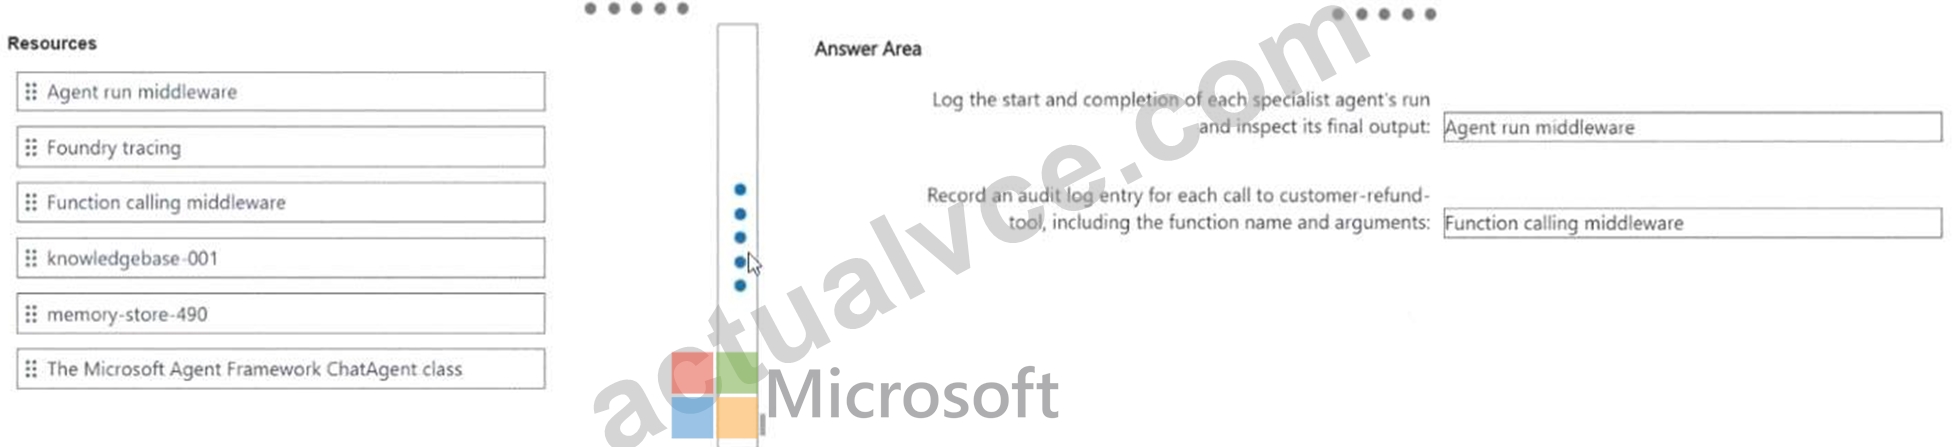
NEW QUESTION # 11
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.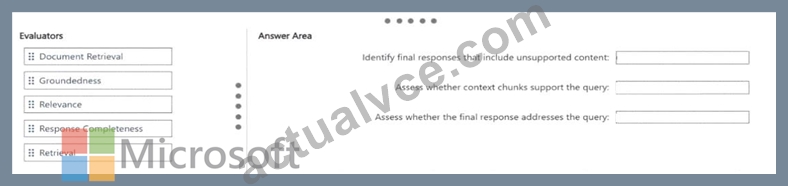
Answer:
Explanation: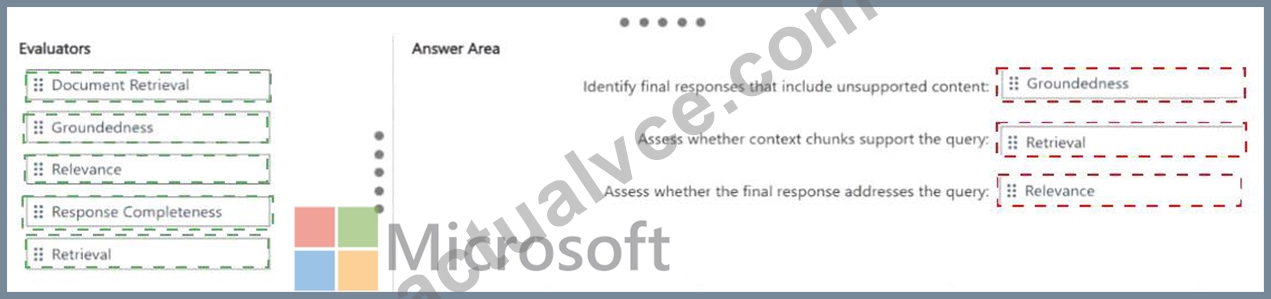
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 12
You have a Microsoft Foundry multi-agent solution that uses Microsoft Agent Framework and LangGraph.
Telemetry from the workload is sent to Application Insights.
You need to implement observability components to meet the following requirements:
* Support the investigation of user interactions across agents, models, tools, functions, and API boundaries without relying on verbose production logs.
* Produce recurring and comparable measurements of deployed response quality and safety over time.
What should you use? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.
Answer:
Explanation: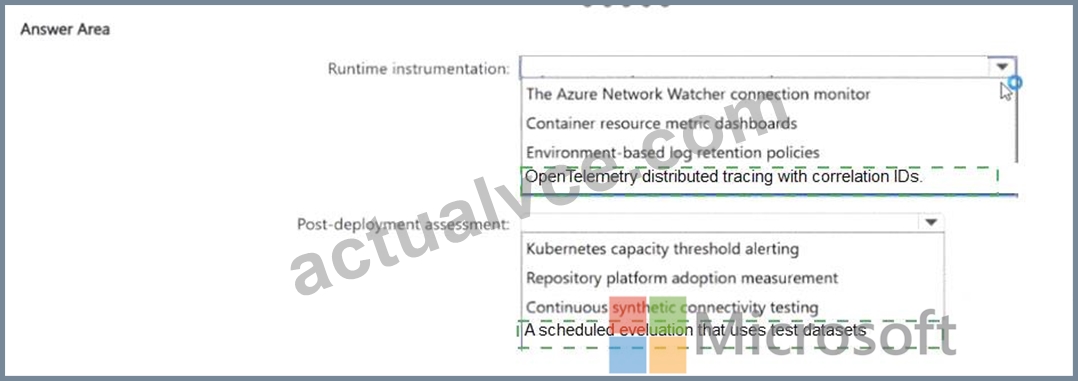
Explanation:
Runtime instrumentation: OpenTelemetry distributed tracing with correlation IDs; Post-deployment assessment: A scheduled evaluation that uses test datasets.
Distributed tracing is the correct runtime mechanism because the objective is to reconstruct a user interaction across agents, models, tools, functions, and API boundaries without relying on verbose log text. Microsoft Foundry uses OpenTelemetry-compatible traces and Application Insights so related spans can be correlated into one execution path. Correlation identifiers allow operators to isolate one conversation and inspect where latency, failures, or unexpected behavior originated. The second requirement is different: it asks for recurring, comparable measurements of deployed response quality and safety. Scheduled evaluations against stable test datasets provide that longitudinal benchmark and are more appropriate than ad hoc tracing or infrastructure- only dashboards. Together, OpenTelemetry answers "what happened in this run?" while scheduled evaluation answers "is behavior getting better or worse over time?" The selected pair therefore covers both operational diagnosis and quality regression monitoring. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry observability concepts
NEW QUESTION # 13
You have a Microsoft Foundry Agent Sen/ice solution that includes two agents.
You need to configure memory for the agents. The solution must meet the following requirements:
* Isolate the memory between end users
* Isolate the memory between the agent domains.
* Support the deletion of one user ' s memory without deleting other users ' memory.
Solution: You create a dedicated memory store for each agent and set scope for each memory search tool to
{{Suserld}} Does this meet the goal?
Answer: A
Explanation:
A dedicated memory store for each agent establishes agent-domain isolation. Setting each memory search tool
' s scope to the current user identity establishes the second isolation dimension: users within the same agent domain receive separate logical memory collections. Microsoft Foundry Memory documents `scope` as the partitioning mechanism and specifically supports `{{$userId}}` for automatic per-user isolation. Memory associated with one scope can be deleted without removing memories stored under other scopes, which satisfies the deletion requirement. The source text renders the token imperfectly as `{{Suserld}}`; the current documented syntax is `{{$userId}}`. Interpreting the question as the documented user-scope token, the design satisfies domain isolation, user isolation, and per-user deletion. Therefore A, Yes, is correct. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Create and use memory in Foundry Agent Service
NEW QUESTION # 14
You have an Azure API Management Premium instance that hosts a REST API named inventoryAPl.
You plan to provide Microsoft Foundry agents with the ability to call API operations by using the Model Context Protocol (MCP). You will use API Management as the gateway without a separate MCP backend.
You need to recommend a solution for the MCP deployment that supports the following:
* Microsoft Entra JSON Web Token (JWT) validation
* Azure Monitor diagnostics
* Request quotas
What should you recommend?
Answer: A
Explanation:
Azure API Management can expose an existing managed REST API directly as a remote MCP server, turning selected REST operations into MCP tools without requiring a separate MCP backend. The API Management gateway continues to apply its policy engine, so Microsoft Entra JWT validation, quotas/rate limits, and Azure Monitor/Application Insights diagnostics can be enforced at the MCP endpoint. Azure API Center catalogs APIs but does not itself create the MCP runtime endpoint. Azure Functions or Logic Apps could host MCP-compatible code, but both would introduce the separate backend that the question explicitly says to avoid. Because the API already resides in an APIM Premium instance, using APIM ' s native MCP exposure capability is the minimal and policy-rich design. Therefore B is correct. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure API Management - Expose REST API as an MCP server
NEW QUESTION # 15
......
On our webiste, you have easy access to our free demos of our AI-500 exam braindumps. Once you apply for our free trials of the AI-500 study materials, our system will quickly send it via email. Last but not least, you are available for our free updated version of the AI-500 Real Exam. Whenever you have problems about our study materials, you can contact our online workers via email. We warmly welcome you to experience our considerate service.
New AI-500 Braindumps Questions: https://www.actualvce.com/Microsoft/AI-500-valid-vce-dumps.html