DOWNLOAD the newest TestkingPass Data-Engineer-Associate PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1xsPfY6iNLO3e4uKUKe2wpKD1F0APf7aD
It will provide them with the Data-Engineer-Associate exam pdf questions updates free of charge if the Data-Engineer-Associate certification exam issues the latest changes. If you work hard using our top-rated, updated, and excellent Amazon Data-Engineer-Associate PDF Questions, nothing can refrain you from getting the Amazon Data-Engineer-Associate certificate on the maiden endeavor.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Ingestion and Transformation | 34% | - Transform and enrich data
|
| Topic 2: Data Store Management | 26% | - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Topic 3: Data Operations and Support | 22% | - Backup, restore, and disaster recovery - Monitor and troubleshoot data pipelines
- Automate operational tasks |
| Topic 4: Data Security and Governance | 18% | - Implement access control and authentication
- Enforce compliance and data governance
|
>> Reliable Data-Engineer-Associate Test Cram <<
There are great and plenty benefits after the clients pass the Data-Engineer-Associate test. Because the knowledge that our Data-Engineer-Associate exam practice materials provides is conducive to enhancing the client' practical working abilities and stocks of knowledge, the clients will be easier to increase their wages and be promoted by their boss. Besides, they will be respected by their colleagues, friends and family members and be recognized as the elites among the industry. They will acquire more access to work abroad for further studies. So the clients must appreciate our Data-Engineer-Associate study question after they pass the test.
NEW QUESTION # 296
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?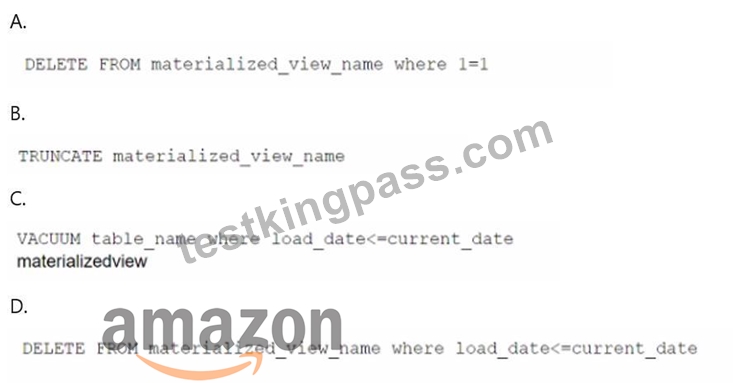
Answer: C
Explanation:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
* Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
* Amazon Redshift Materialized Views Documentation
* Deleting Data from Redshift
NEW QUESTION # 297
A company is building a data lake for a new analytics team. The company is using Amazon S3 for storage and Amazon Athena for query analysis. All data that is in Amazon S3 is in Apache Parquet format.
The company is running a new Oracle database as a source system in the company's data center. The company has 70 tables in the Oracle database. All the tables have primary keys. Data can occasionally change in the source system. The company wants to ingest the tables every day into the data lake.
Which solution will meet this requirement with the LEAST effort?
Answer: B
Explanation:
The company needs to ingest tables from an on-premises Oracle database into a data lake on Amazon S3 in Apache Parquet format. The most efficient solution, requiring the least manual effort, would be to use AWS Database Migration Service (DMS) for continuous data replication.
Option C: Create an AWS Database Migration Service (AWS DMS) task for ongoing replication. Set the Oracle database as the source. Set Amazon S3 as the target. Configure the task to write the data in Parquet format.
AWS DMS can continuously replicate data from the Oracle database into Amazon S3, transforming it into Parquet format as it ingests the data. DMS simplifies the process by providing ongoing replication with minimal setup, and it automatically handles the conversion to Parquet format without requiring manual transformations or separate jobs. This option is the least effort solution since it automates both the ingestion and transformation processes.
Other options:
Option A (Apache Sqoop on EMR) involves more manual configuration and management, including setting up EMR clusters and writing Sqoop jobs.
Option B (AWS Glue bookmark job) involves configuring Glue jobs, which adds complexity. While Glue supports data transformations, DMS offers a more seamless solution for database replication.
Option D (RDS and Lambda triggers) introduces unnecessary complexity by involving RDS and Lambda for a task that DMS can handle more efficiently.
Reference:
AWS Database Migration Service (DMS)
DMS S3 Target Documentation
NEW QUESTION # 298
A company has five offices in different AWS Regions. Each office has its own human resources (HR) department that uses a unique IAM role. The company stores employee records in a data lake that is based on Amazon S3 storage.
A data engineering team needs to limit access to the records. Each HR department should be able to access records for only employees who are within the HR department's Region.
Which combination of steps should the data engineering team take to meet this requirement with the LEAST operational overhead? (Choose two.)
Answer: A,E
Explanation:
AWS Lake Formation is a service that helps you build, secure, and manage data lakes on Amazon S3. You can use AWS Lake Formation to register the S3 path as a data lake location, and enable fine-grained access control to limit access to the records based on the HR department's Region. You can use data filters to specify which S3 prefixes or partitions each HR department can access, and grant permissions to the IAM roles of the HR departments accordingly. This solution will meet the requirement with the least operational overhead, as it simplifies the data lake management and security, and leverages the existing IAM roles of the HR departments12.
The other options are not optimal for the following reasons:
A . Use data filters for each Region to register the S3 paths as data locations. This option is not possible, as data filters are not used to register S3 paths as data locations, but to grant permissions to access specific S3 prefixes or partitions within a data location. Moreover, this option does not specify how to limit access to the records based on the HR department's Region.
C . Modify the IAM roles of the HR departments to add a data filter for each department's Region. This option is not possible, as data filters are not added to IAM roles, but to permissions granted by AWS Lake Formation. Moreover, this option does not specify how to register the S3 path as a data lake location, or how to enable fine-grained access control in AWS Lake Formation.
E . Create a separate S3 bucket for each Region. Configure an IAM policy to allow S3 access. Restrict access based on Region. This option is not recommended, as it would require more operational overhead to create and manage multiple S3 buckets, and to configure and maintain IAM policies for each HR department. Moreover, this option does not leverage the benefits of AWS Lake Formation, such as data cataloging, data transformation, and data governance.
Reference:
1: AWS Lake Formation
2: AWS Lake Formation Permissions
: AWS Identity and Access Management
: Amazon S3
NEW QUESTION # 299
A media company wants to improve a system that recommends media content to customer based on user behavior and preferences. To improve the recommendation system, the company needs to incorporate insights from third-party datasets into the company's existing analytics platform.
The company wants to minimize the effort and time required to incorporate third-party datasets.
Which solution will meet these requirements with the LEAST operational overhead?
Answer: C
Explanation:
AWS Data Exchange is a service that makes it easy to find, subscribe to, and use third-party data in the cloud.
It provides a secure and reliable way to access and integrate data from various sources, such as data providers, public datasets, or AWS services. Using AWS Data Exchange, you can browse and subscribe to data products that suit your needs, and then use API calls or the AWS Management Console to export the data to Amazon S3, where you can use it with your existing analytics platform. This solution minimizes the effort and time required to incorporate third-party datasets, as you do not need to set up and manage data pipelines, storage, or access controls. You also benefit from the data quality and freshness provided by the data providers, who can update their data products as frequently as needed12.
The other options are not optimal for the following reasons:
* B. Use API calls to access and integrate third-party datasets from AWS. This option is vague and does not specify which AWS service or feature is used to access and integrate third-party datasets. AWS offers a variety of services and features that can help with data ingestion, processing, and analysis, but not all of them are suitable for the given scenario. For example, AWS Glue is a serverless data integration service that can help you discover, prepare, and combine data from various sources, but it requires you to create and run data extraction, transformation, and loading (ETL) jobs, which can add operational overhead3.
* C. Use Amazon Kinesis Data Streams to access and integrate third-party datasets from AWS CodeCommit repositories. This option is not feasible, as AWS CodeCommit is a source control service that hosts secure Git-based repositories, not a data source that can be accessed by Amazon Kinesis Data Streams. Amazon Kinesis Data Streams is a service that enables you to capture, process, and analyze data streams in real time, such as clickstream data, application logs, or IoT telemetry. It does not support accessing and integrating data from AWS CodeCommit repositories, which are meant for storing and managing code, not data .
* D. Use Amazon Kinesis Data Streams to access and integrate third-party datasets from Amazon Elastic Container Registry (Amazon ECR). This option is also not feasible, as Amazon ECR is a fully managed container registry service that stores, manages, and deploys container images, not a data source that can be accessed by Amazon Kinesis Data Streams. Amazon Kinesis Data Streams does not support accessing and integrating data from Amazon ECR, which is meant for storing and managing container images, not data .
:
1: AWS Data Exchange User Guide
2: AWS Data Exchange FAQs
3: AWS Glue Developer Guide
4: AWS CodeCommit User Guide
5: Amazon Kinesis Data Streams Developer Guide
6: Amazon Elastic Container Registry User Guide
7: Build a Continuous Delivery Pipeline for Your Container Images with Amazon ECR as Source
NEW QUESTION # 300
A data engineer is launching an Amazon EMR cluster. The data that the data engineer needs to load into the new cluster is currently in an Amazon S3 bucket. The data engineer needs to ensure that data is encrypted both at rest and in transit.
The data that is in the S3 bucket is encrypted by an AWS Key Management Service (AWS KMS) key. The data engineer has an Amazon S3 path that has a Privacy Enhanced Mail (PEM) file.
Which solution will meet these requirements?
Answer: A
Explanation:
To meet both encryption at rest and in transit, a single Amazon EMR security configuration can be created specifying the AWS KMS key for encryption at rest and the PEM file for in-transit encryption. The study guide clearly states:
"AWS Key Management Service (KMS) provides encryption for data at rest, and SSL/TLS ensures encryption for data in transit, providing end-to-end encryption within an AWS environment."
-Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf A single security configuration is sufficient and the cleanest way to apply these security features during EMR cluster setup.
NEW QUESTION # 301
......
The Software version of our Data-Engineer-Associate exam materials can let the user to carry on the simulation study on the Data-Engineer-Associate study materials, fully in accordance with the true real exam simulation, as well as the perfect timing system, at the end of the test is about to remind users to speed up the speed to solve the problem, the Data-Engineer-Associate Training Materials let users for their own time to control has a more profound practical experience, thus effectively and perfectly improve user efficiency to solve the problem in practice, let them do it keep up on exams.
Reliable Data-Engineer-Associate Exam Practice: https://www.testkingpass.com/Data-Engineer-Associate-testking-dumps.html
P.S. Free & New Data-Engineer-Associate dumps are available on Google Drive shared by TestkingPass: https://drive.google.com/open?id=1xsPfY6iNLO3e4uKUKe2wpKD1F0APf7aD