Databricks-Certified-Data-Engineer-Professional Valid Exam Objectives | Test Databricks-Certified-Data-Engineer-Professional Score Report
BTW, DOWNLOAD part of It-Tests Databricks-Certified-Data-Engineer-Professional dumps from Cloud Storage: https://drive.google.com/open?id=1zkVniQelyNnBe0walaMXC0K7sXI28lp9
As a member of the people working in the Databricks-Certified-Data-Engineer-Professional industry, do you have a headache for passing some Databricks certification exams? Generally, Databricks-Certified-Data-Engineer-Professional certification exams are used to test the examinee's related Databricks-Certified-Data-Engineer-Professional professional knowledge and experience and it is not easy pass these exams. For the examinees who are the first time to participate Databricks-Certified-Data-Engineer-Professional certification exam, choosing a good pertinent training program is very necessary. It-Tests can offer a specific training program for many examinees participating in Databricks certification exams. Our training program includes simulation test before the formal examination, specific training course and the current exam which has 95% similarity with the real exam. Please add It-Tests to you shopping car quickly.
| Section | Objectives |
|---|
| Delta Lake and Data Management | - Time travel and versioning
- Schema evolution and enforcement
- Delta Lake transactions and ACID properties
|
| Data Ingestion and Processing | - ETL pipeline design patterns
- Batch and streaming ingestion with Auto Loader
- Structured Streaming fundamentals
|
| Production Pipelines and Orchestration | - Error handling and recovery strategies
- Job scheduling and monitoring
- Databricks Workflows
|
| Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Workspace and cluster architecture
- Medallion architecture (Bronze, Silver, Gold)
|
| Data Modeling and Transformation | - Spark SQL transformations
- Performance optimization techniques
- Dimensional modeling concepts
|
>> Databricks-Certified-Data-Engineer-Professional Valid Exam Objectives <<
Hot Databricks-Certified-Data-Engineer-Professional Valid Exam Objectives | Valid Databricks Test Databricks-Certified-Data-Engineer-Professional Score Report: Databricks Certified Data Engineer Professional Exam
You don't need to worry about wasting your precious time but failing to get the Databricks-Certified-Data-Engineer-Professional certification. Many people have used our Databricks-Certified-Data-Engineer-Professional study materials and the pass rate of the exam is 99%. This means as long as you learn with our Databricks-Certified-Data-Engineer-Professional Practice Guide, you will pass the exam without doubt. And we will give you one year's free update of the exam study materials you purchase and 24/7 online service. Now just make up your mind and get your Databricks-Certified-Data-Engineer-Professional exam dumps!
Databricks Certified Data Engineer Professional Exam Sample Questions (Q18-Q23):
NEW QUESTION # 18
A data engineer needs to design an efficient pipeline that automatically processes new CSV files as they arrive in S3 storage. Which Databricks feature should the data engineer use to meet these requirements?
- A. COPY INTO SQL command with parameters to track processed files
- B. Traditional batch processing with scheduled Databricks Jobs
- C. Streaming from cloud storage using standard Spark readStream with format ("csv") and format ("json")
- D. Auto Loader with schema inference and evolution enabled
Answer: D
Explanation:
Auto Loader is designed to efficiently and incrementally process new files as they arrive in cloud object storage. It provides scalable file discovery, supports schema inference and evolution, and minimizes overhead compared to traditional batch or manual streaming approaches.
NEW QUESTION # 19
A facilities-monitoring team is building a near-real-time PowerBI dashboard off the Delta table device_readings:
Columns:
device_id (STRING, unique sensor ID)
event_ts (TIMESTAMP, ingestion timestamp UTC)
temperature_c (DOUBLE, temperature in °C)
Requirement:
For each sensor, generate one row per non-overlapping 5-minute
interval, offset by 2 minutes (e.g., 00:02-00:07, 00:07-00:12, ...).
Each row must include interval start, interval end, and average
temperature in that slice.
Downstream BI tools (e.g., Power BI) must use the interval timestamps
to plot time-series bars.
- A. SELECT device_id,
event_ts,
AVG(temperature_c) OVER (
PARTITION BY device_id
ORDER BY event_ts
RANGE BETWEEN INTERVAL 5 MINUTES PRECEDING AND CURRENT ROW
) AS avg_temp_5m
FROM device_readings
WINDOW w AS (window(event_ts, '5 minutes', '2 minutes')); - B. SELECT device_id,
window.start AS bucket_start,
window.end AS bucket_end,
AVG(temperature_c) AS avg_temp_5m
FROM device_readings
GROUP BY device_id, window(event_ts, '5 minutes', '5 minutes', '2 minutes') ORDER BY device_id, bucket_start; - C. SELECT device_id,
date_trunc('minute', event_ts - INTERVAL 2 MINUTES) + INTERVAL 2 MINUTES AS bucket_start, date_trunc('minute', event_ts - INTERVAL 2 MINUTES) + INTERVAL 7 MINUTES AS bucket_end, AVG(temperature_c) AS avg_temp_5m FROM device_readings GROUP BY device_id, date_trunc('minute', event_ts - INTERVAL 2 MINUTES) ORDER BY device_id, bucket_start; - D. WITH buckets AS (
SELECT device_id,
window(event_ts, '5 minutes', '2 minutes', '5 minutes') AS win,
temperature_c
FROM device_readings
)
SELECT device_id,
win.start AS bucket_start,
win.end AS bucket_end,
AVG(temperature_c) AS avg_temp_5m
FROM buckets
GROUP BY device_id, win
ORDER BY device_id, bucket_start;
Answer: D
Explanation:
The correct way to satisfy non-overlapping windows with an offset in Databricks SQL is to use the window function with three parameters: window duration, slide duration, and start offset.
In option A, the function call:
window(event_ts, '5 minutes', '2 minutes', '5 minutes')
creates 5-minute windows that slide every 5 minutes, with a 2-minute offset, which exactly matches the requirement (intervals like 00:02?0:07, 00:07?0:12, ...).
NEW QUESTION # 20
A distributed team of data analysts share computing resources on an interactive cluster with autoscaling configured. In order to better manage costs and query throughput, the workspace administrator is hoping to evaluate whether cluster upscaling is caused by many concurrent users or resource-intensive queries.
In which location can one review the timeline for cluster resizing events?
- A. Driver's log file
- B. Ganglia
- C. Executor's log file
- D. Cluster Event Log
- E. Workspace audit logs
Answer: D
Explanation:
The Cluster Event Log in Databricks will show the timeline for cluster resizing events, including details about when and why a cluster was resized (scaled up or down). This log would help the workspace administrator determine the causes of cluster scaling, whether due to many concurrent users submitting jobs or a few users running resource-intensive queries.
NEW QUESTION # 21
A data engineer, while designing a Pandas UDF to process financial time-series data with complex calculations that require maintaining state across rows within each stock symbol group, must ensure the function is efficient and scalable. Which approach will solve the problem with minimum overhead while preserving data integrity?
- A. Use a grouped_agg Pandas UDF that processes each stock symbol group independently, maintaining state through intermediate aggregation results that get passed between successive UDF calls via broadcast variables.
- B. Use a SCALAR Pandas UDF that processes the entire dataset at once, implementing custom partitioning logic within the UDF to group by stock symbol and maintain state using global variables shared across all executor processes.
- C. Use applyInPandas() on a Spark DataFrame that receives all rows for each stock symbol as a Pandas DataFrame, allowing processing within each group while maintaining state variables local to each group's processing function.
- D. Use a SCALAR_ITER Pandas UDF with iterator-based processing, implementing state management through persistent storage (Delta tables) that gets updated after each batch to maintain continuity across iterator chunks.
Answer: C
Explanation:
The Databricks documentation recommends applyInPandas() for complex per-group operations where maintaining internal state within each group is necessary. When using applyInPandas(), Spark provides all records for each grouping key as a Pandas DataFrame to the function, allowing efficient vectorized operations with local state management. This approach ensures high performance and scalability while maintaining logical isolation between groups. In contrast, SCALAR and SCALAR_ITER UDFs operate on individual rows or batches and cannot maintain inter-row state effectively. grouped_agg UDFs are limited to computing aggregates and do not support complex multi-row transformations. Therefore, applyInPandas() is the correct and Databricks-recommended solution for stateful per-group time-series computations.
NEW QUESTION # 22
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".
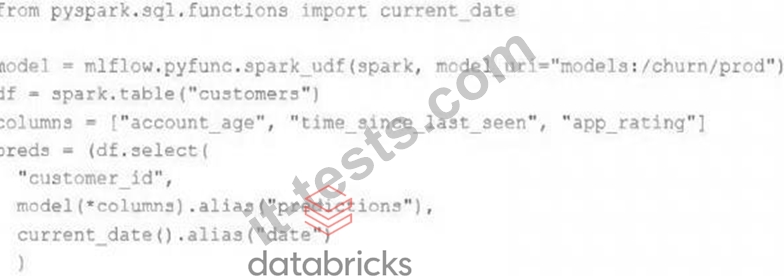
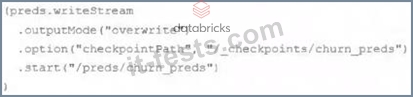
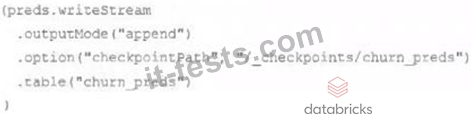
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
- A.
- B.
- C. preds.write.mode("append").saveAsTable("churn_preds")
- D.
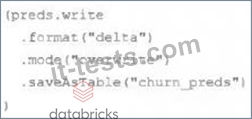
- E. preds.write.format("delta").save("/preds/churn_preds")
Answer: C
NEW QUESTION # 23
......
For the Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) web-based practice exam no special software installation is required. Because it is a browser-based Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) practice test. The web-based Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional) practice exam works on all operating systems like Mac, Linux, iOS, Android, and Windows.
Test Databricks-Certified-Data-Engineer-Professional Score Report: https://www.it-tests.com/Databricks-Certified-Data-Engineer-Professional.html
- Databricks-Certified-Data-Engineer-Professional Exam Cost ❣ Valid Test Databricks-Certified-Data-Engineer-Professional Format 🥺 Databricks-Certified-Data-Engineer-Professional Valid Exam Format 💒 Search for 【 Databricks-Certified-Data-Engineer-Professional 】 and download it for free on ☀ www.vceengine.com ️☀️ website 👦Valid Databricks-Certified-Data-Engineer-Professional Test Blueprint
- Free PDF 2026 Databricks Databricks-Certified-Data-Engineer-Professional: High-quality Databricks Certified Data Engineer Professional Exam Valid Exam Objectives 🧰 Simply search for 【 Databricks-Certified-Data-Engineer-Professional 】 for free download on ➠ www.pdfvce.com 🠰 🌀Databricks-Certified-Data-Engineer-Professional Pdf Dumps
- Databricks-Certified-Data-Engineer-Professional Valid Exam Objectives - Databricks Databricks Certified Data Engineer Professional Exam - Valid Test Databricks-Certified-Data-Engineer-Professional Score Report 🎡 Open ➤ www.examcollectionpass.com ⮘ enter ▷ Databricks-Certified-Data-Engineer-Professional ◁ and obtain a free download ✅Databricks-Certified-Data-Engineer-Professional Pdf Dumps
- Dumps Databricks-Certified-Data-Engineer-Professional PDF 🙀 Practice Test Databricks-Certified-Data-Engineer-Professional Fee ⛑ Test Databricks-Certified-Data-Engineer-Professional Simulator 🚇 Open ▷ www.pdfvce.com ◁ enter { Databricks-Certified-Data-Engineer-Professional } and obtain a free download 👞Databricks-Certified-Data-Engineer-Professional Exam Cost
- Pass Guaranteed Quiz 2026 Databricks High Pass-Rate Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam Valid Exam Objectives 🍰 Immediately open ⏩ www.troytecdumps.com ⏪ and search for [ Databricks-Certified-Data-Engineer-Professional ] to obtain a free download ⚛Valid Databricks-Certified-Data-Engineer-Professional Test Simulator
- Practice Databricks-Certified-Data-Engineer-Professional Exam Fee 🖍 Exam Databricks-Certified-Data-Engineer-Professional Bootcamp 🗺 Databricks-Certified-Data-Engineer-Professional Mock Test 🔹 Immediately open ▛ www.pdfvce.com ▟ and search for ☀ Databricks-Certified-Data-Engineer-Professional ️☀️ to obtain a free download 😙Databricks-Certified-Data-Engineer-Professional New Braindumps Ebook
- Databricks-Certified-Data-Engineer-Professional Valid Exam Format 🤍 Dumps Databricks-Certified-Data-Engineer-Professional PDF 🦎 Databricks-Certified-Data-Engineer-Professional Pdf Dumps 👜 Enter ☀ www.testkingpass.com ️☀️ and search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ to download for free 📀Training Databricks-Certified-Data-Engineer-Professional For Exam
- Practice Test Databricks-Certified-Data-Engineer-Professional Fee ⬜ Databricks-Certified-Data-Engineer-Professional Valid Exam Format 🏎 Pass4sure Databricks-Certified-Data-Engineer-Professional Exam Prep 🍐 Search for { Databricks-Certified-Data-Engineer-Professional } on “ www.pdfvce.com ” immediately to obtain a free download 🙎Databricks-Certified-Data-Engineer-Professional Mock Test
- Databricks Databricks-Certified-Data-Engineer-Professional Valid Exam Objectives Exam Latest Release | Updated Databricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam 🏓 Download { Databricks-Certified-Data-Engineer-Professional } for free by simply searching on ➠ www.verifieddumps.com 🠰 🐁Databricks-Certified-Data-Engineer-Professional Most Reliable Questions
- Valid Databricks Databricks-Certified-Data-Engineer-Professional Valid Exam Objectives | Try Free Demo before Purchase 💷 Enter 《 www.pdfvce.com 》 and search for ➠ Databricks-Certified-Data-Engineer-Professional 🠰 to download for free 👖Practice Test Databricks-Certified-Data-Engineer-Professional Fee
- Online Databricks-Certified-Data-Engineer-Professional Version 🖕 Databricks-Certified-Data-Engineer-Professional Mock Test ⛷ Valid Databricks-Certified-Data-Engineer-Professional Test Simulator 🎓 Search for ➤ Databricks-Certified-Data-Engineer-Professional ⮘ and download it for free immediately on { www.prep4sures.top } 🧿Databricks-Certified-Data-Engineer-Professional Most Reliable Questions
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, blogfreely.net, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
P.S. Free 2026 Databricks Databricks-Certified-Data-Engineer-Professional dumps are available on Google Drive shared by It-Tests: https://drive.google.com/open?id=1zkVniQelyNnBe0walaMXC0K7sXI28lp9