Certified-Data-Engineer-Professional Exam, Certified-Data-Engineer-Professional Examengine

Viele Leute meinen, man braucht viel fachliche IT-Kenntnisse, um die schwierigen Databricks Certified-Data-Engineer-Professional IT-Zertifizierungsprüfung zu bestehen. Nur diejenigen, die umfassende IT-Kenntnisse besitzen, sind qualifiziert dazu, sich an der Databricks Certified-Data-Engineer-Professional Prüfung zu beteiligen. Jetzt gibt es viele Methoden, die Ihre unausreichenden Fachkenntnisse wettmachen. Sie können sogar mit weniger Zeit und Energie als die fachlich gutqualifizierten die Databricks Certified-Data-Engineer-Professional Prüfung auch bestehen. Wie es heißt, viele Wege führen nach Rom.
Databricks Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 5. Apply Change Data Feed to address streaming table limitations and improve latency
|
| Debugging and Deploying | - Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
- Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
|
| Data Sharing and Federation | - Share and federate data
- 1. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 2. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 3. Configure Lakehouse Federation with appropriate governance across supported source systems
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Design and implement scalable data models using Delta Lake to manage large datasets
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Identify the benefits of liquid clustering over partitioning and Z-Ordering
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use Query Profile and Spark UI to monitor workloads
|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Use row filters and column masks to protect sensitive table data
- 3. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 2. Develop User-Defined Functions using Pandas/Python UDF
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 2. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 3. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 4. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Create pipeline components using control flow operators such as if/else and foreach
- 7. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 8. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
|
>> Certified-Data-Engineer-Professional Exam <<
Kostenlose Databricks Certified Data Engineer Professional vce dumps & neueste Certified-Data-Engineer-Professional examcollection Dumps
Es ist nicht leicht für ITer, die Databricks Certified-Data-Engineer-Professional IT-Zertifizierungen zu besitzen. Aber Diese Weise ist am besten für sie, ihre Fähigkeit zu entwickeln und ihren Wert zu beweisen. Deshalb müssen viele Leute die Databricks Certified-Data-Engineer-Professional Prüfungen anmelden. So, gibt es eine einfache Methode, dass sie diese IT-Zertifizierungsprüfungen sehr leicht bestehen. Selbstverständig! Die DeutschPrüfung Dumps ist die beste Wahl. Alle Prüfungsunterlagen sind an DeutschPrüfung vorhanden. Und es kann Ihre Forderungen erfüllen. Sie können sich mehr über die Prüfungsunterlagen an DeutschPrüfung informieren.
Databricks Certified Data Engineer Professional Certified-Data-Engineer-Professional Prüfungsfragen mit Lösungen (Q243-Q248):
243. Frage
A data engineer is running a groupBy aggregation on a massive user activity log grouped by user_id. A few users have millions of records, causing task skew and long runtimes. Which technique will fix the skew in this aggregation?
- A. Use reduceByKey instead of groupBy to avoid shuffles.
- B. Use salting by adding a random prefix to skewed keys before aggregation, then aggregate again after removing the prefix.
- C. Filter out the skewed users before the aggregation.
- D. Increase the Spark driver memory and retry.
Antwort: B
Begründung:
Salting distributes records for heavily skewed keys across multiple partitions by adding a random prefix, which balances task execution during the aggregation. A second aggregation after removing the prefix correctly recombines the partial results, eliminating skew-related bottlenecks without losing accuracy.
244. Frage
A company stores account transactions in a Delta Lake table. The company needs to apply frequent account-level correlations (e.g., UPDATE statements) but wants to avoid rewriting entire Parquet files for each change to reduce file churn and improve write performance. Which Delta Lake feature should they enable?
- A. Enable automatic file compaction on writes
- B. Enable change data feed on the Delta table
- C. Enable deletion vectors on the Delta table
- D. Partition the Delta table by account_id
Antwort: C
Begründung:
Deletion vectors allow Delta Lake to track row-level deletes and updates without rewriting entire Parquet files. By recording changes separately from the base files, this feature significantly reduces file churn and improves write performance for workloads with frequent row-level modifications such as account-level updates.
245. Frage
A data engineer is troubleshooting a slow-running Delta Lake query on Databricks SQL involves complex joins and large datasets. They need to identify whether the root cause is related to poor data skipping, inefficient join strategies, or excessive data shuffling. Which approach should identify the specific bottlenecks using native Databricks tools?
- A. Use the LIMIT clause to run a subset of the query and compare execution times with the full dataset.
- B. Analyze the Top Operators panel in the Query Profile to identify high-cost operations like BroadcastNestedLoopJoin
- C. Check the query's execution time in the Jobs UI and correlate it with cluster resource utilization metrics.
- D. Enable the EXPLAIN command to review the parsed logical plan and manually estimate shuffle sizes.
Antwort: B
Begründung:
The Query Profile's Top Operators panel surfaces the most expensive operators in the query execution, making it possible to directly identify bottlenecks such as inefficient join strategies, poor data skipping, or excessive shuffling. This native visualization highlights where time and resources are spent, enabling precise root-cause analysis for slow-running queries.
246. Frage
The data engineering team has configured a Databricks SQL query and alert to monitor the values in a Delta Lake table. The recent_sensor_recordings table contains an identifying sensor_id alongside the timestamp and temperature for the most recent 5 minutes of recordings.
The below query is used to create the alert:
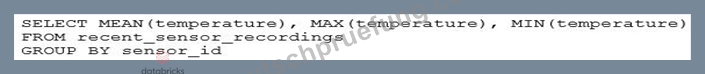
The query is set to refresh each minute and always completes in less than 10 seconds. The alert is set to trigger when mean (temperature) > 120. Notifications are triggered to be sent at most every 1 minute.
If this alert raises notifications for 3 consecutive minutes and then stops, which statement must be true?
- A. The source query failed to update properly for three consecutive minutes and then restarted
- B. The recent_sensor_recordingstable was unresponsive for three consecutive runs of the query
- C. The maximum temperature recording for at least one sensor exceeded 120 on three consecutive executions of the query
- D. The total average temperature across all sensors exceeded 120 on three consecutive executions of the query
- E. The average temperature recordings for at least one sensor exceeded 120 on three consecutive executions of the query
Antwort: E
Begründung:
This is the correct answer because the query is using a GROUP BY clause on the sensor_id column, which means it will calculate the mean temperature for each sensor separately. The alert will trigger when the mean temperature for any sensor is greater than 120, which means at least one sensor had an average temperature above 120 for three consecutive minutes. The alert will stop when the mean temperature for all sensors drops below 120.
247. Frage
Which statement describes a key benefit of an end-to-end test?
- A. It closely simulates real world usage of your application.
- B. It provides testing coverage for all code paths and branches.
- C. It makes it easier to automate your test suite
- D. It pinpoint errors in the building blocks of your application.
Antwort: A
Begründung:
End-to-end testing is a methodology used to test whether the flow of an application, from start to finish, behaves as expected. The key benefit of an end-to-end test is that it closely simulates real- world, user behavior, ensuring that the system as a whole operates correctly.
248. Frage
......
Chancen gehören zu den Leuten, wer gut vorbereitet hat. Wenn unsere Chance vor uns vorhanden ist, können wir sie erfolgreich greifen? Die Databricks Certified-Data-Engineer-Professional exam Fragen können die Garantie für Sie sein, Certified-Data-Engineer-Professional Prüfung abzulegen. Mit diesen Dumps können Sie viel Zeit sparen und hohe Effektivität haben. Sie können ihre Besonderheit und hohe Qualität kennen, wenn sie die echten Fragen und Antworten von DeutschPrüfung benutzen. Es ist wirklich ein kürzester Weg zu Ihrem Erfolg. Damit können Sie sich auf Databricks Certified-Data-Engineer-Professional Exam voll vorbereiten.
Certified-Data-Engineer-Professional Examengine: https://www.deutschpruefung.com/Certified-Data-Engineer-Professional-deutsch-pruefungsfragen.html
- Certified-Data-Engineer-Professional PDF Demo 🏅 Certified-Data-Engineer-Professional Fragen&Antworten 🎎 Certified-Data-Engineer-Professional Dumps ⚾ Suchen Sie auf 「 www.it-pruefung.com 」 nach kostenlosem Download von ➤ Certified-Data-Engineer-Professional ⮘ ✔Certified-Data-Engineer-Professional Dumps
- Das neueste Certified-Data-Engineer-Professional, nützliche und praktische Certified-Data-Engineer-Professional pass4sure Trainingsmaterial 🖋 ⏩ www.itzert.com ⏪ ist die beste Webseite um den kostenlosen Download von ⮆ Certified-Data-Engineer-Professional ⮄ zu erhalten 🆕Certified-Data-Engineer-Professional PDF Demo
- Certified-Data-Engineer-Professional aktueller Test, Test VCE-Dumps für Databricks Certified Data Engineer Professional 🕠 Suchen Sie auf ➠ www.itzert.com 🠰 nach “ Certified-Data-Engineer-Professional ” und erhalten Sie den kostenlosen Download mühelos 🦚Certified-Data-Engineer-Professional Originale Fragen
- Die seit kurzem aktuellsten Databricks Certified Data Engineer Professional Prüfungsunterlagen, 100% Garantie für Ihen Erfolg in der Databricks Certified-Data-Engineer-Professional Prüfungen! 🍲 Suchen Sie auf der Webseite “ www.itzert.com ” nach ▶ Certified-Data-Engineer-Professional ◀ und laden Sie es kostenlos herunter ◀Certified-Data-Engineer-Professional Lerntipps
- Sie können so einfach wie möglich - Certified-Data-Engineer-Professional bestehen! 💄 URL kopieren ⮆ de.fast2test.com ⮄ Öffnen und suchen Sie [ Certified-Data-Engineer-Professional ] Kostenloser Download 🔪Certified-Data-Engineer-Professional Examsfragen
- Certified-Data-Engineer-Professional Deutsch Prüfungsfragen ✡ Certified-Data-Engineer-Professional Originale Fragen 🔲 Certified-Data-Engineer-Professional Lerntipps 🐘 Geben Sie 【 www.itzert.com 】 ein und suchen Sie nach kostenloser Download von ⮆ Certified-Data-Engineer-Professional ⮄ ➖Certified-Data-Engineer-Professional Prüfungsübungen
- Certified-Data-Engineer-Professional Online Praxisprüfung 🧀 Certified-Data-Engineer-Professional Examsfragen ❣ Certified-Data-Engineer-Professional Dumps ☝ Suchen Sie auf der Webseite { www.zertpruefung.ch } nach [ Certified-Data-Engineer-Professional ] und laden Sie es kostenlos herunter 🖊Certified-Data-Engineer-Professional Online Praxisprüfung
- Das neueste Certified-Data-Engineer-Professional, nützliche und praktische Certified-Data-Engineer-Professional pass4sure Trainingsmaterial 🥨 Sie müssen nur zu ➤ www.itzert.com ⮘ gehen um nach kostenloser Download von ➤ Certified-Data-Engineer-Professional ⮘ zu suchen 🍔Certified-Data-Engineer-Professional Simulationsfragen
- Certified-Data-Engineer-Professional examkiller gültige Ausbildung Dumps - Certified-Data-Engineer-Professional Prüfung Überprüfung Torrents 🐭 [ www.echtefrage.top ] ist die beste Webseite um den kostenlosen Download von ▷ Certified-Data-Engineer-Professional ◁ zu erhalten 🖼Certified-Data-Engineer-Professional Zertifizierungsantworten
- Certified-Data-Engineer-Professional PDF Demo 🎍 Certified-Data-Engineer-Professional Examengine 🎻 Certified-Data-Engineer-Professional Praxisprüfung 💹 Suchen Sie einfach auf 「 www.itzert.com 」 nach kostenloser Download von [ Certified-Data-Engineer-Professional ] 📄Certified-Data-Engineer-Professional Zertifikatsfragen
- Certified-Data-Engineer-Professional examkiller gültige Ausbildung Dumps - Certified-Data-Engineer-Professional Prüfung Überprüfung Torrents ▛ Öffnen Sie die Webseite ⇛ www.deutschpruefung.com ⇚ und suchen Sie nach kostenloser Download von ⮆ Certified-Data-Engineer-Professional ⮄ 🦅Certified-Data-Engineer-Professional Fragen&Antworten
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.chordie.com, experiment.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, giphy.com, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes