Exam4Docs provides Microsoft DP-750 exam questions for the DP-750 exam in PDF format. The DP-750 exam questions pdf file is easy to understand and can be downloaded on all smart devices. You can access your DP-750 practice exam questions pdf by downloading the DP-750 Exam Questions on your PC, laptop, Mac, tablet, and smartphone. You can use the DP-750 pdf questions at any time and anywhere you want, making exam preparation convenient and accessible from the comfort of your home.
| Section | Weight | Objectives |
|---|---|---|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
It is inescapable choice to make why don't you choose our DP-750 practice materials with passing rate up to 98-100 percent. You can have a sweeping through of our DP-750 practice materials with intelligibly and under-stable contents. It is time to take the plunge and you will not feel depressed. All incomprehensible issues will be small problems and all contents will be printed on your minds. So even trifling mistakes can be solved by using our DP-750 practice materials, as well as all careless mistakes you may make.
NEW QUESTION # 71
Case Study 1 - Contoso, Inc.
Overview
Company Information
Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Existing Environment
Azure Environment
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region. Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
- In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
- A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
- An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Data Environment Contoso ingests the following operational and business data:
- Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
- Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
- Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
- External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
- ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
- Telemetry pipelines fall behind during peak loads.
- Telemetry ingestion fails when schema drift occurs.
- Streaming pipelines reprocess events after a pipeline restarts.
Compute
Production and development workloads run on the same all-purpose clusters.
Production and development workloads do NOT support autoscaling or workload isolation.
Governance
- The ERP data is duplicated across systems and development teams.
- Naming conventions are inconsistent across development teams, regions, and products.
- Ownership of the IoT sensors changes over time, and analysts must track the full history of the ownership.
- Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names.
Historical values are NOT required.
Pipeline operations
- Pipelines lack resiliency, alerting, and centralized scheduling.
Requirements
Planned Changes
Contoso plans to implement the following changes:
- Implement scalable data pipeline orchestration.
- Create a managed analytics catalog in Unity Catalog.
- Implement a consistent approach to creating curated datasets.
- Establish a centralized governance model across ingestion, cleansed, and curated layers.
- Grant data engineers access to the ERP tables by using minimal development effort.
- Adopt a compute strategy that isolates production workloads and supports autoscaling.
- Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
- Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
- Provide fast and consistent performance for business intelligence (BI) workloads.
- Prevent development activity from affecting production pipelines.
- Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
- Auto-scale ingestion pipelines to handle bursty workloads.
- Handle schema drift for the maintenance and telemetry data.
- Ingest file-based telemetry data by using minimal operational effort.
- Store all the ingested data in a format that supports incremental processing.
- Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
- Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
- Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
- Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
- Build curated tables that standardize business logic.
- Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements:
- Orchestrate multi-step ingestion and transformation workflows.
- Define a clear execution order and dependencies.
- Automatically retry failed steps and notify operators.
- Schedule ingestion and transformation workloads consistently.
Governance Requirements
Contoso identifies the following governance requirements:
- Centralize the metadata catalog.
- Provide isolated development areas that follow standard naming conventions.
- Establish a consistent structure for organizing raw, cleansed, and curated data.
- Provide a read-only mechanism to reference the ERP data through a foreign catalog.
Business Requirements
Contoso identifies the following business requirements:
- Improve ingestion reliability and reduce operational effort.
- Standardize data definitions across development teams.
You need to configure compute for the ingestion of telemetry data. The solution must meet the data ingestion and processing requirements. What should you do?
Answer: B
Explanation:
Enabling Photon acceleration on a job compute cluster is the best option. It significantly speeds up data engineering pipelines, handles JSON file ingestion seamlessly, and optimizes cost- efficiency for bursty production workloads, which are key for processing rapidly arriving IoT sensor events.
Enable Photon acceleration for a job compute cluster:
Databricks Auto Loader is designed for low-latency, high-volume file ingestion. Running Auto Loader on a job compute cluster provides the lowest operational cost because job clusters are billed at a much lower rate than all-purpose clusters.
Enabling Photon acceleration heavily optimizes the ingestion, parsing, and processing of raw JSON data strings, allowing the cluster to handle bursty workloads faster and auto-scale more efficiently.
Scenario, Data Environment, Contoso ingests the following operational and business data:
Telemetry data: More than 40,000 IoT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
Contoso identifies the following data ingestion and processing requirements:
-> Auto-scale ingestion pipelines to handle bursty workloads.
Handle schema drift for the maintenance and telemetry data.
-> Ingest file-based telemetry data by using minimal operational effort.
Reference:
https://medium.com/@krthiak/10-days-of-data-engineering-interview-qna-day-5-db1c0b58bf86
NEW QUESTION # 72
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Sales. Sales stores transaction data and contains the following columns:
* transactionjd (string)
* transaction date (date)
* amount (decimal)
You need to implement the following data quality requirements by using table-level data quality enforcement:
* amount must be greater than 0.
* transaction id must never be null.
* Invalid records must be rejected when data is written to the Sales table.
What should you do?
Answer: C
Explanation:
The correct answer is D - a NOT NULL constraint on transaction_id and a CHECK constraint on amount.
Delta Lake table constraints are enforced at write time by the Delta engine itself. A NOT NULL constraint rejects any INSERT or UPDATE that would place a null in transaction_id. A CHECK constraint with amount
> 0 rejects any row where amount is zero or negative. Combined, they implement exactly the stated quality rules: bad rows are rejected when data is written, not filtered away at read time.
Options A and C (SELECT with WHERE / views) are read-time constructs - they don't prevent invalid data from entering the table. A clever pipeline bypass could write directly to the table and skip the view entirely.
Option B (row-level security with WHERE conditions) is an access-control feature for restricting which rows users see, not for enforcing data quality on writes. Table constraints are the only mechanism that genuinely blocks bad data at the storage layer.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/delta-constraints
NEW QUESTION # 73
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains:
* A catalog named Corpdb
* A schema named Finance in the Corpdb catalog
* A table named Sales in the Finance schema
You have a group named Analysts.
You assign the following permissions to Analysts:
* USE CATALOG on the Corpdb catalog
* USE SCHEMA on the Finance schema
* SELECT on the Sales table
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.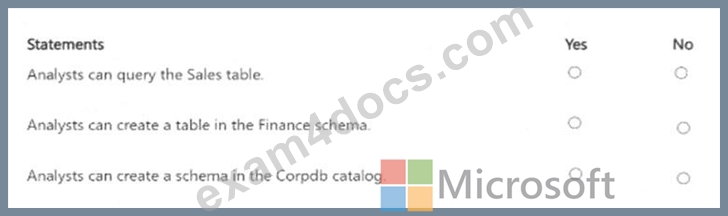
Answer:
Explanation: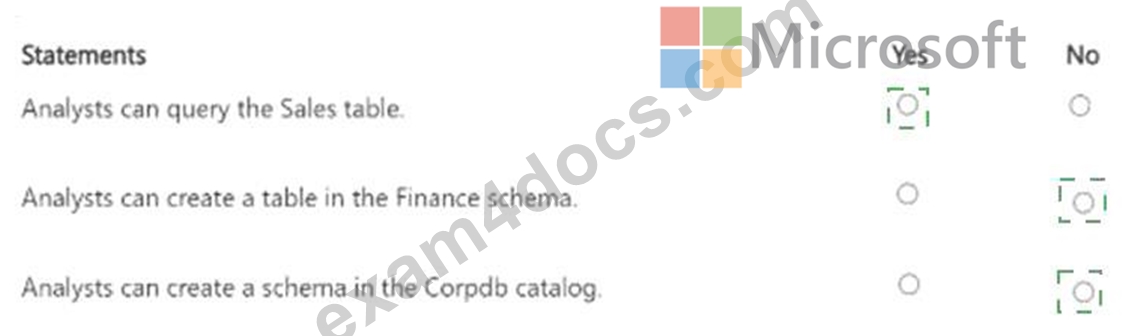
Explanation: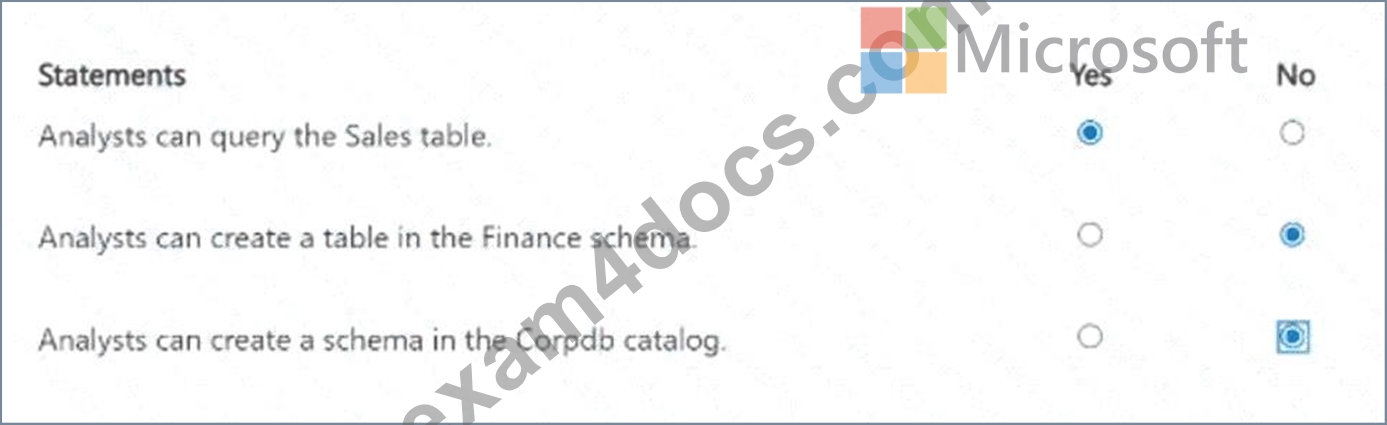
The Analysts group can query the Sales table because it has all three privileges required by the Unity Catalog hierarchy: USE CATALOG on Corpdb, USE SCHEMA on Finance, and SELECT on Sales. These permissions allow the group to navigate through the catalog and schema and read the table. However, USE SCHEMA does not grant permission to create tables. Creating a table in Finance would additionally require CREATE TABLE on that schema. Similarly, USE CATALOG only permits access to the catalog; it does not permit schema creation. Creating a schema in Corpdb would require the CREATE SCHEMA privilege on the catalog. Therefore, only the first statement is true.
NEW QUESTION # 74
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Sales_orders. Sales.orders stores historical sales data.
You receive a daily CSV file daily that contains new sales records only. The file does NOT contain updates to existing rows You need to load the daily data into Sales.orders. The solution must meet the following requirements:
* Preserve the existing data.
* Add only the new records.
* Minimize processing effort.
Which command should include in the loading strategy?
Answer: B
Explanation:
The correct answer is C - INSERT INTO.
The scenario is clear: the daily file contains only new records, no updates to existing rows. INSERT INTO is the right command because it appends the new rows to Sales.orders without touching the existing historical data. All three requirements are satisfied: existing data is preserved, only new records are added, and the loading strategy is as simple as it gets.
Option A (INSERT OVERWRITE) replaces the existing data with just today's file. After the first day you'd have only 24 hours of history - all prior sales records would be gone. Option B (UPDATE) modifies specific existing rows based on a match condition; it doesn't load new records at all.
Because the source file is guaranteed to contain only new records and no duplicates of existing rows, a full MERGE is unnecessary overhead. Simple INSERT INTO is both correct and the most efficient approach.
Reference: https://learn.microsoft.com/en-us/azure/databricks/sql/language-manual/delta-insert-into
NEW QUESTION # 75
You manage Declarative Automation Bundles by using the Databricks CLI.
You run the following command in a terminal window.
databricks bundle init
What occurs when you run the command?
Answer: A
Explanation:
The databricks bundle init command initializes a new bundle project from a selected default or custom project template. It prompts for relevant project values and creates the local project structure and starter configuration files. It does not deploy resources; deployment is performed with databricks bundle deploy. It does not merely validate an existing configuration, because validation uses databricks bundle validate. Running deployed bundle resources requires databricks bundle run followed by the resource key. The distinction matters in an automated bundle lifecycle: initialization scaffolds the project, validation checks configuration, deployment creates or updates workspace resources, and run starts a configured job or pipeline. Therefore, option A accurately describes the initialization command's function. Microsoft Learn
NEW QUESTION # 76
......
DP-750 Dumps Torrent and DP-750 learning materials are created by our IT workers who are specialized in the study of real Microsoft test questions for many years and they check the updating of dumps pdf everyday to make sure the valid of questions and answer, so you can totally rest assure of the accuracy of our Exam4Docs vce braindumps.
DP-750 Brain Dump Free: https://www.exam4docs.com/DP-750-study-questions.html