
BONUS!!! Download part of VCE4Plus MLA-C01 dumps for free: https://drive.google.com/open?id=1a-UX09n5YxRiHRp8fXQl-5iWJIjjCVja
The MLA-C01 exam questions formats are PDF dumps files, desktop practice test software, and web-based practice test software. All these MLA-C01exam questions format hold some common and unique features. Such as MLA-C01 PDF dumps file is the PDF version of AWS Certified Machine Learning Engineer - Associate exam dumps that works VCE4Plus all operating systems and devices. Whereas the other two MLA-C01 Practice Test questions formats are concerned, both are the mock MLA-C01 exam. Both will give you a real-time AWS Certified Machine Learning Engineer - Associate exam preparation environment and you get experience to attempt the MLA-C01 exam preparation experience before the final exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
>> Valid MLA-C01 Exam Review <<
Our MLA-C01 practice materials are your best choice for their efficiency in different aspects: first of all, do not need to wait, you can get them immediately if you pay for it and download as your wish. Clear-arranged content is our second advantage. Some exam candidates are prone to get anxious about the MLA-C01 Exam Questions, but with clear and points of necessary questions within our MLA-C01 study guide, you can master them effectively in limited time.
NEW QUESTION # 117
A company has deployed a model to predict the churn rate for its games by using Amazon SageMaker Studio.
After the model is deployed, the company must monitor the model performance for data drift and inspect the report. Select and order the correct steps from the following list to model monitor actions. Select each step one time. (Select and order THREE.) .
Check the analysis results on the SageMaker Studio console. .
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Schedule an hourly model explainability monitor.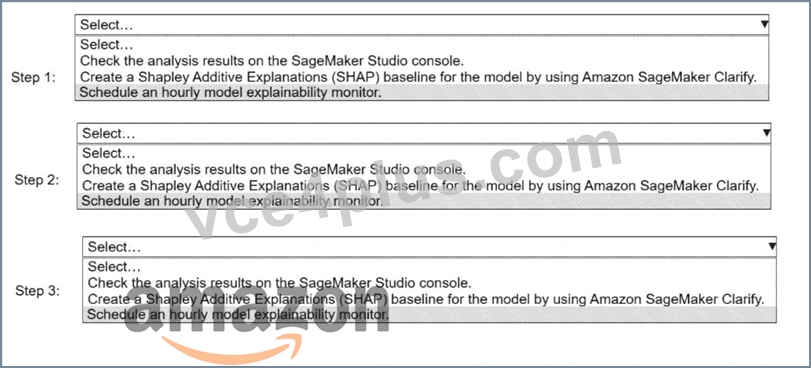
Answer:
Explanation: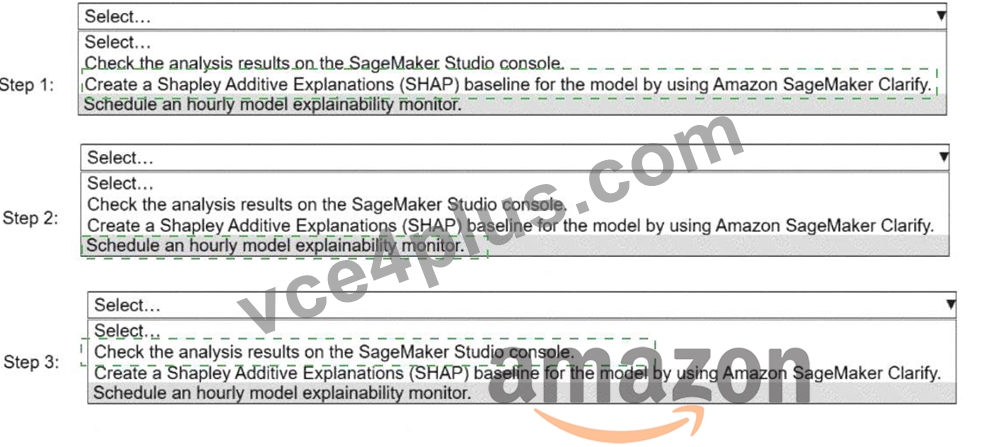
Explanation:
Step 1:
Create a Shapley Additive Explanations (SHAP) baseline for the model by using Amazon SageMaker Clarify.
Step 2:
Schedule an hourly model explainability monitor.
Step 3:
Check the analysis results on the SageMaker Studio console.
When monitoring a deployed model for data drift and explainability, AWS prescribes a specific workflow using SageMaker Clarify and SageMaker Model Monitor:
Create a SHAP baseline (Step 1)Before any monitoring can occur, SageMaker Clarify must establish a baseline explainability configuration. This baseline captures the reference SHAP values for feature importance using training or baseline data. Model Monitor uses this baseline to compare future inferences and detect drift in feature attributions.
Schedule the model explainability monitor (Step 2)After the baseline is created, an explainability monitoring schedule must be configured (hourly in this case). The monitor periodically analyzes inference data, compares it against the SHAP baseline, and generates reports that highlight drift or anomalies in feature contributions.
Inspect results in SageMaker Studio (Step 3)Once monitoring jobs run, SageMaker stores the analysis results in Amazon S3 and surfaces them in the SageMaker Studio console, where engineers can review metrics, violations, and visual reports.
This sequence is mandatory because:
A monitor cannot run without a baseline
Results cannot be reviewed until the monitor executes
NEW QUESTION # 118
A company is planning to use an Amazon SageMaker prebuilt algorithm to create a recommendation model. The algorithm must be able to make predictions on high-dimensional sparse data. Which SageMaker algorithm should the company choose for the recommendation model?
Answer: A
Explanation:
The Factorization Machines algorithm in SageMaker is specifically designed for recommendation systems and works well with high-dimensional sparse data such as user-item interactions. It efficiently models variable interactions and is the best choice for building a recommendation model in this scenario.
NEW QUESTION # 119
A company uses AWS CodePipeline to orchestrate a continuous integration and continuous delivery (CI/CD) pipeline for ML models and applications.
Select and order the steps from the following list to describe a CI/CD process for a successful deployment.
Select each step one time. (Select and order FIVE.)
. CodePipeline deploys ML models and applications to production.
CodePipeline detects code changes and starts to build automatically.
. Human approval is provided after testing is successful.
. The company builds and deploys ML models and applications to staging servers for testing.
. The company commits code changes or new training datasets to a Git repository.
Answer:
Explanation:
Explanation:
Step 1:
The company commits code changes or new training datasets to a Git repository.
This is the trigger point. A source code or data change initiates the CI/CD pipeline.
Step 2:
CodePipeline detects code changes and starts to build automatically.
CodePipeline monitors the Git repository (for example, AWS CodeCommit, GitHub, or Bitbucket) and automatically triggers the pipeline when changes are detected.
Step 3:
The company builds and deploys ML models and applications to staging servers for testing.
The pipeline runs build, training, and test stages (often using AWS CodeBuild and SageMaker) and deploys artifacts to a staging or test environment for validation.
Step 4:
Human approval is provided after testing is successful.
A manual approval action is a best practice for ML workflows to ensure governance, compliance, and quality checks before production deployment.
Step 5:
CodePipeline deploys ML models and applications to production.
After approval, the pipeline automatically deploys the validated model or application to the production environment.
NEW QUESTION # 120
An ML engineer needs to use Amazon SageMaker Feature Store to create and manage features to train a model.
Select and order the steps from the following list to create and use the features in Feature Store. Each step should be selected one time. (Select and order three.)
* Access the store to build datasets for training.
* Create a feature group.
* Ingest the records.
Answer:
Explanation:
Explanation:
Step 1: Create a feature group.
Step 2: Ingest the records.
Step 3: Access the store to build datasets for training.
Step 1: Create a Feature Group
Why? A feature group is the foundational unit in SageMaker Feature Store, where features are defined, stored, and organized. Creating a feature group specifies the schema (name, data type) for the features and the primary keys for data identification.
How? Use the SageMaker Python SDK or AWS CLI to define the feature group by specifying its name, schema, and S3 storage location for offline access.
Step 2: Ingest the Records
Why? After creating the feature group, the raw data must be ingested into the Feature Store. This step populates the feature group with data, making it available for both real-time and offline use.
How? Use the SageMaker SDK or AWS CLI to batch-ingest historical data or stream new records into the feature group. Ensure the records conform to the feature group schema.
Step 3: Access the Store to Build Datasets for Training
Why? Once the features are stored, they can be accessed to create training datasets. These datasets combine relevant features into a single format for machine learning model training.
How? Use the SageMaker Python SDK to query the offline store or retrieve real-time features using the online store API. The offline store is typically used for batch training, while the online store is used for inference.
Order Summary:
Create a feature group.
Ingest the records.
Access the store to build datasets for training.
This process ensures the features are properly managed, ingested, and accessible for model training using Amazon SageMaker Feature Store.
NEW QUESTION # 121
Case study
An ML engineer is developing a fraud detection model on AWS. The training dataset includes transaction logs, customer profiles, and tables from an on-premises MySQL database. The transaction logs and customer profiles are stored in Amazon S3.
The dataset has a class imbalance that affects the learning of the model's algorithm. Additionally, many of the features have interdependencies. The algorithm is not capturing all the desired underlying patterns in the data.
Which AWS service or feature can aggregate the data from the various data sources?
Answer: C
Explanation:
* Problem Description:
* The dataset includes multiple data sources:
* Transaction logs and customer profiles in Amazon S3.
* Tables in an on-premises MySQL database.
* There is aclass imbalancein the dataset andinterdependenciesamong features that need to be addressed.
* The solution requiresdata aggregationfrom diverse sources for centralized processing.
* Why AWS Lake Formation?
* AWS Lake Formationis designed to simplify the process of aggregating, cataloging, and securing data from various sources, including S3, relational databases, and other on-premises systems.
* It integrates with AWS Glue for data ingestion and ETL (Extract, Transform, Load) workflows, making it a robust choice for aggregating data from Amazon S3 and on-premises MySQL databases.
* How It Solves the Problem:
* Data Aggregation: Lake Formation collects data from diverse sources, such as S3 and MySQL, and consolidates it into a centralized data lake.
* Cataloging and Discovery: Automatically crawls and catalogs the data into a searchable catalog, which the ML engineer can query for analysis or modeling.
* Data Transformation: Prepares data using Glue jobs to handle preprocessing tasks such as addressing class imbalance (e.g., oversampling, undersampling) and handling interdependencies among features.
* Security and Governance: Offers fine-grained access control, ensuring secure and compliant data management.
* Steps to Implement Using AWS Lake Formation:
* Step 1: Set up Lake Formation and register data sources, including the S3 bucket and on- premises MySQL database.
* Step 2: Use AWS Glue to create ETL jobs to transform and prepare data for the ML pipeline.
* Step 3: Query and access the consolidated data lake using services such as Athena or SageMaker for further ML processing.
* Why Not Other Options?
* Amazon EMR Spark jobs: While EMR can process large-scale data, it is better suited for complex big data analytics tasks and does not inherently support data aggregation across sources like Lake Formation.
* Amazon Kinesis Data Streams: Kinesis is designed for real-time streaming data, not batch data aggregation across diverse sources.
* Amazon DynamoDB: DynamoDB is a NoSQL database and is not suitable for aggregating data from multiple sources like S3 and MySQL.
Conclusion: AWS Lake Formation is the most suitable service for aggregating data from S3 and on-premises MySQL databases, preparing the data for downstream ML tasks, and addressing challenges like class imbalance and feature interdependencies.
References:
* AWS Lake Formation Documentation
* AWS Glue for Data Preparation
NEW QUESTION # 122
......
Our AWS Certified Associate exam question is widely known throughout the education market. Almost all the candidates who are ready for the qualifying examination know our products. Even when they find that their classmates or colleagues are preparing a MLA-C01 exam, they will introduce our study materials to you. So, our learning materials help users to be assured of the MLA-C01 exam. Currently, my company has introduced a variety of learning materials, covering almost all the official certification of qualification exams, and each MLA-C01 practice dump in our online store before the listing, are subject to stringent quality checks within the company. Thus, users do not have to worry about such trivial issues as typesetting and proofreading, just focus on spending the most practice to use our AWS Certified Associate test materials. After careful preparation, I believe you will be able to pass the exam.
MLA-C01 Latest Braindumps Pdf: https://www.vce4plus.com/Amazon/MLA-C01-valid-vce-dumps.html
What's more, part of that VCE4Plus MLA-C01 dumps now are free: https://drive.google.com/open?id=1a-UX09n5YxRiHRp8fXQl-5iWJIjjCVja