2026 Latest Pass4training Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1cr1Pmtc9FR5IbE2CVNZ_fNOooKLPE-Tp
Before clients buy our Professional-Machine-Learning-Engineer questions torrent they can download them and try out them freely. The pages of our product provide the demo and the aim is to let the client know part of our titles before their purchase and what form our Professional-Machine-Learning-Engineer guide torrent is. The pages introduce the quantity of our questions and answers of our Professional-Machine-Learning-Engineer Guide Torrent. After you try out the free demo you could decide whether our Professional-Machine-Learning-Engineer exam torrent is worthy to buy or not. So you needn't worry that you will waste your money or our Professional-Machine-Learning-Engineer exam torrent is useless and boosts no values.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Real Exam Qty: | Approximately 50–60 questions |
| Related Certifications: | Google Cloud Associate Cloud Engineer Google Cloud Professional Data Engineer Google Cloud Professional Cloud Architect |
| Certificate Validity Period: | 2 years |
| Exam Price: | $200 USD |
| Available Languages: | English, Japanese |
| Exam Format: | Multiple choice, Multiple select, Case study |
| Exam Duration: | 120 minutes |
| Recommended Training: | Google Cloud Skills Boost - Machine Learning Engineer Path Vertex AI Documentation |
| Exam Registration: | Google Cloud Certification Portal Kryterion Webassessor |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online proctored exam or in-person testing via Kryterion test centers. |
| Pre Condition: | No formal prerequisites required, but 3+ years of industry experience in ML/AI and familiarity with Google Cloud Platform are strongly recommended. |
| Official Syllabus URL: | https://cloud.google.com/certification/machine-learning-engineer |
>> Relevant Professional-Machine-Learning-Engineer Questions <<
Visit Pass4training and find out the best features of updated Professional-Machine-Learning-Engineer exam dumps that is available in three user-friendly formats. We guarantee that you will be able to ace the Google Professional Machine Learning Engineer Professional-Machine-Learning-Engineer examination on the first attempt by studying with our actual Google Professional-Machine-Learning-Engineer exam questions.
Google Professional Machine Learning Engineer certification is highly valued by employers and is a testament to the candidate's knowledge and expertise in the field of machine learning. Google Professional Machine Learning Engineer certification also opens up new job opportunities for professionals in the field of machine learning, as more and more organizations are adopting machine learning technologies to improve their business processes and gain a competitive edge.
Google Professional Machine Learning Engineer exam is a certification program designed to test the skills and knowledge of individuals who work in the field of machine learning. Google Professional Machine Learning Engineer certification is intended for professionals who have a strong background in machine learning and who are interested in demonstrating their expertise in this field to potential employers.
NEW QUESTION # 281
You trained a text classification model. You have the following SignatureDefs: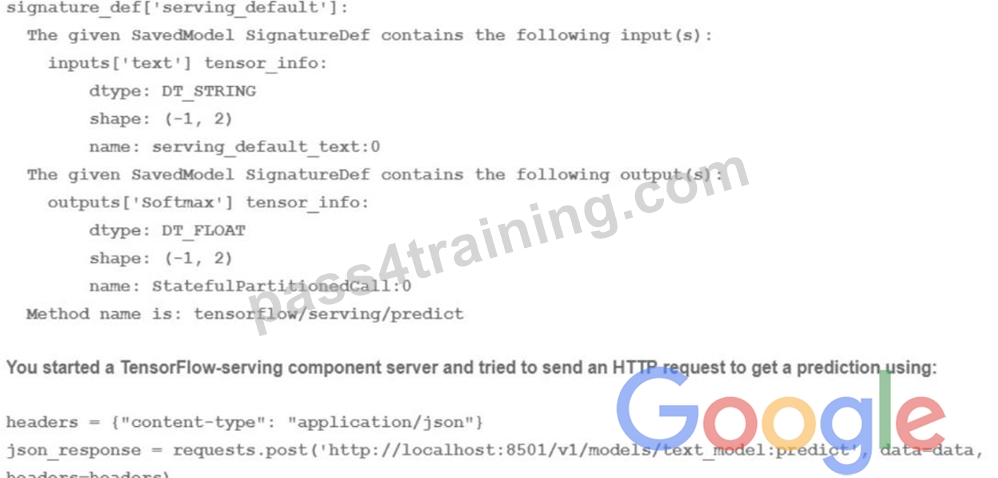
What is the correct way to write the predict request?
Answer: A
Explanation:
https://stackoverflow.com/questions/37956197/what-is-the-negative-index-in-shape-arrays-used-for-tensorflow
NEW QUESTION # 282
You are building a TensorFlow model for a financial institution that predicts the impact of consumer spending on inflation globally. Due to the size and nature of the data, your model is long-running across all types of hardware, and you have built frequent checkpointing into the training process. Your organization has asked you to minimize cost. What hardware should you choose?
Answer: D
Explanation:
The best hardware to choose for your model while minimizing cost is a Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with a preemptible v3-8 TPU. This hardware configuration can provide you with high performance, scalability, and efficiency for your TensorFlow model, as well as low cost and flexibility for your long-running and checkpointing process. The v3-8 TPU is a cloud tensor processing unit (TPU) device, which is a custom ASIC chip designed by Google to accelerate ML workloads.
It can handle large and complex models and datasets, and offer fast and stable training and inference. The n1- standard-16 is a general-purpose VM that can support the CPU and memory requirements of your model, as well as the data preprocessing and postprocessing tasks. By choosing a preemptible v3-8 TPU, you can take advantage of the lower price and availability of the TPU devices, as long as you can tolerate the possibility of the device being reclaimed by Google at any time. However, since you have built frequent checkpointing into your training process, you can resume your model from the last saved state, and avoid losing any progress or data. Moreover, you can use the Vertex AI Workbench user-managed notebooks to create and man age your notebooks instances, and leverage the integration with Vertex AI and other Google Cloud services.
The other options are not optimal for the following reasons:
* A. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with 4 NVIDIA P100 GPUs is not a good option, as it has higher cost and lower performance than the v3-8 TPU. The NVIDIA P100 GPUs are the previous generation of GPUs from NVIDIA, which have lower performance, scalability, and efficiency than the latest NVIDIA A100 GPUs or the TPUs. They also have higher price and lower availability than the preemptible TPUs, which can increase the cost and complexity of your solution.
* B. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with an NVIDIA P100 GPU is not a good option, as it has higher cost and lower performance than the v3-8 TPU. It also has less GPU memory and compute power than the option with 4 NVIDIA P100 GPUs, which can limit the size and complexity of your model, and affect the training and inference speed and quality.
* C. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with a non- preemptible v3-8 TPU is not a good option, as it has higher cost and lower flexibility than the preemptible v3-8 TPU. The non-preemptible v3-8 TPU has the same performance, scalability, and efficiency as the preemptible v3-8 TPU, but it has higher price and lower availability, as it is reserved for your exclusive use. Moreover, since your model is long-running and checkpointing, you do not need the guarantee of the device not being reclaimed by Google, and you can benefit from the lower cost and higher availability of the preemptible v3-8 TPU.
:
Professional ML Engineer Exam Guide
Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate Google Cloud launches machine learning engineer certification Cloud TPU Vertex AI Workbench user-managed notebooks Preemptible VMs NVIDIA Tesla P100 GPU
NEW QUESTION # 283
You manage a team of data scientists who use a cloud-based backend system to submit training jobs. This system has become very difficult to administer, and you want to use a managed service instead. The data scientists you work with use many different frameworks, including Keras, PyTorch, theano, scikit-learn, and custom libraries. What should you do?
Answer: D
Explanation:
The best option for using a managed service to submit training jobs with different frameworks is to use Vertex AI Training. Vertex AI Training is a fully managed service that allows you to train custom models on Google Cloud using any framework, such as TensorFlow, PyTorch, scikit-learn, XGBoost, etc. You can also use custom containers to run your own libraries and dependencies. Vertex AI Training handles the infrastructure provisioning, scaling, and monitoring for you, so you can focus on your model development and optimization.
Vertex AI Training also integrates with other Vertex AI services, such as Vertex AI Pipelines, Vertex AI Experiments, and Vertex AI Prediction. The other options are not as suitable for using a managed service to submit training jobs with different frameworks, because:
* Configuring Kubeflow to run on Google Kubernetes Engine and submit training jobs through TFJob would require more infrastructure maintenance, as Kubeflow is not a fully managed service, and you would have to provision and manage your own Kubernetes cluster. This would also incur more costs, as you would have to pay for the cluster resources, regardless of the training job usage. TFJob is also mainly designed for TensorFlow models, and might not support other frameworks as well as Vertex AI Training.
* Creating a library of VM images on Compute Engine, and publishing these images on a centralized repository would require more development time and effort, as you would have to create and maintain different VM images for different frameworks and libraries. You would also have to manually configure and launch the VMs for each training job, and handle the scaling and monitoring yourself.
This would not leverage the benefits of a managed service, such as Vertex AI Training.
* Setting up Slurm workload manager to receive jobs that can be scheduled to run on your cloud infrastructure would require more configuration and administration, as Slurm is not a native Google Cloud service, and you would have to install and manage it on your own VMs or clusters. Slurm is also a general-purpose workload manager, and might not have the same level of integration and optimization for ML frameworks and libraries as Vertex AI Training. References:
* Vertex AI Training | Google Cloud
* Kubeflow on Google Cloud | Google Cloud
* TFJob for training TensorFlow models with Kubernetes | Kubeflow
* Compute Engine | Google Cloud
* Slurm Workload Manager
NEW QUESTION # 284
You work for an online grocery store. You recently developed a custom ML model that recommends a recipe when a user arrives at the website. You chose the machine type on the Vertex Al endpoint to optimize costs by using the queries per second (QPS) that the model can serve, and you deployed it on a single machine with
8 vCPUs and no accelerators.
A holiday season is approaching and you anticipate four times more traffic during this time than the typical daily traffic You need to ensure that the model can scale efficiently to the increased demand. What should you do?
Answer: C
Explanation:
Vertex AI Endpoint is a service that allows you to serve your ML models online and scale them automatically. You can use Vertex AI Endpoint to deploy the custom ML model that you developed for recommending recipes to the users. You can maintain the same machine type on the endpoint, which is a single machine with 8 vCPUs and no accelerators. This machine type can optimize the costs by using the queries per second (QPS) that the model can serve. You can also configure the endpoint to enable autoscaling based on vCPU usage. Autoscaling is a feature that allows the endpoint to adjust the number of compute nodes based on the traffic demand. By enabling autoscaling based on vCPU usage, you can ensure that the endpoint can scale efficiently to the increased demand during the holiday season, without overprovisioning or underprovisioning the resources. You can also set up a monitoring job and an alert for CPU usage. Monitoring is a service that allows you to collect and analyze the metrics and logs from your Google Cloud resources.
You can use Monitoring to monitor the CPU usage of your endpoint, which is an indicator of the load and performance of your model. You can also set up an alert for CPU usage, which is a feature that allows you to receive notifications when the CPU usage exceeds a certain threshold. By setting up a monitoring job and an alert for CPU usage, you can keep track of the health and status of your endpoint, and detect any issues or anomalies. If you receive an alert, you can investigate the cause by using the Monitoring dashboard, which provides a graphical interface for viewing and analyzing the metrics and logs from your endpoint. You can also use the Monitoring dashboard to troubleshoot and resolve the issues, such as adjusting the autoscaling parameters, optimizing the model, or updating the machine type. By using Vertex AI Endpoint, autoscaling, and Monitoring, you can ensure that the model can scale efficiently to the increased demand during the holiday season, and handle any issues or alerts that might arise. References:
* [Vertex AI Endpoint documentation]
* [Autoscaling documentation]
* [Monitoring documentation]
* [Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate]
NEW QUESTION # 285
You are developing a model to identify traffic signs in images extracted from videos taken from the dashboard of a vehicle. You have a dataset of 100 000 images that were cropped to show one out of ten different traffic signs. The images have been labeled accordingly for model training and are stored in a Cloud Storage bucket You need to be able to tune the model during each training run. How should you train the model?
Answer: C
Explanation:
Image classification is a task where the model assigns a label to an image based on its content, such as "stop sign" or "speed limit"1. Object detection is a task where the model locates and identifies multiple objects in an image, and draws bounding boxes around them2. Since your dataset consists of images that were cropped to show one out of ten different traffic signs, you are dealing with an image classification problem, not an object detection problem. Therefore, you need to train a model for image classification, not object detection.
Vertex AI AutoML is a service that allows you to train and deploy high-quality ML models with minimal effort and machine learning expertise3. You can use Vertex AI AutoML to train a model for image classification by uploading your images and labels to a Vertex AI dataset, and then launching an AutoML training job4. However, Vertex AI AutoML does not allow you to tune the model during each training run, as it automatically selects the best model architecture and hyperparameters for your data4.
Vertex AI custom training is a service that allows you to train and deploy your own custom ML models using your own code and frameworks5. You can use Vertex AI custom training to train a model for image classification by writing your own model training code, such as using TensorFlow or PyTorch, and then creating and running a custom training job. Vertex AI custom training allows you to tune the model during each training run, as you can specify the model architecture and hyperparameters in your code, and use Vertex AI Hyperparameter Tuning to optimize them .
Therefore, the best option for your scenario is to develop the model training code for image classification and train a model by using Vertex AI custom training.
References:
* Image classification | TensorFlow Core
* Object detection | TensorFlow Core
* Introduction to Vertex AI AutoML | Google Cloud
* AutoML Vision | Google Cloud
* Introduction to Vertex AI custom training | Google Cloud
* [Custom training with TensorFlow | Vertex AI | Google Cloud]
* [Hyperparameter tuning overview | Vertex AI | Google Cloud]
NEW QUESTION # 286
......
Test Professional-Machine-Learning-Engineer Vce Free: https://www.pass4training.com/Professional-Machine-Learning-Engineer-pass-exam-training.html
2026 Latest Pass4training Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=1cr1Pmtc9FR5IbE2CVNZ_fNOooKLPE-Tp