If you really want to pass the real test and get the Microsoft certification? At first, you should be full knowledgeable and familiar with the AI-500 certification. Even if you have acquired the knowledge about the AI-500 actual test, the worries still exist. You do not know what questions you may be faced with when attending the real test. Now, you need the AI-500 practice dumps which can simulate the actual test to help you. Our AI-500 training dumps can ensure you pass at first attempt.
| Section | Weight | Objectives |
|---|---|---|
| Develop multi-agent solutions in Azure | 30-35% | - Design and implement advanced prompt engineering strategies
|
| Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security
|
| Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Evaluate solution quality
|
| Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
>> Microsoft AI-500 Latest Test Camp <<
If you are craving for getting promotion in your company, you must master some special skills which no one can surpass you. To suit your demands, our company has launched the Microsoft AI-500 exam materials especially for office workers. For on one hand, they are busy with their work, they have to get the Microsoft AI-500 Certification by the little spread time.
NEW QUESTION # 12
You have a LangGraph multi-agent workflow that uses Azure Cosmos DB as a checkpointer.
You plan to change the pruning rules for the running message list before the next release You need to implement evaluations tor memory. The solution must meet the following requirements:
* Verify that claim-related state values remain correct at transition points.
* Verify that conversation context is preserved after an interruption.
* Identify the source of any loss of continuity during a run
Which three actions should you perform Each correct answer presents part of the solution NOTE: Each correct selection is worth one point.
Answer: C,D,F
Explanation:
Memory evaluation must verify persistence across interruption, correctness of checkpointed state, and enough telemetry to locate where continuity was lost. Running a scripted multi-turn case with one stable `thread_id` before and after a restart directly tests whether the Cosmos-backed LangGraph checkpointer restores the same conversation/workflow. Comparing persisted checkpoint documents with expected state values at each handoff verifies that claim-related state has not been corrupted by the new pruning rules. Correlating the evaluation run with trace spans then provides the diagnostic path to identify which agent transition or state- management operation caused a failure. Changing the thread ID each turn would intentionally create separate state scopes, and removing durable artifacts would defeat the persistence test. Tool-call arguments alone do not prove workflow-memory continuity. Therefore D, E, and F are the complementary actions required. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Azure Cosmos DB integrations for LangGraph and agent state
NEW QUESTION # 13
You have a Microsoft Agent Framework workflow processor that receives customer support requests from a queue. Each request is evaluated by three independent Microsoft Foundry agents.
You discover that the current processor dequeues 30 requests at a time and starts all agent runs immediately.
During peak load, as many as 90 agent runs execute simultaneously, and the downstream API receives partial participant messages.
A single agent run completes in five seconds at the 95th percentile (95p), and the target throughput is 120 requests per minute.
You need to change the orchestration to ensure that it meets the throughput target and prevents more than 30 agent runs from executing simultaneously. The solution must produce one consolidated downstream payload for each request.
What should you do?
Answer: A
Explanation:
Each customer request requires three independent agent runs. Dequeuing ten requests and launching a concurrent three-agent workflow for each request creates at most 30 simultaneous agent runs, exactly meeting the concurrency ceiling. Because the three agents execute in parallel and one run takes about five seconds at the 95th percentile, ten requests can complete in roughly five seconds, which corresponds to 120 requests per minute. Microsoft Agent Framework ' s ConcurrentBuilder performs a fan-out to independent participants and a fan-in that can produce one consolidated response, solving the downstream partial-message problem.
Sequential workflows would require roughly three agent durations per request and miss the throughput target.
A 90-participant workflow violates the concurrency limit. Therefore C is the only option that satisfies the numerical and orchestration constraints together. The implementation should also preserve clear inputs and outputs around this step so that later agents receive only the information they require. This improves debuggability and keeps token, permission, and state growth under control as the workflow becomes more complex.
Official Microsoft reference: Microsoft Agent Framework - Concurrent orchestration
NEW QUESTION # 14
You have a multi-agent Retrieval-Augmented Generation (RAG) solution that uses a Foundry IQ knowledge base. The solution includes a support agent and a policy agent.
You have an evaluation dataset that contains the following for each user query
* The expected source IDs
* Retrieved chunks in rank order
* The final agent response
You discover that an embedding model change and a custom analyzer change cause the failed traces shown in the following table.
You need to isolate the failing parts of the RAG pipeline.
Which evaluator should you use for each agent? To answer, drag the appropriate evaluators to the correct agents. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Support agent: Document Retrieval; Policy agent: Document Retrieval.
Both failures are retrieval failures and should therefore be diagnosed with the Document Retrieval evaluator.
The dataset includes expected source IDs and ranked retrieved chunks, which provides the retrieval ground truth required by that evaluator. For the support agent, the expected source appears too low in the ranking after unrelated chunks. For the policy agent, the required exception-table source is missing entirely.
Groundedness would evaluate whether the final response is supported by the context it actually received; it could therefore pass even when the retrieval stage failed to fetch a required source. Microsoft Foundry ' s Document Retrieval evaluator compares retrieved documents against labeled ground truth and reports ranking
/search metrics such as NDCG and Fidelity. The corrected answer is Document Retrieval for both agents. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
NEW QUESTION # 15
You are designing Microsoft Foundry multi-agent solution. The agents will use Agent-to-Agent (A2A) delegation and access separate Azure Storage containers within a resource group named RG1.
You need to recommend identity components for the design. The solution must meet the following requirements:
* Eliminate stored application secrets.
* Limit the impact of a compromised agent or deployment.
Solution: Use delegated user permissions for agent actions. Assign Azure roles by using a shared security group. Does this meet the goal?
Answer: A
Explanation:
The proposed solution uses delegated user permissions for agent actions and assigns Azure roles through one shared security group. Even if it avoids storing an application secret, it does not create strong per-agent authorization boundaries. Sharing downstream permissions through one group can allow a compromised agent to inherit access intended for other agents, which conflicts with the requirement to limit blast radius.
Microsoft Foundry identity guidance recommends distinct logical agent/workload identities and narrowly scoped role assignments when agents have different resource responsibilities or audit requirements. Delegated user access is appropriate when an operation genuinely needs the signed-in user ' s authorization context, not as a general service-to-service isolation model for autonomous A2A workers. Therefore the proposed design does not meet both goals, and B, No, remains correct. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry agent identity
NEW QUESTION # 16
You have a Microsoft Foundry ticket-triage solution that uses connected agents. Each subagent prompt includes instructions for allowed tools and a JSON handoff.
You need to add automated prompt evaluations. The solution must identify changes that cause the subagents to do the following:
* Skip mandated evidence gathering.
* Return payloads that downstream agents cannot process.
* Handle work outside their assigned responsibilities.
How should you configure the evaluation suite? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.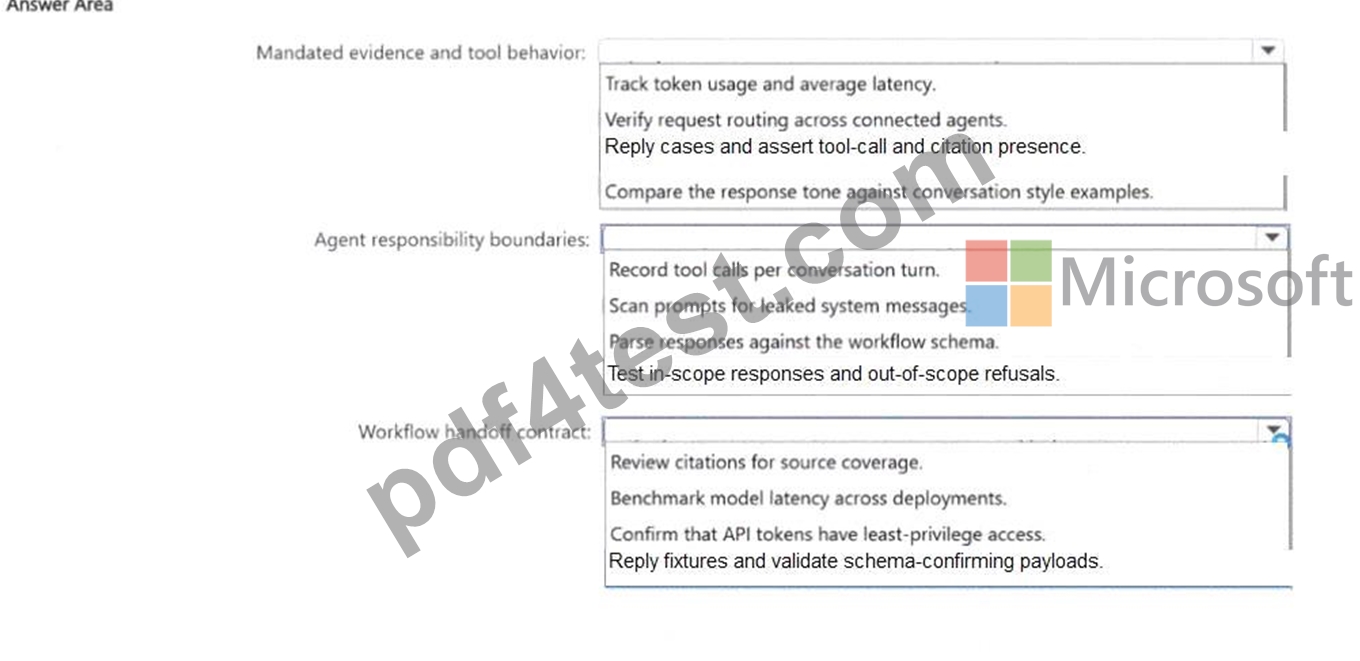
Answer:
Explanation: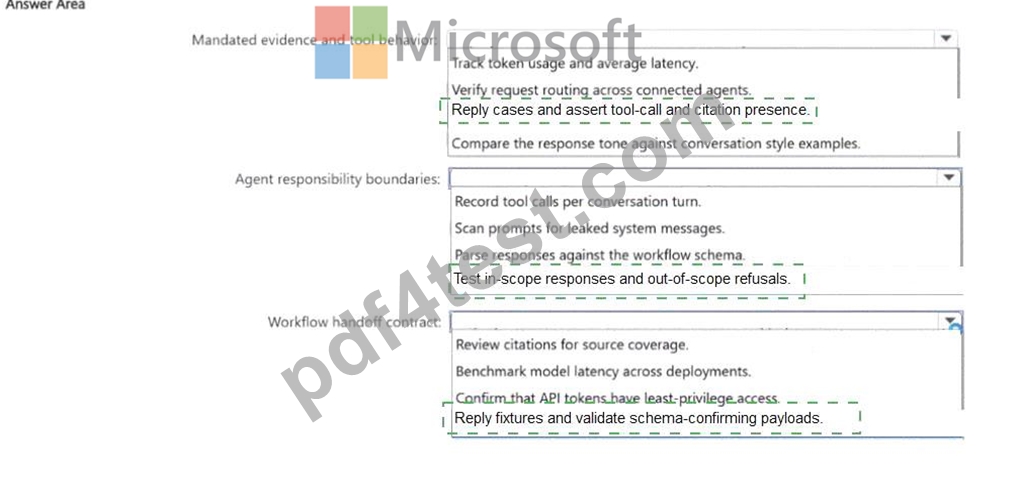
Explanation:
Mandated evidence/tool behavior: Replay cases and assert tool-call and citation presence; Agent responsibility boundaries: Test in-scope responses and out-of-scope refusals; Workflow handoff contract: Replay fixtures and validate schema-conforming payloads.
The three regressions target different interfaces and should be evaluated with tests that directly observe those interfaces. Required evidence gathering is a process behavior, so replayed cases should assert that mandated tool calls and citations occur. Responsibility boundaries are best tested with both positive and negative prompts: in-scope cases must be handled, while out-of-scope work should be refused or redirected. The JSON handoff is an interface contract, so replay fixtures should be validated against the expected schema to catch missing fields, renamed properties, and type changes before downstream agents fail. Microsoft Foundry ' s agent evaluators and evaluation datasets support process-level tool checks, task-adherence checks, and structured regression testing. The supplied mappings therefore correctly align each evaluation technique with the failure it is intended to detect. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - built-in evaluators and evaluation datasets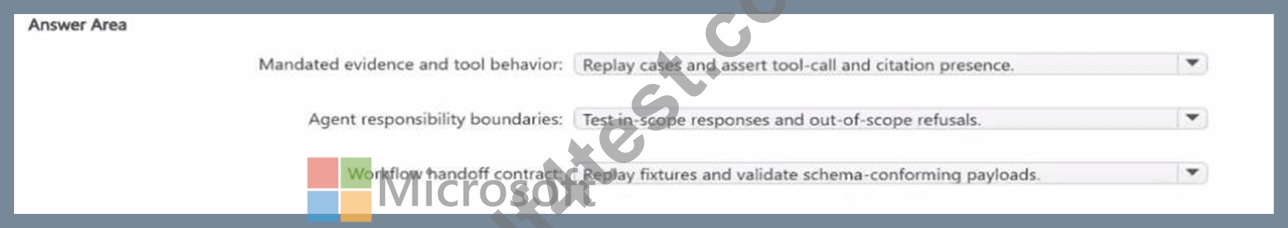
NEW QUESTION # 17
......
In order to better meet users' needs, our AI-500 study materials have set up a complete set of service system, so that users can enjoy our professional one-stop service. We not only in the pre-sale for users provide free demo, when buy the user can choose in we provide in the three versions, at the same time, our AI-500 Study Materials also provides 24-hour after-sales service, even if you are failing the exam, don't pass the exam, the user may also demand a full refund with purchase vouchers, make the best use of the test data, not for the user to increase the economic burden.
AI-500 Valid Test Bootcamp: https://www.pdf4test.com/AI-500-dump-torrent.html