After decades of hard work, our products are currently in a leading position in the same kind of education market, our DP-800 learning materials, with their excellent quality and constantly improved operating system, In many areas won the unanimous endorsement of many international customers. Advanced operating systems enable users to quickly log in and use, in constant practice and theoretical research, our DP-800 learning materials have come up with more efficient operating system to meet user needs, so we can assure users here , after user payment , users can perform a review of the DP-800 Exam in real time , because our advanced operating system will immediately send users DP-800 learning material to the email address where they are paying , this greatly facilitates the user, lets the user be able to save more study time.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
Why we are ahead of the other sites in the IT training industry? Because the information we provide have a wider coverage, higher quality, and the accuracy is also higher. So VCE4Plus is not only the best choice for you to participate in the Microsoft Certification DP-800 Exam, but also the best protection for your success.
NEW QUESTION # 85
You have a SQL database in Microsoft Fabric that contains a column named Payload. Payload stores customer data in JSON documents that have the following format:
JSON
{
" date " : " 2026-01-25 " ,
" customer_email " : " user@contoso.com " ,
...
}
Data analysis shows that some customers have subaddressing in their email address; for example, user1+promo@contoso.com.
You need to return a normalized email value that removes the subaddressing, for example, user1+promo@contoso.com must be normalized to user1@contoso.com.
Which Transact-SQL expression should you use?
Answer: B
NEW QUESTION # 86
You need to generate embeddings to resolve the issues identified by the analysts. Which column should you use?
Answer: B
Explanation:
The correct column to use for generating embeddings is incidentDescrlption because embeddings are intended to represent the semantic meaning of rich textual content , not simple categorical, numeric, or location-only values. Microsoft's DP-800 study guide explicitly includes skills such as identifying which columns to include in embeddings , generating embeddings , and implementing semantic vector search for scenarios where users need to find similar records based on meaning rather than exact matches.
In this scenario, analysts report that it is difficult to find similar incidents based on details such as weather, traffic conditions, and location . Those are descriptive context elements that are typically captured in a free- text incident description field. An embedding generated from incidentDescrlption can encode the semantic relationships among these narrative details, making it suitable for similarity search , semantic search , and RAG retrieval . Microsoft documentation on vectors and embeddings explains that embeddings are generated from text data and then stored for vector search to find semantically related items.
The other options are weaker choices:
* vehicleLocation is too narrow and usually better handled with geospatial filtering , not embeddings.
* incidentType is likely categorical and too low in semantic richness.
* SeverityScore is numeric and not appropriate as the primary source for semantic embeddings.
Microsoft also notes that when multiple useful attributes exist, you can either embed each text column separately or concatenate relevant text fields into one textual representation before generating the embedding.
But among the options given, the best and most exam-aligned answer is the textual narrative column :
incidentDescrlption .
NEW QUESTION # 87
You have an Azure SQL database that contains a table named dbo.Orders.
You have an application that calls a stored procedure named dbo.usp_tresteOrder to insert rows into dbo.
Orders.
When an insert fails, the application receives inconsistent error details.
You need to implement error handling to ensure that any failures inside the procedure abort the transaction and return a consistent error to the caller.
How should you complete the stored procedure? To answer, drag the appropriate values to the correct targets, tach value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
* After the INSERT # SET @OrderId = SCOPE_IDENTITY()
* Inside CATCH # IF @@TRANCOUNT > 0 ROLLBACK TRANSACTION
The correct drag-and-drop choices are:
* SET @OrderId = SCOPE_IDENTITY()
* IF @@TRANCOUNT > 0 ROLLBACK TRANSACTION
After the INSERT, the procedure should assign the newly generated identity value to the output parameter by using SCOPE_IDENTITY() . Microsoft documents that SCOPE_IDENTITY() returns the last identity value inserted in the same scope, which makes it the correct choice for returning the new OrderId from the procedure.
Inside the CATCH block, the procedure should use IF @@TRANCOUNT > 0 ROLLBACK TRANSACTION before THROW. This ensures any open transaction is rolled back only when one actually exists, which prevents transaction-state issues and guarantees the failure aborts the transaction cleanly.
Keeping THROW after the rollback is also the correct modern pattern because THROW re-raises the error to the caller with the original error information intact, giving consistent error behavior. This matches SQL Server best practice for TRY...CATCH transaction handling.
NEW QUESTION # 88
Case Study 1 - Contoso
Existing Environment
Azure Environment
Contoso has an Azure subscription in North Europe that contains the corporate infrastructure.
The current infrastructure contains a Microsoft SQL Server 2017 database. The database contains the following tables.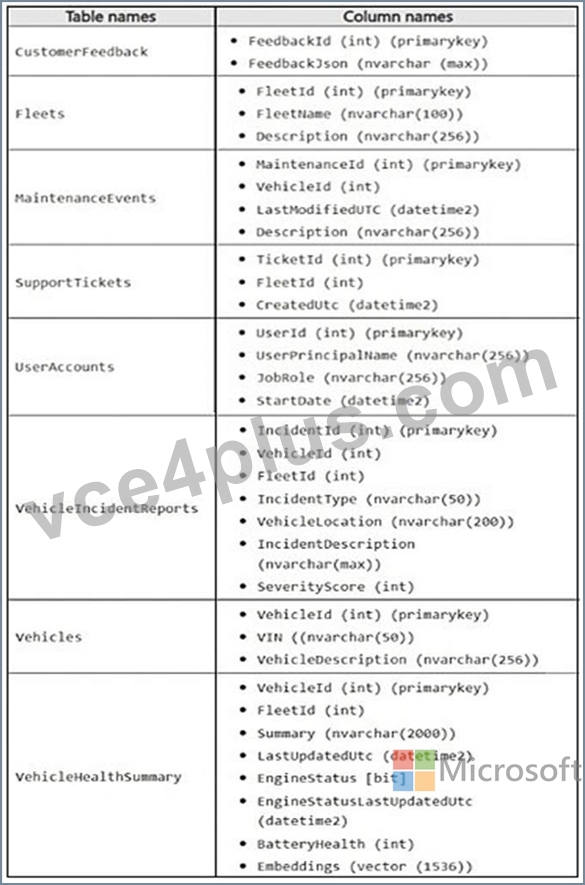
The FeedbackJsoncolumn has a full-text index and stores JSON documents in the following format.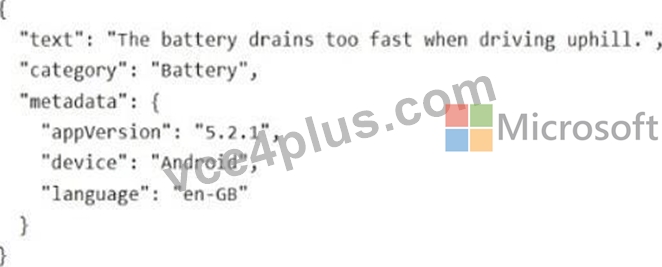
The support staff at Contoso never has the UNMASKpermission.
Problem Statements
Contoso is deploying a new Azure SQL database that will become the authoritative data store for the following:
* AI workloads
* Vector search
* Modernized API access
* Retrieval Augmented Generation (RAG) pipelines
Sometimes the ingestion pipeline fails due to malformed JSON and duplicate payloads.
The engineers at Contoso report that the following dashboard query runs slowly.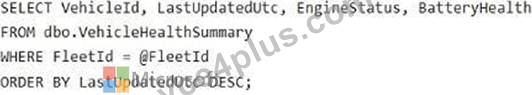
You review the execution plan and discover that the plan shows a clustered index scan.
VehicleIncidentReportsoften contains details about the weather, traffic conditions, and location. Analysts report that it is difficult to find similar incidents based on these details.
Requirements
Planned Changes
Contoso wants to modernize Fleet Intelligence Platform to support AI-powered semantic search over incident reports.
Security Requirements
Contoso identifies the following security requirements:
* Restrict the support staff from viewing Personally Identifiable Information (PII) data, which is full email addresses and phone numbers.
* Enforce row-level filtering so that analysts see only incidents for the fleets to which they are assigned. The analysts can be assigned to multiple fleets.
Database Performance and Requirements
Contoso identifies the following telemetry requirements:
* Telemetry data must be stored in a partitioned table.
* Telemetry data must provide predictable performance for ingestion and retention operations.
* latitude, longitude, and accuracyJSON properties must be filtered by using an index seek.
Contoso identifies the following maintenance data requirements:
* Ensure that any changes to a row in the MaintenanceEventstable updates the corresponding value in the LastModifiedUtccolumn to the time of the change.
* Avoid recursive updates.
AI Search, Embeddings, and Vector Indexing
Contoso plans to implement semantic search over incident data to meet the following requirements:
* Embeddings must be stored in dedicated Azure SQL Database tables.
* Embeddings must be generated from rich natural language fields.
* Chunking must preserve semantic coherence.
* Hybrid search must combine the following:
- Vector similarity
- Keyword filtering or boosting
Development Requirements
The development team at Contoso will use Microsoft Visual Studio Code and GitHub Copilot and will retrieve live metadata from the databases.
Contoso identifies the following requirements for querying data in the FeedbackJsoncolumn of the CustomerFeedbacktable:
* Extract the customer feedback text from the JSON document.
* Filter rows where the JSON text contains a keyword.
* Calculate a fuzzy similarity score between the feedback text and a known issue description.
* Order the results by similarity score, with the highest score first.
Hotspot Question
You need to meet the development requirements for the FeedbackJson column.
How should you complete the Transact-SQL query? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: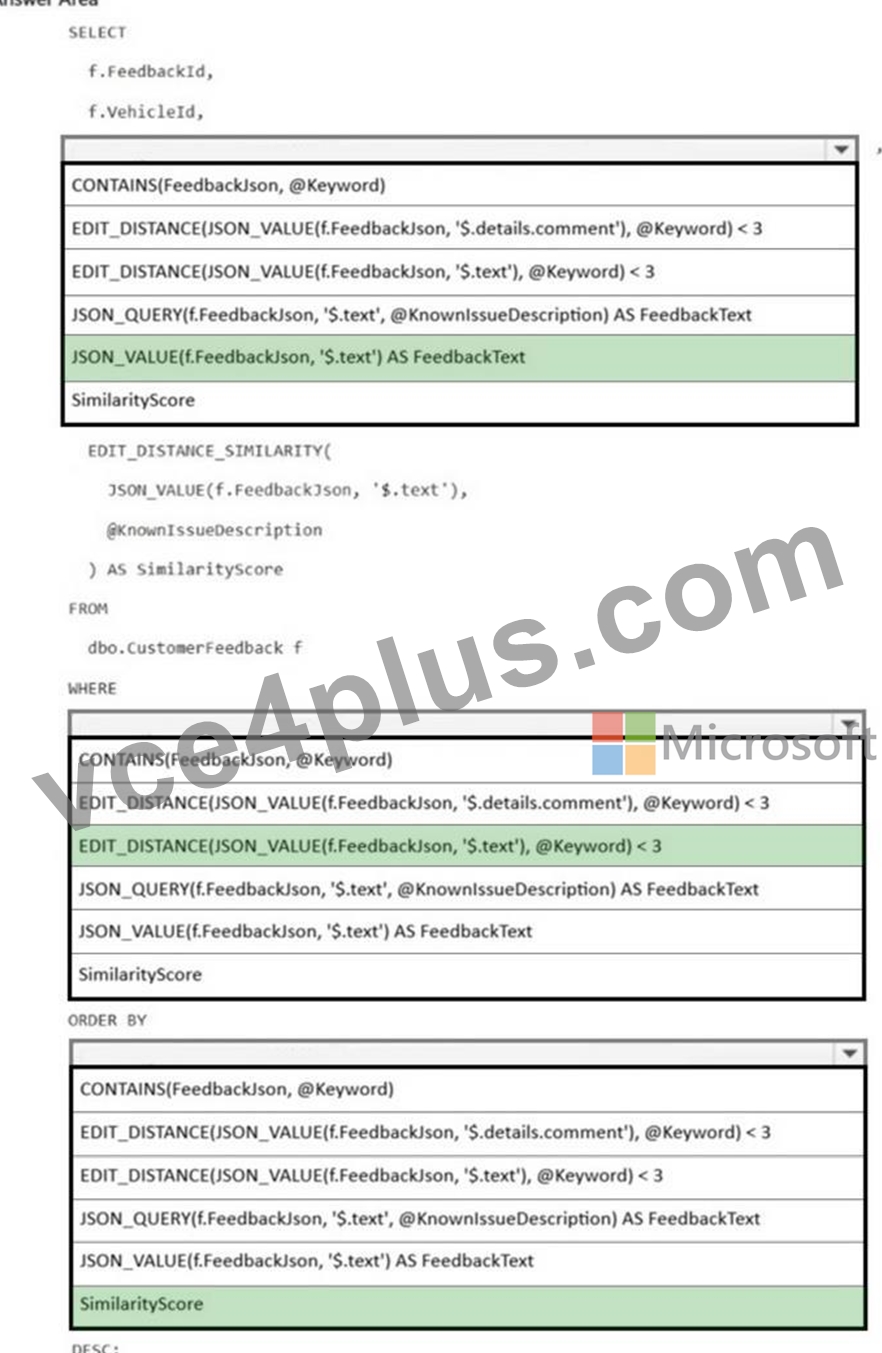
NEW QUESTION # 89
You have an Azure SQL database that contains tables named dbo.Tickets and dbo.TicketNotes.
dbo.Tickets contains support tickets and dbo.TicketNotes contains ticket notes.
A retrieval query returns the top five relevant ticket notes for a user question.
You plan to implement a Retrieval Augmented Generation (RAG) pattern that meets the following requirements:
- Formats the retrieved relational data for large language model (LLM)
processing
- Sends the user question and retrieved context to an Azure OpenAI REST endpoint for chat completions
- Extracts the response text from the LLM response
Which Transact-SQL function should you use to extract the response text?
Answer: B
Explanation:
The Transact-SQL function used to extract the response text from the Azure OpenAI REST endpoint is JSON_VALUE.
When you call the Azure OpenAI REST endpoint using sp_invoke_external_rest_endpoint, the response is returned as a JSON string. To isolate the actual text content from the LLM, you must parse this JSON structure.
Function: JSON_VALUE(response_body, '$.choices[0].message.content')
Purpose: It extracts a scalar (text) value from a JSON string.
Path: In the OpenAI schema, the generated response is always located at
$.choices[0].message.content.
Reference:
https://pub.towardsai.net/mastering-retrieval-augmented-generation-from-zero-to-expert-in-rag- for-quickly-building-a-08141a308836
NEW QUESTION # 90
......
The DP-800 exam questions formats are PDF dumps files, desktop practice test software, and web-based practice test software. All these DP-800exam questions format hold some common and unique features. Such as DP-800 PDF dumps file is the PDF version of Developing AI-Enabled Database Solutions exam dumps that works VCE4Plus all operating systems and devices. Whereas the other two DP-800 Practice Test questions formats are concerned, both are the mock DP-800 exam. Both will give you a real-time Developing AI-Enabled Database Solutions exam preparation environment and you get experience to attempt the DP-800 exam preparation experience before the final exam.
Exam DP-800 Questions Fee: https://www.vce4plus.com/Microsoft/DP-800-valid-vce-dumps.html