Certified-Data-Engineer-Professional Reliable Study Questions, Valid Test Certified-Data-Engineer-Professional Experience

Our passing rate of Certified-Data-Engineer-Professional learning quiz is 99% and our Certified-Data-Engineer-Professional practice guide boosts high hit rate. Our Certified-Data-Engineer-Professional test torrents are compiled by professionals and the answers and the questions we provide are based on the real exam. The content of our Certified-Data-Engineer-Professional exam questions is simple to be understood and mastered. To let you get well preparation for the exam, our software provides the function to stimulate the real exam and the timing function to help you adjust the speed. Based on those merits of our Certified-Data-Engineer-Professional Guide Torrent you can pass the Certified-Data-Engineer-Professional exam with high possibility.
| Section | Objectives |
|---|
| Topic 1: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 2: Data Modeling | - Design and optimize data models
- 1. Design and implement scalable data models using Delta Lake to manage large datasets
- 2. Design dimensional models for analytical workloads with efficient querying and aggregation
- 3. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 4. Simplify data layout decisions and optimize query performance using liquid clustering
|
| Topic 3: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Topic 4: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 5. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 6. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 7. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 8. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
| Topic 5: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 6: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Topic 7: Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand Delta optimization techniques such as deletion vectors and liquid clustering
|
| Topic 8: Data Governance | - Govern enterprise data
- 1. Create and add descriptions and metadata to enterprise data to improve discoverability
- 2. Demonstrate understanding of the Unity Catalog permission inheritance model
|
| Topic 9: Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 4. Use system tables for observability of resource utilization, cost, auditing, and workloads
|
| Topic 10: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
>> Certified-Data-Engineer-Professional Reliable Study Questions <<
Certified-Data-Engineer-Professional EXAM DUMPS WITH GUARANTEED SUCCESS
Experts before starting the compilation of " the Certified-Data-Engineer-Professional latest questions ", has put all the contents of the knowledge point build a clear framework in mind, though it needs a long wait, but product experts and not give up, but always adhere to the effort, in the end, they finished all the compilation. So, you're lucky enough to meet our Certified-Data-Engineer-Professional Test Guide l, and it's all the work of the experts. If you want to pass the qualifying Certified-Data-Engineer-Professional exam with high quality, choose our Certified-Data-Engineer-Professional exam questions. We are absolutely responsible for you. Don't hesitate!
Databricks Certified Data Engineer Professional Sample Questions (Q225-Q230):
NEW QUESTION # 225
The marketing team is looking to share data in an aggregate table with the sales organization, but the field names used by the teams do not match, and a number of marketing specific fields have not been approval for the sales org.
Which of the following solutions addresses the situation while emphasizing simplicity?
- A. Instruct the marketing team to download results as a CSV and email them to the sales organization.
- B. Create a new table with the required schema and use Delta Lake's DEEP CLONE functionality to sync up changes committed to one table to the corresponding table.
- C. Create a view on the marketing table selecting only these fields approved for the sales team alias the names of any fields that should be standardized to the sales naming conventions.
- D. Add a parallel table write to the current production pipeline, updating a new sales table that varies as required from marketing table.
- E. Use a CTAS statement to create a derivative table from the marketing table configure a production jon to propagation changes.
Answer: C
Explanation:
Creating a view is a straightforward solution that can address the need for field name standardization and selective field sharing between departments. A view allows for presenting a transformed version of the underlying data without duplicating it. In this scenario, the view would only include the approved fields for the sales team and rename any fields as per their naming conventions.
NEW QUESTION # 226
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement ?the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
What code will satisfy the requirements?
- A. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading < 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - B. @dlt.table
@dlt.expect("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - C. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings") - D. @dlt.table
@dlt.expect_or_drop("valid_sensor_reading", "reading < 120")
def silver_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
@dlt.table
@dlt.expect_or_drop("invalid_sensor_reading", "reading >= 120")
def quarantine_sensor_readings():
return spark.readStream.table("bronze_sensor_readings")
Answer: B
Explanation:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect,
@dlt.expect_or_drop, and @dlt.expect_all.
@dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows. Instead, failing rows can be written to a quarantine table.
@dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
Good rows (reading < 120) go to the silver table.
Bad rows (reading >= 120) go to a quarantine table.
Bad rows should not be included in silver.
The correct implementation is Option A, where:
The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
The quarantine table applies an expectation for reading >= 120, ensuring bad records are captured separately.
Other options are incorrect:
Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
NEW QUESTION # 227
A data engineer is configuring a pipeline that will potentially see late-arriving, duplicate records.
In addition to de-duplicating records within the batch, which of the following approaches allows the data engineer to deduplicate data against previously processed records as it is inserted into a Delta table?
- A. Rely on Delta Lake schema enforcement to prevent duplicate records.
- B. VACUUM the Delta table after each batch completes.
- C. Perform a full outer join on a unique key and overwrite existing data.
- D. Set the configuration delta.deduplicate = true.
- E. Perform an insert-only merge with a matching condition on a unique key.
Answer: E
Explanation:
To deduplicate data against previously processed records as it is inserted into a Delta table, you can use the merge operation with an insert-only clause. This allows you to insert new records that do not match any existing records based on a unique key, while ignoring duplicate records that match existing records. For example, you can use the following syntax:
MERGE INTO target_table USING source_table ON target_table.unique_key = source_table.unique_key WHEN NOT MATCHED THEN INSERT * This will insert only the records from the source table that have a unique key that is not present in the target table, and skip the records that have a matching key. This way, you can avoid inserting duplicate records into the Delta table.
NEW QUESTION # 228
A Delta Lake table in the Lakehouse named customer_parsams is used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
Immediately after each update succeeds, the data engineer team would like to determine the difference between the new version and the previous of the table. Given the current implementation, which method can be used?
- A. Parse the Spark event logs to identify those rows that were updated, inserted, or deleted.
- B. Execute a query to calculate the difference between the new version and the previous version using Delta Lake's built-in versioning and time travel functionality.
- C. Parse the Delta Lake transaction log to identify all newly written data files.
- D. Execute DESCRIBE HISTORY customer_churn_params to obtain the full operation metrics for the update, including a log of all records that have been added or modified.
Answer: B
Explanation:
Delta Lake provides built-in versioning and time travel capabilities, allowing users to query previous snapshots of a table. This feature is particularly useful for understanding changes between different versions of the table. In this scenario, where the table is overwritten nightly, you can use Delta Lake's time travel feature to execute a query comparing the latest version of the table (the current state) with its previous version. This approach effectively identifies the differences (such as new, updated, or deleted records) between the two versions. The other options do not provide a straightforward or efficient way to directly compare different versions of a Delta Lake table.
NEW QUESTION # 229
The data engineering team maintains the following code:
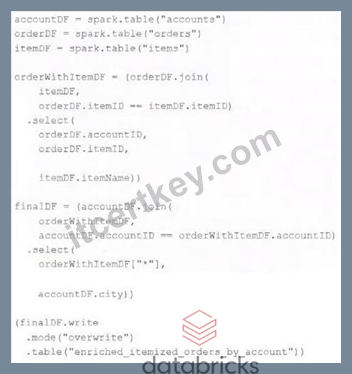
Assuming that this code produces logically correct results and the data in the source tables has been de-duplicated and validated, which statement describes what will occur when this code is executed?
- A. A batch job will update the enriched_itemized_orders_by_account table, replacing only those rows that have different values than the current version of the table, using accountID as the primary key.
- B. An incremental job will leverage information in the state store to identify unjoined rows in the source tables and write these rows to the enriched_iteinized_orders_by_account table.
- C. The enriched_itemized_orders_by_account table will be overwritten using the current valid version of data in each of the three tables referenced in the join logic.
- D. An incremental job will detect if new rows have been written to any of the source tables; if new rows are detected, all results will be recalculated and used to overwrite the enriched_itemized_orders_by_account table.
- E. No computation will occur until enriched_itemized_orders_by_account is queried; upon query materialization, results will be calculated using the current valid version of data in each of the three tables referenced in the join logic.
Answer: C
Explanation:
This is the correct answer because it describes what will occur when this code is executed. The code uses three Delta Lake tables as input sources: accounts, orders, and order_items. These tables are joined together using SQL queries to create a view called new_enriched_itemized_orders_by_account, which contains information about each order item and its associated account details. Then, the code uses write.format("delta").mode("overwrite") to overwrite a target table called enriched_itemized_orders_by_account using the data from the view. This means that every time this code is executed, it will replace all existing data in the target table with new data based on the current valid version of data in each of the three input tables.
NEW QUESTION # 230
......
Each of the Itcertkey Databricks Certified-Data-Engineer-Professional exam dumps formats excels in its way and carries actual Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) exam questions for optimal preparation. All of these Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) practice question formats are easy to use and extremely convenient such that even newbies find them simple.
Valid Test Certified-Data-Engineer-Professional Experience: https://www.itcertkey.com/Certified-Data-Engineer-Professional_braindumps.html
- Exam Certified-Data-Engineer-Professional Assessment 🤫 Exam Certified-Data-Engineer-Professional Assessment 🔒 Valid Certified-Data-Engineer-Professional Torrent 🍬 Search on ➽ www.dumpsmaterials.com 🢪 for “ Certified-Data-Engineer-Professional ” to obtain exam materials for free download 🛷Certified-Data-Engineer-Professional Dump Collection
- Exam Certified-Data-Engineer-Professional Assessment 📗 Certified-Data-Engineer-Professional Dump Collection 🕥 Test Certified-Data-Engineer-Professional Question 🎨 Easily obtain free download of ➤ Certified-Data-Engineer-Professional ⮘ by searching on 「 www.pdfvce.com 」 🚥Latest Certified-Data-Engineer-Professional Braindumps Files
- Valid Certified-Data-Engineer-Professional Mock Test 😠 Certified-Data-Engineer-Professional Pass Test 🥨 Latest Certified-Data-Engineer-Professional Exam Questions 😚 Immediately open ➽ www.vce4dumps.com 🢪 and search for ☀ Certified-Data-Engineer-Professional ️☀️ to obtain a free download 🚟Latest Certified-Data-Engineer-Professional Exam Questions
- Certified-Data-Engineer-Professional New Braindumps Pdf 🧞 Reliable Certified-Data-Engineer-Professional Exam Registration 🏧 Valid Certified-Data-Engineer-Professional Mock Test 🤦 Easily obtain free download of ▶ Certified-Data-Engineer-Professional ◀ by searching on ➽ www.pdfvce.com 🢪 ☃Valid Certified-Data-Engineer-Professional Mock Test
- Certified-Data-Engineer-Professional Reliable Study Questions | Amazing Pass Rate For Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional | Valid Test Certified-Data-Engineer-Professional Experience 🥂 Search for ⏩ Certified-Data-Engineer-Professional ⏪ on “ www.troytecdumps.com ” immediately to obtain a free download 🧨Reliable Certified-Data-Engineer-Professional Exam Registration
- Databricks Certified-Data-Engineer-Professional Exam | Certified-Data-Engineer-Professional Reliable Study Questions - Reliable Planform of Valid Test Certified-Data-Engineer-Professional Experience 🐞 Easily obtain free download of { Certified-Data-Engineer-Professional } by searching on ▷ www.pdfvce.com ◁ 🕠Latest Certified-Data-Engineer-Professional Braindumps Files
- Test Certified-Data-Engineer-Professional Question 📎 Certified-Data-Engineer-Professional Training Courses 📑 Exam Certified-Data-Engineer-Professional Assessment 😝 Enter ➥ www.examcollectionpass.com 🡄 and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free 🐱Test Certified-Data-Engineer-Professional Valid
- Valid Certified-Data-Engineer-Professional Torrent 😮 Latest Certified-Data-Engineer-Professional Braindumps Files 🧘 Certified-Data-Engineer-Professional Pass Test 🛌 Search for 「 Certified-Data-Engineer-Professional 」 and download it for free immediately on ➤ www.pdfvce.com ⮘ 🤽Certified-Data-Engineer-Professional Dump Collection
- New Certified-Data-Engineer-Professional Mock Exam 🥔 Certified-Data-Engineer-Professional New Practice Materials ↕ Certified-Data-Engineer-Professional Pass Test 😮 Easily obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download through 【 www.dumpsmaterials.com 】 🚰Certified-Data-Engineer-Professional Pass Test
- Databricks Certified-Data-Engineer-Professional Exam | Certified-Data-Engineer-Professional Reliable Study Questions - Reliable Planform of Valid Test Certified-Data-Engineer-Professional Experience 🕦 Easily obtain 《 Certified-Data-Engineer-Professional 》 for free download through ➥ www.pdfvce.com 🡄 🟥Exam Certified-Data-Engineer-Professional Assessment
- Databricks Certified-Data-Engineer-Professional Exam PDF Dumps And Practice Test Software Is Ready For Download ‼ Search for ⏩ Certified-Data-Engineer-Professional ⏪ on 「 www.practicevce.com 」 immediately to obtain a free download 🥃Reliable Certified-Data-Engineer-Professional Exam Registration
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.4shared.com, connect.garmin.com, learn.csisafety.com.au, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes