2026 Latest Dumpleader Databricks-Certified-Professional-Data-Engineer PDF Dumps and Databricks-Certified-Professional-Data-Engineer Exam Engine Free Share: https://drive.google.com/open?id=11pfEZS88vSPOs1ut_qE-VB05B5CHH-1j
After clients pay successfully for our Databricks Certified Professional Data Engineer Exam guide torrent, they will receive our mails sent by our system in 5-10 minutes. Then they can dick the mail and log in to use our software to learn immediately. For that time is extremely important for the learners, everybody hope that they can get the efficient learning. So clients can use our Databricks-Certified-Professional-Data-Engineer test torrent immediately is the great merit of our product. We have set strict computer procedure to protect the client’s privacy about purchasing Databricks-Certified-Professional-Data-Engineer Study Tool and there is no one which can see the privacy information through online or other illegal channels except us. We have set the rigorous interception procedure to protect others from stealing the client’s personal privacy information.
| Section | Weight | Objectives |
|---|---|---|
| Debugging and Deploying | 10% | - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors - CI/CD and DevOps practices |
| Data Modelling | 6% | - Delta Lake table design - Schema design and management - Medallion Architecture implementation |
| Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Integration with Databricks APIs and tools - Batch and incremental processing logic |
| Monitoring and Alerting | 10% | - Setting up alerts and notifications - Performance and health monitoring - Pipeline observability and logging |
| Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Standardization and normalization - Data validation and quality checks |
| Ensuring Data Security and Compliance | 10% | - Data encryption and masking - Access control and permissions - Compliance standards implementation |
| Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Auto Loader and streaming ingestion - Connecting to diverse data sources |
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling - Query optimization and caching |
| Data Governance | 7% | - Unity Catalog management - Data lineage and metadata tracking - Policy enforcement |
| Data Sharing and Federation | 5% | - Cross-workspace and cross-cloud access - Unity Catalog data sharing |
>> Databricks-Certified-Professional-Data-Engineer Study Tool <<
Even if you have received a lot of services, you will still be surprised by the service of our Databricks-Certified-Professional-Data-Engineer simulating exam. Our company takes great care in every aspect from the selection of staff, training, and system setup. No matter what problems of the Databricks-Certified-Professional-Data-Engineer Practice Questions you encounter, our staff can solve them for you right away and give you the most professional guide. And our service can help you 24/7 on the the Databricks-Certified-Professional-Data-Engineer exam materials.
NEW QUESTION # 170
Why does AUTO LOADER require schema location?
Answer: B
Explanation:
Explanation
The answer is, Schema location is used to store schema inferred by AUTO LOADER, so the next time AUTO LOADER runs faster as does not need to infer the schema every single time by trying to use the last known schema.
Auto Loader samples the first 50 GB or 1000 files that it discovers, whichever limit is crossed first. To avoid incurring this inference cost at every stream start up, and to be able to provide a stable schema across stream restarts, you must set the option cloudFiles.schemaLocation. Auto Loader creates a hidden directory _schemas at this location to track schema changes to the input data over time.
The below link contains detailed documentation on different options
Auto Loader options | Databricks on AWS
NEW QUESTION # 171
How do you check the location of an existing schema in Delta Lake?
Answer: C
Explanation:
Explanation
Here is an example of how it looks
Graphical user interface, text, application, email Description automatically generated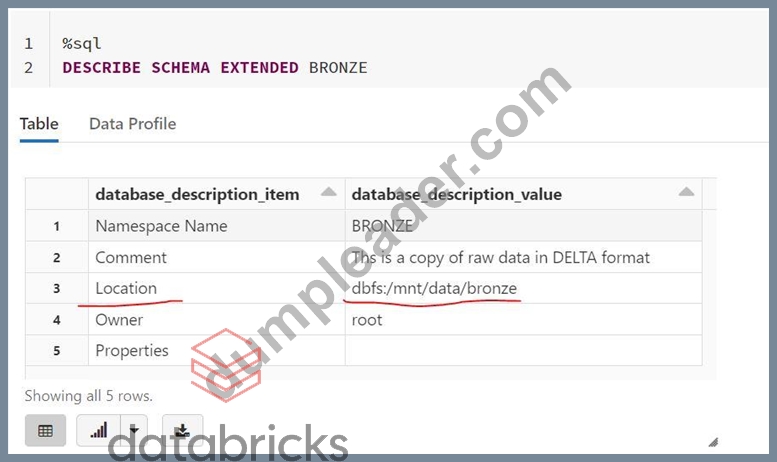
NEW QUESTION # 172
Which of the following statements describes Delta Lake?
Answer: A
Explanation:
Explanation
Delta Lake
NEW QUESTION # 173
To reduce storage and compute costs, the data engineering team has been tasked with curating a series of aggregate tables leveraged by business intelligence dashboards, customer-facing applications, production machine learning models, and ad hoc analytical queries.
The data engineering team has been made aware of new requirements from a customer-facing application, which is the only downstream workload they manage entirely. As a result, an aggregate tableused by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added.
Which of the solutions addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed?
Answer: A
Explanation:
This is the correct answer because it addresses the situation while minimally interrupting other teams in the organization without increasing the number of tables that need to be managed. The situation is that an aggregate table used by numerous teams across the organization will need to have a number of fields renamed, and additional fields will also be added, due to new requirements from a customer-facing application. By configuring a new table with all the requisite fields and new names and using this as the source for the customer-facing application, the data engineering team can meet the new requirements without affecting other teams that rely on the existing table schema and name. By creating a view that maintains the original data schema and table name by aliasing select fields from the new table, the data engineering team can also avoid duplicating data or creating additional tables that need to be managed. Verified References:
[Databricks Certified Data Engineer Professional], under "Lakehouse" section; Databricks Documentation, under "CREATE VIEW" section.
NEW QUESTION # 174
A table in the Lakehouse namedcustomer_churn_paramsis used in churn prediction by the machine learning team. The table contains information about customers derived from a number of upstream sources. Currently, the data engineering team populates this table nightly by overwriting the table with the current valid values derived from upstream data sources.
The churn prediction model used by the ML team is fairly stable in production. The team is only interested in making predictions on records that have changed in the past 24 hours.
Which approach would simplify the identification of these changed records?
Answer: B
Explanation:
Explanation
The approach that would simplify the identification of the changed records is to replace the current overwrite logic with a merge statement to modify only those records that have changed, and write logic to make predictions on the changed records identified by the change data feed. This approach leverages the Delta Lake features of merge and change data feed, which are designed to handle upserts and track row-level changes in a Delta table12. By using merge, the data engineering team can avoid overwriting the entire table every night, and only update or insert the records that have changed in the source data. By using change data feed, the ML team can easily access the change events that have occurred in the customer_churn_params table, and filter them by operation type (update or insert) and timestamp. This way, they can only make predictions on the records that have changed in the past 24 hours, and avoid re-processing the unchanged records.
The other options are not as simple or efficient as the proposed approach, because:
Option A would require applying the churn model to all rows in the customer_churn_params table, which would be wasteful and redundant. It would also require implementing logic to perform an upsert into the predictions table, which would be more complex than using the merge statement.
Option B would require converting the batch job to a Structured Streaming job, which would involve changing the data ingestion and processing logic. It would also require using the complete output mode, which would output the entire result table every time there is a change in the source data, which would be inefficient and costly.
Option C would require calculating the difference between the previous model predictions and the current customer_churn_params on a key identifying unique customers, which would be computationally expensive and prone to errors. It would also require storing and accessing the previous predictions, which would add extra storage and I/O costs.
Option D would require modifying the overwrite logic to include a field populated by calling spark.sql.functions.current_timestamp() as data are being written, which would add extra complexity and overhead to the data engineering job. It would also require using this field to identify records written on a particular date, which would be less accurate and reliable than using the change data feed.
References: Merge, Change data feed
NEW QUESTION # 175
......
Databricks-Certified-Professional-Data-Engineer test guide is an examination material written by many industry experts based on the examination outlines of the calendar year and industry development trends. Its main purpose is to help students who want to obtain the certification of Databricks-Certified-Professional-Data-Engineer to successfully pass the exam. Compared with other materials available on the market, the main feature of Databricks-Certified-Professional-Data-Engineer exam materials doesn’t like other materials simply list knowledge points. It allows students to find time-saving and efficient learning methods while memorizing knowledge points. With Databricks-Certified-Professional-Data-Engineer study braindumps, learning from day and night will never happen. You can learn more with less time. You will become a master of learning in the eyes of others. With Databricks-Certified-Professional-Data-Engineer study braindumps, successfully passing the exam will no longer be a dream.
Databricks-Certified-Professional-Data-Engineer Pass4sure: https://www.dumpleader.com/Databricks-Certified-Professional-Data-Engineer_exam.html
What's more, part of that Dumpleader Databricks-Certified-Professional-Data-Engineer dumps now are free: https://drive.google.com/open?id=11pfEZS88vSPOs1ut_qE-VB05B5CHH-1j