Certified-Data-Engineer-Professional Valid Exam Tutorial, Certified-Data-Engineer-Professional Valid Exam Review

Are you still worried about whether or not our Certified-Data-Engineer-Professional materials will help you pass the exam? Are you still afraid of wasting money and time on our materials? Don’t worry about it now, our Certified-Data-Engineer-Professional materials have been trusted by thousands of candidates. They also doubted it at the beginning, but the high pass rate of us allow them beat the Certified-Data-Engineer-Professional at their first attempt. What most important is that your money and exam attempt is bound to award you a sure and definite success with 100% money back guarantee. You can claim for the refund of money if you do not succeed to pass the Certified-Data-Engineer-Professional Exam and achieve your target. We ensure you that you will be paid back in full without any deduction.
| Section | Objectives |
|---|
| Ensuring Data Security and Compliance | - Ensuring Compliance
- 1. Implement compliant batch and streaming pipelines that detect and mask PII
- 2. Develop data purging solutions that comply with data retention policies
- Applying Data Security Mechanisms
- 1. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 2. Use row filters and column masks to protect sensitive table data
- 3. Use ACLs to secure workspace objects and enforce the principle of least privilege
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
- 2. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 2. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- 3. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- Deploying CI/CD
- 1. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design dimensional models for analytical workloads with efficient querying and aggregation
- 4. Design and implement scalable data models using Delta Lake to manage large datasets
|
| Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 2. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 3. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 4. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- 5. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 6. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 7. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 8. Create pipeline components using control flow operators such as if/else and foreach
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
- 3. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
|
| Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Data Sharing and Federation | - Share and federate data
- 1. Use Delta Sharing to share live data from the Lakehouse with any computing platform
- 2. Configure Lakehouse Federation with appropriate governance across supported source systems
- 3. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
|
| Monitoring and Alerting | - Alerting
- 1. Use SQL Alerts to monitor data quality
- 2. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- Monitoring
- 1. Use Query Profile and Spark UI to monitor workloads
- 2. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
|
| Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
- 2. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
|
| Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 3. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 4. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
>> Certified-Data-Engineer-Professional Valid Exam Tutorial <<
Certified-Data-Engineer-Professional Valid Exam Review, Free Certified-Data-Engineer-Professional Exam Dumps
All Certified-Data-Engineer-Professional online tests begin somewhere, and that is what the Certified-Data-Engineer-Professional training guide will do for you: create a foundation to build on. Study guides are essentially a detailed Certified-Data-Engineer-Professional training guide and are great introductions to new Certified-Data-Engineer-Professional training guide as you advance. The content is always relevant, and compound again to make you pass your Certified-Data-Engineer-Professional exams on the first attempt.
Databricks Certified Data Engineer Professional Sample Questions (Q80-Q85):
NEW QUESTION # 80
Which statement describes Delta Lake Auto Compaction?
- A. Before a Jobs cluster terminates, optimize is executed on all tables modified during the most recent job.
- B. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 128 MB.
- C. Optimized writes use logical partitions instead of directory partitions; because partition boundaries are only represented in metadata, fewer small files are written.
- D. Data is queued in a messaging bus instead of committing data directly to memory; all data is committed from the messaging bus in one batch once the job is complete.
- E. An asynchronous job runs after the write completes to detect if files could be further compacted; if yes, an optimize job is executed toward a default of 1 GB.
Answer: B
Explanation:
This is the correct answer because it describes the behavior of Delta Lake Auto Compaction, which is a feature that automatically optimizes the layout of Delta Lake tables by coalescing small files into larger ones. Auto Compaction runs as an asynchronous job after a write to a table has succeeded and checks if files within a partition can be further compacted. If yes, it runs an optimize job with a default target file size of 128 MB. Auto Compaction only compacts files that have not been compacted previously.
NEW QUESTION # 81
An external object storage container has been mounted to the location /mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team:
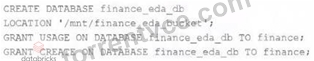
After the database was successfully created and permissions configured, a member of the finance team runs the following code:
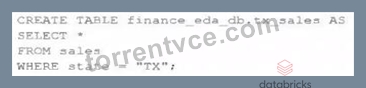
If all users on the finance team are members of the finance group, which statement describes how the tx_sales table will be created?
- A. A managed table will be created in the DBFS root storage container.
- B. A logical table will persist the query plan to the Hive Metastore in the Databricks control plane.
- C. An managed table will be created in the storage container mounted to /mnt/finance_eda_bucket.
- D. A logical table will persist the physical plan to the Hive Metastore in the Databricks control plane.
- E. An external table will be created in the storage container mounted to /mnt/finance eda bucket.
Answer: C
Explanation:
https://docs.databricks.com/en/data-governance/unity-catalog/create-schemas.html#language-SQL
NEW QUESTION # 82
A data engineer needs to provide access to a group named manufacturing-team. The team needs privileges to create tables in the quality schema. Which set of SQL commands will grant a group named manufacturing-team to create tables in a schema named production with the parent catalog named manufacturing with the least privileges?
- A. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- B. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- C. GRANT USE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT USE CATALOG ON CATALOG manufacturing TO manufacturing-team;
- D. GRANT CREATE TABLE ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE SCHEMA ON SCHEMA manufacturing.quality TO manufacturing-team; GRANT CREATE CATALOG ON CATALOG manufacturing TO manufacturing-team;
Answer: B
Explanation:
To create a table within a schema, a principal must have CREATE TABLE on the schema, USE SCHEMA on that schema, and USE CATALOG on the parent catalog. This combination ensures the group has just enough privileges to create objects in that schema without excessive permissions like CREATE SCHEMA or CREATE CATALOG.
NEW QUESTION # 83
A data engineer wants to refactor the following DLT code, which includes multiple table definitions with very similar code.
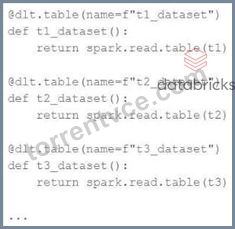
In an attempt to programmatically create these tables using a parameterized table definition, the data engineer writes the following code.
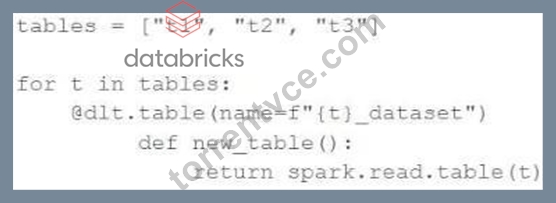
The pipeline runs an update with this refactored code, but generates a different DAG showing incorrect configuration values for these tables.
How can the data engineer fix this?
- A. Load the configuration values for these tables from a separate file, located at a path provided by a pipeline parameter.
- B. Convert the list of configuration values to a dictionary of table settings, using table names as keys.
- C. Convert the list of configuration values to a dictionary of table settings, using different input the for loop.
- D. Wrap the loop inside another table definition, using generalized names and properties to replace with those from the inner table
Answer: B
Explanation:
The issue with the refactored code is that it tries to use string interpolation to dynamically create table names within the dlc.table decorator, which will not correctly interpret the table names.
Instead, by using a dictionary with table names as keys and their configurations as values, the data engineer can iterate over the dictionary items and use the keys (table names) to properly configure the table settings. This way, the decorator can correctly recognize each table name, and the corresponding configuration settings can be applied appropriately.
NEW QUESTION # 84
A data engineer is testing a collection of mathematical functions, one of which calculates the area under a curve as described by another function.
assert(myIntegrate(lambda x: x*x, 0, 3) [0] == 9)
Which kind of the test does the above line exemplify?
- A. End-to-end
- B. Integration
- C. Manual
- D. Unit
- E. functional
Answer: D
Explanation:
A unit test is designed to verify the correctness of a small, isolated piece of code, typically a single function. Testing a mathematical function that calculates the area under a curve is an example of a unit test because it is testing a specific, individual function to ensure it operates as expected.
NEW QUESTION # 85
......
Our to-the-point and trustworthy Databricks Certified Data Engineer Professional Exam Questions in three formats for the Databricks Certified-Data-Engineer-Professional certification exam will surely assist you to qualify for Databricks Certified-Data-Engineer-Professional Certification. Do not underestimate the value of our Databricks Certified-Data-Engineer-Professional exam dumps because it is the make-or-break point of your career.
Certified-Data-Engineer-Professional Valid Exam Review: https://www.torrentvce.com/Certified-Data-Engineer-Professional-valid-vce-collection.html
- Reliable Study Certified-Data-Engineer-Professional Questions 🏮 Certified-Data-Engineer-Professional Reliable Test Experience 🗻 Certified-Data-Engineer-Professional Real Exam Answers 😗 Go to website ☀ www.troytecdumps.com ️☀️ open and search for 《 Certified-Data-Engineer-Professional 》 to download for free 🐴Reliable Study Certified-Data-Engineer-Professional Questions
- Newest Certified-Data-Engineer-Professional Valid Exam Tutorial - Unparalleled Certified-Data-Engineer-Professional Exam Tool Guarantee Purchasing Safety 💃 Search for “ Certified-Data-Engineer-Professional ” and obtain a free download on ⇛ www.pdfvce.com ⇚ 🧦Exam Questions Certified-Data-Engineer-Professional Vce
- Certified-Data-Engineer-Professional Lead2pass 🥤 New Certified-Data-Engineer-Professional Exam Name 🐂 Certified-Data-Engineer-Professional Reliable Test Experience 🦺 Search on ➠ www.verifieddumps.com 🠰 for ( Certified-Data-Engineer-Professional ) to obtain exam materials for free download 🛢Certified-Data-Engineer-Professional Real Exam Answers
- Certified-Data-Engineer-Professional Exam Valid Exam Tutorial - Excellent Certified-Data-Engineer-Professional Valid Exam Review Pass Success 🐗 Simply search for ▷ Certified-Data-Engineer-Professional ◁ for free download on ➥ www.pdfvce.com 🡄 🎀Certified-Data-Engineer-Professional Frequent Updates
- Certified-Data-Engineer-Professional Reliable Test Experience 🧜 Certified-Data-Engineer-Professional Frequent Updates 🧓 Certified-Data-Engineer-Professional Exam Simulator Fee 🐌 Search on ➽ www.prepawaypdf.com 🢪 for ➤ Certified-Data-Engineer-Professional ⮘ to obtain exam materials for free download 😤Certified-Data-Engineer-Professional Customizable Exam Mode
- Certified-Data-Engineer-Professional Lead2pass 🔇 Certified-Data-Engineer-Professional Valid Test Pass4sure 🎴 Certified-Data-Engineer-Professional Downloadable PDF 🎒 ▛ www.pdfvce.com ▟ is best website to obtain ➥ Certified-Data-Engineer-Professional 🡄 for free download 📣New Certified-Data-Engineer-Professional Exam Name
- 2026 Databricks Certified-Data-Engineer-Professional –The Best Valid Exam Tutorial 🌳 Download ▶ Certified-Data-Engineer-Professional ◀ for free by simply entering ➡ www.troytecdumps.com ️⬅️ website 💎Certified-Data-Engineer-Professional Free Updates
- Providing You High-quality Certified-Data-Engineer-Professional Valid Exam Tutorial with 100% Passing Guarantee ⛄ The page for free download of ➠ Certified-Data-Engineer-Professional 🠰 on ▷ www.pdfvce.com ◁ will open immediately 📧Certified-Data-Engineer-Professional Valid Study Questions
- Valid Databricks Certified-Data-Engineer-Professional Exam Dumps Questions - Confirm Your Success Reply 🐰 Search for ➽ Certified-Data-Engineer-Professional 🢪 and download exam materials for free through 【 www.practicevce.com 】 🕵Certified-Data-Engineer-Professional Valid Study Questions
- Printable Certified-Data-Engineer-Professional PDF 🔕 Valid Certified-Data-Engineer-Professional Test Online 🗜 Premium Certified-Data-Engineer-Professional Files 🏉 Enter 【 www.pdfvce.com 】 and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download for free 🥚Certified-Data-Engineer-Professional Free Updates
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: Authoritative Databricks Certified Data Engineer Professional Valid Exam Tutorial 🥅 Search for ➥ Certified-Data-Engineer-Professional 🡄 and download it for free immediately on 【 www.pass4test.com 】 🤲Exam Questions Certified-Data-Engineer-Professional Vce
- www.bandlab.com, me.muz.li, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, freestyler.ws, Disposable vapes