P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by Dumpkiller: https://drive.google.com/open?id=1gK5FslFbAPJ3-7efOw5NCOenVzEiLsJC
A growing number of people start to take the DP-800 exam in order to gain more intensifying attention in the different field. It is known to us that the knowledge workers have been playing an increasingly important role all over the world, since we have to admit the fact that the DP-800 certification means a great deal to a lot of the people, especially these who want to change the present situation and get a better opportunity for development. Our DP-800 Exam Questions will help you make it to pass the DP-800 exam and get the certification for sure.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Microsoft Developing AI-Enabled Database Solutions (DP-800) |
| Exam Number: | DP-800 |
| Exam Format: | Multiple choice, Case studies |
| Passing Score: | 700/1000 (typical Microsoft passing score; subject to confirmation) |
| Certificate Validity Period: | 1 year (Microsoft role-based certifications require annual renewal) |
| Available Languages: | English |
| Recommended Training: | Microsoft Learn - Azure Data & AI Learning Paths |
| Exam Registration: | Microsoft Certification Dashboard |
| Sample Questions: | Microsoft DP-800 Sample Questions |
| Exam Way: | Online proctored or onsite testing center |
| Pre Condition: | No formal prerequisites required, but familiarity with Azure data services and database concepts is recommended |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/ |
>> DP-800 Valid Test Vce Free <<
Our experts are responsible to make in-depth research on the DP-800 exam who contribute to growth of our DP-800 preparation materials even the practice materials in the market as role models. Both normal and essential exam knowledge is written by them with digestible ways to understand. Their highly accurate exam point can help you detect flaws on the review process and trigger your enthusiasm about the exam. DP-800 Exam Questions can fuel your speed and help you achieve your dream.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 66
You have an Azure SQL database named ToDo that contains a table named dbo.ToDo.
Your company plans to develop an Azure Functions app to run whenever the rows in dbo.ToDo change. The app will process INSERT, UPDATE, and DELETE events by using the Azure SQL trigger binding.
You need to configure ToDo to support the planned app.
What should you do?
Answer: A
Explanation:
To use the Azure SQL trigger for Azure Functions, your database table must have Change Tracking enabled. This is the underlying mechanism the trigger uses to monitor row-level modifications.
Required Table Configuration
To facilitate the app, you must follow these three steps:
1. Enable Change Tracking on the Database
Before the table can be tracked, the feature must be turned on at the database level.
2. Enable Change Tracking on the Table
The specific table the Function monitors must have tracking enabled.
3. Define a Primary Key
The Azure SQL trigger requires the table to have a Primary Key.
The trigger uses the Primary Key to identify which specific rows were changed.
If your table lacks a Primary Key, the Function will fail to start.
Reference:
https://demiliani.com/2025/05/08/azure-function-sql-trigger-how-to-use-it-and-why-it-can-be- useful-in-your-business-central-projects/
NEW QUESTION # 67
You have a GitHub Actions workflow that builds and deploys an Azure SQL database. The schema is stored in a GitHub repository as an SDK-style SQL database project.
Following a code review, you discover that you need to generate a report that shows whether the production schema has diverged from the model in source control.
Which action should you add to the pipeline?
Answer: D
Explanation:
Microsoft documents that DriftReport creates an XML report showing changes that have been made to the registered database since it was last registered . That is the action intended to detect whether the production schema has diverged from the expected model baseline in your deployment workflow.
This is different from DeployReport , which shows the changes that would be made by a publish action . In other words:
* DriftReport answers: Has the deployed database drifted from the registered state/model?
* DeployReport answers: What changes would be applied if I published now?
The other options are not the right fit:
* Extract creates a DACPAC from an existing database, not a drift analysis report.
* Script generates a deployment script, not a schema-drift report.
So to generate a report that shows whether production has diverged from the model in source control , add:
SqlPackage.exe /Action:DriftReport
NEW QUESTION # 68
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders, dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.orders.
Solution: Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABIE dbo.Orders
WITH (PARTITIONS (partition number));
Does this meet the goal?
Answer: A
Explanation:
Yes, this meets the goal. Microsoft documents that on a partitioned table , you can use TRUNCATE TABLE ... WITH (PARTITIONS (...)) to remove data from a specific partition, and that this is an efficient maintenance operation that targets only that data subset rather than the whole table. Microsoft's partitioning guidance explicitly lists truncating a single partition as an example of a fast partition-level maintenance or retention operation.
That matches the requirement to remove the oldest month while minimizing impact on other queries.
Because the table is already partitioned by month on OrderDate , identifying the partition number for that oldest month and truncating only that partition is the correct low-impact approach, assuming the table and indexes are aligned as required for partition truncation.
NEW QUESTION # 69
You have an Azure SQL database named SalesDB that supports an ecommerce application. SalesDB contains a table named dbo.Orders that has a clustered index on a column named orderid.
dbo.Orders receives continuous OLTP inserts and updates during business hours.
Your analytics team runs hourly aggregate queries that scan dbo.Orders to calculate revenue trends for recent dates.
You need to improve the performance of the hourly analytics queries without significantly affecting OLTP throughput. The solution must meet the following requirements:
Support near-real-time (NRT) analytics on the dbo.Orders table.
Reduce read time when retrieving analytical data from dbo.Orders.
Support indexing only rows that match a predicate, such as Active = 1.
Which type of index should you use for each requirement? To answer, drag the appropriate index types to the correct requirements. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
NEW QUESTION # 70
You have an Azure SQL database that stores sales data and contains tables named Sales and Products. Sales contains three columns named SalesDate, ProductKey, and TotalSale.
Sales is 10 TB and is loaded nightly by using a batch process. Most reporting queries scan large portions of Sales, filter on SalesDate or ProductKey, and use SUM() to aggregate TotalSale.
Products is relatively small and is used primarily for point lookups and joins to Sales.
You need to recommend which indexes to create to optimize the reporting queries. The solution must minimize storage requirements.
Which type of index should you recommend for each table? To answer, drag the appropriate index types to the correct tables. Each index type may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.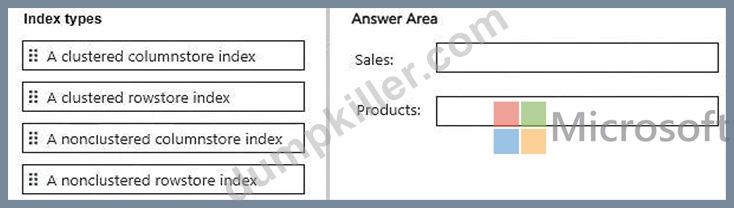
Answer:
Explanation:
Explanation:
Sales # A clustered columnstore index
Products # A clustered rowstore index
For Sales, the correct choice is a clustered columnstore index. Microsoft identifies clustered columnstore indexes as the standard storage choice for large fact tables and analytical/data-warehouse workloads. The Sales table is 10 TB, loaded in nightly batches, and its reporting queries scan large portions of the table and perform aggregations such as SUM(TotalSale). Those are exactly the workload characteristics that benefit from columnstore storage, batch-mode execution, aggregate pushdown, and high compression. Microsoft also notes that clustered columnstore indexes can provide substantial storage reduction compared with traditional uncompressed rowstore structures, which directly supports the requirement to minimize storage requirements.
For Products, the correct choice is a clustered rowstore index. Microsoft states that rowstore B-tree indexes perform best for point lookups, equality searches, and small-range retrieval, whereas columnstore is optimized for large analytical scans. Since Products is relatively small and primarily supports point lookups and joins to Sales, a rowstore structure is the better fit.
A nonclustered columnstore index would retain the underlying rowstore and add another compressed copy of selected columns, increasing storage. That is more appropriate for real-time analytics over an OLTP table, not for this dedicated large analytical fact table.
NEW QUESTION # 71
......
Reliable DP-800 Test Pass4sure: https://www.dumpkiller.com/DP-800_braindumps.html
P.S. Free 2026 Microsoft DP-800 dumps are available on Google Drive shared by Dumpkiller: https://drive.google.com/open?id=1gK5FslFbAPJ3-7efOw5NCOenVzEiLsJC