BTW, DOWNLOAD part of Itcertking Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=17jZjqrqQfn8uet5X-N3N6HSkGSjvbW9q
our experts have rewritten the textbooks according to the exam outline of Professional-Machine-Learning-Engineer, and have gathered all the key difficulties and made key notes, so that you can review them in a centralized manner. Experts also conducted authoritative interpretations of all incomprehensible knowledge points through examples and other methods. The expressions used in Professional-Machine-Learning-Engineer Learning Materials are very easy to understand. Even if you are an industry rookie, you can understand professional knowledge very easily. The Professional-Machine-Learning-Engineer training torrent will be the best study guide for you to obtain your certification.
The following will be discussed in Google Professional-Machine-Learning-Engineer exam dumps:
Design pipeline. Considerations include:
Google Professional Machine Learning Engineer exam is a certification offered by Google Cloud that validates the skills and knowledge of individuals working in the field of machine learning. Professional-Machine-Learning-Engineer Exam is designed to test the candidate's ability to design, build, and deploy machine learning models at scale using Google Cloud technologies. Professional-Machine-Learning-Engineer exam is intended for experienced machine learning engineers who have expertise in working with and implementing machine learning algorithms in production environments.
>> Professional-Machine-Learning-Engineer Valid Dumps Pdf <<
In today's fast-paced world, having access to Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) study material on the go is important. Itcertking Google Professional Machine Learning Engineer (Professional-Machine-Learning-Engineer) PDF questions are compatible with all smart devices, allowing you to study and prepare for the Professional-Machine-Learning-Engineer Exam whenever and wherever you choose. Since you can access real Google Professional-Machine-Learning-Engineer dumps in PDF from your smartphone or tablet, you can easily fit Professional-Machine-Learning-Engineer exam preparation into your busy schedule.
The Google Professional Machine Learning Engineer certification exam is a great way for professionals to demonstrate their knowledge and skills in machine learning. It is also an excellent way for employers to identify and hire qualified candidates with advanced skills in machine learning. Google Professional Machine Learning Engineer certification exam is recognized by Google and is a valuable asset for professionals who want to advance their career in machine learning.
NEW QUESTION # 190
You are responsible for building a unified analytics environment across a variety of on-premises data marts.
Your company is experiencing data quality and security challenges when integrating data across the servers, caused by the use of a wide rangeof disconnected tools and temporary solutions. You need a fully managed, cloud-native data integration service that will lower the total cost of work and reduce repetitive work. Some members on your team prefer a codeless interface for building Extract, Transform, Load (ETL) process.
Which service should you use?
Answer: D
Explanation:
Cloud Data Fusion is a fully managed, cloud-native data integration service that helps users efficiently build and manage ETL/ELT data pipelines. It provides a graphical interface to increase time efficiency and reduce complexity, and allows users to easily create and explore data pipelines using a code-free, point and click visual interface. Cloud Data Fusion also supports a broad range of data sources and formats, including on-premises data marts, and ensures data quality and security by using built-in transformation capabilities and Cloud Data Loss Prevention. Cloud Data Fusion lowers the total cost of ownership by handling performance, scalability, availability, security, and compliance needs automatically. References:
* Cloud Data Fusion documentation
* Cloud Data Fusion overview
NEW QUESTION # 191
You are investigating the root cause of a misclassification error made by one of your models. You used Vertex AI Pipelines to train and deploy the model. The pipeline reads data from BigQuery.
creates a copy of the data in Cloud Storage in TFRecord format, trains the model in Vertex AI Training on that copy, and deploys the model to a Vertex AI endpoint. You have identified the specific version of that model that misclassified, and you need to recover the data this model was trained on. How should you find that copy of the data?
Answer: D
NEW QUESTION # 192
You have developed an application that uses a chain of multiple scikit-learn models to predict the optimal price for your company's products. The workflow logic is shown in the diagram Members of your team use the individual models in other solution workflows. You want to deploy this workflow while ensuring version control for each individual model and the overall workflow Your application needs to be able to scale down to zero. You want to minimize the compute resource utilization and the manual effort required to manage this solution. What should you do?
Answer: D
Explanation:
The option C is the most efficient and scalable solution for deploying a machine learning workflow with multiple models while ensuring version control and minimizing compute resource utilization. By exposing each model as an endpoint in Vertex AI Endpoints, it allows for easy versioning and management of individual models. Using Cloud Run to orchestrate the workflow ensures that the application can scale down to zero, thus minimizing resource utilization when not in use. Cloud Run is a service that allows you to run stateless containers on a fully managed environment or on Google Kubernetes Engine. You can use Cloud Run to invoke the endpoints of each model in the workflow and pass the data between them. You can also use Cloud Run to handle the input and output of the workflow and provide an HTTP interface for the application.
References:
* Vertex AI Endpoints documentation
* Cloud Run documentation
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
NEW QUESTION # 193
You are building a TensorFlow model for a financial institution that predicts the impact of consumer spending on inflation globally. Due to the size and nature of the data, your model is long-running across all types of hardware, and you have built frequent checkpointing into the training process. Your organization has asked you to minimize cost. What hardware should you choose?
Answer: A
Explanation:
The best hardware to choose for your model while minimizing cost is a Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with a preemptible v3-8 TPU. This hardware configuration can provide you with high performance, scalability, and efficiency for your TensorFlow model, as well as low cost and flexibility for your long-running and checkpointing process. The v3-8 TPU is a cloud tensor processing unit (TPU) device, which is a custom ASIC chip designed by Google to accelerate ML workloads.
It can handle large and complex models and datasets, and offer fast and stable training and inference. The n1-standard-16 is a general-purpose VM that can support the CPU and memory requirements of your model, as well as the data preprocessing and postprocessing tasks. By choosing a preemptible v3-8 TPU, you can take advantage of the lower price and availability of the TPU devices, as long as you can tolerate the possibility of the device being reclaimed by Google at any time. However, since you have built frequent checkpointing into your training process, you can resume your model from the last saved state, and avoid losing any progress or data. Moreover, you can use the Vertex AI Workbench user-managed notebooks to create and manage your notebooks instances, and leverage the integration with Vertex AI and other Google Cloud services.
The other options are not optimal for the following reasons:
* A. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with 4 NVIDIA P100 GPUs is not a good option, as it has higher cost and lower performance than the v3-8 TPU. The NVIDIA P100 GPUs are the previous generation of GPUs from NVIDIA, which have lower performance, scalability, and efficiency than the latest NVIDIA A100 GPUs or the TPUs. They also have higher price and lower availability than the preemptible TPUs, which can increase the cost and complexity of your solution.
* B. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with an NVIDIA P100 GPU is not a good option, as it has higher cost and lower performance than the v3-8 TPU. It also has less GPU memory and compute power than the option with 4 NVIDIA P100 GPUs, which can limit the size and complexity of your model, and affect the training and inference speed and quality.
* C. A Vertex AI Workbench user-managed notebooks instance running on an n1-standard-16 with a non-preemptible v3-8 TPU is not a good option, as it has higher cost and lower flexibility than the preemptible v3-8 TPU. The non-preemptible v3-8 TPU has the same performance, scalability, and
* efficiency as the preemptible v3-8 TPU, but it has higher price and lower availability, as it is reserved for your exclusive use. Moreover, since your model is long-running and checkpointing, you do not need the guarantee of the device not being reclaimed by Google, and you can benefit from the lower cost and higher availability of the preemptible v3-8 TPU.
References:
* Professional ML Engineer Exam Guide
* Preparing for Google Cloud Certification: Machine Learning Engineer Professional Certificate
* Google Cloud launches machine learning engineer certification
* Cloud TPU
* Vertex AI Workbench user-managed notebooks
* Preemptible VMs
* NVIDIA Tesla P100 GPU
NEW QUESTION # 194
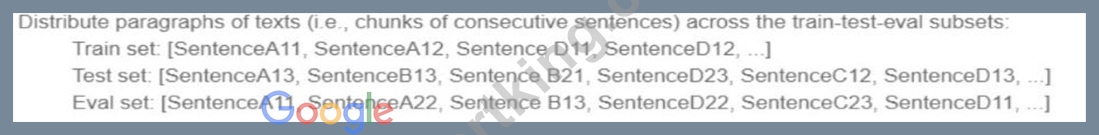
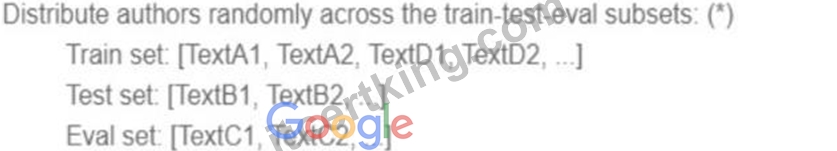
Your team is working on an NLP research project to predict political affiliation of authors based on articles they have written. You have a large training dataset that is structured like this:
You followed the standard 80%-10%-10% data distribution across the training, testing, and evaluation subsets. How should you distribute the training examples across the train-test-eval subsets while maintaining the 80-10-10 proportion?


Answer: C
Explanation:
If we just put inside the Training set , Validation set and Test set , randomly Text, Paragraph or sentences the model will have the ability to learn specific qualities about The Author's use of language beyond just his own articles. Therefore the model will mixed up different opinions. Rather if we divided things up a the author level, so that given authors were only on the training data, or only in the test data or only in the validation data. The model will find more difficult to get a high accuracy on the test validation (What is correct and have more sense!). Because it will need to really focus in author by author articles rather than get a single political affiliation based on a bunch of mixed articles from different authors. https://developers.google.com/machine-learning/crash-course/18th-century-literature For example, suppose you are training a model with purchase data from a number of stores. You know, however, that the model will be used primarily to make predictions for stores that are not in the training data. To ensure that the model can generalize to unseen stores, you should segregate your data sets by stores. In other words, your test set should include only stores different from the evaluation set, and the evaluation set should include only stores different from the training set. https://cloud.google.com/automl-tables/docs/prepare#ml-use
NEW QUESTION # 195
......
Professional-Machine-Learning-Engineer Test Collection Pdf: https://www.itcertking.com/Professional-Machine-Learning-Engineer_exam.html
2026 Latest Itcertking Professional-Machine-Learning-Engineer PDF Dumps and Professional-Machine-Learning-Engineer Exam Engine Free Share: https://drive.google.com/open?id=17jZjqrqQfn8uet5X-N3N6HSkGSjvbW9q