Avail Efficient Best Certified-Data-Engineer-Professional Study Material to Pass Certified-Data-Engineer-Professional on the First Attempt

It is a common sense that in terms of a kind of Databricks Certified Data Engineer Professional test torrent, the pass rate would be the best advertisement, since only the pass rate can be the most powerful evidence to show whether the Certified-Data-Engineer-Professional guide torrent is effective and useful or not. We are so proud to tell you that according to the statistics from the feedback of all of our customers, the pass rate among our customers who prepared for the exam under the guidance of our Databricks Certified Data Engineer Professional test torrent has reached as high as 98%to 100%, which definitely marks the highest pass rate in the field. Therefore, the Certified-Data-Engineer-Professional Guide Torrent compiled by our company is definitely will be the most sensible choice for you.
| Section | Objectives |
|---|
| Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Share live Lakehouse data with external computing platforms
- 3. Configure Databricks-to-Databricks Sharing
|
| Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Monitoring and Alerting | - Alerting
- 1. Configure Lakeflow Jobs notifications for job status and performance issues
- 2. Use SQL Alerts for data quality monitoring
- Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
|
| Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Data Modelling | - Scalable Data Models
- 1. Optimize data layout using Liquid Clustering
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
| Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
- 3. Build append-only pipelines for batch and streaming data using Delta
|
| Ensuring Data Security and Compliance | - Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
- Data Security
- 1. Use row filters and column masks for sensitive data
- 2. Use ACLs to secure workspace objects and enforce least privilege
- 3. Apply anonymization and pseudonymization techniques
|
| Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
- Building and Testing ETL Pipelines
- 1. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 2. Use APPLY CHANGES APIs for change data capture
- 3. Use control flow operators in pipeline components
- 4. Compare streaming tables and materialized views
- 5. Configure environments, dependencies, memory, and retry behavior
- 6. Develop unit and integration tests for data processing code
- 7. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 8. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
|
| Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Understand deletion vectors and liquid clustering
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Apply data skipping and file pruning techniques
- Query Performance
- 1. Identify inefficient joins and excessive data shuffling
- 2. Use Query Profile to identify performance bottlenecks
|
| Data Transformation, Cleansing, and Quality | - Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
- Advanced Data Transformation
- 1. Write efficient Spark SQL and PySpark transformations
- 2. Apply window functions, joins, and aggregations to large datasets
|
>> Best Certified-Data-Engineer-Professional Study Material <<
Excellent Best Certified-Data-Engineer-Professional Study Material - Easy and Guaranteed Certified-Data-Engineer-Professional Exam Success
With our professional experts’ unremitting efforts on the reform of our Certified-Data-Engineer-Professional guide materials, we can make sure that you can be focused and well-targeted in the shortest time when you are preparing a test, simplify complex and ambiguous contents. With the assistance of our Certified-Data-Engineer-Professional Study Guide you will be more distinctive than your fellow workers. For all the above services of our Certified-Data-Engineer-Professional practice engine can enable your study more time-saving and energy-saving.
Databricks Certified Data Engineer Professional Sample Questions (Q91-Q96):
NEW QUESTION # 91
Which statement regarding stream-static joins and static Delta tables is correct?
- A. Each microbatch of a stream-static join will use the most recent version of the static Delta table as of the job's initialization.
- B. Each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch.
- C. Stream-static joins cannot use static Delta tables because of consistency issues.
- D. The checkpoint directory will be used to track updates to the static Delta table.
- E. The checkpoint directory will be used to track state information for the unique keys present in the join.
Answer: B
Explanation:
This is the correct answer because stream-static joins are supported by Structured Streaming when one of the tables is a static Delta table. A static Delta table is a Delta table that is not updated by any concurrent writes, such as appends or merges, during the execution of a streaming query. In this case, each microbatch of a stream-static join will use the most recent version of the static Delta table as of each microbatch, which means it will reflect any changes made to the static Delta table before the start of each microbatch.
NEW QUESTION # 92
A platform engineer is creating catalogs and schemas for the development team to use.
The engineer has created an initial catalog, catalog_A, and initial schema, schema_A. The engineer has also granted USE CATALOG, USE SCHEMA, and CREATE TABLE to the development team so that the engineer can begin populating the schema with new tables.
Despite being owner of the catalog and schema, the engineer noticed that they do not have access to the underlying tables in Schema_A.
What explains the engineer's lack of access to the underlying tables?
- A. Users granted with USE CATALOG can modify the owner's permissions to downstream tables.
- B. Permissions explicitly given by the table creator are the only way the Platform Engineer could access the underlying tables in their schema.
- C. The platform engineer needs to execute a REFRESH statement as the table permissions did not automatically update for owners.
- D. The owner of the schema does not automatically have permission to tables within the schema, but can grant them to themselves at any point.
Answer: D
Explanation:
In Databricks, owning a catalog or schema does not automatically grant access to the tables within it. Table-level permissions are separate, so even the schema or catalog owner must be explicitly granted privileges on individual tables or use the ability to grant themselves access.
NEW QUESTION # 93
A junior data engineer seeks to leverage Delta Lake's Change Data Feed functionality to create a Type 1 table representing all of the values that have ever been valid for all rows in a bronze table created with the property delta.enableChangeDataFeed = true. They plan to execute the following code as a daily job:
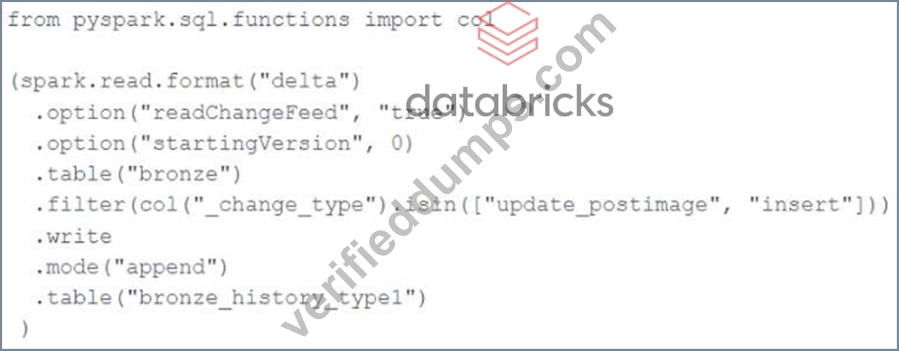
Which statement describes the execution and results of running the above query multiple times?
- A. Each time the job is executed, the differences between the original and current versions are calculated; this may result in duplicate entries for some records.
- B. Each time the job is executed, newly updated records will be merged into the target table, overwriting previous values with the same primary keys.
- C. Each time the job is executed, only those records that have been inserted or updated since the last execution will be appended to the target table giving the desired result.
- D. Each time the job is executed, the target table will be overwritten using the entire history of inserted or updated records, giving the desired result.
- E. Each time the job is executed, the entire available history of inserted or updated records will be appended to the target table, resulting in many duplicate entries.
Answer: E
Explanation:
Reading table's changes, captured by CDF, using spark.read means that you are reading them as a static source. So, each time you run the query, all table's changes (starting from the specified startingVersion) will be read.
NEW QUESTION # 94
A data engineer is configuring a Lakeflow Declarative Pipeline to process CDC (Change Data Capture) data from a source. The source events sometimes arrive out of order, and multiple updates may occur with the same update_timestamp but with different update_sequence_id.
What should the data engineer do to ensure events are sequenced correctly?
- A. Use a window function to sort update_sequence_id within the same partition, i.e., update_timestamp in the LDP pipeline.
- B. Use dropDuplicates() to remove out-of-order and duplicate records in LDP.
- C. Use SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) in AUTO CDC APIs.
- D. Set track_history_column_list to [event_timestamp, event_id] in AUTO CDC APIs.
Answer: C
Explanation:
When handling CDC data, sequencing is critical because updates may arrive out of order or multiple changes may occur for the same record at the same timestamp. Databricks' AUTO CDC APIs provide built-in constructs to handle ordering logic.
The correct mechanism is to use the SEQUENCE BY clause in the CDC configuration.
Specifically, when both update_timestamp and update_sequence_id exist, the recommended approach is:
SEQUENCE BY STRUCT(event_timestamp, update_sequence_id)
This ensures that within the same record key, the engine applies updates in the exact sequence they occurred, resolving conflicts where multiple updates share the same timestamp but differ in sequence ID.
Option A (track_history_column_list) is used for historical tracking and auditing changes, not for sequencing logic. It ensures lineage but does not enforce correct event order.
Option B (dropDuplicates()) only removes exact duplicates; it cannot guarantee sequencing correctness when multiple updates exist.
Option C is correct: SEQUENCE BY STRUCT(event_timestamp, update_sequence_id) explicitly enforces ordering, as recommended by the CDC pipeline guidelines.
Option D (window function) would be a manual approach in Spark Structured Streaming, but Lakeflow Declarative Pipelines already provide native CDC sequencing support, making this unnecessary.
Thus, the best practice per Databricks CDC documentation is to use Option C with SEQUENCE BY STRUCT.
NEW QUESTION # 95
A data engineer deploys a multi-task Databricks job that orchestrates three notebooks. One task intermittently fails with Exit Code 1 but succeeds on retry. The engineer needs to collect detailed logs for the failing attempts, including stdout/stderr and cluster lifecycle context, and share them with the platform team. What steps the data engineer needs to follow using built-in tools?
- A. Use the notebook interactive debugger to re-run the entire multi-task job, and capture step- through traces for the failing task.
- B. Download worker logs directly from the Spark UI and ignore driver logs, as worker logs contain stdout/stderr for all tasks and cluster events.
- C. Export the notebook run results to HTML; this bundle includes complete stdout, stderr, and cluster event history across all tasks.
- D. From the job run details page, export the job's logs or configure log delivery; then retrieve the compute driver logs and event logs from the compute details page to correlate stdout/stderr with cluster events.
Answer: D
Explanation:
The recommended way to troubleshoot and collect detailed job logs is through the Job Run Details page in Databricks. From there, engineers can export run logs or configure automatic log delivery to a storage destination. The driver and event logs available under compute details provide stdout, stderr, and cluster lifecycle context required for root-cause analysis.
NEW QUESTION # 96
......
Our company committed all versions of Certified-Data-Engineer-Professional practice materials attached with free update service. When Certified-Data-Engineer-Professional exam preparation has new updates, the customer services staff will send you the latest version. So we never stop the pace of offering the best services and Certified-Data-Engineer-Professional practice materials for you. Tens of thousands of candidates have fostered learning abilities by using our Certified-Data-Engineer-Professional Learning materials you can be one of them definitely.
New Certified-Data-Engineer-Professional Exam Answers: https://www.verifieddumps.com/Certified-Data-Engineer-Professional-valid-exam-braindumps.html
- Certified-Data-Engineer-Professional Reliable Exam Prep ☀ Certified-Data-Engineer-Professional Study Test 🖋 Authorized Certified-Data-Engineer-Professional Test Dumps 👒 Easily obtain ⏩ Certified-Data-Engineer-Professional ⏪ for free download through ➥ www.pdfdumps.com 🡄 🛌Certified-Data-Engineer-Professional Valid Test Materials
- Certified-Data-Engineer-Professional Practice Tests 🕕 Certified-Data-Engineer-Professional New Question 🚋 Reliable Certified-Data-Engineer-Professional Braindumps Files 🦂 Open website ( www.pdfvce.com ) and search for 【 Certified-Data-Engineer-Professional 】 for free download 👮Certified-Data-Engineer-Professional Reliable Exam Prep
- Latest Study Certified-Data-Engineer-Professional Questions 👖 Certified-Data-Engineer-Professional Certification Cost ⬆ Certified-Data-Engineer-Professional Study Test 📑 Immediately open “ www.pdfdumps.com ” and search for { Certified-Data-Engineer-Professional } to obtain a free download 🟫Latest Study Certified-Data-Engineer-Professional Questions
- Certified-Data-Engineer-Professional Actual Exam Preparation Materials and Certified-Data-Engineer-Professional Test Engine - Pdfvce 🆚 Open website ▛ www.pdfvce.com ▟ and search for ⏩ Certified-Data-Engineer-Professional ⏪ for free download 🌸Valid Certified-Data-Engineer-Professional Exam Question
- Certified-Data-Engineer-Professional Valid Test Materials 🦺 Certified-Data-Engineer-Professional New Question ✔ Certified-Data-Engineer-Professional Testking Exam Questions 🎪 Search for ➥ Certified-Data-Engineer-Professional 🡄 on ⏩ www.vce4dumps.com ⏪ immediately to obtain a free download 🩸Certified-Data-Engineer-Professional New Question
- Certified-Data-Engineer-Professional Testking Exam Questions 🕎 Certified-Data-Engineer-Professional New Question 🎌 Certified-Data-Engineer-Professional Certification Cost 👵 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download it for free immediately on ✔ www.pdfvce.com ️✔️ 🚺Certified-Data-Engineer-Professional Testking Exam Questions
- Quiz Certified-Data-Engineer-Professional - Reliable Best Databricks Certified Data Engineer Professional Study Material 🥧 The page for free download of ➤ Certified-Data-Engineer-Professional ⮘ on ➽ www.dumpsquestion.com 🢪 will open immediately 🏔Certified-Data-Engineer-Professional Certification Cost
- Certified-Data-Engineer-Professional Official Study Guide 😇 Latest Certified-Data-Engineer-Professional Exam Questions 💨 Free Certified-Data-Engineer-Professional Updates 💰 Search for ⇛ Certified-Data-Engineer-Professional ⇚ and download it for free on ➤ www.pdfvce.com ⮘ website 🎲Certified-Data-Engineer-Professional Practice Tests
- Certified-Data-Engineer-Professional Valid Test Materials 🦰 Certified-Data-Engineer-Professional New Question 🕑 Valid Certified-Data-Engineer-Professional Exam Format 🦅 Open 「 www.verifieddumps.com 」 and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download exam materials for free 🎒Latest Study Certified-Data-Engineer-Professional Questions
- Free PDF Quiz 2026 Databricks Valid Certified-Data-Engineer-Professional: Best Databricks Certified Data Engineer Professional Study Material 🕙 Simply search for ( Certified-Data-Engineer-Professional ) for free download on ➠ www.pdfvce.com 🠰 🗨Exam Certified-Data-Engineer-Professional Quick Prep
- Certified-Data-Engineer-Professional Testking Exam Questions 💋 Certified-Data-Engineer-Professional New Question 🤖 Valid Certified-Data-Engineer-Professional Exam Question ⏹ Search for ▛ Certified-Data-Engineer-Professional ▟ and obtain a free download on ➽ www.troytecdumps.com 🢪 👟Certified-Data-Engineer-Professional Study Test
- estar.jp, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes