To practice for a Designing and Implementing Multi-Agent AI Solutions in the software (free test), you should perform a self-assessment. The Microsoft AI-500 practice test software keeps track of each previous attempt and highlights the improvements with each attempt. The Microsoft AI-500 Mock Exam setup can be configured to a particular style & arrive at unique questions.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Topic 2: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize operational performance
|
| Topic 3: Secure, govern, and deploy multi-agent solutions | 20-25% | - Design and implement security
|
| Topic 4: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
>> AI-500 Valid Exam Question <<
The Microsoft wants to win the trust of Microsoft AI-500 exam candidates at any cost. To do this the Microsoft is offering some important features with Microsoft AI-500 exam. These AI-500 Exam Questions features are valid, updated, and real Microsoft AI-500 exam questions, availability of Microsoft AI-500 exam questions in three different formats.
NEW QUESTION # 34
You need to recommend an end-to-end release lifecycle for claim Approval. The solution must meet the technical requirements.
What should you recommend for each requirement? To answer, drag the appropriate recommendations to the correct requirements. Each recommendation may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation: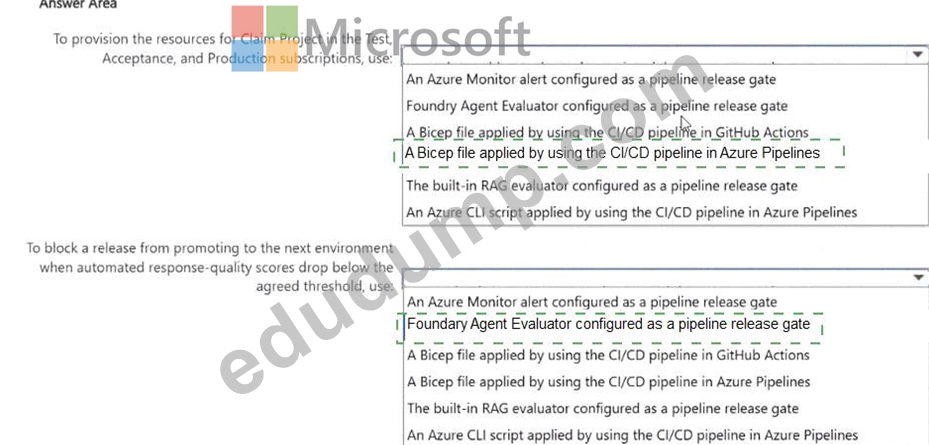
Explanation:
Provision Test, Acceptance, and Production by using a Bicep file applied through the CI/CD pipeline in Azure Pipelines; block promotion when quality falls below the threshold by using Foundry Agent Evaluator as a pipeline release gate.
The release lifecycle must satisfy two independent requirements: repeatable infrastructure deployment across DTAP environments and an automated quality gate before promotion. Bicep is Azure ' s infrastructure-as- code language, and Microsoft documents deploying Bicep through Azure Pipelines so the same declarative resources can be promoted consistently across subscriptions. For the promotion decision, an automated Foundry evaluation is the appropriate control because response quality is an AI-system property that should be measured against a defined threshold before the next stage is released. A manual portal deployment would weaken repeatability, while a deployment-only gate would not measure model or agent behavior. The important design point is that infrastructure provisioning and AI quality validation are separate controls in the same pipeline: Bicep establishes environment parity, and the evaluation gate prevents a technically deployable but behaviorally degraded agent version from advancing. From a security and governance perspective, the control should be enforced at the narrowest platform boundary that can deterministically block or constrain the action. Relying only on prompt text is weaker because the model can still be induced to behave unexpectedly.
Official Microsoft reference: Deploy Bicep files with Azure Pipelines; AI-500 Study Guide
NEW QUESTION # 35
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
Answer: A
NEW QUESTION # 36
You have a Microsoft Foundry multi-agent assistant that uses a Retrieval-Augmented Generation (RAG)- enabled workflow. A retrieval agent returns document chunks to an answer agent, and the answer agent produces the final response.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in RAG evaluators that meet the following requirements:
* Identify final responses that include content that is NOT supported by the retrieved context.
* Assess whether the retrieved context chunks and final responses support the user query.
Which evaluator should you use for each requirement? To answer, drag the appropriate evaluators to the correct requirements. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
Unsupported final-response content: Groundedness; Context support for the query: Retrieval; Final- response support for the query: Relevance.
Groundedness detects whether the generated response contains claims that are not supported by the retrieved context, which directly matches the first requirement. Retrieval evaluates how relevant the provided context chunks are to the query when no document relevance ground truth is available. Relevance evaluates whether the final response directly and adequately answers the query. Microsoft Foundry separates these metrics so teams can diagnose whether a poor RAG result originated in retrieval or generation. Document Retrieval would require labeled retrieval ground truth, which the question explicitly says is absent. Response Completeness likewise depends on expected/ground-truth information. The supplied Groundedness, Retrieval, and Relevance mapping therefore matches the documented evaluator inputs and purposes. A robust evaluation program separates process metrics from final-response metrics. The selected answer measures the layer where the stated failure actually occurs, which is essential for deciding whether to change retrieval, orchestration, prompt behavior, or the final generator. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators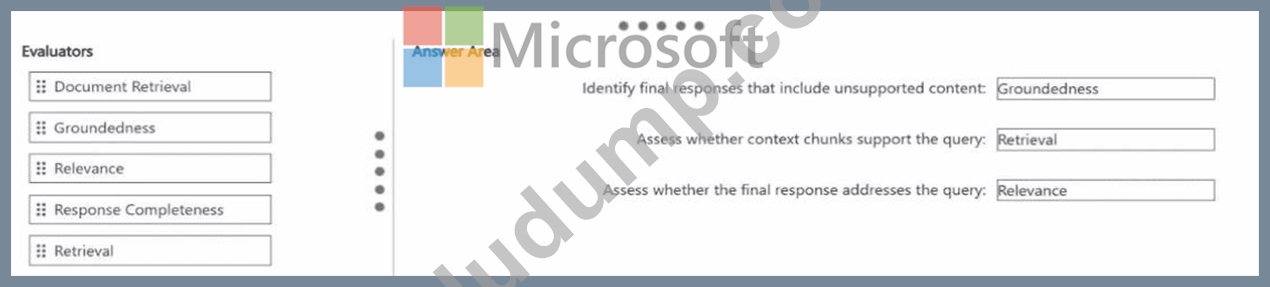
NEW QUESTION # 37
You are designing a Microsoft Foundry multi-agent solution for claims processing. The design includes multiple specialized agents.
You need to specify the agent personas. scopes, boundaries, and autonomy levels. The solution must meet the following requirements:
* Provide a clear owner for conflicts between specialist agents.
* Validate agent outputs before downstream agents consume the outputs.
* Prevent specialist agents from invoking tools outside the assigned domain.
* Isolate each business domain so that adding a specialist agent affects only that domain.
What should you do?
Answer: D
Explanation:
Domain-scoped sub-orchestrators under a claims supervisor provide the clearest ownership and isolation model. Each domain can contain its own specialists and tools, so adding a new specialist affects only that domain. The supervisor becomes the explicit authority for cross-domain conflicts. Requiring every domain output to satisfy a structured contract before it is consumed downstream provides a deterministic validation boundary instead of relying on unconstrained narrative summaries. Microsoft AI-500 architecture objectives emphasize agent scopes, tool boundaries, structured interfaces, and explicit control loops. Option B gates only the final settlement and therefore allows invalid intermediate outputs to propagate. Option D deliberately leaves conflict resolution to consuming domains, which violates the requirement for a clear owner. Option A lacks a strong validation contract. C is therefore the most robust architecture. The architecture should still be validated with representative end-to-end tests, but the selected component establishes the correct structural boundary first. Microsoft ' s AI-500 blueprint consistently favors explicit scopes, interfaces, and persistence or identity boundaries over prompt-only conventions.
Official Microsoft reference: AI-500 Study Guide - agent personas, scopes, boundaries, and workflows
NEW QUESTION # 38
You have a multi-agent solution in Microsoft Foundry. Every request begins with the same 1,800-token instruction block and Model Context Protocol (MCP) tool definitions, and then appends a unique user message.
Input-token costs and Time to First Token (TTFT) increase during peak hours.
You need to reduce the input-token costs and TTFT for requests that share common instructions and tool definitions. The solution must meet the following requirements:
Reuse cached work only when the common prefix matches exactly.
Generate a new completion for each user request.
Minimize application changes.
Which type of caching should you use?
Answer: B
Explanation:
Prompt caching is designed for requests that share a long, identical prefix but still require a new completion for the unique user input. Azure OpenAI prompt caching reuses computation for matching prompt prefixes, reducing the effective input cost and improving Time to First Token for supported models. The stable 1,800- token instruction and MCP tool-definition block is large enough to benefit from this mechanism, and the unique user message can remain at the end so each request still generates a fresh response. Response caching would reuse an old completion, which violates the requirement. Semantic caching matches similar meaning rather than exact prompt prefixes, and retrieval caching applies to knowledge retrieval rather than model prompt processing. Because prompt caching is handled automatically for supported deployments, it also minimizes application changes. Therefore D is correct. At implementation time, the same rule should be expressed through the framework or service configuration rather than left only as a natural-language convention. That makes the behavior repeatable across runs, easier to test, and less sensitive to model variability.
Official Microsoft reference: Azure OpenAI - Prompt caching
NEW QUESTION # 39
......
To keep with such an era, when new knowledge is emerging, you need to pursue latest news and grasp the direction of entire development tendency, our AI-500 training questions have been constantly improving our performance and updating the exam bank to meet the conditional changes. Our working staff regards checking update of our AI-500 Preparation exam as a daily routine. So without doubt, our AI-500 exam questions are always the latest and valid.
AI-500 Reliable Braindumps Book: https://www.edudump.com/exams/Microsoft/AI-500/