VCESoft為每個需要通過Microsoft的AI-500考試認證的考生提供了一個明確和卓越的解決方案,我們為你提供Microsoft的AI-500考試詳細的問題及答案, 我們團隊的IT專家是最有經驗和資格的,我們的考試測試題及答案幾乎和真實得考試一樣,做到這樣的確很了不起,更重要的是我們VCESoft網站在全球範圍內執行這項考試培訓通過率最大。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Secure, govern, and deploy multi-agent solutions | 20-25% | - Deploy multi-agent solutions to Azure
|
| Topic 2: Architect multi-agent solutions | 15-20% | - Design logical architecture for multi-agent solutions
|
| Topic 3: Develop multi-agent solutions in Azure | 30-35% | - Implement multi-agent orchestration
|
| Topic 4: Evaluate, optimize, and monitor multi-agent solutions | 20-25% | - Optimize operational performance
|
想更好更快的通過Microsoft的AI-500考試嗎?快快選擇我們VCESoft吧!它可以迅速的完成你的夢想。我們VCESoft是一個為多種IT認證考試的人,提供準確的考試材料的網站,我們VCESoft是一個可以為很多IT人士提升自己的職業藍圖,我們的力量會讓你難以置信。你可以先嘗試我們VCESoft為你們提供的免費下載關於Microsoft的AI-500考試的部分考題及答案,檢測我們的可靠性。
問題 #48
You are designing a multitenant software as a service (SaaS) platform that uses multiple agents. Users will send latency-sensitive inference requests to the platform by using a shared API.
Initially, there will be 20 tenants, and the platform will expand to 200 tenants.
You need to identify the compute component for a production agent runtime. The solution must meet the following requirements:
Isolate workloads for each tenant by using containerization.
Dynamically scale based on demand.
Minimize administrative effort.
What should you use?
答案:A
解題說明:
Microsoft Foundry Agent Service is the managed option that best satisfies containerized production agent execution, dynamic scaling, and low administrative overhead. Hosted agents run in Foundry-managed container compute and scale according to workload demand while the platform manages much of the runtime, endpoint, identity, and operational plumbing. AKS could provide strong tenant/workload isolation and autoscaling, but it also requires Kubernetes cluster operations, policy, upgrades, node pools, and scaling configuration, which conflicts with the requirement to minimize administration as the tenant count grows.
Azure Container Instances is simpler but lacks the same managed autoscaling model, and GPU virtual machines create the highest infrastructure burden. Therefore C is the strongest fit for a SaaS platform that wants production agent compute without owning the orchestration platform. From an architecture perspective, the selection also creates explicit ownership and boundaries that can be tested independently. That matters in multi-agent systems because implicit sharing or loosely defined authority often becomes the source of cross- agent coupling, security drift, and difficult incident diagnosis.
Official Microsoft reference: Microsoft Foundry Agent Service overview
問題 #49
You have a multi-agent customer support solution in a Microsoft Foundry project.
You have a dataset that contains query, context, and response without document relevance labels.
You need to implement built-in evaluators that provide 1 to-5 scores with pass/fail labels for the following metrics:
* The quality of the retrieved context
* How directly a response answers a query
Which evaluator should you use for each metric? To answer, drag the appropriate evaluators to the correct metrics. Each evaluator may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.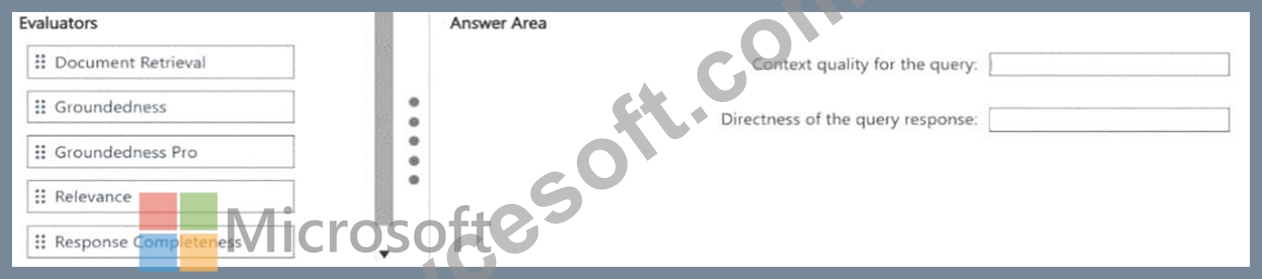
答案:
解題說明: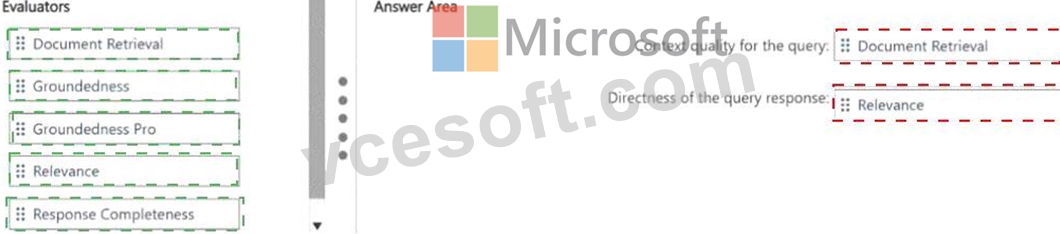
Explanation:
Quality of retrieved context: Retrieval evaluator; Directness of response to query: Relevance evaluator.
The dataset contains query, context, and response but does not contain document relevance labels. Microsoft ' s Retrieval evaluator is designed for exactly that situation: it uses an LLM judge to rate how relevant the retrieved context chunks are to the query and returns a 1-to-5 score with pass/fail behavior. The Relevance evaluator operates on the final response and measures whether the answer accurately, completely, and directly addresses the query. Document Retrieval is not appropriate because it requires retrieval ground truth such as known relevant documents or qrels. Groundedness answers a different question: whether response claims are supported by the provided context. Therefore the correct mapping is Retrieval for context quality and Relevance for response directness. For operational use, the measurement should be captured in a repeatable dataset, trace, or automated gate so that the same criterion can be compared across versions. That is more useful than a one-off manual observation and makes regressions visible before they become production incidents.
Official Microsoft reference: Microsoft Foundry - RAG evaluators
問題 #50
HOTSPOT -
You have a multi-agent solution in a Microsoft Foundry project. The project is connected to an Application Insights resource.
You have the following code that implements tracing.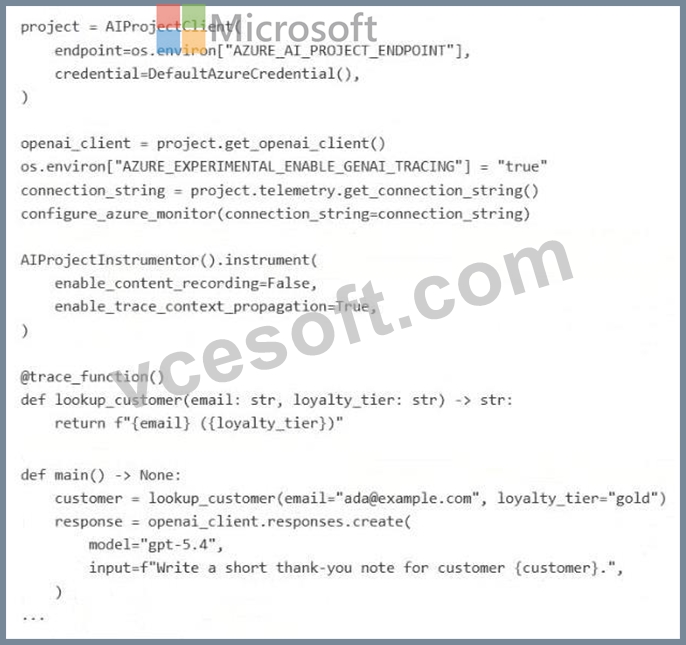
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.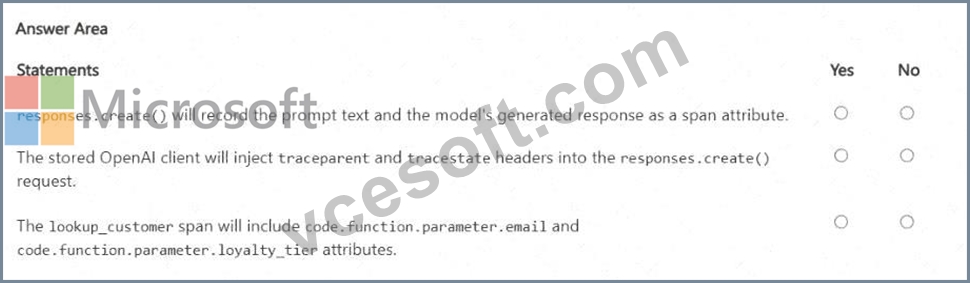
答案:
解題說明: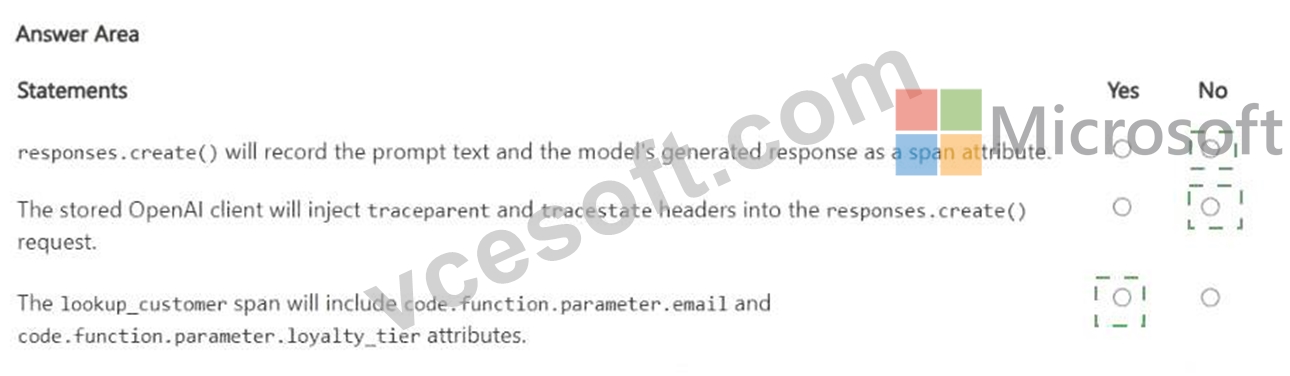
Explanation:
No / No / Yes
The first statement is false because content recording is explicitly disabled, so prompt and generated response text are not stored as GenAI span content attributes even though tracing remains active. The second is false because the OpenAI client is obtained before trace-context propagation is enabled; Microsoft documents that clients created before the instrumentation change are not retroactively configured for that propagation behavior. The third statement is true because the tracing decorator for ordinary functions records supported function parameters as `code.function.parameter. < name > ` attributes. Those parameter attributes are separate from GenAI prompt-content recording, so disabling message content does not suppress them.
Consequently `email` and `loyalty_tier` can appear on the `lookup_customer` span. The correct sequence is No, No, Yes. The evaluation should also preserve correlation identifiers and version information where possible so a failed score can be traced back to the exact agent, model, tool call, or retrieval step that produced it. This turns the metric into an actionable diagnostic rather than only a dashboard number.
Official Microsoft reference: Microsoft Foundry - client-side agent tracing
問題 #51
You have a Microsoft Foundry multi-agent customer support solution that retrieves grounding data from a shared vector index. The indexed corpus contains product runbooks in Markdown and support articles in HTML Both document types use a consistent hierarchical markup.
You discover that current fixed-size token chunking creates chunks that cross section boundaries.
You need to recommend a chunking approach for the ingestion pipeline. The solution must preserve existing document structure boundaries and minimize custom chunking code.
What should you recommend?
答案:A
解題說明:
The corpus already contains reliable document hierarchy in Markdown and HTML, so the ingestion pipeline should preserve those author-defined boundaries rather than infer new ones from token counts or topic shifts.
Format-specific header splitters can divide Markdown by heading levels and HTML by structural headers, producing chunks that align with meaningful sections. This directly solves the current problem of fixed-size token chunks crossing section boundaries and requires less custom logic than building a semantic topic-shift chunker. Recursive character splitting can be configured with structure-aware separators, but it remains a more generic fallback when format-specific structure is already available. Microsoft Azure AI Search guidance recommends exploiting document structure such as headings when chunking. Therefore B is the most direct and maintainable approach. In production, add telemetry and regression tests around this behavior so changes to prompts, models, tools, or orchestration do not silently alter the intended contract. The selected approach is the one that best matches the platform ' s native execution semantics.
Official Microsoft reference: Azure AI Search - structure-aware chunking and Markdown indexing
問題 #52
You are designing Microsoft Foundry multi-agent solution. The agents will use Agent-to-Agent (A2A) delegation and access separate Azure Storage containers within a resource group named RG1.
You need to recommend identity components for the design. The solution must meet the following requirements:
* Eliminate stored application secrets.
* Limit the impact of a compromised agent or deployment.
Solution: Use delegated user permissions for agent actions. Assign Azure roles by using a shared security group. Does this meet the goal?
答案:B
解題說明:
The proposed solution uses delegated user permissions for agent actions and assigns Azure roles through one shared security group. Even if it avoids storing an application secret, it does not create strong per-agent authorization boundaries. Sharing downstream permissions through one group can allow a compromised agent to inherit access intended for other agents, which conflicts with the requirement to limit blast radius.
Microsoft Foundry identity guidance recommends distinct logical agent/workload identities and narrowly scoped role assignments when agents have different resource responsibilities or audit requirements. Delegated user access is appropriate when an operation genuinely needs the signed-in user ' s authorization context, not as a general service-to-service isolation model for autonomous A2A workers. Therefore the proposed design does not meet both goals, and B, No, remains correct. The same configuration should be paired with auditable identity, trace, and evaluation data so reviewers can prove which principal acted, which policy was applied, and why a request was allowed or blocked. That is particularly important for production multi-agent systems with external tools.
Official Microsoft reference: Microsoft Foundry agent identity
問題 #53
......
VCESoft是個可以滿足很多客戶的需求的網站。有些使用我們類比測試軟體已經通過相關IT認證考試的人成為了VCESoft的回頭客。VCESoft可以提供領先的Microsoft 培訓技術助你通過Microsoft AI-500 認證考試。
AI-500資訊: https://www.vcesoft.com/AI-500-pdf.html