P.S. Free & New 810-110 dumps are available on Google Drive shared by Test4Cram: https://drive.google.com/open?id=1vCCl5R66KLVUNrBNU2bOkFo6_K4zucEs
The Test4Cram 810-110 Practice Questions are designed and verified by experienced and renowned 810-110 exam trainers. They work collectively and strive hard to ensure the top quality of 810-110 exam practice questions all the time. The 810-110 Exam Questions are real, updated, and error-free that helps you in Cisco 810-110 exam preparation and boost your confidence to crack the upcoming 810-110 exam easily.
| Section | Weight | Objectives |
|---|---|---|
| AI for Data Research and Analysis | - Data exploration and transformation
| |
| Generative AI Models | 20% | - Model hosting and architecture
|
| Ethics and Security | 15% | - Responsible AI principles
|
| Prompt Engineering | 15% | - Security and robustness
|
| Agentic AI Systems | - Agent architecture
| |
| AI for Code and Workflow Optimization | - Automation workflows
|
>> Valid Braindumps 810-110 Ppt <<
Likewise, Web-Based Cisco 810-110 exam questions are supported by all the major browsers like Chrome, Opera, Safari, Firefox, and IE. In the same way, the Web-based Cisco AI Technical Practitioner pdf exam requires no special plugin. Lastly, the web-based Cisco AI Technical Practitioner (810-110) practice exam is customizable and requires an active Internet connection.
NEW QUESTION # 64
A prototype application has high latency during the "time-to-first-token" phase. To ensure the AI has the needed information, the developer currently includes the entire 50-page technical manual in every prompt.
What is the most effective approach to reduce latency while preserving prototype quality?
Answer: B
Explanation:
Retrieval-Augmented Generation (RAG) is an architectural approach that retrieves relevant information from an external knowledge source and supplies that information to a generative model during inference. Option A is correct because retrieving only the relevant portions of a 50-page technical manual significantly reduces unnecessary input-token processing while preserving task-specific information.
Time-to-first-token (TTFT) measures the interval between submitting an inference request and receiving the first generated token. Processing extensive input context can contribute to increased prefill latency.
A RAG pipeline typically divides the technical manual into passages, creates searchable representations, and retrieves relevant sections based on the user's query. Only selected passages are included in the prompt.
Option B is incorrect because removing formatting may save some tokens but does not address the fundamental inefficiency of transmitting the entire manual.
Option C is incorrect because increasing the output-token allowance does not reduce input processing time.
Option D is incorrect because larger models can have higher inference costs and latency.
RAG can improve response relevance and resource efficiency, although retrieval introduces its own processing overhead. Effective implementation requires appropriate chunking, indexing, retrieval evaluation, and source validation.
Specific Cisco AITECH Course Guide References: Customizing AI Models; AI Architect's Toolkit; Objective
1.5 - RAG and vector databases; Objective 5.4 - Token usage, latency, cost, and output quality.
NEW QUESTION # 65
When designing an AI agent for a high-stakes deployment task, which feature combination ensures that the system functions safely and predictably in a production environment?
Answer: D
Explanation:
Safe production deployment of agentic AI requires explicit operational boundaries, well-defined tool interfaces, resource controls, and authorization mechanisms. Option A is correct because it combines complementary safeguards that promote predictable agent behavior and limit the impact of errors.
Bounded goals restrict an agent to clearly defined objectives and prevent uncontrolled expansion of its responsibilities.
Explicit tool definitions establish permitted operations, required parameters, and expected responses. This reduces ambiguity when the agent interacts with external systems.
Cost and latency budgets control resource consumption by establishing limits on model calls, execution duration, and operational expenditure.
Human approval gates prevent consequential operations from proceeding without authorization.
For example, a production deployment agent might generate a Kubernetes configuration, validate it, run automated checks, and request engineering approval before applying the change.
Option B is incorrect because unrestricted token usage and error bypasses undermine operational control.
Option C is incorrect because high temperature and unlimited autonomy can increase behavioral variability and resource consumption.
Option D is incorrect because implicit tool definitions and uncontrolled deployment triggers increase execution risk.
These safeguards should be supplemented with observability, least-privilege permissions, rollback mechanisms, and defined failure-handling procedures.
Specific Cisco AITECH Course Guide References:
* AI-Powered Workflows and Agentic AI
* Generative AI Security and Privacy Fundamentals
* Exam Objective 6.2: AI agent design principles and orchestration
* Exam Objective 6.4: Human-in-the-Loop strategies
NEW QUESTION # 66
Match each RAG architectural component with its primary function.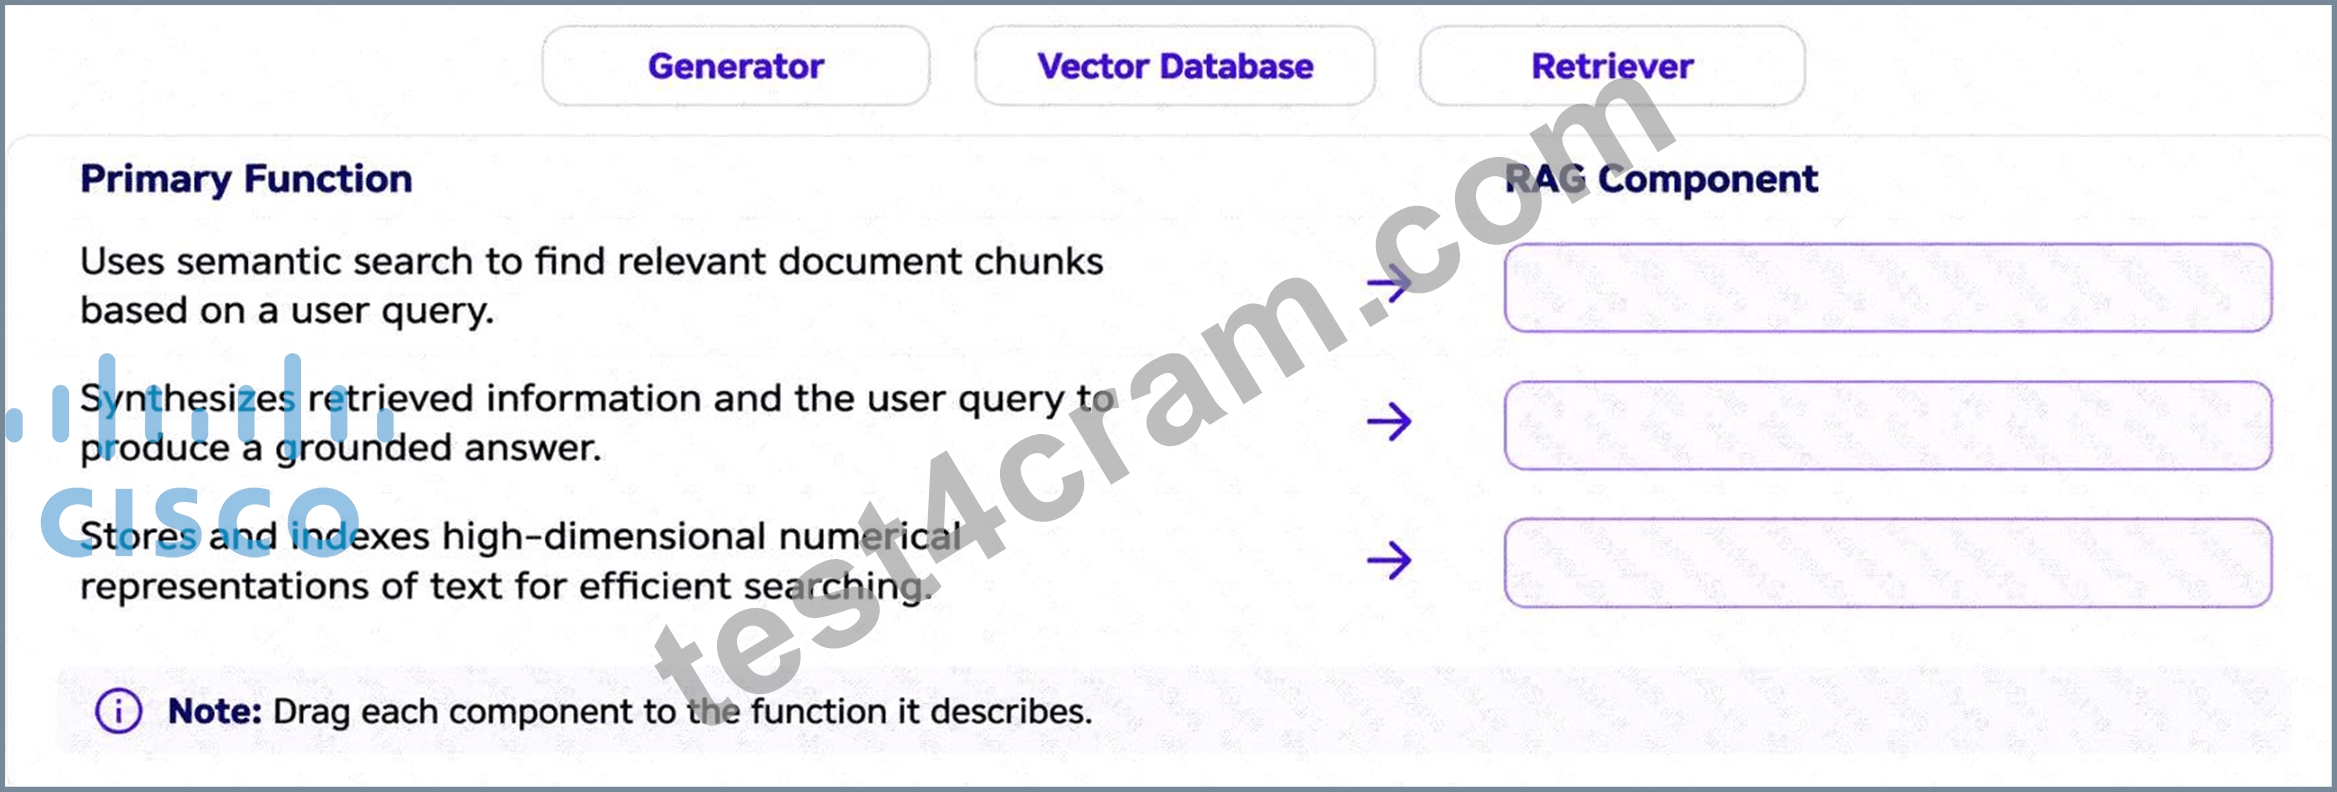
Answer:
Explanation: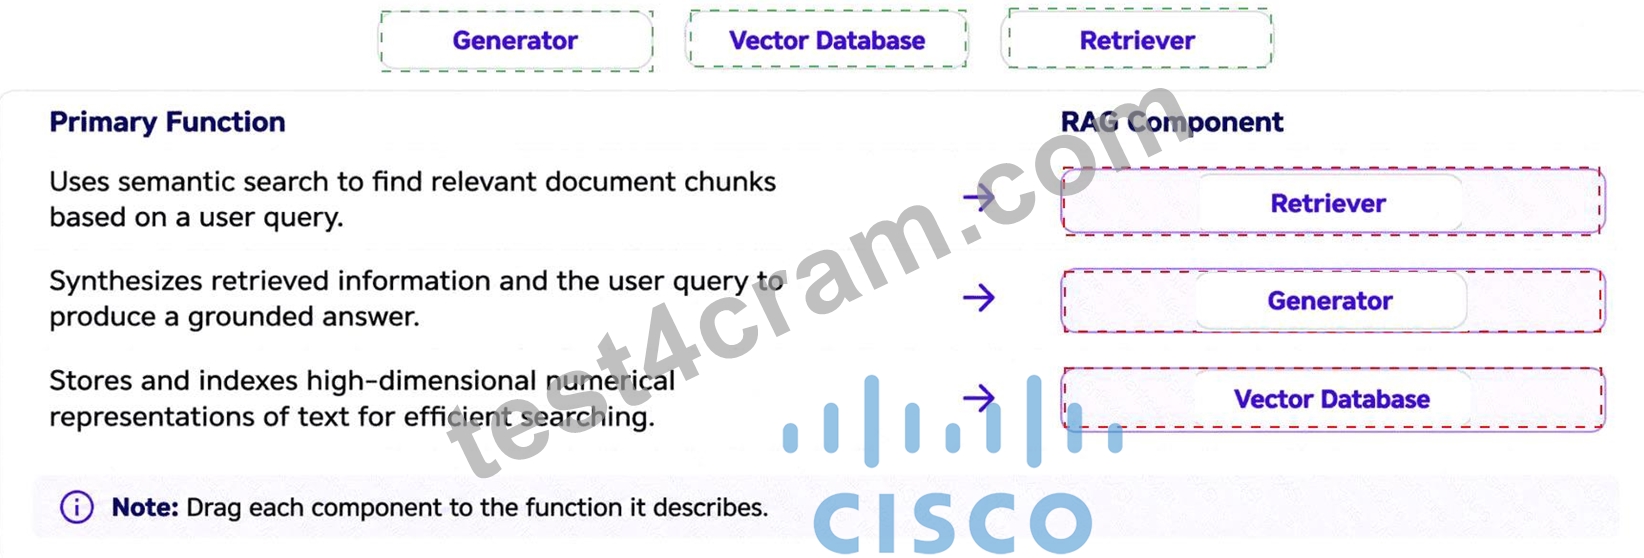
Explanation:
Retrieval-Augmented Generation (RAG) combines information retrieval with generative AI to produce responses informed by external knowledge sources. The architecture uses three important components.
1. Retriever: The retriever identifies relevant passages from a document collection based on the user's query.
It may use semantic similarity search, keyword matching, or hybrid retrieval techniques to select appropriate supporting information.
2. Generator: The generator is typically a Large Language Model (LLM) that processes the user's question alongside retrieved information and produces a coherent response. Grounding the answer in relevant source material can improve factual accuracy and reduce unsupported claims, although it does not guarantee correctness.
3. Vector Database: A vector database stores and indexes numerical embeddings representing the semantic characteristics of text or other information. Specialized similarity-search algorithms enable efficient identification of relevant content across large document collections.
In a typical RAG workflow, documents are converted into embeddings and stored in the vector database. The retriever searches for relevant passages, and the generator uses those passages to formulate an answer.
Specific Cisco AITECH Course Guide References:
* Generative AI Ecosystem
* Customizing AI Models
* Retrieval-Augmented Generation (RAG)
* Embeddings, Vector Databases, and Semantic Search
NEW QUESTION # 67
Why is enforcing a strict JSON schema for agent-to-agent communication considered a best practice?
Answer: C
Explanation:
JSON Schema provides a formal specification describing the structure, required properties, permitted data types, and validation constraints of JSON documents. Option C is correct because a strict schema establishes an explicit data contract that enables receiving agents to interpret and validate exchanged information consistently.
In multi-agent architectures, different agents may generate outputs that are subsequently processed by other components.
For example, a network analysis agent might produce a JSON object containing device_id, severity, findings, and recommended_action.
A remediation agent can validate the document against an agreed schema before taking further action.
This helps identify missing fields, unexpected data types, malformed structures, and unsupported values.
Option A is incorrect because schema enforcement does not inherently reduce token consumption. Detailed schemas may increase prompt or payload size.
Option B is incorrect because strict schemas generally constrain permitted structures rather than encourage arbitrary field generation.
Option D is incorrect because schema validation does not replace explicit task semantics, authorization policies, or operating instructions.
Strict schemas improve interoperability, predictability, and error handling.
However, syntactically valid JSON may still contain incorrect information, so applications must also perform semantic validation and enforce appropriate authorization.
Specific Cisco AITECH Course Guide References:
* AI Systems Integration with APIs
* AI-Powered Workflows and Agentic AI
* Exam Objective 6.2: Agent orchestration and design
* Exam Objective 6.5: Data transformation and mapping within AI agents
NEW QUESTION # 68
How does managing the context window help control the cost of a long-running AI conversation?
Answer: C
Explanation:
Context-window management controls how much conversational history and supporting information is included in each inference request. Option B is correct because limiting the number of input tokens transmitted with each new prompt helps reduce repeated processing and associated usage-based costs.
Many conversational AI applications include previous messages in subsequent requests to maintain conversational continuity.
As the conversation grows, the amount of historical context supplied to the model can increase substantially, even when earlier messages are no longer relevant.
For example, a technical support assistant may process hundreds of exchanges during a troubleshooting session. Retaining every previous message could cause each new request to include thousands of unnecessary tokens.
Context management strategies can retain essential instructions, summarize previous findings, discard irrelevant messages, and retrieve historical details only when required.
Option A is incorrect because model switching requires application-level selection logic and is not an automatic consequence of context-window management.
Option C is incorrect because increasing the maximum context window does not inherently reduce billed input tokens.
Option D is incorrect because context management does not fundamentally change the model's tokenizer or tokenization algorithm.
Efficient context management balances operational expenditure against information retention, response accuracy, and conversational continuity.
Specific Cisco AITECH Course Guide References: Generative AI Ecosystem; AI Architect's Toolkit; Exam Objective 1.3 - Context windows and token limits; Objective 5.4 - Token usage, cost, latency, and output quality.
Cisco Learning Content
NEW QUESTION # 69
......
Try to have a positive mindset, keep your mind focused on what you have to do. Self- discipline is important if you want to become successful. Learn to reject temptations. As old saying goes, no pains no gains. Learning our 810-110 preparation materials will help you calm down. What you have learned will finally pay off. With the 810-110 Certification, you can have more oppotunities to the bigger companies. And our 810-110 exam guide is condersidered the best aid to obtain the certification.
Updated 810-110 Test Cram: https://www.test4cram.com/810-110_real-exam-dumps.html
P.S. Free 2026 Cisco 810-110 dumps are available on Google Drive shared by Test4Cram: https://drive.google.com/open?id=1vCCl5R66KLVUNrBNU2bOkFo6_K4zucEs