2026 Die neuesten ZertSoft Databricks-Generative-AI-Engineer-Associate PDF-Versionen Prüfungsfragen und Databricks-Generative-AI-Engineer-Associate Fragen und Antworten sind kostenlos verfügbar: https://drive.google.com/open?id=1WdCVAYn02HUa0vMkz5cxm8e6oG452f77
Die Ausbildungsmaterialien zur Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung aus ZertSoft sind nicht nur der Grundstein auf dem Weg zu Ihrem Erfolg, sie können Ihnen auch dabei helfen, Ihre Fähigkeiten in der IT-Branche effektiver zu entfalten. Nach mehrjährigen Bemühungen beträgt die Hit-Rate von Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung von ZertSoft bereits 100%. Wenn Sie die Zertifizierungsprüfung nicht bestehen, nachdem Sie unsere Fragenpool gekauft haben, werden wir alle Ihre bezahlten Summe zurückgeben.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
| Thema 4 |
|
| Thema 5 |
|
>> Databricks-Generative-AI-Engineer-Associate Vorbereitungsfragen <<
Viele auf die Databricks Databricks-Generative-AI-Engineer-Associate Prüfung vorbereitende Prüfungsteilnehmer haben schon ins Berufsleben eingestiegen. Und manche davon stehen jetzt vor Herausforderungen anderer Sachen. Deshalb bieten wir die Prüfungsteilnehmer die effizienteste Methode für die Vorbereitung der Databricks Databricks-Generative-AI-Engineer-Associate. Um Sie unbesorgt unsere Produkte kaufen zu lassen, bieten wir noch kostenlose Demos von verschiedenen Versionen der Databricks Databricks-Generative-AI-Engineer-Associate. Wir haben schon zahllosen Prüfungskandidaten geholfen, Databricks Databricks-Generative-AI-Engineer-Associate Prüfung zu bestehen. Wir hoffen Ihnen, auch die Vorteile unserer Produkte zu empfinden.
47. Frage
A Generative AI Engineer wants to build an LLM-based solution to help a restaurant improve its online customer experience with bookings by automatically handling common customer inquiries. The goal of the solution is to minimize escalations to human intervention and phone calls while maintaining a personalized interaction. To design the solution, the Generative AI Engineer needs to define the input data to the LLM and the task it should perform.
Which input/output pair will support their goal?
Antwort: B
Begründung:
Context: The goal is to improve the online customer experience in a restaurant by handling common inquiries about bookings, minimizing escalations, and maintaining personalized interactions.
Explanation of Options:
* Option A: Grouping and summarizing chat logs by user could provide insights into customer interactions but does not directly address the task of handling booking inquiries or minimizing escalations.
* Option B: Using chat logs to generate interactive buttons for booking details directly supports the goal of facilitating online bookings, minimizing the need for human intervention by providing clear, interactive options for customers to self-serve.
* Option C: Classifying sentiment of customer reviews does not directly help with booking inquiries, although it might provide valuable feedback insights.
* Option D: Providing cancellation options is helpful but narrowly focuses on one aspect of the booking process and doesn't support the broader goal of handling common inquiries about bookings.
Option Bbest supports the goal of improving online interactions by using chat logs to generate actionable items for customers, helping them complete booking tasks efficiently and reducing the need for human intervention.
48. Frage
A Generative AI Engineer is evaluating a customer-support agent in Databricks. The team needs to score each response on a domain-specific policy: the answer must cite an approved refund rule and must not mention unsupported escalation paths. Built-in evaluation metrics do not capture this logic. The team wants the metric to run during agent evaluation in Databricks and return a repeatable, structured score for each trace.
Which approach should the engineer use?
Antwort: D
Begründung:
MLflow supports custom scorers for application-specific evaluation requirements that built-in metrics do not address. The engineer can define a scorer that examines the generated answer and, when necessary, the complete execution trace. It can verify references against an approved refund-rule list and check whether escalation statements violate the policy. The scorer returns structured feedback, such as a Boolean result, numerical score, or Feedback object, and is supplied to mlflow.genai.evaluate(). Deterministic checks are appropriate when repeatability is essential; semantic checks may require a carefully specified judge. Latency and token counts measure operational behavior rather than policy compliance. Reviewing traces manually does not create an automated metric, and the generating model's self-assessment is not an independent compliance evaluation. Databricks documentation
49. Frage
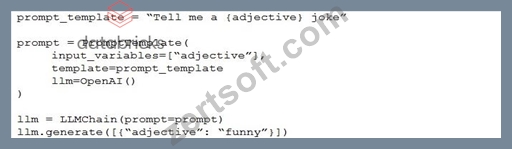
A Generative AI Engineer is testing a simple prompt template in LangChain using the code below, but is getting an error.
Assuming the API key was properly defined, what change does the Generative AI Engineer need to make to fix their chain?


Antwort: A
Begründung:
To fix the error in the LangChain code provided for using a simple prompt template, the correct approach is Option C. Here's a detailed breakdown of why Option C is the right choice and how it addresses the issue:
Proper Initialization: In Option C, the LLMChain is correctly initialized with the LLM instance specified as OpenAI(), which likely represents a language model (like GPT) from OpenAI. This is crucial as it specifies which model to use for generating responses.
Correct Use of Classes and Methods:
The PromptTemplate is defined with the correct format, specifying that adjective is a variable within the template. This allows dynamic insertion of values into the template when generating text.
The prompt variable is properly linked with the PromptTemplate, and the final template string is passed correctly.
The LLMChain correctly references the prompt and the initialized OpenAI() instance, ensuring that the template and the model are properly linked for generating output.
Why Other Options Are Incorrect:
Option A: Misuses the parameter passing in generate method by incorrectly structuring the dictionary.
Option B: Incorrectly uses prompt.format method which does not exist in the context of LLMChain and PromptTemplate configuration, resulting in potential errors.
Option D: Incorrect order and setup in the initialization parameters for LLMChain, which would likely lead to a failure in recognizing the correct configuration for prompt and LLM usage.
Thus, Option C is correct because it ensures that the LangChain components are correctly set up and integrated, adhering to proper syntax and logical flow required by LangChain's architecture. This setup avoids common pitfalls such as type errors or method misuses, which are evident in other options.
50. Frage
A company has a typical RAG-enabled, customer-facing chatbot on its website.
Select the correct sequence of components a user ' s questions will go through before the final output is returned. Use the diagram above for reference.
Antwort: C
Begründung:
To understand how a typical RAG-enabled customer-facing chatbot processes a user ' s question, let's go through the correct sequence as depicted in the diagram and explained in option A:
* Embedding Model (1) : The first step involves the user ' s question being processed through an embedding model. This model converts the text into a vector format that numerically represents the text. This step is essential for allowing the subsequent vector search to operate effectively.
* Vector Search (2) : The vectors generated by the embedding model are then used in a vector search mechanism. This search identifies the most relevant documents or previously answered questions that are stored in a vector format in a database.
* Context-Augmented Prompt (3) : The information retrieved from the vector search is used to create a context-augmented prompt. This step involves enhancing the basic user query with additional relevant information gathered to ensure the generated response is as accurate and informative as possible.
* Response-Generating LLM (4) : Finally, the context-augmented prompt is fed into a response- generating large language model (LLM). This LLM uses the prompt to generate a coherent and contextually appropriate answer, which is then delivered as the final output to the user.
Why Other Options Are Less Suitable :
* B, C, D : These options suggest incorrect sequences that do not align with how a RAG system typically processes queries. They misplace the role of embedding models, vector search, and response generation in an order that would not facilitate effective information retrieval and response generation.
Thus, the correct sequence is embedding model, vector search, context-augmented prompt, response- generating LLM , which is option A.
51. Frage
When developing an LLM application, it's crucial to ensure that the data used for training the model complies with licensing requirements to avoid legal risks.
Which action is NOT appropriate to avoid legal risks?
Antwort: B
Begründung:
* Problem Context: When using data to train a model, it's essential to ensure compliance with licensing to avoid legal risks. Legal issues can arise from using data without permission, especially when it comes from third-party sources.
* Explanation of Options:
* Option A: Reaching out to data curatorsbeforeusing the data is an appropriate action. This allows you to ensure you have permission or understand the licensing terms before starting to use the data in your model.
* Option B: Usingoriginal datathat you personally created is always a safe option. Since you have full ownership over the data, there are no legal risks, as you control the licensing.
* Option C: Using data that is explicitly labeled with an open license and adhering to the license terms is a correct and recommended approach. This ensures compliance with legal requirements.
* Option D: Reaching out to the data curatorsafteryou have already started using the trained model isnot appropriate. If you've already used the data without understanding its licensing terms, you may have already violated the terms of use, which could lead to legal complications. It's essential to clarify the licensing termsbeforeusing the data, not after.
Thus,Option Dis not appropriate because it could expose you to legal risks by using the data without first obtaining the proper licensing permissions.
52. Frage
......
Es gibt doch Methode, den Erfolg zu erzielen, solange Sie geeignete Wahl treffen. Die Fragenkataloge zur Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung von ZertSoft sind speziell für die IT-Fachleute entworfen, um Ihnen zu helfen, die Prüfung zu bestehen. Wenn Sie noch sich anstrengend bemühen, um sich auf dieDatabricks Databricks-Generative-AI-Engineer-Associate Prüfung vorzubereiten, haben Sie nämlich eine falsche Methode gewählt. Das verschwendet nicht nur Zeit, sondern führt sehr wahrscheinlich zur Niederlage. Aber man kann noch rechtzeitig die Abhilfemaßnahmen ergreifen, indem man die Fragenkataloge zur Databricks Databricks-Generative-AI-Engineer-Associate Zertifizierungsprüfung von ZertSoft kauft. Mit ihr können Sie ein ganz anderes Leben führen. Merken Sie sich doch, das Schicksal ist in Ihrer eigenen Hand.
Databricks-Generative-AI-Engineer-Associate Online Prüfung: https://www.zertsoft.com/Databricks-Generative-AI-Engineer-Associate-pruefungsfragen.html
P.S. Kostenlose und neue Databricks-Generative-AI-Engineer-Associate Prüfungsfragen sind auf Google Drive freigegeben von ZertSoft verfügbar: https://drive.google.com/open?id=1WdCVAYn02HUa0vMkz5cxm8e6oG452f77