We have three versions of DP-750 learning materials available, including PDF, Software and APP online. The most popular one is PDF version of DP-750 study guide can be printed into papers so that you are able to write some notes or highlight the emphasis. On the other hand, Software version of our DP-750 Practice Questions is also welcomed by customers, especially for windows users. As for PPT online version, as long as you download the app into your computer. You can enjoy the nice service from us.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
As is known to us, getting the newest information is very important for all people to pass the exam and get the certification in the shortest time. In order to help all customers gain the newest information about the DP-750 exam, the experts and professors from our company designed the best DP-750 Study Materials. The IT experts will update the system every day. If there is new information about the exam, you will receive an email about the newest information about the DP-750 study materials.
NEW QUESTION # 96
You have an Azure Databricks workspace that uses Databricks SQL.
You have a table named sales_goals_source that contains the following columns:
Salesperson
Item
2019
2020
2021
You need to transform the year columns into rows and return the columns Salesperson, Item, Year, and Value.
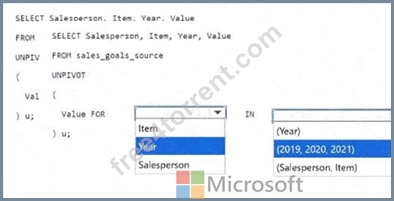
How should you complete the SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
SELECT Salesperson, Item, Year, Value
FROM sales_goals_source
UNPIVOT
(
Value FOR [first dropdown] IN [second dropdown]
);
Answer:
Explanation:
Explanation:
First dropdown: Year
Second dropdown: (2019, 2020, 2021)
The UNPIVOT operator converts the separate 2019, 2020, and 2021 columns into rows. Value becomes the output column containing the values previously stored in those year columns. Year becomes the output name column that identifies the original column from which each value came. Therefore, the expression must use Value FOR Year IN (2019, 2020, 2021). The Salesperson and Item columns are not included in the IN list because they remain identifier columns and are repeated for every resulting year row. A single source row consequently produces three output rows-one for each listed year. Selecting (Year) would reference an output name rather than the source columns that must be rotated.
NEW QUESTION # 97
Note: This section contains one or more sets of questions with the same scenario and problem. Each question presents a unique solution to the problem. You must determine whether the solution meets the stated goals. More than one solution in the set might solve the problem. It is also possible that none of the solutions in the set solve the problem.
After you answer a question in this section, you will NOT be able to return. As a result, these questions do not appear on the Review Screen.
You have an Azure Databricks workspace named Workspace1 that contains a lakehouse and is enabled for Unity Catalog.
You have a connection to a Microsoft SQL Server database named DB1.
You need to expose the schemas and tables of DB1 to meet the following requirements:
- The schemas and tables can be queried in Databricks.
- The schemas and tables appear alongside other Unity Catalog objects.
- The data is NOT copied into Databricks-managed storage.
Solution: You create a Lakeflow Connect pipeline and connect it to DB1.
Does this meet the goal?
Answer: B
Explanation:
Correct:
* You create a foreign catalog in Catalog Explorer.
You should create a Foreign Catalog using Lakehouse Federation.
Data Copying: Lakehouse Federation queries data directly in the source SQL Server without moving or copying it.
Seamless Integration: The database schemas and tables appear right inside Unity Catalog alongside your other data objects.Real-time Access: It provides immediate access to live SQL Server data.
Incorrect:
* You create a Databricks access connector.
* You create a Lakeflow Connect pipeline and connect it to DB1.
Data Copying: Lakeflow Connect is an ingestion tool that physically replicates and copies data into Databricks-managed storage (Delta tables).
Storage Costs: It violates your requirement to keep data out of Databricks storage.
* You create a new native catalog in Unity Catalog.
Note:
To expose the external SQL Server database in Unity Catalog without copying the data, you must use Lakehouse Federation.
Here are the step-by-step actions you need to take:
1. Create a Connection
Create a securable object in Unity Catalog that specifies the path and credentials to access the SQL Server database.
Go to Catalog Explorer or use SQL.
Select External Data > Connections.
Create a connection using the SQL Server connection details (URL, host, port, and database credentials).
*-> 2. Create a Foreign Catalog
Create a specific type of catalog in Unity Catalog that mirrors the external database.
Use the CREATE FOREIGN CATALOG SQL command or the Catalog Explorer UI.
Link this foreign catalog directly to the connection you created in step 1.
3. Query the DataOnce the foreign catalog is created, Unity Catalog automatically syncs the schemas and tables from SQL Server.
Reference:
https://docs.databricks.com/gcp/en/database-objects/
NEW QUESTION # 98
You have an Azure Databricks workspace that contains multiple all-purpose clusters. You discover that some clusters remain idle for long periods after users finish their work. You need to reduce compute costs without affecting active workloads. What should you do?
Answer: A
Explanation:
The correct answer is D - configure automatic termination.
The problem is specific: clusters sit idle after users finish working but nobody manually shuts them down.
Automatic termination solves this directly - once a cluster has been idle for the configured period (no running commands, no attached notebooks with active execution), it shuts itself down. You eliminate the idle cost without any manual intervention and without affecting any workload that is actually running.
Option A (convert to job clusters) would force users off interactive all-purpose clusters, disrupting their development workflow. Option B (spot instances) reduces the hourly rate while a cluster is running but does nothing about the idle-time problem - a cheaper idle cluster is still waste. Option C (enable autoscaling) reduces the number of workers during light load but keeps the cluster alive at the minimum node count. It saves some cost but doesn't fully eliminate idle spend the way auto-termination does.
Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/configure#auto-termination
NEW QUESTION # 99
You have an Azure Databricks workspace that uses serverless compute.
You need to ingest data by using Lakeflow Jobs. New records must be processed as soon as they become available.
Which type of job trigger should you use for the ingestion?
Answer: B
Explanation:
The best trigger type for this scenario is the Continuous trigger.
Immediate Processing: The Continuous trigger mode processes new records as soon as they arrive at the configured data sources. This matches your requirement to ingest and process records without waiting for an artificial time interval.
Native Serverless Support: When paired with serverless compute, Lakeflow Jobs efficiently manage resources by automatically scaling up or down according to the real-time stream volume.
Built-in Fault Tolerance: Continuous pipelines on Databricks automatically handle failures by retrying with an exponential backoff policy, keeping your automated ingestion operational 24/7 without manual intervention.
Reference:
https://docs.databricks.com/aws/en/jobs/continuous
NEW QUESTION # 100
You have an Azure Databricks solution that was developed by multiple engineers and deployed to development, test, and production environments.
You need to implement an application lifecycle management (ALM) process that meets the following requirements:
* Deploys and provides source control for Databricks notebooks, workflows, and jobs in a consistent and repeatable way.
* Parameterizes the target deployment environment.
What should you include in the solution?
Answer: A
Explanation:
Declarative Automation Bundles provide an infrastructure-as-code approach for defining, deploying, and managing complete Azure Databricks projects. A bundle can contain notebooks and other source files together with resource definitions for Lakeflow Jobs, pipelines, dashboards, models, and related workspace resources. Storing the bundle in Git provides source control, collaboration, code review, and integration with automated CI/CD workflows.
Bundle targets can define environment-specific values and overrides for development, test, and production.
The same source-controlled project can therefore be deployed repeatedly to different environments without manually modifying its core definitions. This directly satisfies the requirement to parameterize the target deployment environment. Microsoft Learn Git folders provide source control but manual promotion is inconsistent and error-prone. Terraform is primarily intended for provisioning infrastructure and workspace resources rather than packaging the entire Databricks application lifecycle, including its source files. Exporting and importing workspaces is also a manual process that does not provide a reliable parameterized deployment model. Therefore, Declarative Automation Bundles stored in Git are the appropriate solution.
NEW QUESTION # 101
......
Free4Torrent's study material is available in three different formats. The reason we have introduced three formats of the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice material is to meet the learning needs of every student. Some candidates prefer DP-750 practice exams and some want real Implementing Data Engineering Solutions Using Azure Databricks (DP-750) questions due to a shortage of time. At Free4Torrent, we meet the needs of both types of aspirants. We have DP-750 PDF format, a web-based practice exam, and Implementing Data Engineering Solutions Using Azure Databricks (DP-750) desktop practice test software.
DP-750 Download Demo: https://www.free4torrent.com/DP-750-braindumps-torrent.html