Exam Databricks-Certified-Data-Analyst-Associate Guide | Databricks-Certified-Data-Analyst-Associate Test Braindumps
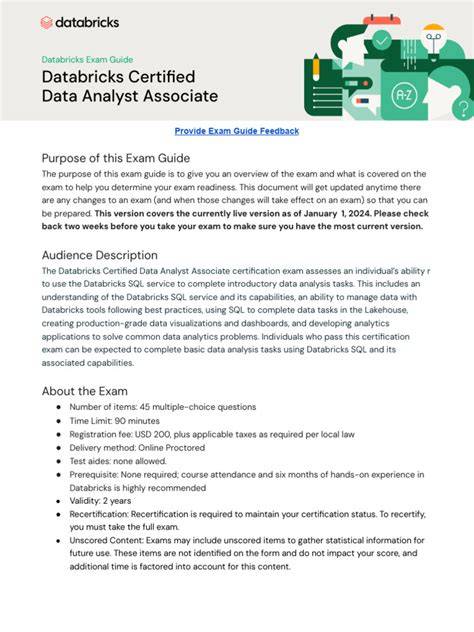
P.S. Free 2026 Databricks Databricks-Certified-Data-Analyst-Associate dumps are available on Google Drive shared by DumpsQuestion: https://drive.google.com/open?id=1qZvWHp3ZeCvyEPfMsusCz9S_gfAPHIch
As a worldwide leader in offering the best Databricks-Certified-Data-Analyst-Associate test torrent, we are committed to providing comprehensive service to the majority of consumers and strive for constructing an integrated service. What’s more, we have achieved breakthroughs in Databricks-Certified-Data-Analyst-Associate certification training application as well as interactive sharing and after-sales service. A good deal of researches has been made to figure out how to help different kinds of candidates to get Databricks Certified Data Analyst Associate Exam certification. We revise and update the Databricks Certified Data Analyst Associate Exam guide torrent according to the changes of the syllabus and the latest developments in theory and practice. We base the Databricks-Certified-Data-Analyst-Associate Certification Training on the test of recent years and the industry trends through rigorous analysis.
| Section | Objectives |
|---|
| Data Visualization and Dashboards | - Creating dashboards in Databricks SQL
- 1. Dashboard configuration and sharing
- 2. Visualizing query results
|
| Data Governance and Security | - Access control and permissions
- 1. Row-level and column-level security concepts
- 2. Unity Catalog basics
|
| Data Management in Lakehouse | - Data ingestion and preparation
- 1. Batch and streaming ingestion concepts
- Delta Lake fundamentals
- 1. ACID transactions and versioning
- 2. Table optimization concepts
|
| Databricks SQL and SQL Analytics | - Querying data using SQL in Databricks
- 1. Joins and aggregations
- 2. SELECT statements and filtering data
- Data transformation and analysis
- 1. Window functions
- 2. Common table expressions (CTEs)
|
>> Exam Databricks-Certified-Data-Analyst-Associate Guide <<
Databricks-Certified-Data-Analyst-Associate Test Braindumps, New Databricks-Certified-Data-Analyst-Associate Test Registration
Our Databricks-Certified-Data-Analyst-Associate study materials include 3 versions and they are the PDF version, PC version, APP online version. You can understand each version’s merits and using method in detail before you decide to buy our Databricks-Certified-Data-Analyst-Associate learning guide. And the content of the three different versions is the same, but the displays are totally different according to the study interest and hobbies. And it is quite enjoyable to learn with our Databricks-Certified-Data-Analyst-Associate Exam Questions.
Databricks Certified Data Analyst Associate Exam Sample Questions (Q26-Q31):
NEW QUESTION # 26
Which of the following statements about a refresh schedule is incorrect?
- A. Refresh schedules can be configured in the Query Editor.
- B. You must have workspace administrator privileges to configure a refresh schedule
- C. A query being refreshed on a schedule does not use a SQL Warehouse (formerly known as SQL Endpoint).
- D. A refresh schedule is not the same as an alert.
- E. A query can be refreshed anywhere from 1 minute lo 2 weeks
Answer: C
Explanation:
Refresh schedules are used to rerun queries at specified intervals, and these queries typically require computational resources to execute. In the context of a cloud data service like Databricks, this would typically involve the use of a SQL Warehouse (or a SQL Endpoint, as they were formerly known) to provide the necessary computational resources. Therefore, the statement is incorrect because scheduled query refreshes would indeed use a SQL Warehouse/Endpoint to execute the query.
NEW QUESTION # 27
Which of the following statements about adding visual appeal to visualizations in the Visualization Editor is incorrect?
- A. Visualization scale can be changed.
- B. Colors can be changed.
- C. Tooltips can be formatted.
- D. Data Labels can be formatted.
- E. Borders can be added.
Answer: E
Explanation:
The Visualization Editor in Databricks SQL allows users to create and customize various types of charts and visualizations from the query results. Users can change the visualization type, select the data fields, adjust the colors, format the data labels, and modify the tooltips. However, there is no option to add borders to the visualizations in the Visualization Editor. Borders are not a supported feature of the new chart visualizations in Databricks1. Therefore, the statement that borders can be added is incorrect. Reference:
New chart visualizations in Databricks | Databricks on AWS
NEW QUESTION # 28
Which of the following is a benefit of the Databricks Lakehouse Platform embracing open source technologies?
- A. Avoiding vendor lock-in
- B. Ability to scale storage
- C. Cloud-specific integrations
- D. Ability to scale workloads
- E. Simplified governance
Answer: A
Explanation:
Option E is correct. A major benefit of open source technologies and open data formats is avoiding vendor lock-in. Databricks supports open formats and interfaces so data can be used across tools and systems rather than being locked into a proprietary platform. Cloud integrations, governance, and workload scalability are Databricks benefits, but the specific benefit of embracing open source is avoiding vendor lock-in. Official Databricks extract: "Using open data formats and interfaces helps to avoid" vendor lock-in, and Databricks states that no proprietary data formats are used because Delta Lake and Iceberg are open source.
NEW QUESTION # 29
A data scientist wants to tune a set of hyperparameters for a machine learning model. They have wrapped a Spark ML model in the objective function objective_function, and they have defined the search space search_space.
As a result, they have the following code block:
num_evals = 100
trials = SparkTrials()
best_hyperparam = fmin(
fn=objective_function,
space=search_space,
algo=tpe.suggest,
max_evals=num_evals,
trials=trials
)
Which of the following changes do they need to make to the above code block in order to accomplish the task?
- A. Reduce num_evals to be less than 10
- B. Change SparkTrials() to Trials()
- C. Remove the trials=trials argument
- D. Remove the algo=tpe.suggest argument
- E. Change fmin() to fmax()
Answer: B
Explanation:
Option A is correct. The model being tuned is a Spark ML model, which is already distributed. SparkTrials is intended to distribute independent single-machine trials across Spark workers. For distributed ML algorithms such as Spark MLlib/Spark ML, Hyperopt should run trials from the driver so each trial can access the full cluster resources. Therefore, SparkTrials() should be changed to Trials(). Official Databricks documentation explains that this setup works for distributed machine learning algorithms including Apache Spark MLlib, and the Databricks notebook guidance states that SparkTrials is incompatible for that distributed-training pattern because each trial must be evaluated on the driver node.
NEW QUESTION # 30
Consider the following two statements:
Statement 1:

Statement 2:

Which of the following describes how the result sets will differ for each statement when they are run in Databricks SQL?
- A. Both statements will fail because Databricks SQL does not support those join types.
- B. There is no difference between the result sets for both statements.
- C. The first statement will return all data from the customers table and matching data from the orders table. The second statement will return all data from the orders table and matching data from the customers table. Any missing data will be filled in with NULL.
- D. When the first statement is run, all rows from the customers table will be returned and only the customer_id from the orders table will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
- E. When the first statement is run, only rows from the customers table that have at least one match with the orders table on customer_id will be returned. When the second statement is run, only those rows in the customers table that do not have at least one match with the orders table on customer_id will be returned.
Answer: E
Explanation:
Based on the images you sent, the two statements are SQL queries for different types of joins between the customers and orders tables. A join is a way of combining the rows from two table references based on some criteria. The join type determines how the rows are matched and what kind of result set is returned. The first statement is a query for a LEFT SEMI JOIN, which returns only the rows from the left table reference (customers) that have a match with the right table reference (orders) on the join condition (customer_id). The second statement is a query for a LEFT ANTI JOIN, which returns only the rows from the left table reference (customers) that have no match with the right table reference (orders) on the join condition (customer_id). Therefore, the result sets for the two statements will differ in the following way:
The first statement will return a subset of the customers table that contains only the customers who have placed at least one order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT SEMI JOIN does not include any columns from the orders table.
The second statement will return a subset of the customers table that contains only the customers who have not placed any order. The number of rows returned will be less than or equal to the number of rows in the customers table, depending on how many customers have no orders. The number of columns returned will be the same as the number of columns in the customers table, as the LEFT ANTI JOIN does not include any columns from the orders table.
The other options are not correct because:
A) The first statement will not return all data from the customers table, as it will exclude the customers who have no orders. The second statement will not return all data from the orders table, as it will exclude the orders that have a matching customer. Neither statement will fill in any missing data with NULL, as they do not return any columns from the other table.
C) There is a difference between the result sets for both statements, as explained above. The LEFT SEMI JOIN and the LEFT ANTI JOIN are not equivalent operations and will produce different outputs.
D) Both statements will not fail, as Databricks SQL does support those join types. Databricks SQL supports various join types, including INNER, LEFT OUTER, RIGHT OUTER, FULL OUTER, LEFT SEMI, LEFT ANTI, and CROSS. You can also use NATURAL, USING, or LATERAL keywords to specify different join criteria.
E) The first statement will not return only the customer_id from the orders table, as it will return all columns from the customers table. The second statement is correct, but it is not the only difference between the result sets.
NEW QUESTION # 31
......
Nowadays the knowledge capabilities and mental labor are more valuable than the manual labor because knowledge can create more wealth than the mental labor. If you boost professional knowledge capabilities in some area you are bound to create a lot of values and can get a good job with high income. Passing the test of Databricks-Certified-Data-Analyst-Associate Certification can help you achieve that, and our Databricks-Certified-Data-Analyst-Associate training materials are the best study materials for you to prepare for the Databricks-Certified-Data-Analyst-Associate test. Our Databricks-Certified-Data-Analyst-Associate guide materials combine the key information to help the clients both solidify the foundation and advance with the times.
Databricks-Certified-Data-Analyst-Associate Test Braindumps: https://www.dumpsquestion.com/Databricks-Certified-Data-Analyst-Associate-exam-dumps-collection.html
- Real Databricks-Certified-Data-Analyst-Associate Latest Practice - Databricks-Certified-Data-Analyst-Associate Free Questions - Databricks-Certified-Data-Analyst-Associate Tesking Vce 🗨 Enter ➠ www.vceengine.com 🠰 and search for ▶ Databricks-Certified-Data-Analyst-Associate ◀ to download for free 😫Top Databricks-Certified-Data-Analyst-Associate Questions
- 2026 Databricks Useful Exam Databricks-Certified-Data-Analyst-Associate Guide 🦖 Search for ➡ Databricks-Certified-Data-Analyst-Associate ️⬅️ and download exam materials for free through 「 www.pdfvce.com 」 🧖Well Databricks-Certified-Data-Analyst-Associate Prep
- Databricks-Certified-Data-Analyst-Associate Test Dump ⚒ Exam Databricks-Certified-Data-Analyst-Associate Pass Guide 🍞 Databricks-Certified-Data-Analyst-Associate Exam Forum 🥬 Open ⮆ www.exam4labs.com ⮄ and search for { Databricks-Certified-Data-Analyst-Associate } to download exam materials for free 🚢Databricks-Certified-Data-Analyst-Associate Practice Test Pdf
- Use Databricks Databricks-Certified-Data-Analyst-Associate Dumps to Have Great Outcomes In Databricks Exam 😷 Open website 【 www.pdfvce.com 】 and search for 「 Databricks-Certified-Data-Analyst-Associate 」 for free download ♿Databricks-Certified-Data-Analyst-Associate Valid Exam Labs
- Latest Databricks-Certified-Data-Analyst-Associate Exam Labs 🏝 Exam Databricks-Certified-Data-Analyst-Associate Registration 🧬 Databricks-Certified-Data-Analyst-Associate Valid Exam Labs 💏 Search on ⏩ www.examcollectionpass.com ⏪ for ▶ Databricks-Certified-Data-Analyst-Associate ◀ to obtain exam materials for free download 🤍Databricks-Certified-Data-Analyst-Associate Exam Forum
- Use Databricks Databricks-Certified-Data-Analyst-Associate Dumps to Have Great Outcomes In Databricks Exam 🦕 Search for ⏩ Databricks-Certified-Data-Analyst-Associate ⏪ and easily obtain a free download on ⏩ www.pdfvce.com ⏪ 🌀Top Databricks-Certified-Data-Analyst-Associate Questions
- Databricks - Databricks-Certified-Data-Analyst-Associate –Professional Exam Guide 🚲 Search on ⇛ www.prepawayexam.com ⇚ for 【 Databricks-Certified-Data-Analyst-Associate 】 to obtain exam materials for free download 👺Detailed Databricks-Certified-Data-Analyst-Associate Study Plan
- Efficient Exam Databricks-Certified-Data-Analyst-Associate Guide - Leading Offer in Qualification Exams - Free PDF Databricks-Certified-Data-Analyst-Associate: Databricks Certified Data Analyst Associate Exam 🦖 Search on ☀ www.pdfvce.com ️☀️ for ( Databricks-Certified-Data-Analyst-Associate ) to obtain exam materials for free download 🥼Test Databricks-Certified-Data-Analyst-Associate Questions Pdf
- Practice Databricks-Certified-Data-Analyst-Associate Engine 🏋 Latest Databricks-Certified-Data-Analyst-Associate Exam Labs 🖖 Databricks-Certified-Data-Analyst-Associate Latest Test Question 🚻 Search for ➥ Databricks-Certified-Data-Analyst-Associate 🡄 and obtain a free download on ▛ www.vce4dumps.com ▟ 🏛Well Databricks-Certified-Data-Analyst-Associate Prep
- Practice Databricks-Certified-Data-Analyst-Associate Engine 🔡 Test Databricks-Certified-Data-Analyst-Associate Questions Pdf 🚞 Databricks-Certified-Data-Analyst-Associate Latest Braindumps 🥟 Immediately open ▷ www.pdfvce.com ◁ and search for 「 Databricks-Certified-Data-Analyst-Associate 」 to obtain a free download ⏹Databricks-Certified-Data-Analyst-Associate Exam Forum
- Real Databricks-Certified-Data-Analyst-Associate Latest Practice - Databricks-Certified-Data-Analyst-Associate Free Questions - Databricks-Certified-Data-Analyst-Associate Tesking Vce 🧗 Search for ➽ Databricks-Certified-Data-Analyst-Associate 🢪 and easily obtain a free download on { www.prepawayexam.com } 💍Databricks-Certified-Data-Analyst-Associate Online Training
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
BONUS!!! Download part of DumpsQuestion Databricks-Certified-Data-Analyst-Associate dumps for free: https://drive.google.com/open?id=1qZvWHp3ZeCvyEPfMsusCz9S_gfAPHIch