Databricks Databricks-Certified-Data-Engineer-Professional入門知識、Databricks-Certified-Data-Engineer-Professional日本語版参考書

ちなみに、Xhs1991 Databricks-Certified-Data-Engineer-Professionalの一部をクラウドストレージからダウンロードできます:https://drive.google.com/open?id=12DdpnwfaqJP2bSVLfE9FwfMs2g9YyFoC
Xhs1991のDatabricks-Certified-Data-Engineer-Professionalクイズトレントに関するどんな問題やコンサルタントでも、1日を通して効率的なオンラインサービスを提供できます。 遅かれ早かれあなたがそれらを克服するのを助ける努力をspareしみません。 まず、Databricks-Certified-Data-Engineer-ProfessionalのDatabricks Certified Data Engineer Professional Exam試験トレント資料を毎日チェックして更新する専門スタッフがいるため、いつでもDatabricks-Certified-Data-Engineer-Professional試験トレントから最新情報を入手できます。 アフターサービスのほかに、エンジニアは常にオンラインで、必要に応じてDatabricksのDatabricks-Certified-Data-Engineer-Professionalの学習質問に関するリモートガイダンスと支援を提供します。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Modeling and Transformation | - Spark SQL transformations
- Dimensional modeling concepts
- Performance optimization techniques
|
| Delta Lake and Data Management | - Time travel and versioning
- Schema evolution and enforcement
- Delta Lake transactions and ACID properties
|
| Production Pipelines and Orchestration | - Job scheduling and monitoring
- Databricks Workflows
- Error handling and recovery strategies
|
| Data Ingestion and Processing | - Batch and streaming ingestion with Auto Loader
- Structured Streaming fundamentals
- ETL pipeline design patterns
|
| Databricks Lakehouse Platform Architecture | - Workspace and cluster architecture
- Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
|
>> Databricks Databricks-Certified-Data-Engineer-Professional入門知識 <<
最新のDatabricks-Certified-Data-Engineer-Professional入門知識試験-試験の準備方法-ハイパスレートのDatabricks-Certified-Data-Engineer-Professional日本語版参考書
我々Xhs1991は一番信頼できるIT試験資料販売サイトになれるために、弊社はお客様に最完備かつ最新版のDatabricks-Certified-Data-Engineer-Professional問題集を提供して努力します。我々の問題集によって、ほとんどの受験生は大方の人から見る大変なDatabricks Databricks-Certified-Data-Engineer-Professional試験にうまく合格しました。この成功データはDatabricks-Certified-Data-Engineer-Professional試験に準備する皆様にXhs1991のDatabricks-Certified-Data-Engineer-Professional問題集を勧める根拠とします。もしあなたは残念的にDatabricks-Certified-Data-Engineer-Professional試験に失敗したら、全額で返金することを承諾します。すべてのことはあなたの安心的に試験に準備できるのためのです。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q188-Q193):
質問 # 188
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline. Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
- B. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
- C. Stop the existing pipeline; use the returned settings in a reset command
- D. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
正解:B
解説:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
質問 # 189
A junior data engineer has been asked to develop a streaming data pipeline with a grouped aggregation using DataFrame df. The pipeline needs to calculate the average humidity and average temperature for each non-overlapping five-minute interval. Events are recorded once per minute per device.
Streaming DataFrame df has the following schema:
"device_id INT, event_time TIMESTAMP, temp FLOAT, humidity FLOAT"
Code block:
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
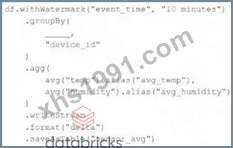
Choose the response that correctly fills in the blank within the code block to complete this task.
- A. to_interval("event_time", "5 minutes").alias("time")
- B. lag("event_time", "10 minutes").alias("time")
- C. "event_time"
- D. window("event_time", "5 minutes").alias("time")
- E. window("event_time", "10 minutes").alias("time")
正解:D
解説:
This is the correct answer because the window function is used to group streaming data by time intervals. The window function takes two arguments: a time column and a window duration. The window duration specifies how long each window is, and must be a multiple of 1 second. In this case, the window duration is "5 minutes", which means each window will cover a non-overlapping five- minute interval. The window function also returns a struct column with two fields: start and end, which represent the start and end time of each window. The alias function is used to rename the struct column as "time".
質問 # 190
A data engineer is brining an existing production Databricks job under asset bundle management and wants to ensure that:
- The job's current configuration is captured as YAML, and all
referenced files are included in their bundle project.
- Future changes to the bundle's YAML will update the existing job in-
place (not create a new job)
How should the data engineer successfully move the production job under asset bundle management?
- A. Export the job definition as JSON, convert it to YAML, and place it in your bundle. Then, run Databricks bundle deploy to update the existing job.
- B. Run databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deployment, bind to link the bundle's job resource to the existing job in Databricks.
- C. Run Databricks bundle generate job --existing-job-id to generate the YAML and download referenced files. Then, run Databricks bundle deploy to deploy the bundle, which will always update the existing job automatically.
- D. Manually create the YAML configuration for the job in your bundle project, ensuring all settings match the existing job. Then, run Databricks bundle deploy the bundle, which will update the existing job in your workspace.
正解:B
解説:
Generating the bundle from the existing job captures the full job configuration as YAML and pulls in all referenced files into the bundle project. Binding the generated job resource to the existing Databricks job establishes a persistent link, ensuring that future bundle deployments update the same production job in place rather than creating a new one.
質問 # 191
Assuming that the Databricks CLI has been installed and configured correctly, which Databricks CLI command can be used to upload a custom Python Wheel to object storage mounted with the DBFS for use with a production job?
- A. jobs
- B. libraries
- C. configure
- D. fs
- E. workspace
正解:D
解説:
https://docs.databricks.com/en/archive/dev-tools/cli/dbfs-cli.html
質問 # 192
A data engineer is tasked with building a nightly batch ETL pipeline that processes very large volumes of raw JSON logs from a data lake into Delta tables for reporting. The data arrives in bulk once per day, and the pipeline takes several hours to complete. Cost efficiency is important, but performance and reliability of completing the pipeline are the highest priorities. Which type of Databricks cluster should the data engineer configure?
- A. An all-purpose cluster always kept running to ensure low-latency job startup times.
- B. A lightweight single-node cluster with low worker node count to reduce costs.
- C. A job cluster configured to autoscale across multiple workers during the pipeline run.
- D. A high-concurrency cluster designed for interactive SQL workloads.
正解:C
解説:
Job clusters are optimized for automated production workloads. They start when a job is triggered and terminate automatically once the task completes. This ensures cost control while maintaining performance and reliability for batch ETL. Autoscaling allows Databricks to add or remove workers dynamically based on workload size, ensuring large data volumes are processed efficiently.
All-purpose clusters are intended for development or ad-hoc workloads, not scheduled ETL.
質問 # 193
......
仕事に取り掛かって顧客とやり取りする前に厳密に訓練された責任ある忍耐強いスタッフ。 Databricks-Certified-Data-Engineer-Professional試験の準備の質を実践し、経験すると、それらの保守性と有用性を思い出すでしょう。 Databricks-Certified-Data-Engineer-Professional練習教材が試験受験者の98%以上が夢の証明書を取得するのに役立った理由を説明しています。あなたもそれを手に入れることができると信じてください。
Databricks-Certified-Data-Engineer-Professional日本語版参考書: https://www.xhs1991.com/Databricks-Certified-Data-Engineer-Professional.html
- Databricks-Certified-Data-Engineer-Professional難易度受験料 🦔 Databricks-Certified-Data-Engineer-Professional日本語 🧽 Databricks-Certified-Data-Engineer-Professional認定資格試験問題集 🙋 今すぐ( www.mogiexam.com )で➽ Databricks-Certified-Data-Engineer-Professional 🢪を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional資格復習テキスト
- Databricks-Certified-Data-Engineer-Professional試験の準備方法|最新のDatabricks-Certified-Data-Engineer-Professional入門知識試験|素敵なDatabricks Certified Data Engineer Professional Exam日本語版参考書 🌙 ⏩ www.goshiken.com ⏪を開き、[ Databricks-Certified-Data-Engineer-Professional ]を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional最新テスト
- Databricks Databricks-Certified-Data-Engineer-Professional認定試験に準備する有効なツール 🏤 “ jp.fast2test.com ”を入力して[ Databricks-Certified-Data-Engineer-Professional ]を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional最新テスト
- 一生懸命にDatabricks-Certified-Data-Engineer-Professional入門知識 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional日本語版参考書 | 最高のDatabricks-Certified-Data-Engineer-Professional資格認定 🕘 ➠ www.goshiken.com 🠰を入力して【 Databricks-Certified-Data-Engineer-Professional 】を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional試験復習
- 素晴らしいDatabricks-Certified-Data-Engineer-Professional入門知識 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional日本語版参考書 | 便利なDatabricks-Certified-Data-Engineer-Professional資格認定 Databricks Certified Data Engineer Professional Exam 💧 “ www.passtest.jp ”に移動し、➽ Databricks-Certified-Data-Engineer-Professional 🢪を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional認定資格試験問題集
- Databricks-Certified-Data-Engineer-Professional復習テキスト 🥩 Databricks-Certified-Data-Engineer-Professionalトレーリング学習 🍾 Databricks-Certified-Data-Engineer-Professional無料ダウンロード 🎃 「 www.goshiken.com 」サイトにて最新( Databricks-Certified-Data-Engineer-Professional )問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional資格認定
- Databricks-Certified-Data-Engineer-Professional資格取得 🌞 Databricks-Certified-Data-Engineer-Professional最新テスト 🧎 Databricks-Certified-Data-Engineer-Professional日本語pdf問題 🏕 ウェブサイト▷ www.xhs1991.com ◁を開き、➽ Databricks-Certified-Data-Engineer-Professional 🢪を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional認定内容
- Databricks-Certified-Data-Engineer-Professional復習テキスト 🏐 Databricks-Certified-Data-Engineer-Professional日本語 🍹 Databricks-Certified-Data-Engineer-Professional日本語対策 ☁ 検索するだけで➥ www.goshiken.com 🡄から➽ Databricks-Certified-Data-Engineer-Professional 🢪を無料でダウンロードDatabricks-Certified-Data-Engineer-Professional日本語pdf問題
- Databricks-Certified-Data-Engineer-Professional資格復習テキスト 🔸 Databricks-Certified-Data-Engineer-Professional認定資格試験問題集 🍤 Databricks-Certified-Data-Engineer-Professional日本語pdf問題 🧚 ➤ www.mogiexam.com ⮘には無料の➽ Databricks-Certified-Data-Engineer-Professional 🢪問題集がありますDatabricks-Certified-Data-Engineer-Professional試験復習
- 正確的なDatabricks-Certified-Data-Engineer-Professional入門知識 | 最初の試行で簡単に勉強して試験に合格する - 公認されたDatabricks-Certified-Data-Engineer-Professional: Databricks Certified Data Engineer Professional Exam 🧰 { Databricks-Certified-Data-Engineer-Professional }を無料でダウンロード➡ www.goshiken.com ️⬅️で検索するだけDatabricks-Certified-Data-Engineer-Professional資格認定
- Databricks-Certified-Data-Engineer-Professional技術問題 ♻ Databricks-Certified-Data-Engineer-Professional試験復習 🌯 Databricks-Certified-Data-Engineer-Professional日本語 ⌚ ⮆ www.xhs1991.com ⮄で▛ Databricks-Certified-Data-Engineer-Professional ▟を検索し、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professionalテスト資料
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, Disposable vapes
さらに、Xhs1991 Databricks-Certified-Data-Engineer-Professionalダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=12DdpnwfaqJP2bSVLfE9FwfMs2g9YyFoC