Latest Implementing Data Engineering Solutions Using Microsoft Fabric pass review & DP-700 getfreedumps study materials

P.S. Free 2026 Microsoft DP-700 dumps are available on Google Drive shared by PDFDumps: https://drive.google.com/open?id=1YBqX0nCbWsUOg0brxwPejYSd5B4R-LD6
Since our Implementing Data Engineering Solutions Using Microsoft Fabric practice exam tracks your progress and reports results, you can review these results and strengthen your weaker concepts. We offer Microsoft DP-700 desktop practice test software which works on Windows computers after installation. The web-based DP-700 practice exam needs no plugins or software installation. Linux, iOS, Android, Windows, and Mac support the web-based Microsoft DP-700 Practice Exam. Additionally, Chrome, Opera, Firefox, Safari, Internet Explorer support this Implementing Data Engineering Solutions Using Microsoft Fabric DP-700 web-based practice test.
| Section | Weight | Objectives |
|---|
| Topic 1: Implement and manage an analytics solution | 30–35% | - Manage data storage
- 1. Choose appropriate data stores
- 2. Create and manage OneLake shortcuts
- 3. Implement data mirroring
- Configure workspace settings
- 1. Configure Dataflows Gen2 settings
- 2. Configure OneLake workspace settings
- 3. Configure domain workspace settings
- 4. Configure Spark workspace settings
- 5. Configure Microsoft Fabric workspace settings
- Manage data lifecycle and governance
- 1. Implement data governance with Microsoft Purview
- 2. Manage data access and security
- 3. Implement data retention and archiving
|
| Topic 2: Monitor and optimize an analytics solution | 30–35% | - Optimize performance
- 1. Optimize pipelines and data flows
- 2. Optimize Spark and query performance
- 3. Optimize Lakehouse and data warehouse performance
- 4. Optimize storage efficiency
- Troubleshoot issues
- 1. Identify and resolve pipeline errors
- 2. Identify and resolve storage and query errors
- 3. Identify and resolve notebook and Spark errors
- 4. Identify and resolve Dataflow errors
- Monitor analytics solutions
- 1. Monitor data ingestion and transformation
- 2. Configure alerts and notifications
- 3. Monitor Fabric items and activities
- 4. Monitor semantic model refreshes
|
| Topic 3: Ingest and transform data | 30–35% | - Orchestrate data operations
- 1. Use parameters and dynamic expressions
- 2. Orchestrate with notebooks and pipelines
- 3. Implement schedules and triggers
- Transform data
- 1. Transform data using PySpark
- 2. Transform data using SQL
- 3. Clean, denormalize, and aggregate data
- 4. Transform data using KQL
- Ingest data
- 1. Ingest data using pipelines
- 2. Ingest data using Dataflows Gen2
- 3. Ingest data using Eventstreams
- Design and implement data loading patterns
- 1. Prepare data for dimensional models
- 2. Design streaming data loading patterns
- 3. Design full and incremental data loads
|
>> DP-700 Reliable Braindumps <<
Stay Updated with Free Microsoft DP-700 Exam Question Updates
As we know, it is necessary to improve your capacity in work if you want to make achievements on the job or your career. At present, many office workers choose to buy our DP-700 study materials to enrich themselves. If you still do nothing, you will be fired sooner or later. God will help those who help themselves. Come to snap up our DP-700 Exam Guide to let yourself always be the most excellent and have a better life!
Microsoft Implementing Data Engineering Solutions Using Microsoft Fabric Sample Questions (Q43-Q48):
NEW QUESTION # 43
You have a Fabric workspace named Workspace1.
You plan to configure Git integration for Workspace1 by using an Azure DevOps Git repository. An Azure DevOps admin creates the required artifacts to support the integration of Workspace1 Which details do you require to perform the integration?
- A. the Git repository URL and the Git folder
- B. the organization, project. Git repository, and branch
- C. the personal access token (PAT) for Git authentication and the Git repository URL
- D. the project, Git repository, branch, and Git folder
Answer: B
NEW QUESTION # 44
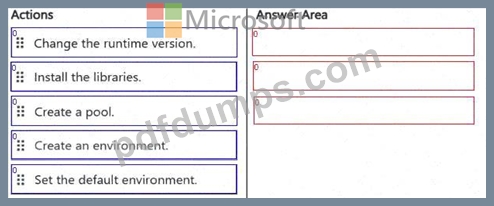
Your company has a team of developers. The team creates Python libraries of reusable code that is used to transform data.
You create a Fabric workspace name Workspace1 that will be used to develop extract, transform, and load (ETL) solutions by using notebooks.
You need to ensure that the libraries are available by default to new notebooks in Workspace1.
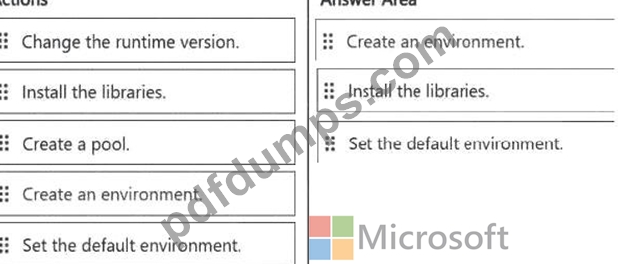
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.
Answer:
Explanation:
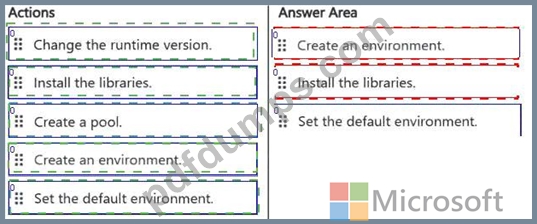
Explanation:
NEW QUESTION # 45
You have a Fabric deployment pipeline that uses three workspaces named Dev, Test, and Prod.
You need to deploy an eventhouse as part of the deployment process.
What should you use to add the eventhouse to the deployment process?
- A. GitHub Actions
- B. an Azure DevOps pipeline
- C. a deployment pipeline
Answer: B
Explanation:
A deployment pipeline in Fabric is designed to automate the process of deploying assets (such as reports, datasets, eventhouses, and other objects) between environments like Dev, Test, and Prod. Since you need to deploy an eventhouse as part of the deployment process, a deployment pipeline is the appropriate tool to move this asset through the different stages of your environment.
NEW QUESTION # 46
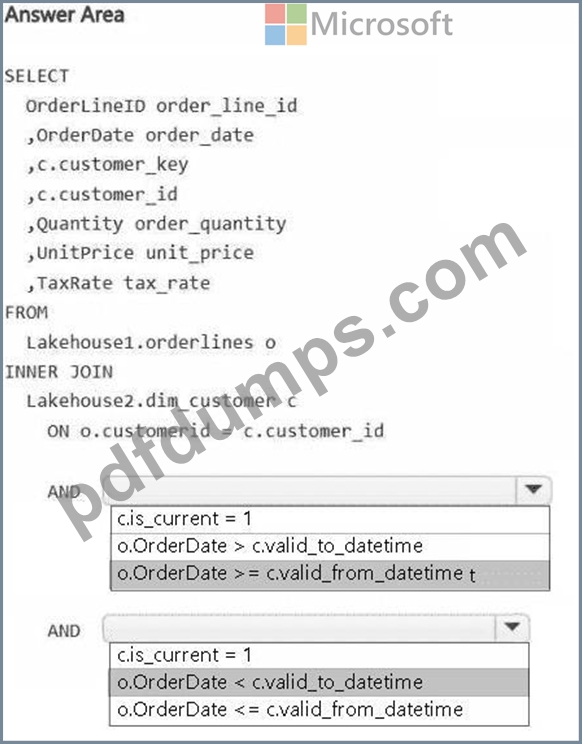
HOTSPOT
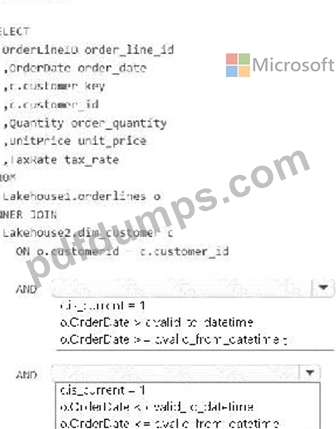
You have a Fabric workspace that contains two lakehouses named Lakehouse1 and Lakehouse2. Lakehouse1 contains staging data in a Delta table named Orderlines. Lakehouse2 contains a Type 2 slowly changing dimension (SCD) dimension table named Dim_Customer.
You need to build a query that will combine data from Orderlines and Dim_Customer to create a new fact table named Fact_Orders. The new table must meet the following requirements:
Enable the analysis of customer orders based on historical attributes.
Enable the analysis of customer orders based on the current attributes.
How should you complete the statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
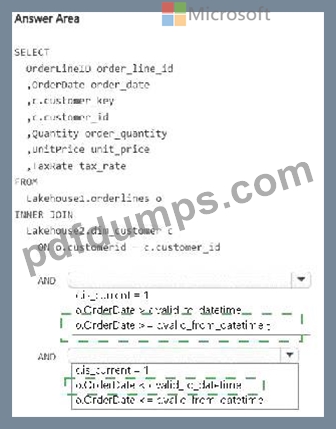
Explanation:
NEW QUESTION # 47
DRAG DROP
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData.
The following is a sample of the data in TaxiData.
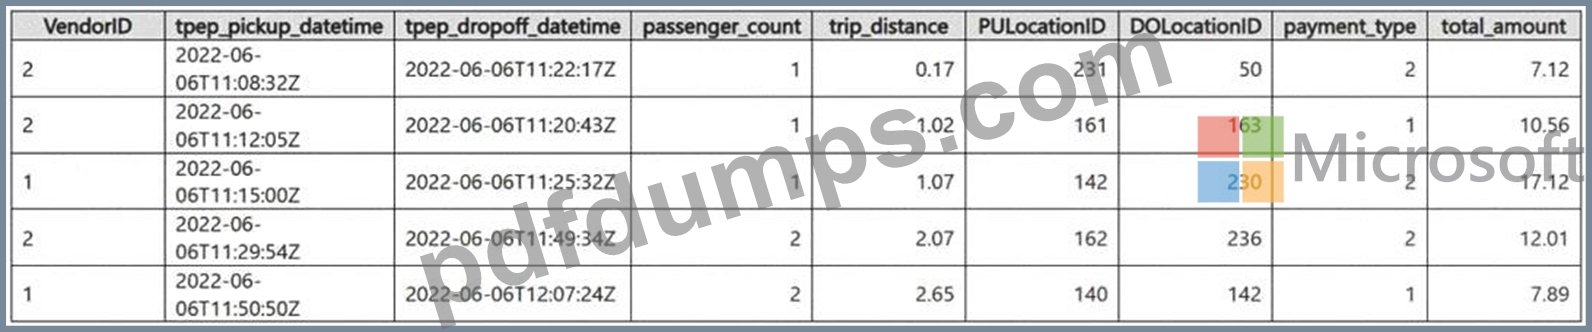
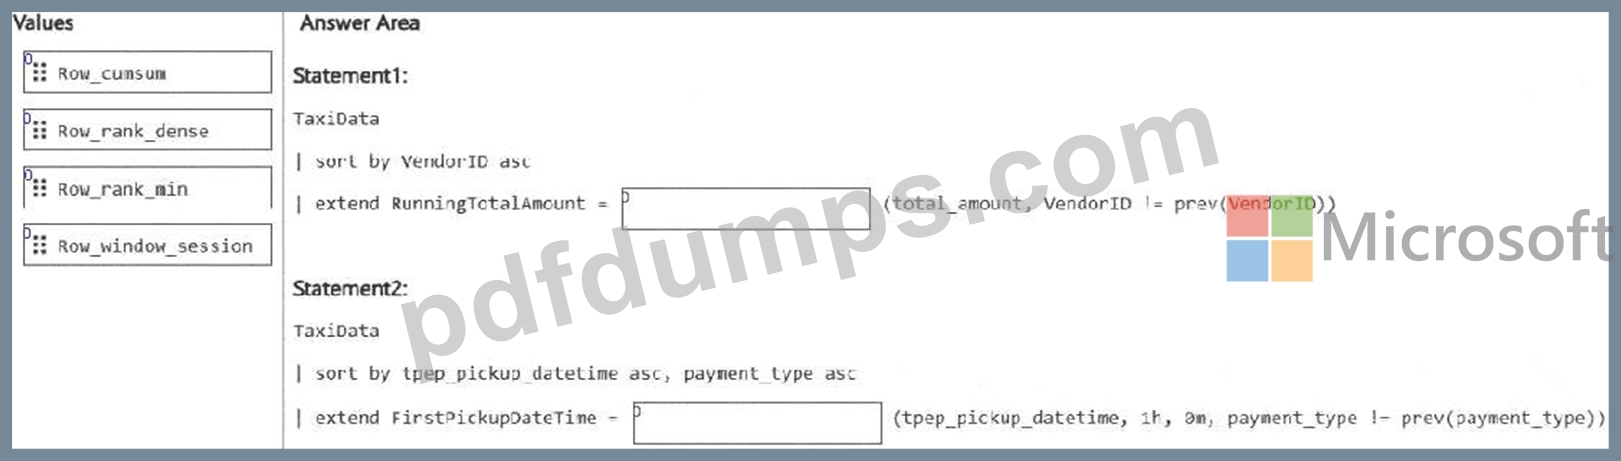
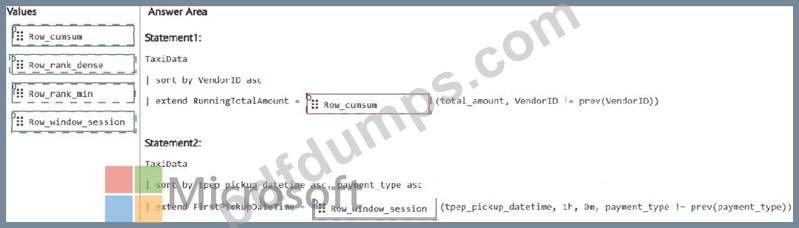
You need to build two KQL queries. The solution must meet the following requirements:
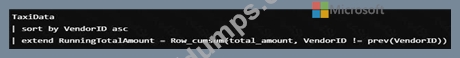
One of the queries must partition RunningTotalAmount by VendorID.
The other query must create a column named FirstPickupDateTime that shows the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
How should you complete each query? To answer, drag the appropriate values the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.
Answer:
Explanation:
Explanation:
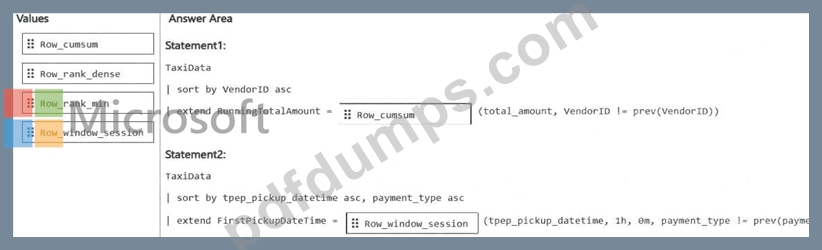
Partition the RunningTotalAmount by VendorID. - Row_cumsum
The Row_cumsum function computes the cumulative sum of a column while optionally restarting the accumulation based on a condition. In this case, it calculates the cumulative sum of total_amount for each VendorID, restarting when the VendorID changes (VendorID != prev(VendorID)).
Create a column FirstPickupDateTime that shows the first value of each hour from tpep_pickup_datetime, partitioned by payment_type - Row_window_session

NEW QUESTION # 48
......
The process of getting a certificate isn’t an easy process for many of the candidates. We will provide you with the company in your whole process of preparation in the DP-700 learning materials. You will find that you are not the only yourself, you also have us, our service stuff will offer you the most considerate service, and in the process of practicing the DP-700 Training Materials, if you have any questions please contact us, we will be very glad to help you.
Reliable DP-700 Dumps Book: https://www.pdfdumps.com/DP-700-valid-exam.html
- New DP-700 Exam Pattern 🧵 DP-700 Latest Dumps Book ❎ DP-700 Latest Dumps Book 🦲 Search for ➥ DP-700 🡄 and obtain a free download on ▷ www.vceengine.com ◁ 💅DP-700 Technical Training
- DP-700 Latest Dumps Book 🔸 Exam DP-700 Bootcamp 📰 DP-700 Latest Dumps Book 🌒 Easily obtain free download of [ DP-700 ] by searching on ⮆ www.pdfvce.com ⮄ 📨DP-700 Reliable Exam Materials
- DP-700 - Implementing Data Engineering Solutions Using Microsoft Fabric –High-quality Reliable Braindumps 🤒 Search for ⇛ DP-700 ⇚ and download it for free on ⇛ www.dumpsquestion.com ⇚ website 📷New DP-700 Exam Pattern
- Use Real Microsoft DP-700 PDF Questions [2026] - 100% Guaranteed Success 🤟 Search for ➥ DP-700 🡄 on 【 www.pdfvce.com 】 immediately to obtain a free download 🔖DP-700 Test Lab Questions
- Hot Microsoft DP-700 Reliable Braindumps Carefully Researched by Microsoft Experienced Trainers 🧕 Immediately open ➥ www.vce4dumps.com 🡄 and search for ( DP-700 ) to obtain a free download 🍔Exam DP-700 Bootcamp
- 100% Pass Quiz Microsoft DP-700 - Marvelous Implementing Data Engineering Solutions Using Microsoft Fabric Reliable Braindumps 🍊 Search for 【 DP-700 】 and download it for free on ➥ www.pdfvce.com 🡄 website ♣DP-700 Test Testking
- DP-700 Latest Test Pdf 😝 Valid Dumps DP-700 Pdf 🚆 DP-700 Technical Training 🏤 Search for 【 DP-700 】 and easily obtain a free download on “ www.prepawayete.com ” 🐯Actual DP-700 Test Answers
- DP-700 Test Testking 🔛 DP-700 New Braindumps Ebook 🎦 DP-700 Reliable Test Tutorial 🛸 Simply search for ➤ DP-700 ⮘ for free download on ▛ www.pdfvce.com ▟ 🌋Exam DP-700 Bootcamp
- DP-700 - Implementing Data Engineering Solutions Using Microsoft Fabric –High-quality Reliable Braindumps 🏴 Search for ⏩ DP-700 ⏪ and download exam materials for free through ⮆ www.practicevce.com ⮄ 🆔Actual DP-700 Test Answers
- DP-700 New Braindumps Ebook 💰 Actual DP-700 Test Answers ⭕ DP-700 Reliable Exam Pattern 👠 Open ➽ www.pdfvce.com 🢪 and search for ⇛ DP-700 ⇚ to download exam materials for free 🦡Books DP-700 PDF
- Latest DP-700 Exam Cost 🚃 DP-700 Valid Dumps Free 🧃 DP-700 Technical Training 😕 Easily obtain free download of ( DP-700 ) by searching on ✔ www.dumpsmaterials.com ️✔️ 🔢Latest DP-700 Exam Cost
- myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, Disposable vapes
2026 Latest PDFDumps DP-700 PDF Dumps and DP-700 Exam Engine Free Share: https://drive.google.com/open?id=1YBqX0nCbWsUOg0brxwPejYSd5B4R-LD6